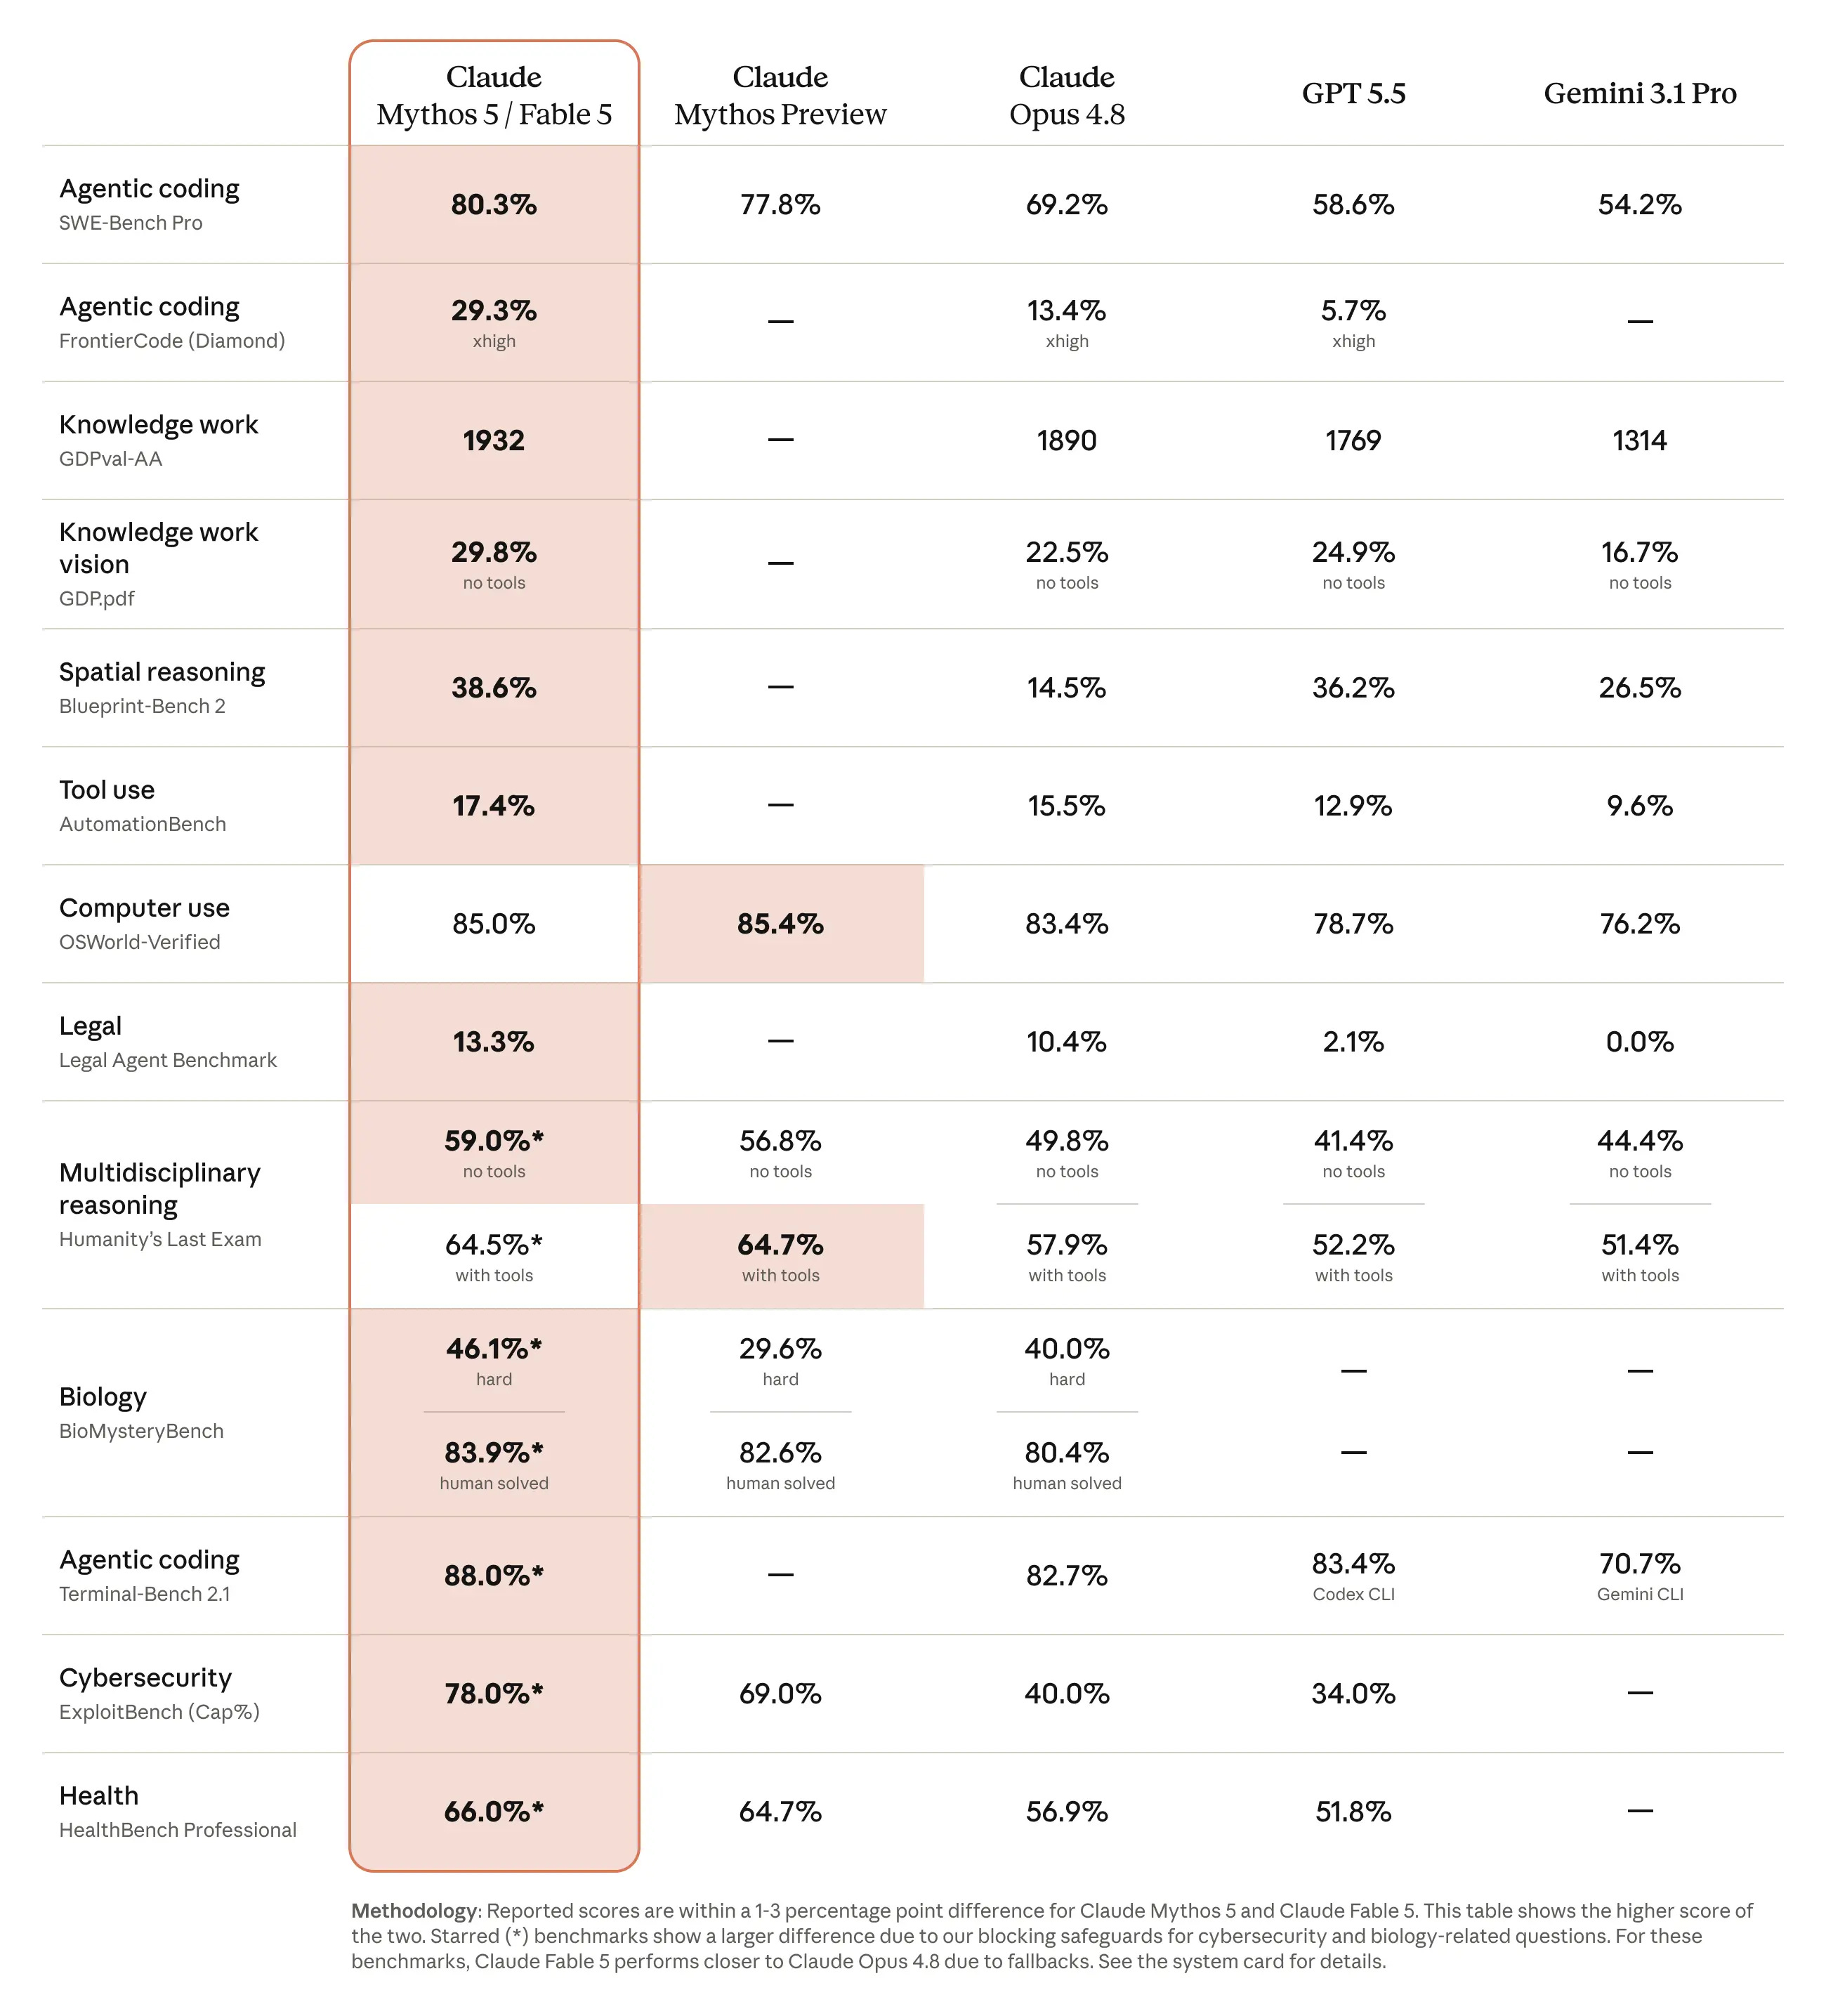
On Thursday July 16th, Moonshot AI released their latest flagship model Kimi K3. K3 is a 2.8T parameter MoE model which will have its weights released on July 27th. Much of this article follows as a reflection on the state of the ecosystem, under the assumption that Moonshot keeps their promise of the weights release date. This is a more extreme view of the equilibrium, and many of the results end up in a middle ground if the state of affairs is that China has similarly powerful, but closed models (i.e. K3 is never released).
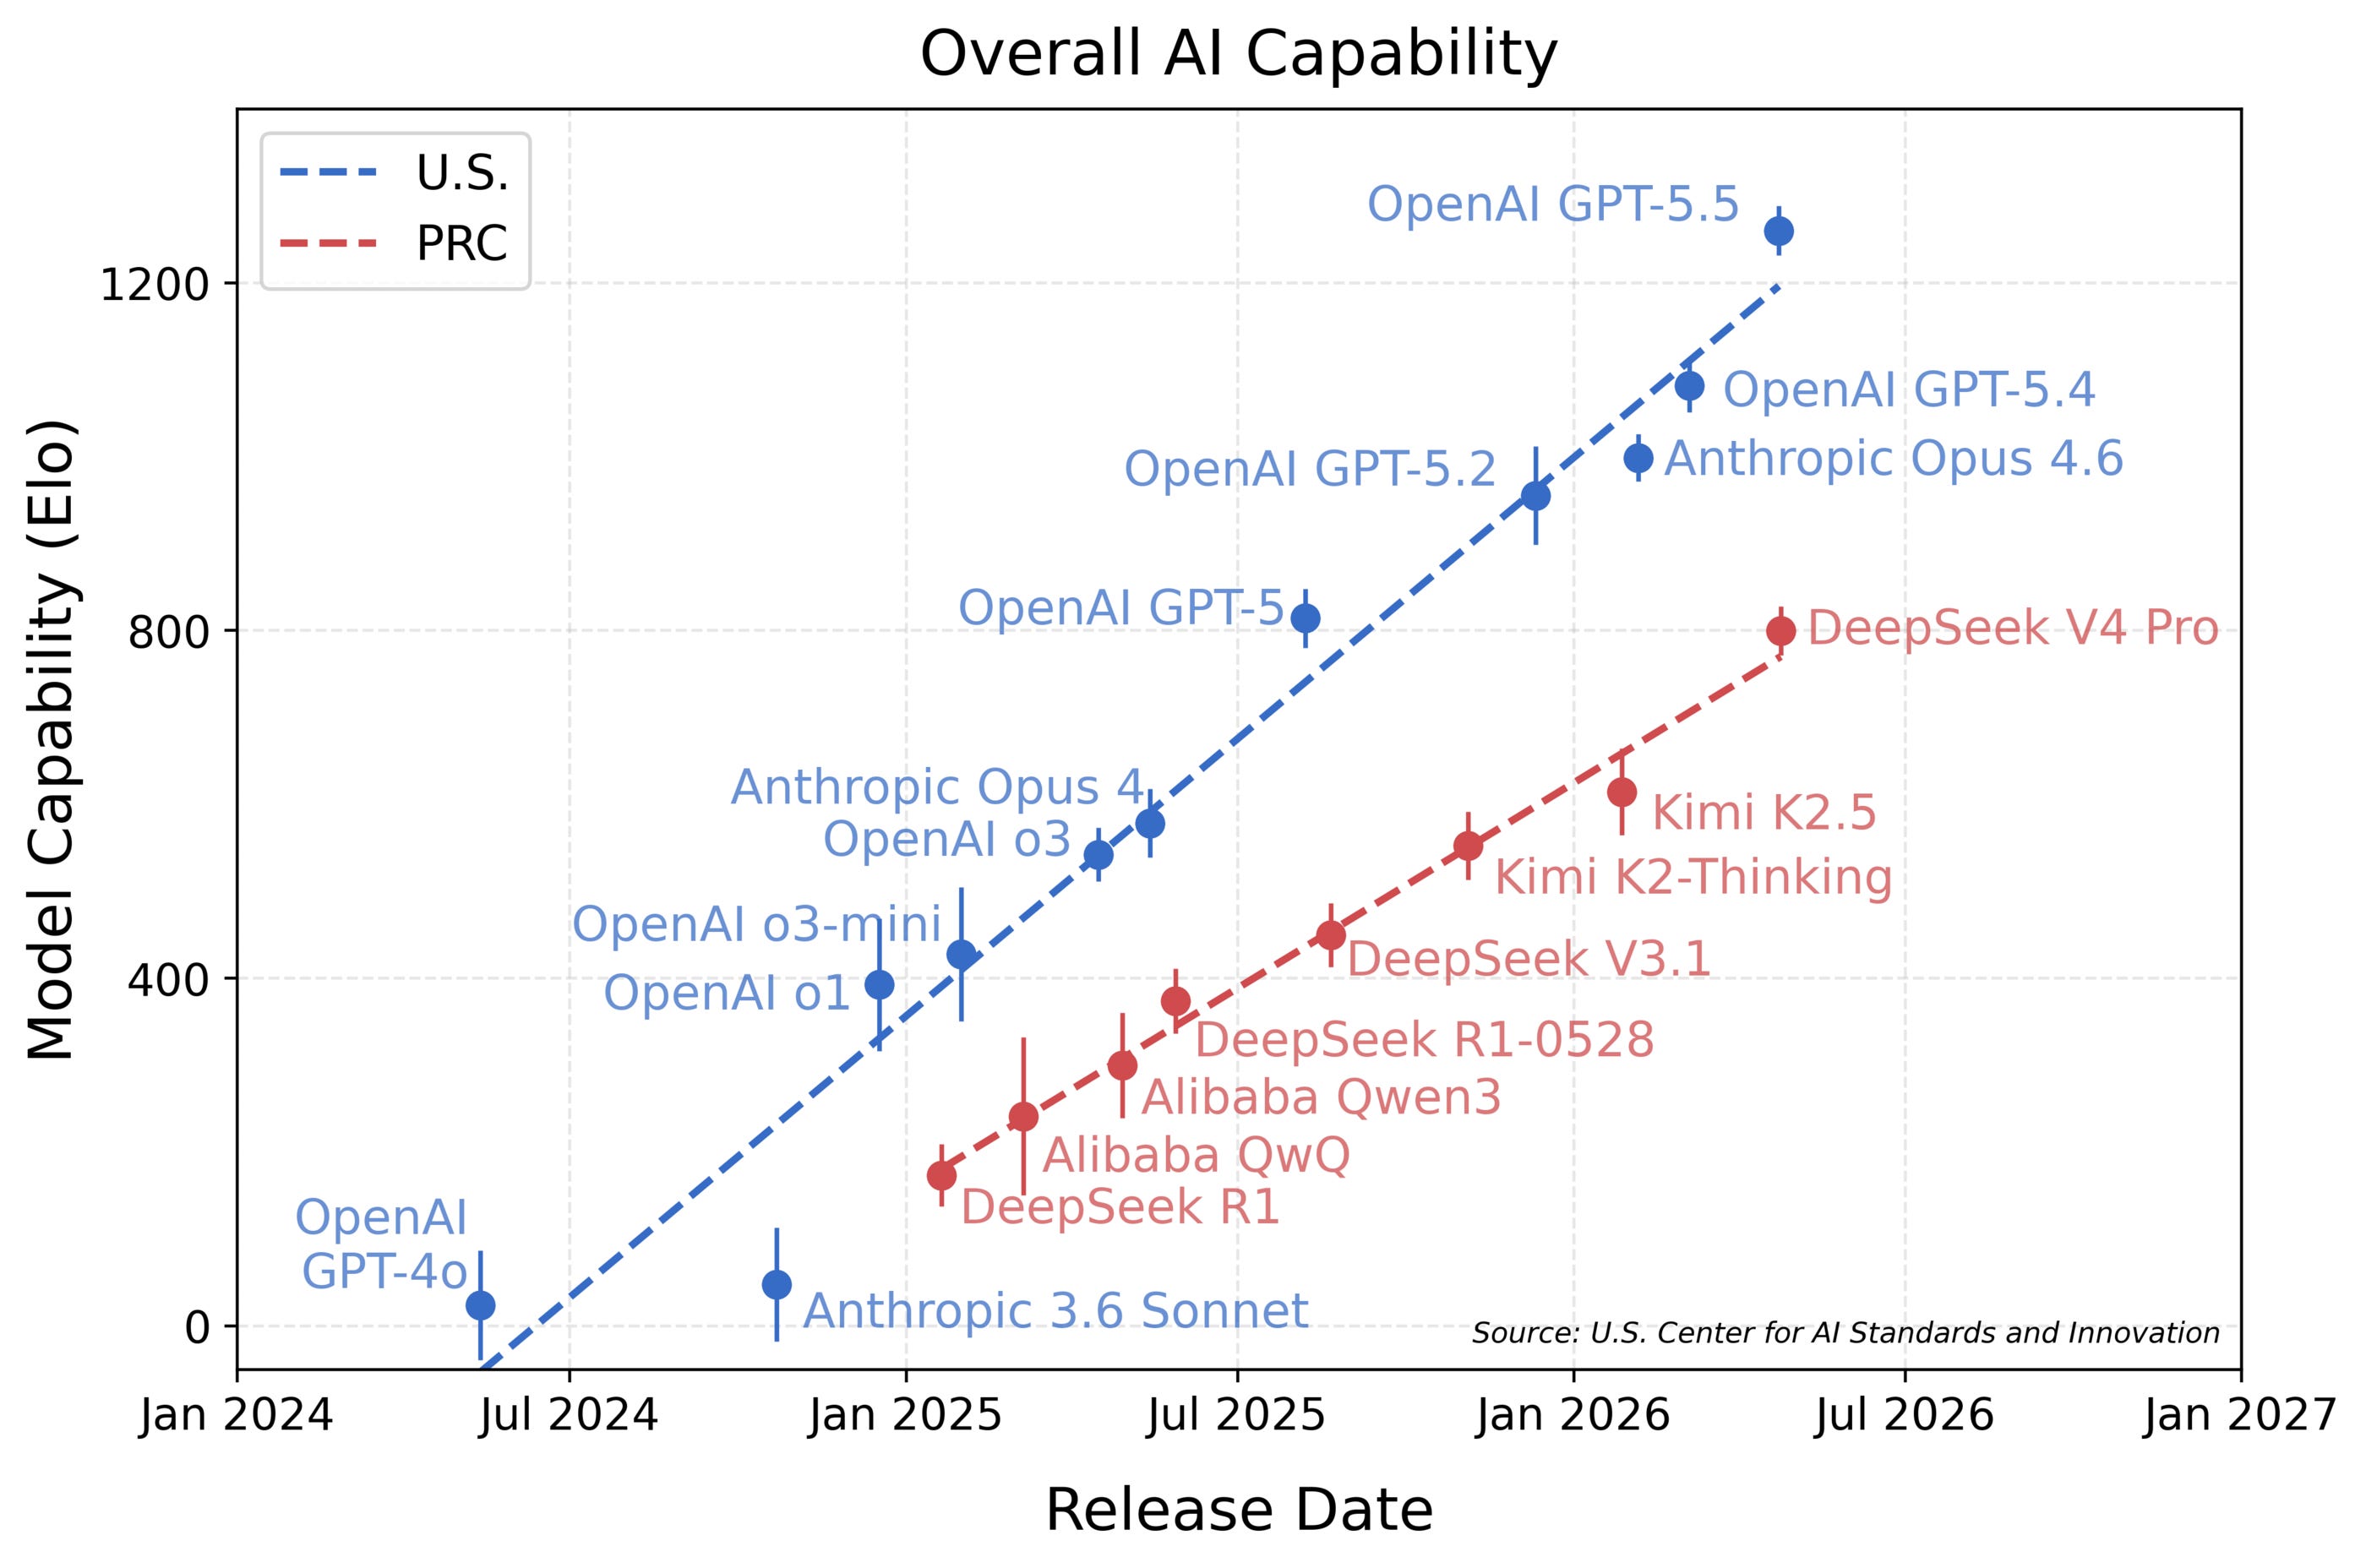
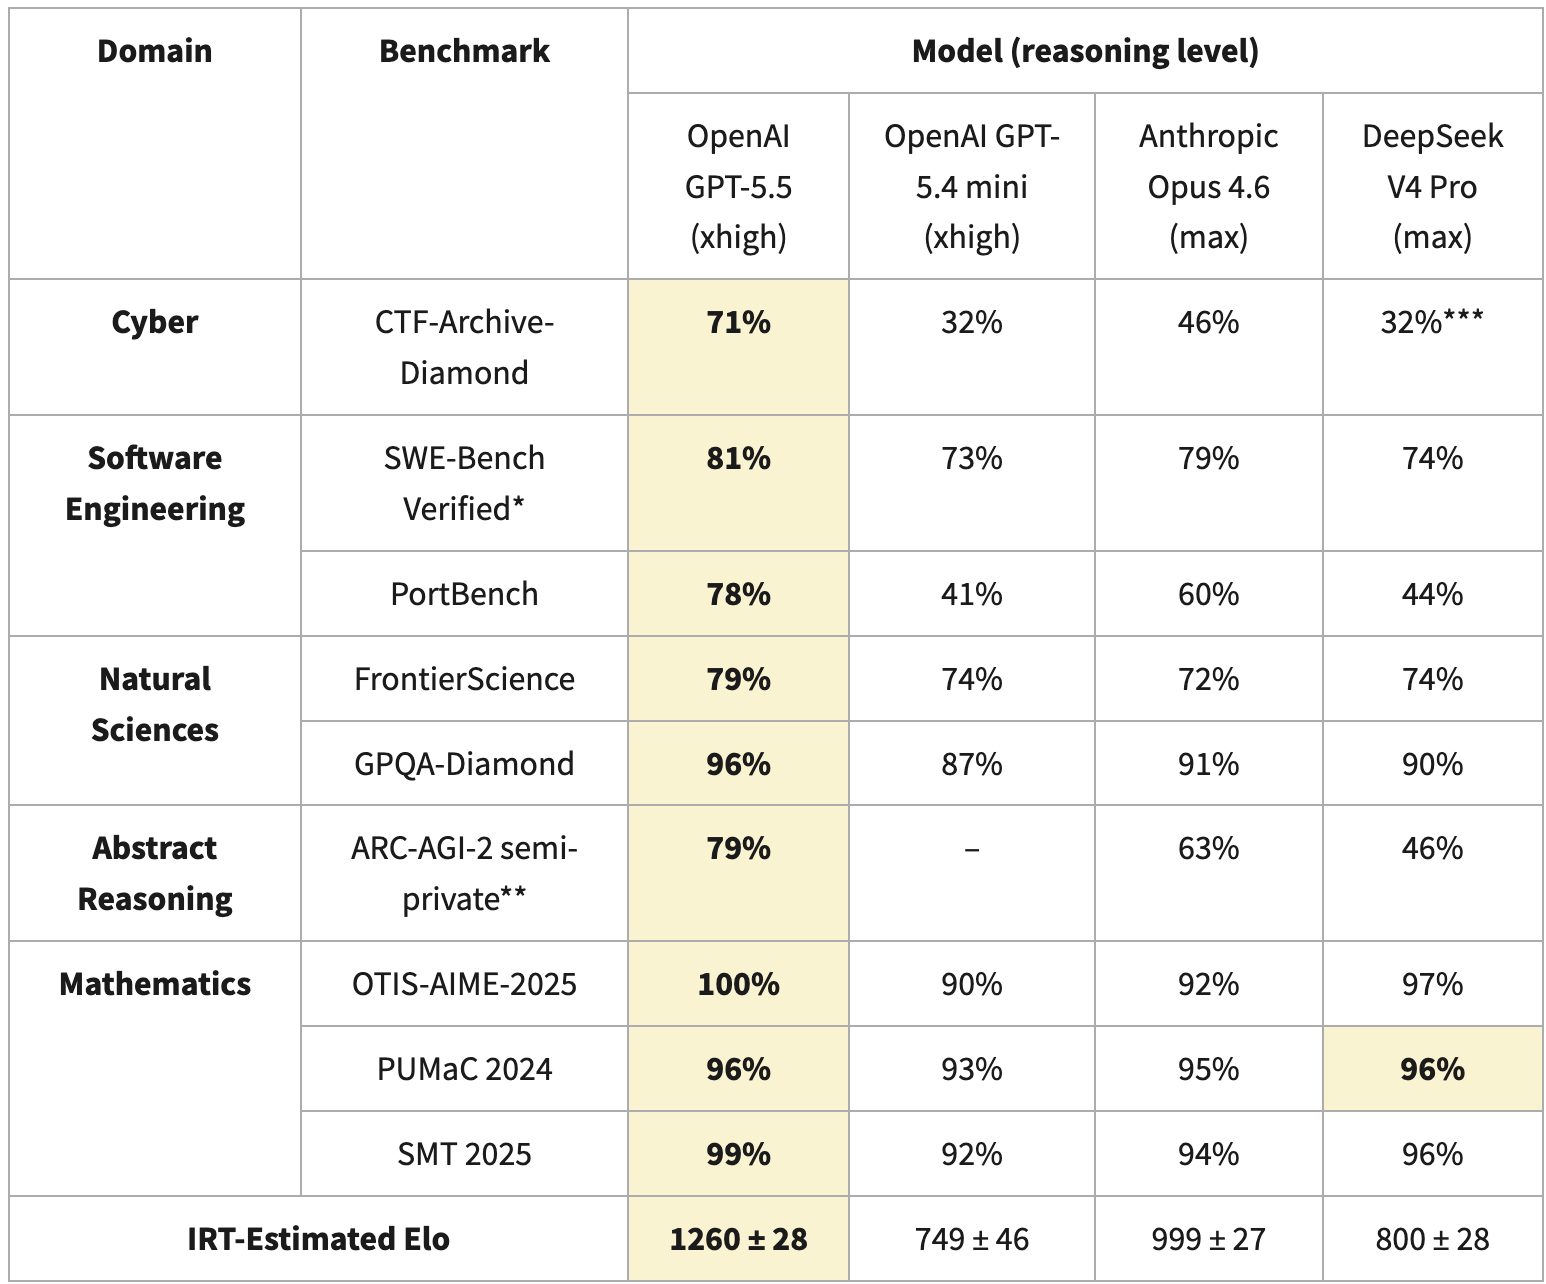
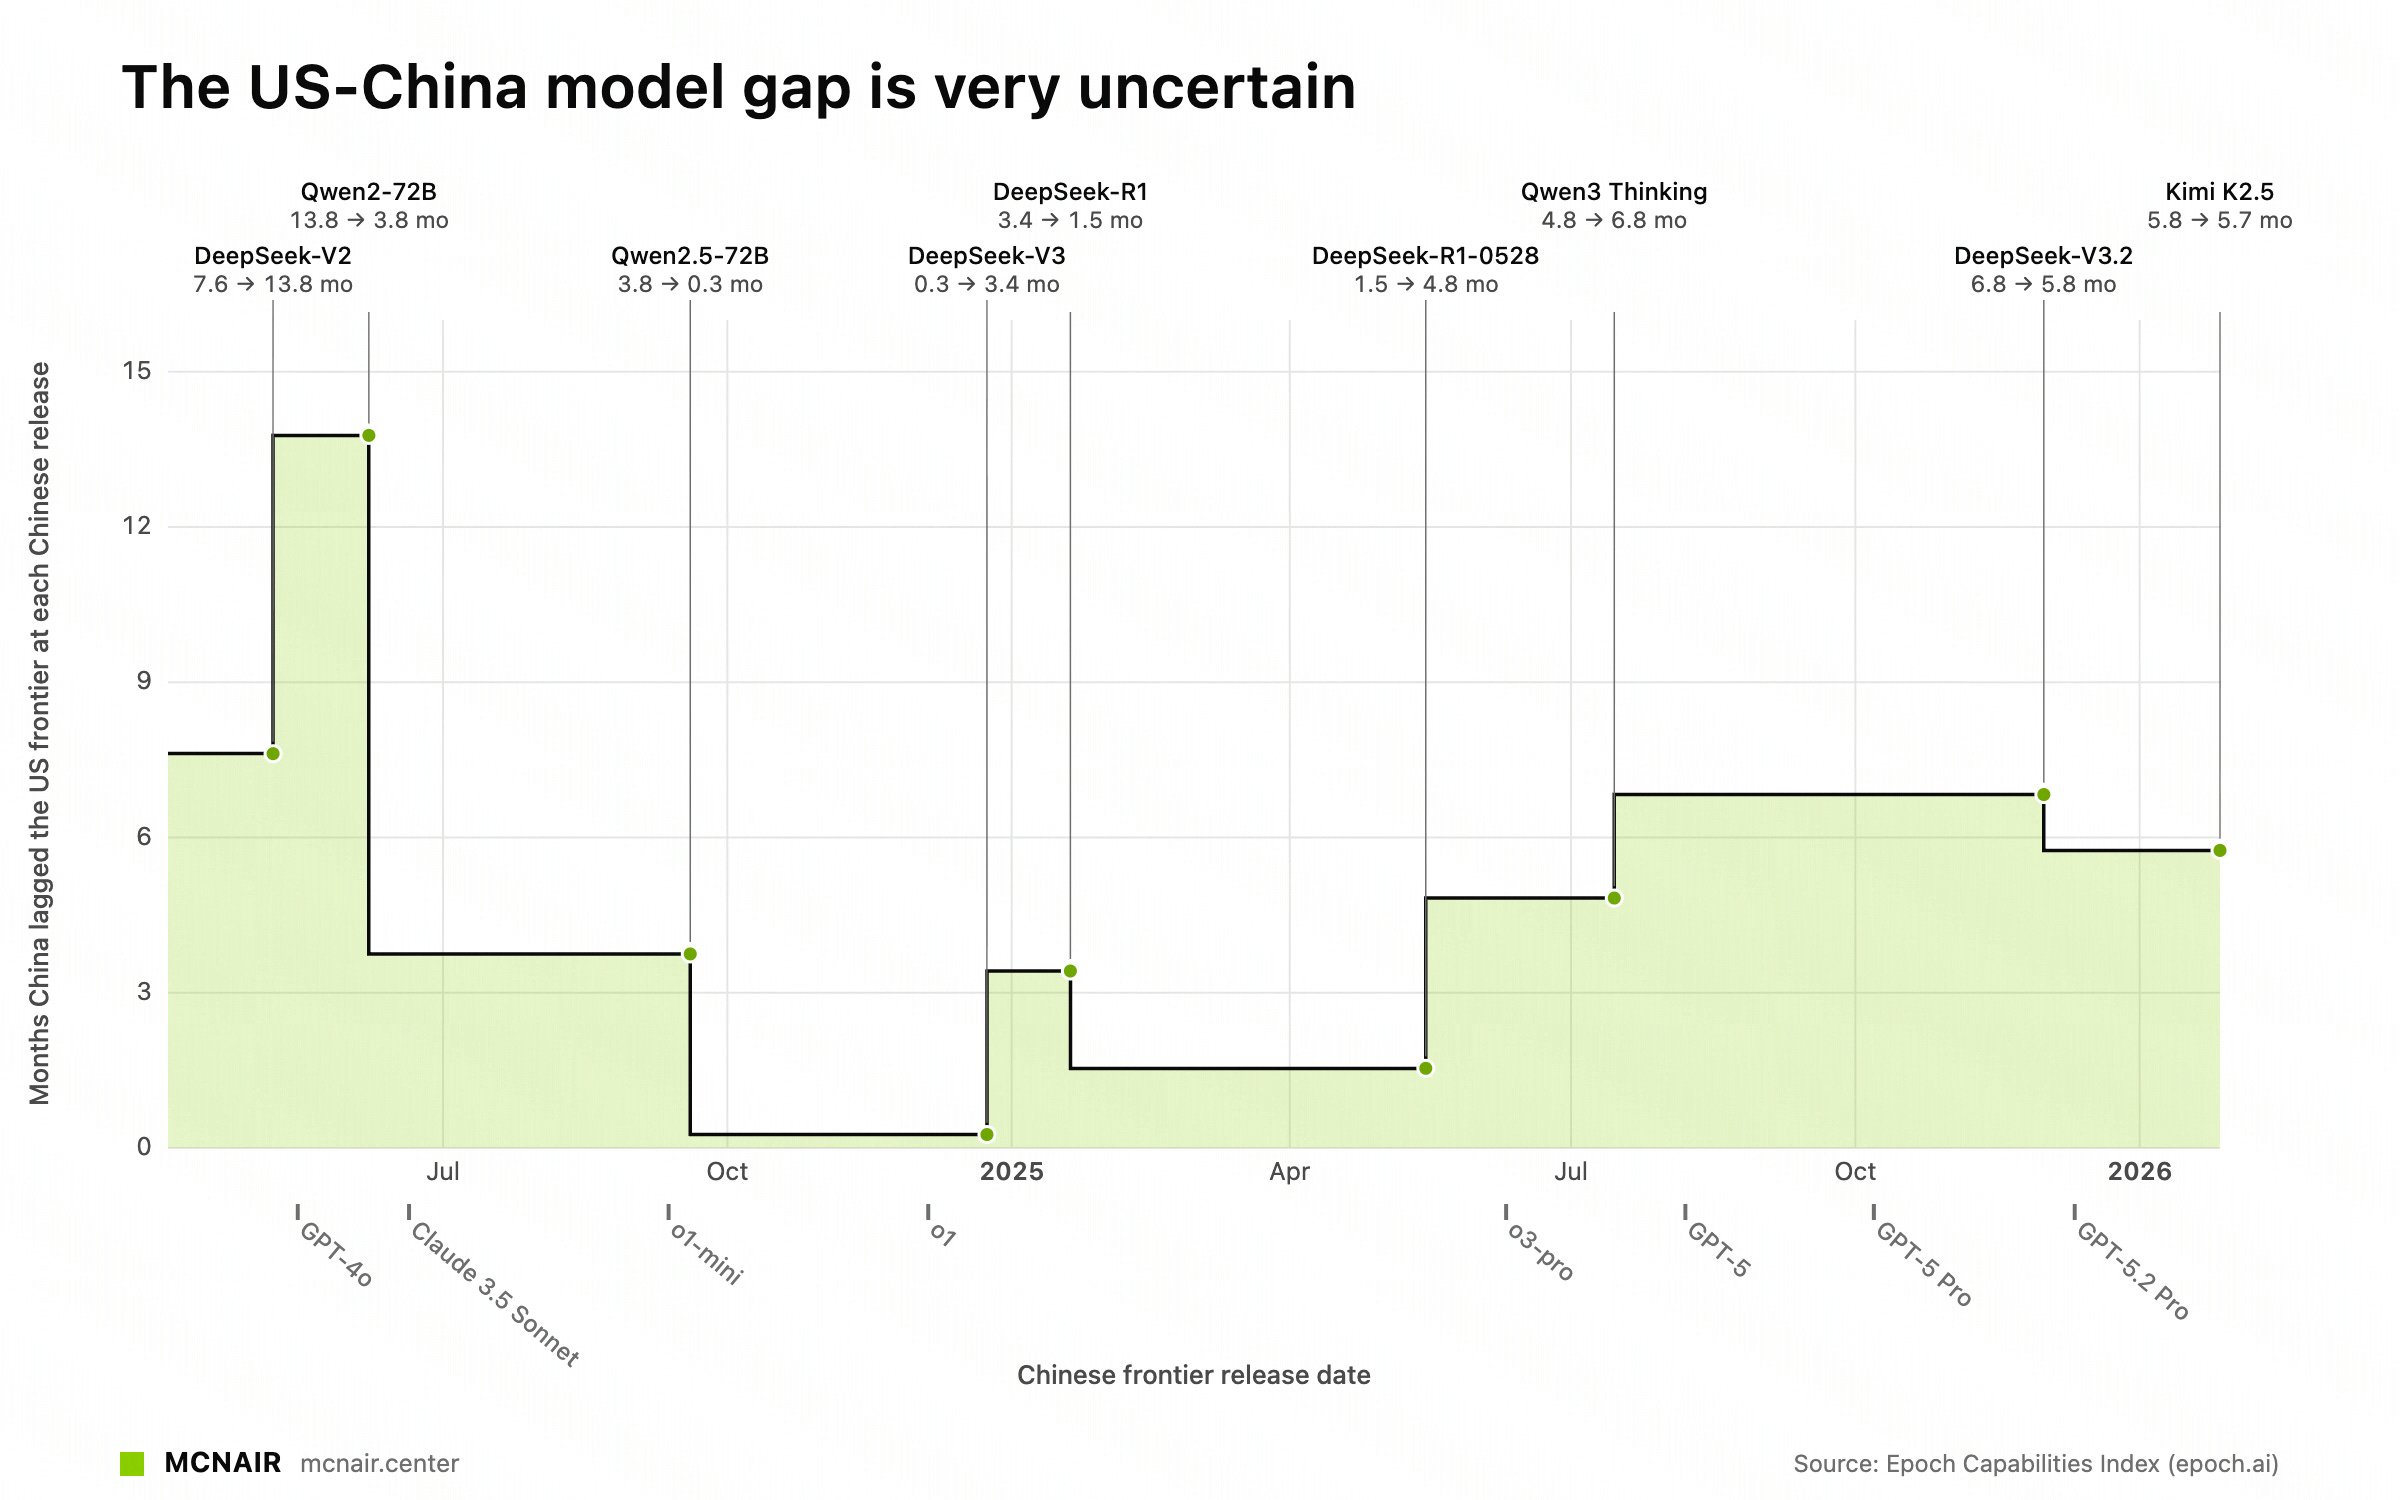
The key fact is that either the open-to-closed or American-to-Chinese model performance gap has been reduced from the debated 6-9 months to something shorter, say 3-5 months.
From the release materials, it is clear that K3 is a true frontier model. It will be the closest open models have been to the frontier since DeepSeek R1. DeepSeek R1 was a different story. This was a Chinese lab being extremely quick to pivot to reasoning models and release one faster than many American companies. Kimi K3 an example of a Chinese lab executing on scaling the known areas: data, algorithms, architecture, tools, environments, etc.
It is clearly the strongest open model ever released. It should be clear looking at this model that if adversarial distillation from the closed frontier models in the U.S. contributed, it is at most to a relatively small degree. AI observers who followed the distillation panic and came away with the wrong conclusion that Chinese AI labs are only producing good models due to IP theft are in for an awakening – that Chinese companies are extremely good at building models in the same way the leading American companies are. Moonshot AI is solving many of the same problems that folks at OpenAI or Anthropic are solving. I’m confident there will be more distillation discussion, and pressure, but the evidence is now out that Chinese companies can do more than just fast following.
Meeting some of the core Kimi team on my trip to China, it was clear to me that they had incredible culture, some would say aura, and a freedom to express it – within the constraints of a GPU-limited environment. Where building models is so much of a scaling game, much of the ability to build a good model still comes down individual execution, motivation, and expression. Having visited them, this result is less surprising. Having visited many AI companies, very few have a culture that you can immediately pick up like this.
At the same time, China’s AI adoption trends started later than those in the U.S. So, while all the Chinese labs have way less compute than their counterparts in the U.S., more of it can certainly go to training. When I joked around about how much compute an average researcher at OpenAI could have – say a few thousand H100 equivalent machines – the researchers at Kimi were shocked. The org chart and approach to building the Kimi models surely reflect this, but it is difficult to tease out what this looks like without substantial proprietary information.
The state of affairs on peak model performance is roughly as follows:
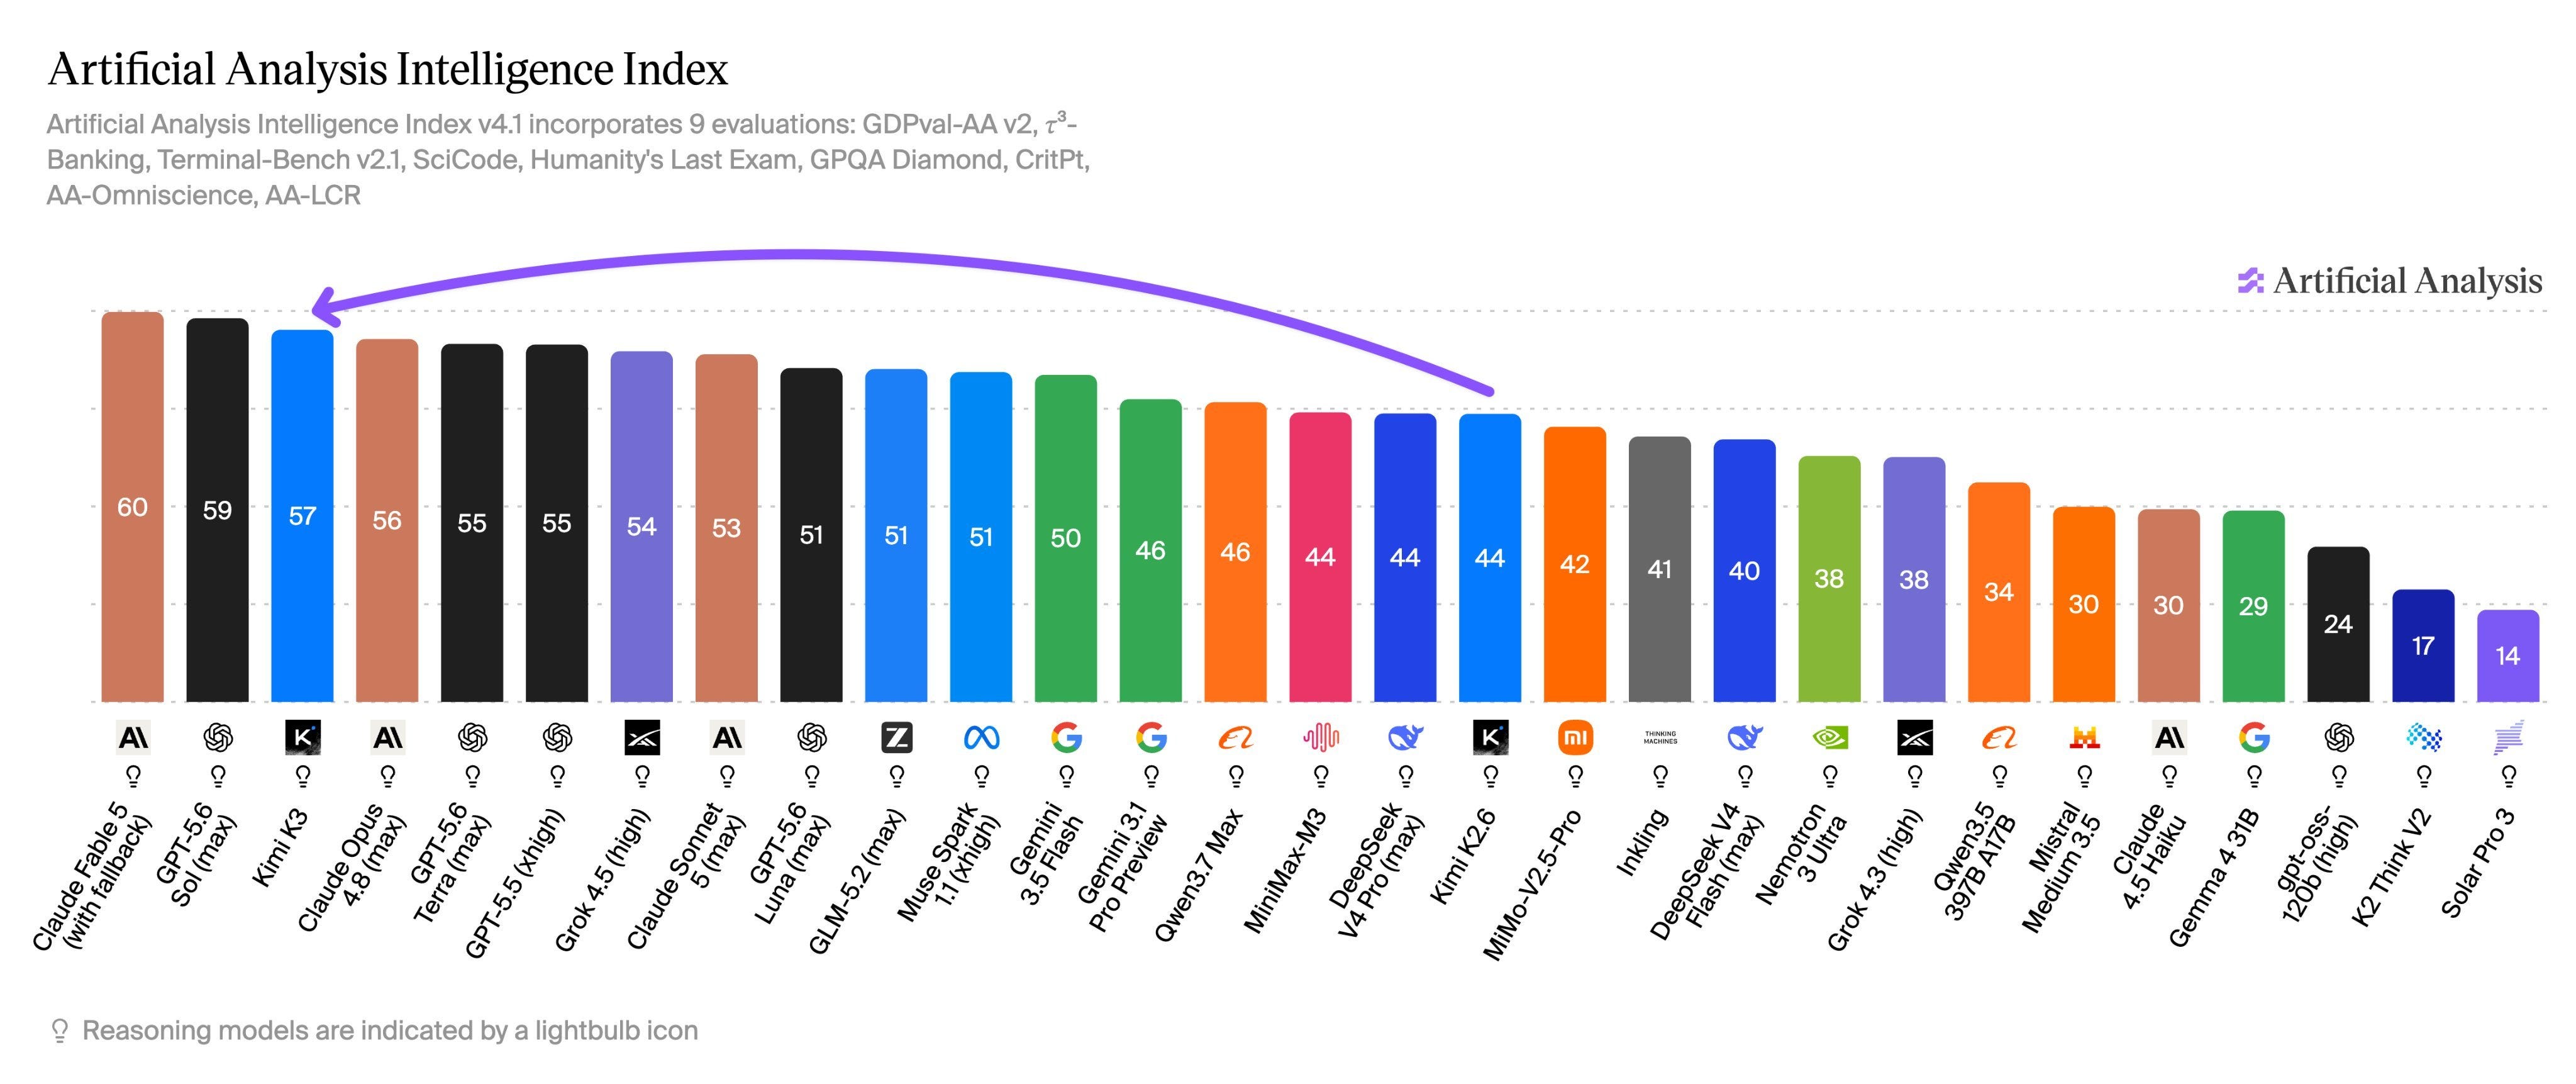
Anthropic – Claude Fable 5
OpenAI – GPT 5.6 Sol
Moonshot AI – Kimi K3 (open weights*)
SpaceXAI – Grok 4.5
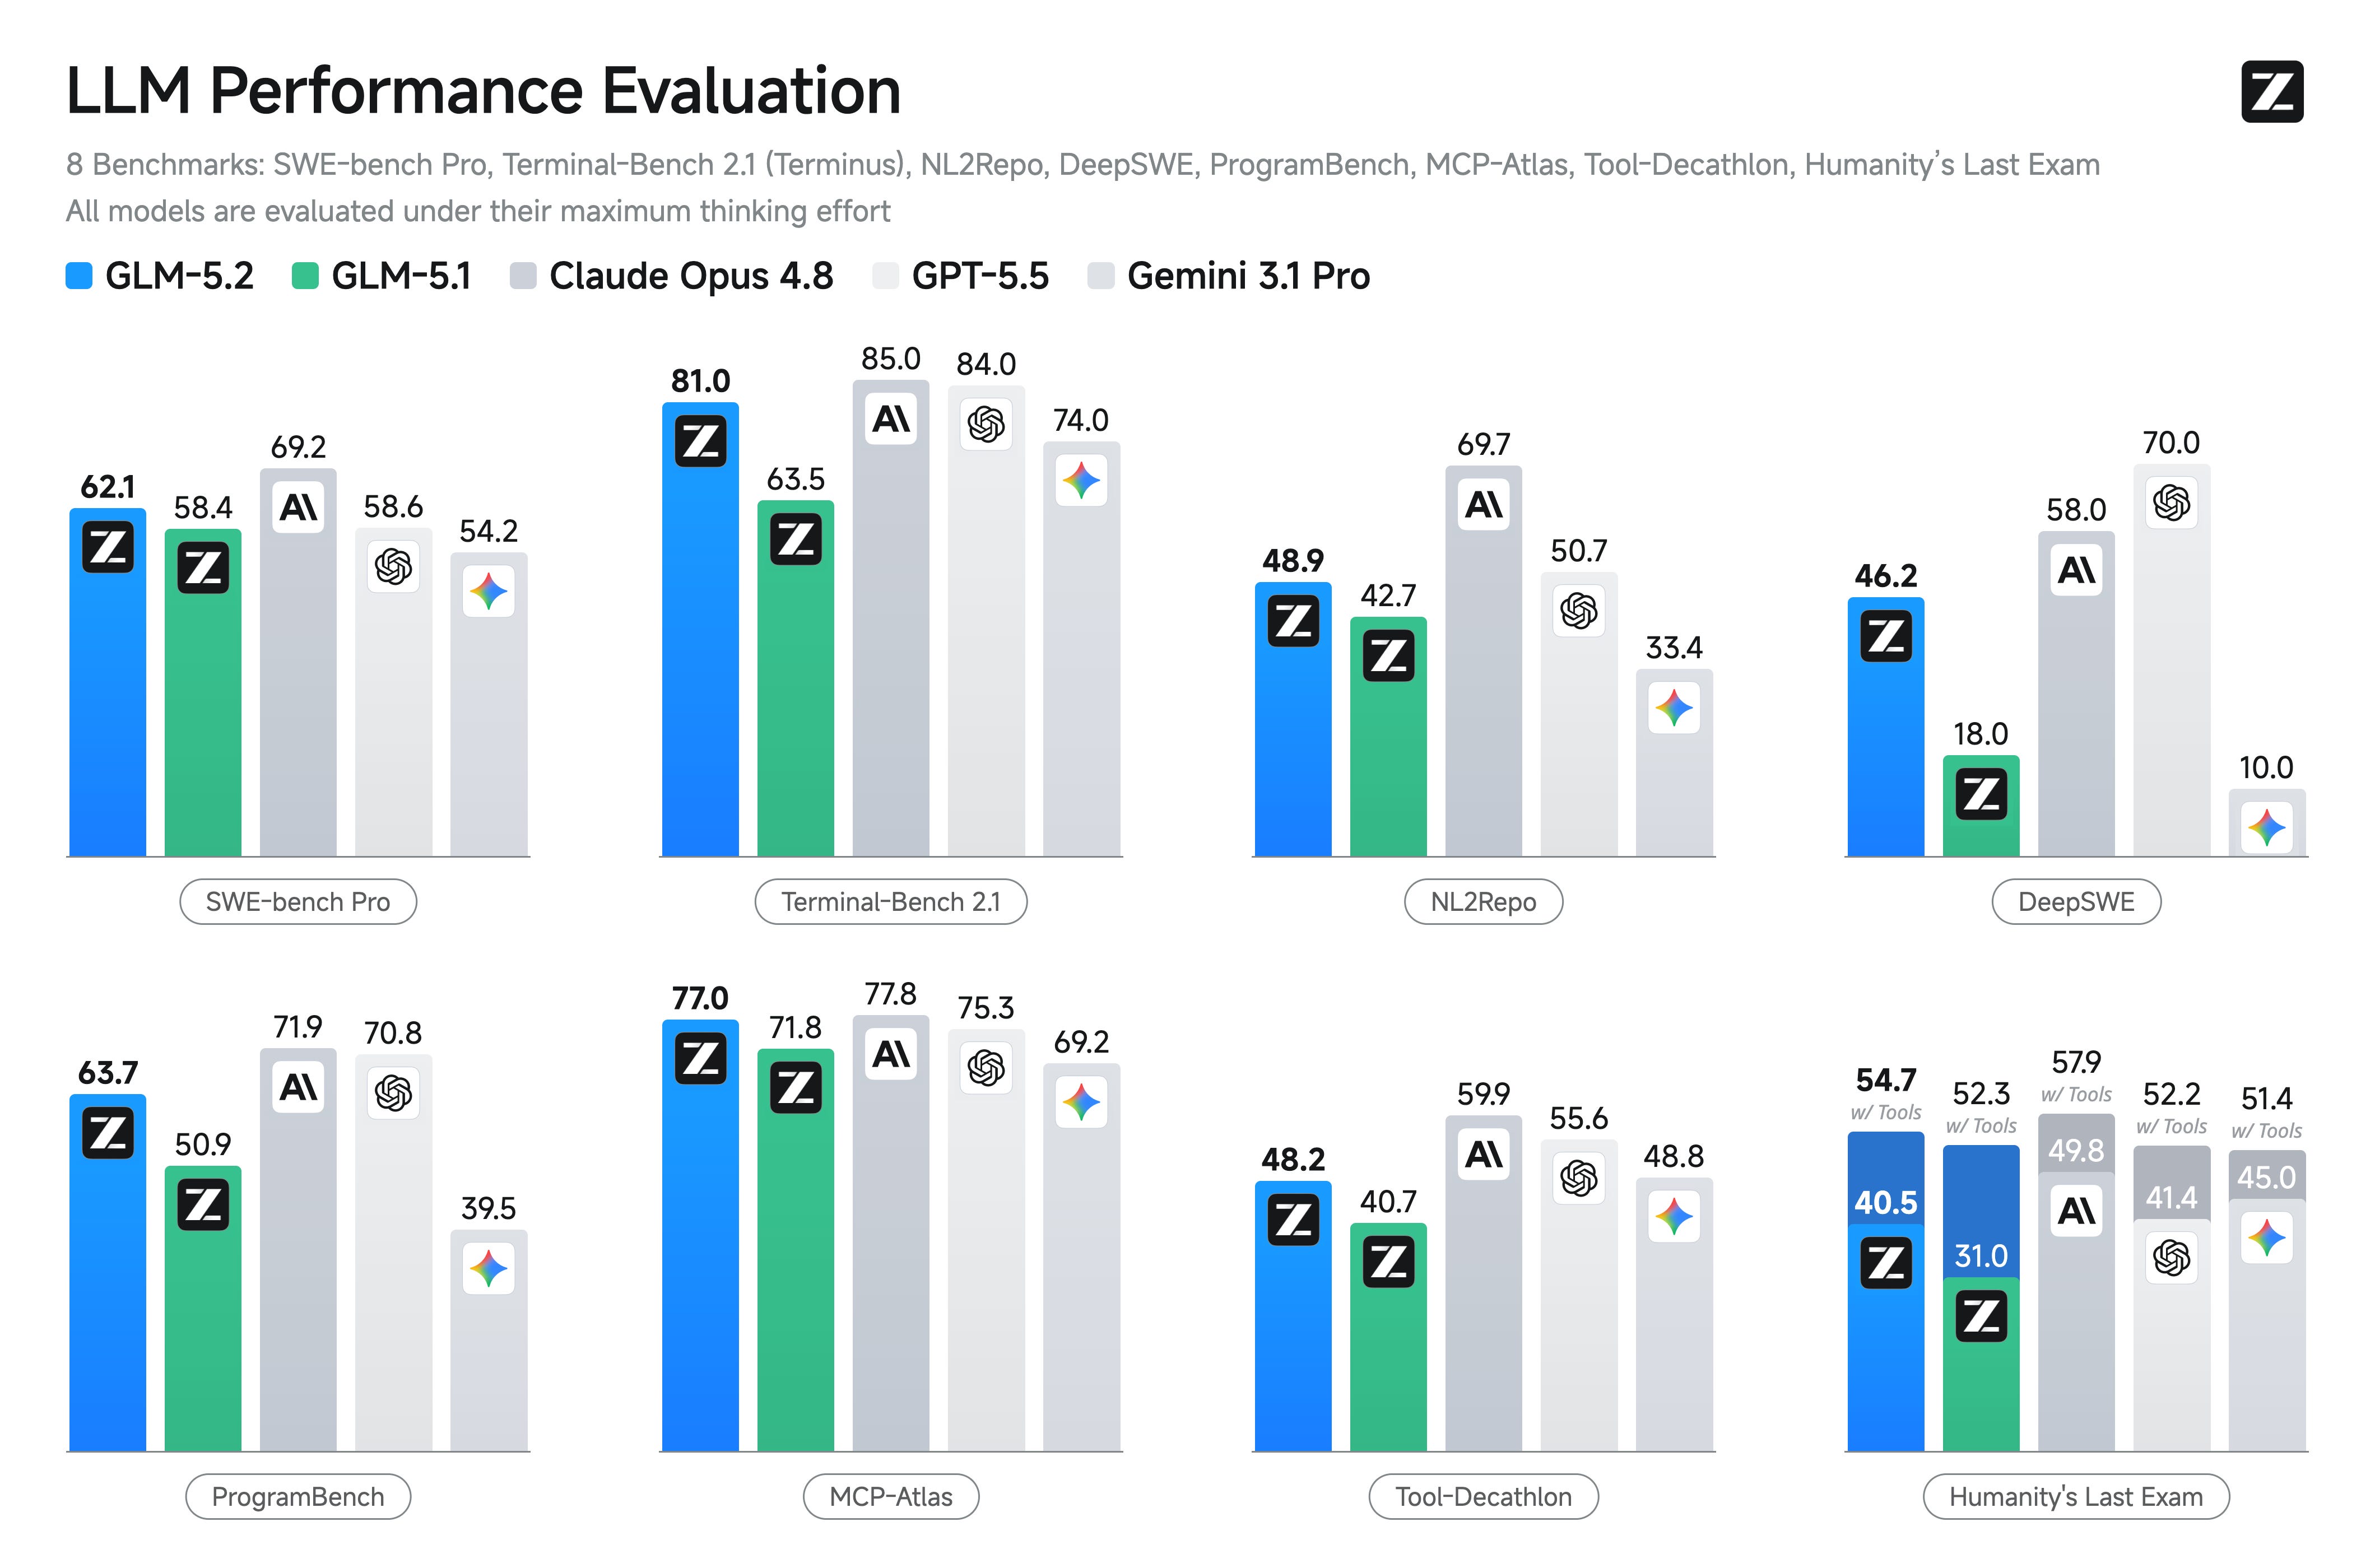
Zhipu (Z.ai) – GLM 5.2 (open weights)
Meta – Muse Spark 1.1
DeepMind – Gemini Flash 3.5
Alibaba – Qwen 3.7 Max (3.8 announced, also to be open-weights, when writing)
It is astonishing to see DeepMind, and some of the other American giants this low. In many ways, the X AI team deserves more credit. A visual summary from Artificial Analysis is below:
This release and other recent events have caused a major change in direction for the most likely outcomes in the balance between open and closed models. I’ll unpack them individually.
In many ways, it feels like the start of a new era. An era with much more competition, but also a much higher need for coordination, as we rollout incredibly powerful technologies around the world.
1. China’s recommits to open-source AI – showing a different read on near-term risks
Many people started following China’s AI scene relatively recently, so they can reach the conclusion that releasing models openly is their core strategy. In fact, I think most labs have a core strategy far closer to Anthropic or OpenAI – build the best intelligence possible. Having followed and engaged with the Chinese labs for years now, the best explanation for their original turn to releasing their models openly is practicality. They needed to release the models openly to get adoption, attention, and feedback (especially in the high-value, Bay Area market).
For a long time, there had been very limited policy in China explaining the role of open-source AI, and what could be the “country-level strategy.” To my knowledge, no senior leaders had commented on open-source AI publicly. This changed this week too, as Xi Jinping gave a keynote address at the World AI Conference (WAIC), and very directly committed the future of China’s AI ecosystem to open-source and global diffusion. This commitment to the status quo, the same week as the announcement of the strongest open-weight model to date, is a clear mark in the early history of modern AI.
This comes during a time period where many potential paths forward have been discussed for the Chinese AI industry – Will they stay open? Can they keep up with the American labs in scaling? Is there a growing revenue market in China? With these, the focus has been on China’s risk tolerance, the companies’ ability to monetize, and any closely related reason for a company to stop releasing their best models openly.
In tying Xi’s commitment in time to a very strong model, China has implicitly commented on its risk tolerance with respect to releasing open-weight models. For the time being, it is a read into the perceived risks of topics like strong cybersecurity capabilities (or bio-dangers) within the Chinese system.
The simplest explanation is that China’s government is definitely following potential risks from the models closely – likely with more technical scope than the US government’s vibe regulation – and would take action if it measured risk. The simple explanation is that they do not find current frontier models to have meaningful risk.
At the same time, China’s economic decision makers think having AI adoption is good, so they can make profits on the industry later – after growing distribution (as China has done for cars, solar, advanced manufacturing, and many areas in recent history).
These can seem somewhat shocking, in an American AI media landscape that has gone through months of hype and fearmongering over the Claude Mythos model. This surprise should be excellent grounding – the world does not have a unanimous agreement with the narratives about AI that we hear most in the U.S.
2. Open models as the economic Achilles heel of frontier labs
Many of the narrators guiding the discussion on AI have clear incentives to depress the perceived capabilities of the best, open AI models. Dean Ball – who is personally supportive of open models, but now works at OpenAI – had a widely commented on post with some reflections on Kimi, where he said the following on open models. It is important to understand the statement, as it focuses the role of open models in the economic side of the AI buildout. Dean says:1
Open-weight models are inherently decelerationist, and I’m continually surprised to see the so-called “accelerationists” so excited about open-weight models.
Explaining why open-weight models are a form of decelerationism is important to understanding the coming world order. He is right.
Open models are decelerationist economically for the frontier labs, which will slow the net investment and capex rollout for AI. This is due to the fact that strong open-weight AI models massively reduce the margin potential for the closed labs. This has two effects. First, the AI labs have fewer profits to re-invest into future models. Second, the market sees the terminal value of these companies as being lower, so they will kneecap future fundraising rounds. These together will slow timelines to the most transformative AI models, but I do not see them as strong enough effects to stop OpenAI and Anthropic from being a few of the top valued companies in the world.
These, to me, are a net good for society. As open-weight models are accelerationist for AI diffusion across the economy by having the entry price for intelligence at a certain level of performance be lower. Open models also encourage customization. The thing is that this type of diffusion is by its nature far slower than the frontier AI labs products, who sell tools used directly by developers. The potential for open models is for nearly every business to use them to craft domain-specific agents. This economic diffusion takes an extremely long time! I’ve described this as open-weight models being on a much slower starting, but potentially bigger exponential. The problem is, if closed models get too far ahead in raw capabilities, this ability to customize can be moot.
The combination of increased diffusion and decreased concentration of power in the AI labs I see to be very positive for the AI transition. It gives us more time to figure out the hard problems of new capabilities and lets more stakeholders impact the story – any one company is very likely to have issues with controlling the world’s most important technology safely.
It is, of course, important to me in this world for the best models to still be made by the U.S. companies, which will allow the US to control the trajectory of the technology and its values. I also expect this to be the case, as the U.S. has larger capital markets that are willing to invest in AI (and a growing share of profits), but it is not a given.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
3. China’s efficiency advantage
Kimi’s launch blog has some technical details that confirm the sort of improvements that are supplying the consistent model improvements we feel. To select one:
Kimi K3 is built on Kimi Delta Attention (KDA) and Attention Residuals (AttnRes), two architectural updates designed to improve how information flows across sequence length and model depth. We have also scaled up Mixture of Experts (MoE) sparsity, effectively activating 16 out of 896 experts when paired with a Stable LatentMoE framework. Together with refined training and data recipes, these structural changes yield an approximate 2.5× improvement in overall scaling efficiency compared to Kimi K2, allowing the model to convert compute into intelligence more effectively.
Training efficiency really adds up. They will result in continued, incredible steps for the models.
As an aside, tracing the path of this particular innovation through the ecosystem is an interesting example. Kimi Delta Attention (KDA) was introduced in the Kimi Linear paper, which is similar to the Gated DeltaNet used for Olmo Hybrid (my last Olmo model while at Ai2). Qwen’s latest models switched to a related architecture and the recent Nemotron models also are hybrid (but still closer to Mamba than Gated DeltaNet). It’s awesome to see new architecture ideas like these, which were heavily progressed by academia, get so quickly translated into frontier-scale models. Gated Delta Networks were introduced in late 2024, building on ideas from Mamba. By mid 2026, they’re in frontier models.
I chose to focus on this example, partially because the Kimi team put a cool number to innovations between models, but primarily to give space to a broader discussion of China’s resource efficiency.
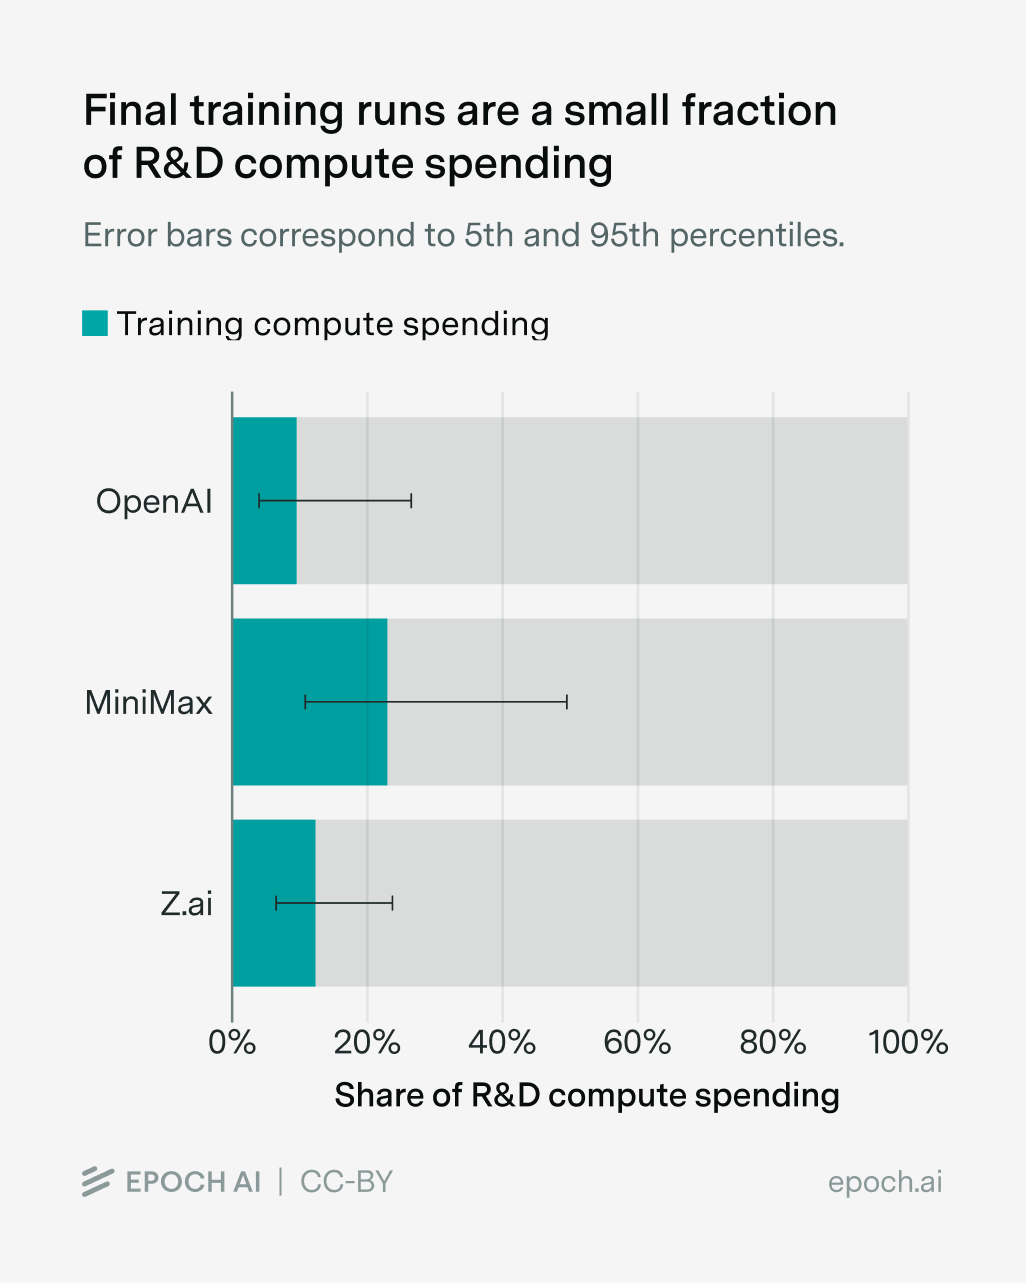
It is becoming clear that the Chinese labs are far more capital efficient. In a world where scaling laws dictate that intelligence is proportional to effective capital – which buys compute, data, & talent – that may be the greatest strength your AI industry could ever have. There are many possible explanations for why this is the case, such as Chinese researchers being paid less while being more effective at LLM research puzzles, but we will probably never get such specific reasons.
Since writing my notes on China, I’m hearing more about an emerging data industry in China (far behind the billion dollar budgets of Anthropic for data) and that Chinese labs have access to meaningful training compute (by skirting export controls). Chinese companies do not have the same inference demand (until recently, as Moonshot AI had to pause new subscriptions for access to their K3 model - while the API is still live), so much more of their compute could go to training. These areas impinge heavily on the truth of the ability of the labs, but we have very limited measurement into them.
The facts on the ground are that these Chinese labs have raised orders of magnitude less capital than any slice of the American AI ecosystem. The most direct comparisons are to OpenAI and Anthropic, who have slightly better public models. Others, such as Google and Meta have the largest cash flows in the history of business, and are behind on building models. As for American neolabs, the picture is even more competitive – Thinking Machines released their first model recently, Inkling, which is strong but not in the same class as Kimi K3.
These American companies with more resources could still catch up, but you need to strongly weigh the public measurements we have of model quality and not resort to hope – which often reflects a bias. If the Chinese labs do have a latent advantage, they could continue to utilize that to build even stronger models than all the competitors! Many outcomes are plausible and K3 should increase most people’s probability that China can outright lead in AI capabilities in the near future on the back of more efficient training efforts – even if it’s not your most likely predicted outcome.
A big contributor to the capital efficiency is likely in the approach, where American labs are spending meaningful energy in pushing the frontier in dramatic, big steps, and the Chinese labs are more focused on catching up — this catch-up is cheaper. Just as the student model can outperform the teacher in distillation generally (not limited to the adversarial distillation of the Chinese labs), an approach of “trying to catch up” rather than “invent the next paradigm” could lead to stronger models.
4. A growing ecosystem of frontier, open models
The weekend after the Kimi K3 release, while writing this and discussing the events broadly, Alibaba announced that a 2.4 trillion parameter Qwen 3.8 model is coming soon with open-weights. Historically, Alibaba has kept their largest models as API-only offerings via their cloud business, so this is another big vibe shift opening the doors to the next chapter of the open model economy. Even if the model is behind Kimi K3 on benchmarks, it signifies that Chinese companies may not only be maintaining the status quo for their open model strategy, but leaning further into it.
If this Qwen 3.8 model releases soon, i.e. before the next Gemini model, it could push Google to the 8th position on the leaderboard of labs with the smartest models – a list that China has been climbing. There are other rumors of more strong Chinese models soon, with DeepSeek V4 expected to graduate out of it’s “preview” version.
5. The very beginning of a long story of frontier open-weight policy
I think that if Claude Mythos was released as an open-weight model today, the negative outcomes would be relatively minor. This is a somewhat challenging opinion to hold, as we have very limited public cybersecurity evaluations and it is a complicated ecosystem (and because I trust many people at Anthropic). I still stand by it. The risks have been over-hyped.
The problem is that this will not always be the case for the strongest AI models. Far stronger models are coming — and with them increased risks — so it is an incredibly safe equilibrium for the best models to be accessed in a controlled, closed manner several months ahead of similar open-weight models.
Open-weight models which are very controllable by the user will always be coming — you cannot effectively ban digital products, especially from bad actors — as AI training has proven globally accessible longer than many analysts expected.
Behind the scenes: The Commerce Department last year considered adding multiple Chinese AI labs to its “Entity List,” which would effectively cut off U.S. access without a license, a source close to the administration told Axios.
The National Security Agency and White House Office of the National Cyber Director also considered putting out an advisory on Chinese AI lab threats last year, practically discouraging U.S. companies from using their tech, the source said.
The White House considered implementing an executive order saying U.S. companies could only host Chinese models if they could guarantee security and take liability if it were breached, the source added.
Commerce last summer also circulated draft rules within the administration leveraging its authorities to secure domestic supply chains to target Chinese open-source models, another source close to the administration said.
This would leave the U.S. in a very asymmetric state where the best models in the U.S. have guardrails on cybersecurity tasks, but global actors have access to great Chinese open-weight models to probe our defenses. This is one of many examples where banning open-weight models is not only harms the free markets of AI but also makes the ecosystem less safe in the short-term. There are other very bad outcomes, such as slowing the diffusion of AI applications and AI research, as I discussed above.
These equilibriums are very hard to maintain, especially as AI tools accelerate progress in the models, but it is important to maintain this status quo between open and closed. Having a model that is truly alone at the frontier in capabilities — something like Mythos when it was announced — also be open-weight poses serious risks as we go into the unknown of capabilities. Models are going to progress very fast and it is increasingly hard to measure their total capabilities.
We are then stuck in a world where we are trying to thread the needle on open models. It’s reasonable to not want something so powerful to be diffused globally in an instant, but meanwhile the makers of the models are incentivized to hype their capabilities, and their competitors are incentivized to hype their risks. It all comes down to careful measurement and proactive hardening of society to risk vectors.
This careening train of policy debates, model releases, and raucous reactions is only going to continue from today. We’ve been on a train of rapid progress, where all the key ideas of how AI should play out are tested, since the release of Claude Opus 4.5 last December, which sent us down the agentic pathway. The key to making good decisions here is evaluation capabilities, independent of the companies with the largest financial stakes. One of many actions needed then, as we enter the AGI era of AI governance, is an Operation Warp Speed style approach of bootstrapping state capacity (and other independent actors) that can evaluate models accurately, and study emerging risks.
Conclusion: The wake-up call
Open-weight models, by accelerating the diffusion of capabilities, are a massive escalation in the good and the potential bad of AI. For now, the bad side of frontier language models has been largely hypothetical, but that will not always remain the case.
Having open weight models be slightly behind the closed frontier is our natural buffer to mitigate the risks. The key point is that we must collectively act to mitigate potential harms as they appear, and whether open-weight models are 3 or 6 or 9 months behind, that is still a very short timeline. If we regulate open-weight models heavy-handedly, I suspect much of the world will be lulled into thinking we no longer need to act. All we would’ve done is slightly delayed the inevitable — open models will continue to cross all the key capability thresholds eventually and regardless of legality.
Understanding and benefiting from this open-closed dance must be a collective action from the AI community across all sectors of power and influence over the coming years.
Kimi K3 is a watershed moment because frontier open-weight models are now real. Many hypotheses will be tested on where risks of open-weight models truly land — I suspect it’ll be narrower than many expect, and many risks of AI will still be proliferated by closed and “safer” APIs. The evaluation of these risks will evolve in time with an acceleration of AI’s integration in our economy. We cannot get one without the other, and we will continue to get both.
With this, 2025 was when open models started to be taken more seriously — especially when China leaped ahead with such a clear lead — as people realized that it would not be a unipolar world, with only American, closed AI labs determining the trajectory. 2026 is when those previously discussed, potential risks and accelerations due to truly frontier, open-weight models landed.
A large portion of the response was for the fourth bullet, which compared the inevitable outcome of open models to AI communism, which I think missed the mark. Specifically, the use of the word communism without explanation caused much of the blowback.
The most serious test to date of open source AI’s viability is happening right now. I’ve seen many waves of anti open-source AI rhetoric come and go since ChatGPT was launched, but none of them had obvious analogues in their potential enforcement to real action already in place targeting the peer, closed models of the day. It is more real because new forms of regulation are being tested and implemented, with minimal oversight. I will be doing far more policy-facing writing than usual until this passes.
As of writing this, many sources are citing White House discussions on how to manage open models via a new executive order. There is no official information here, and it would likely impact a) Chinese-origin models and b) government uses only, but this is how the dominoes start to fall.
Open models lack the central economic champion to represent the potential downside of action against them. From recent coverage of the events surrounding model licensing agreements for Fable (and then GPT-5.6), more was said about what unfolded on June 9th:
At the meeting, the topic of how the program will deal with open-source AI models came up, according to a person familiar with the session. A representative from Reflection AI, a U.S.-based open-source model provider, argued that open-source models should have exemptions from the framework based on their capabilities, the person said. Currently, Chinese open-source models such as DeepSeek have a substantial lead over other available open models, and Reflection has not yet launched a public model.
A ban of any form here would be a big mistake for the long-term trajectory of AI.
The most likely incoming action is to ban or indefinitely delay any open-weights model meaningfully above the capability level in the range of GPT 5.5, Claude Opus 4.8, or GLM-5.2. With the consistent capability gap, this should be within the next 6 months.
As it stands, these would most likely be from a Chinese company, which is how this conversation of frontier open model capabilities inextricably becomes linked to other issues such as distillation. The capability threshold for a “right to review” from the government will shift over time, but once in place will likely progress far slower for open models rather than their closed counterparts. This is partially due to closed models being easier to secure but also due to the closed model companies having far more effective lobbying.
So, this leaves us in a place where there are two crucial policy discussions unfolding at once impacting open models – distillation & frontier capabilities. They’re very different in their nature, the necessity of response, and the potential response space. Still, together they represent the talking points of a surging platform of support for a potential ban of open models in the next 6 months.
The primary driver motivating regulation today is the inevitable truth that an open-weights model will soon reach the capabilities of Claude’s Mythos model. The actual performance of this openly released model will likely be more jagged, but all it takes is the model getting flagged in the nascent White House AI model checker. It’s hard to unwind new habits motivated by fear.
The current distillation debates are regulatory capture and doing nothing for now is fine
Distillation is largely a regulatory capture campaign at this point, as the only solutions on the table massively benefit the organizations pushing for it.
To elaborate, the anti-Chinese models political campaign is led by Anthropic, where they are sharing a mix of blog posts and letters to representatives detailing what the Chinese companies are doing. Anthropic has detected use from foreign companies, which is people coming and paying for its API, and eventually turned off usage and then written strongly worded recommendations of policy action and shared minimal technical evidence. This campaign may have started through a genuine business concern, but it has progressed to be the definition of regulatory capture, as Anthropic would gain substantial economic security in its products if the Chinese model makers they accused were banned.
If Anthropic was presenting information in a more neutral “you decide what to do” way, the community would have a lot more sympathy. It is more of a policy recommendation than an information sharing exercise at the frontier of a rapidly evolving technology. If Anthropic’s technology is as powerful as they say it is – so powerful that open models like it should likely be banned – then they should be able to secure their API. I continue to wait for them to explain why they cannot. One of their statements would need to be walked back.
Anthropic is also pulling up the ladder for access to intelligence in other ways — so the political recommendations they make in the vein of China competition are consistent with a much broader pattern of restriction of access to competitors of related technology in the vein of safety. It is easy to buy into company culture like an extra safety focus when many employees are on track for generational wealth. I do not blame the employees for this, but Anthropic’s corporate strategy should be understood in these broad, contextual lenses. Ben Thompson’s piece, Anthropic’s Safety Superpower, is the best writing on the subject.
The action that Anthropic is effectively asking for is the wholesale banning of pretty much all the Chinese open weight models in the U.S. — as any products built around open models are predicated on their continued improvement, increasing product market fit and compute efficiency as models get better. This would demolish the open model economy that is emerging in the US with inference companies, fine tuning companies, new products, and everything in between. We as a community desperately need to hold the line that conceding anything with respect to the distillation conversation is not acceptable.
Anthropic should try to protect their IP, but they shouldn’t ask the government to cement their position and in the process potentially isolate the US from the global open-source community. There are no good solutions to distillation with the information we have, other than letting the labs self-enforce it.
I’ve written at length on distillation in particular. I’ve written directly on its impact on model capabilities and the regulatory environment, and you can search for more in between the lines mentions on Interconnects.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
APIs aren’t magically secure
There’s a particular messiness to the distillation discussion, where there’s likely meaningful worry of Chinese labs distilling the narrow cybersecurity capabilities of Mythos into an open model. This paints more on the insecurity of current model APIs more than it does on the distillation risk. Even when Claude Mythos was in its most-limited private beta, Discord Sleuths Gained Unauthorized Access to Anthropic’s Mythos. To date, model APIs continue to be jailbroken and accessed in unintended ways.
This proliferates the risk of capabilities falling to bad actors far more rapidly than anything that involves complex fine-tuning of a 1T+ parameter model. I’m not a cybersecurity expert, but the dichotomy that only open-weight models are insecure and APIs are safe has been very overblown in recent years. APIs in concept should be able to be more secure, but that is yet to be demonstrated.
If Anthropic has a truly dangerous capability in their models, the only coherent action would be to not host it in a directly queryable API — before the discussion of it being distilled.
Ready or not, open models are coming
Where this becomes hard is that at the same time as these distillation questions, we’re staring down the barrel of “how do we handle frontier open weight models at the general capability level of Mythos?” This is a hard question, and it’s a natural human tendency to want to take a proposed solution to another problem (distillation) and apply it to the new, far more real problem (frontier capabilities).
We need to figure out the right policy for open frontier capabilities, but a flat out ban is likely not the answer. If the models are not banned in China as well, it is VERY easy for a bad actor to still use said banned open weight model, which negates the safety potential.
At the same time, if we alone ban the import of certain models, the global open-source community will continue. A world where the U.S. bans these models before China, or other more risk-sensitive cultures, would likely indicate that a form of AI fearmongering (or other social, political momentum) pushed the U.S. government to act early. It feels like speedrunning dystopia in the U.S., as our tech industry – the crown jewels of the economy – looks far more like a Chinese system with control and government investments. These are very bad outcomes!
The only way to add a ceiling on open-source progress is a global agreement on the management of risks of AI models, which we aren’t close to. Other delays make the AI rollout less predictable in the US and increasingly messy. It’ll feel a lot like the GPT-5.6 rollout, but instead of just limiting the upsides of open, cheaper intelligence to a few companies all the bad actors will immediately have access, too. Open models increase safety by broad access and understanding, not kneecapping the positive actors only.
In reality, there is no stopping the open-source ecosystem. The people building the best models are assessing risk as well, as China is very risk-sensitive and for example Z ai is already a public company exposed to a comprehensive set of pressures – keeping their rocketing stock up, for one. There will only continue to be more models that cross worrying levels of capabilities. Training AI models is not magic, and we haven’t seen access to building them drop off as the required investment has increased (yet).
One of the short-term off-ramps for this policy death spiral for open-source, a double-helix of related and complementary, scary issues, is for a company in the U.S. to release a similarly capable open model. This will shift the focus away from “only China is building the open models via distillation” to “we’re all in this together, and we should focus on the complex, moving frontier issues within our ecosystem.” This is an existential priority for open-source, and the companies who have the business reasons to release open-weight models like Microsoft and Meta (commoditizing their complements) should do it ASAP. I have less faith in Meta, with the new leadership, but they benefit from mass access to AI and should not get in their own way. If Reflection is sitting on an okay, but not frontier, model, they may need to release it to save their proposed business direction.
The shorter term solution than training a new model is to build the coalition. Open-source is a diffuse technology, without clear ownership, but the benefits will be shared by so many. This “everyone else” outside the frontier labs needs to start working today, on how to continue the safe rollout of open-weight models (and lobby for their principles and values) to the powers that be.
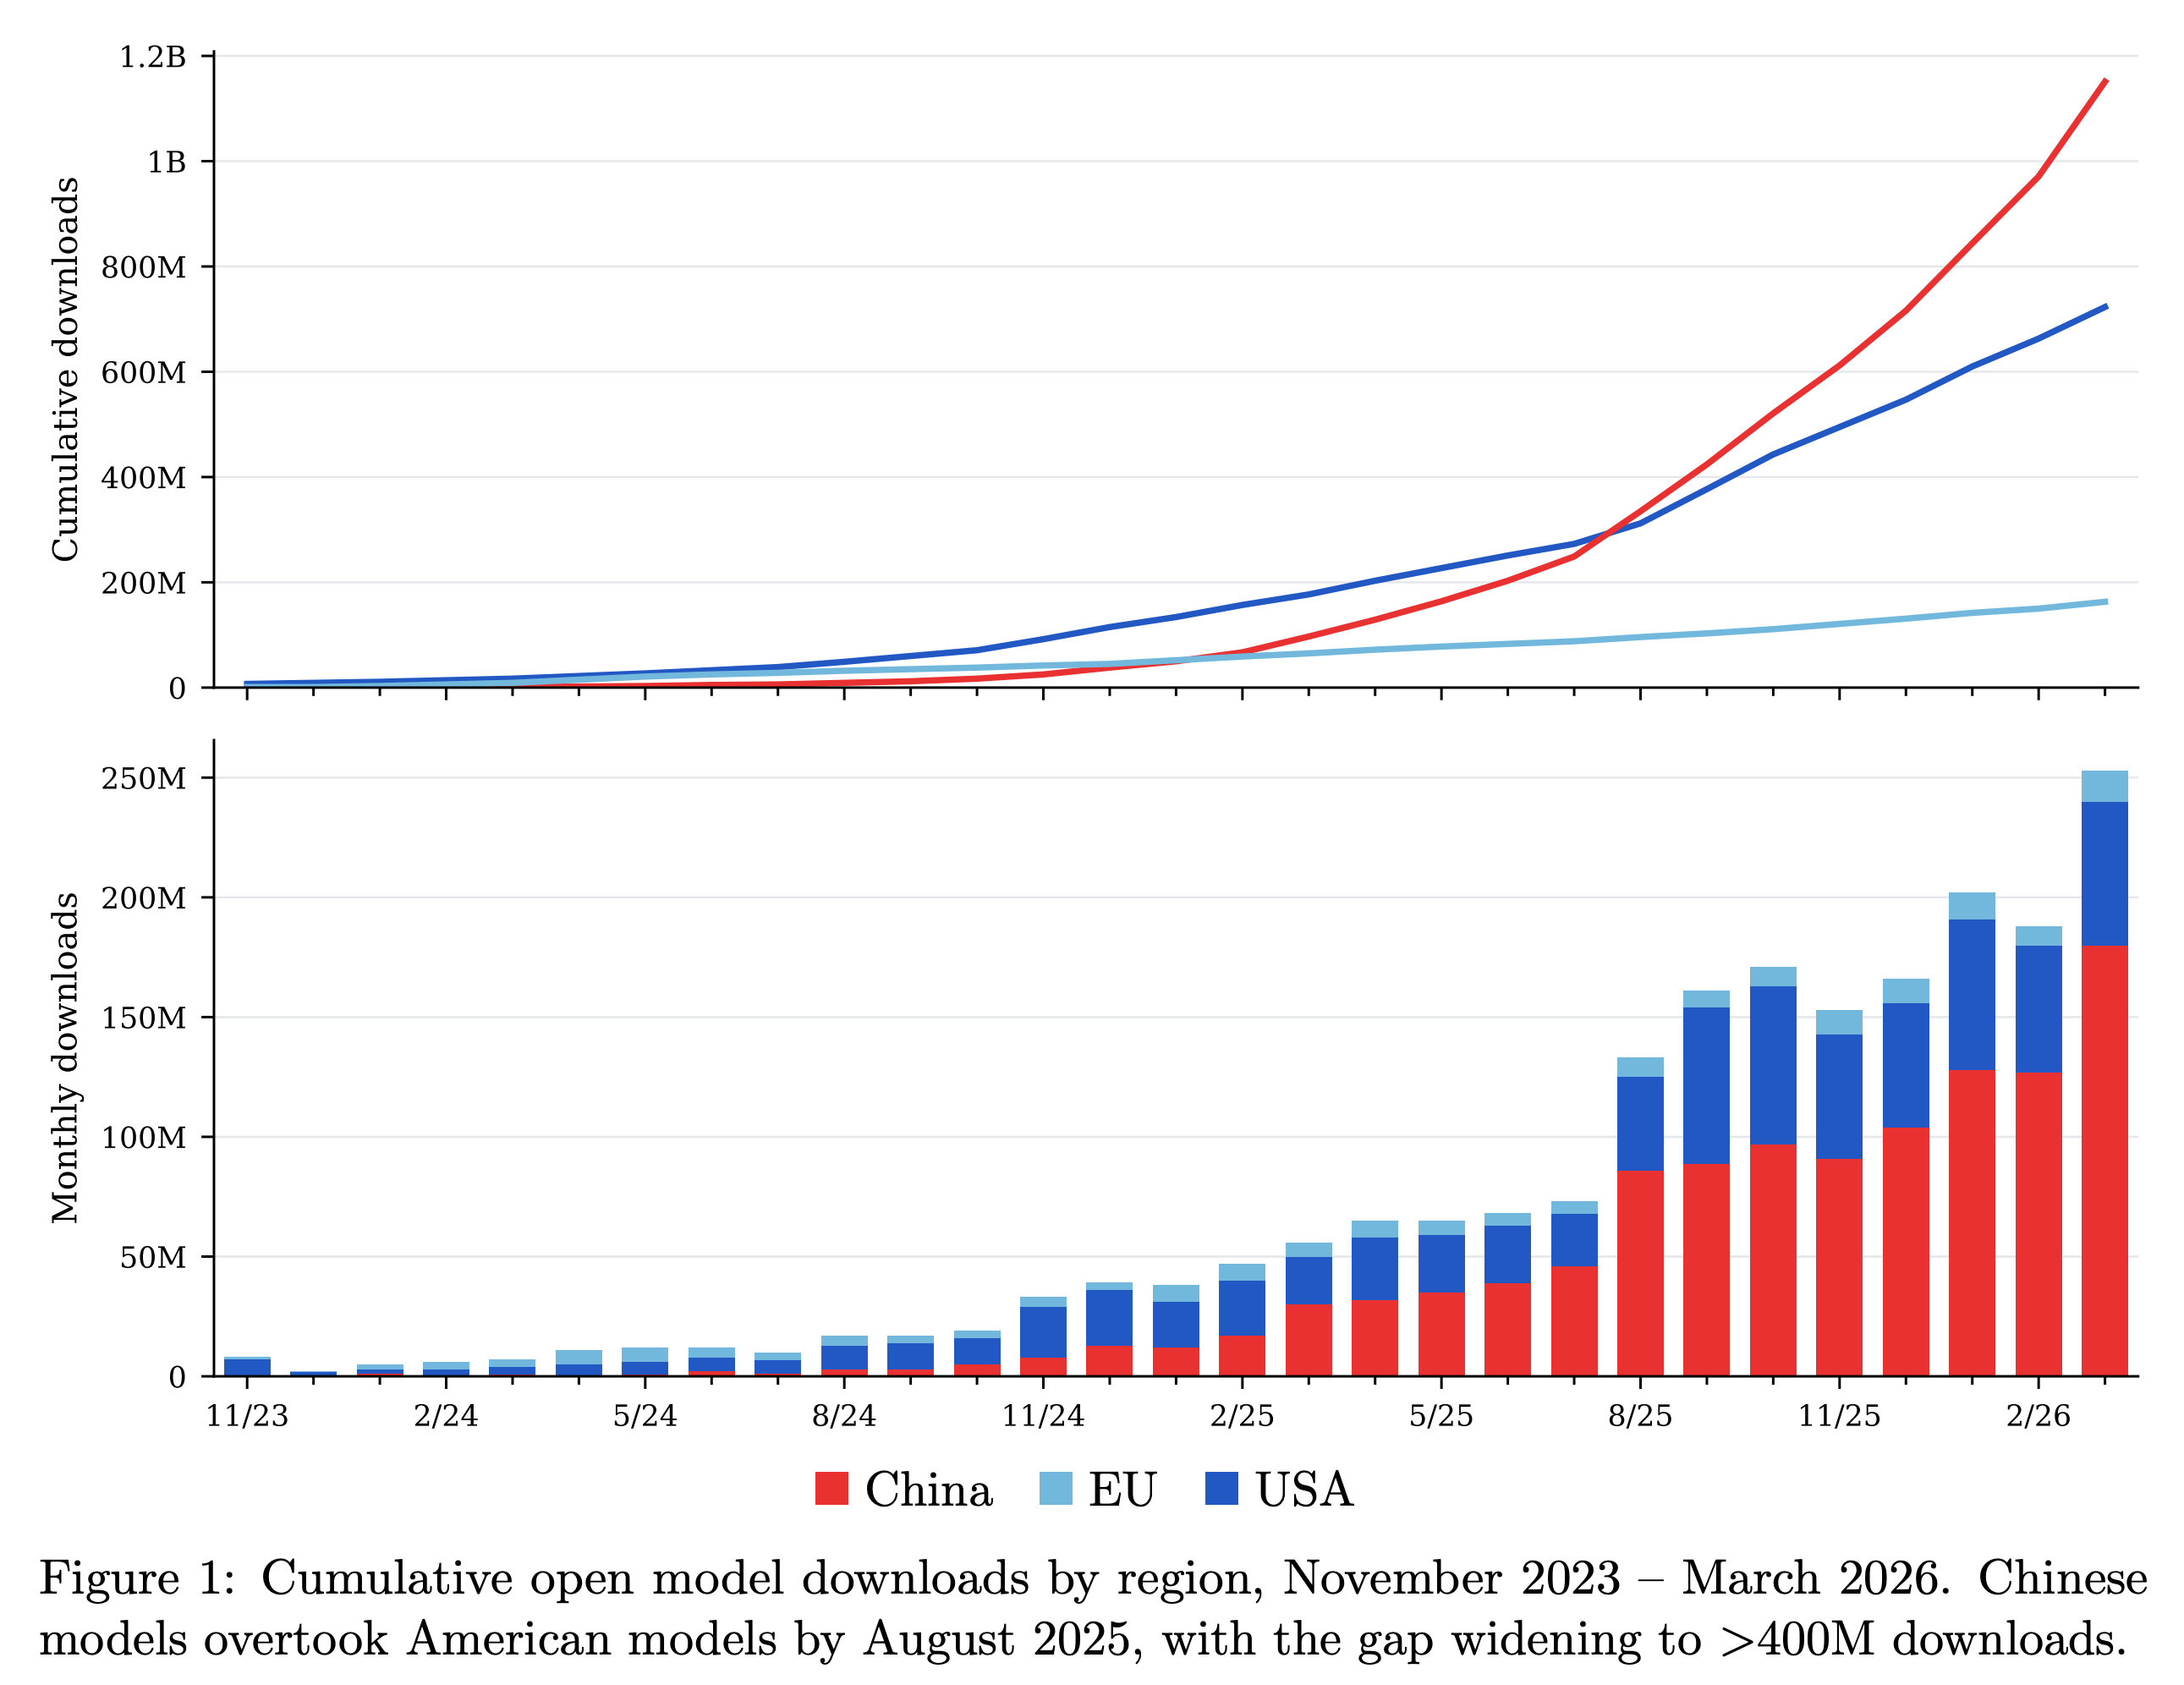
A trend we continue to see in open model releases is that the ecosystem is becoming more diverse, with an increasing number of organizations releasing a wide range of models. A year ago, open artifacts and the open model landscape more broadly were dominated by a handful of (Chinese) players. This has shifted, with us increasingly featuring more niche companies all over the world.
While it is hard to know the exact motivations of the companies themselves, we can broadly observe the following categories:
“Pure” model makers: These are companies whose stated goal is to train models that are at the frontier, or at least close to it. This includes many Chinese companies, such as DeepSeek, Zhipu, and Minimax, but also Western ones like Poolside, Arcee, and Zyphra. It also increasingly includes sovereign AI players, such as Cohere, Sovereign, Mistral, and Trillion Labs. The recent Mythos episode has woken up some policymakers, which may lead to increased interest in sovereign model training.
Big Tech: For Big Tech companies, including Alibaba’s Qwen, Google’s Gemma, and, to some extent, NVIDIA, the motivations are more diverse. Alibaba uses model releases to upsell its closed models, while NVIDIA benefits from a flourishing open model ecosystem as it increases interest in and usage of its GPUs. This vested interest is different from the Llama era of open Western models, where the motivations for open releases were less clear (and ultimately did not hold).
Product companies: Some companies, such as JetBrains, Zed, Krea, and Photoroom, mainly sell products that use AI as a core component. As they don’t want to be cut off from accessing closed models or want to offer something unique, they can train highly specialized, small models that fit their product needs. Thus, open-sourcing those model weights does not hurt their bottom line.
This diversity of makers and models fits our hypothesis that more companies will develop a long-tail of models and the number of companies chasing the absolute, open frontier will diminish.
While not every model release fits neatly into one of these categories, the broader point is that open model development is not driven by a single type of actor or motivation. This diversity is one of the strengths of the open ecosystem and can be seen in the tech reports of model releases, which reuse training methods, architecture choices and data from other open model releases.
Attempts to slow or ban this ecosystem are not only futile, as the history of tech-related bans has shown, but also unsafe and anti-freedom. Such restrictions would concentrate AI development and usage among the select few, which ultimately endangers outsiders’ ability to freely adopt one of the most important technologies of our lifetime.
Our Picks
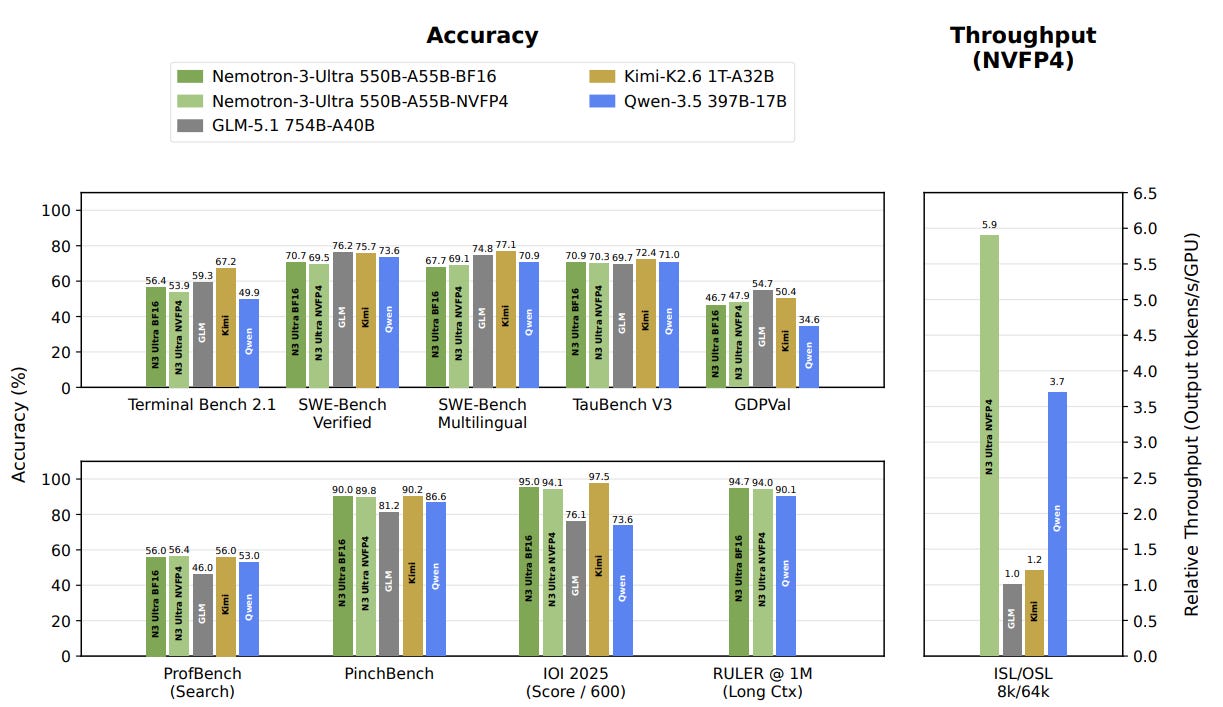
NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16 by nvidia: The big version of the Nemotron series, which uses LatentMoE to be even faster than comparable models. Just like the other Nemotron models, the vast majority of the data is open source. And, to top it all off: NVIDIA commits to using the OpenMDW license, which is tailored specifically for model weights (and data) and drops its custom license. While MIT and Apache are in the same spirit as OpenMDW, only the latter really covers model weights, while the former are software licenses that do not really apply to model weights.
command-a-plus-05-2026-bf16 by CohereLabs: Cohere, which is becoming more of a regular entrant into Artifacts lately, released their flagship, Command A+, under Apache 2.0. Previous iterations of the series have been released under a non-commercial license, so this change is more than welcome! Command A+ combines multi-modal, multi-lingual and agentic capabilities as a 218B-A25B MoE, making it usable with a single B200 (when using 4-bit).
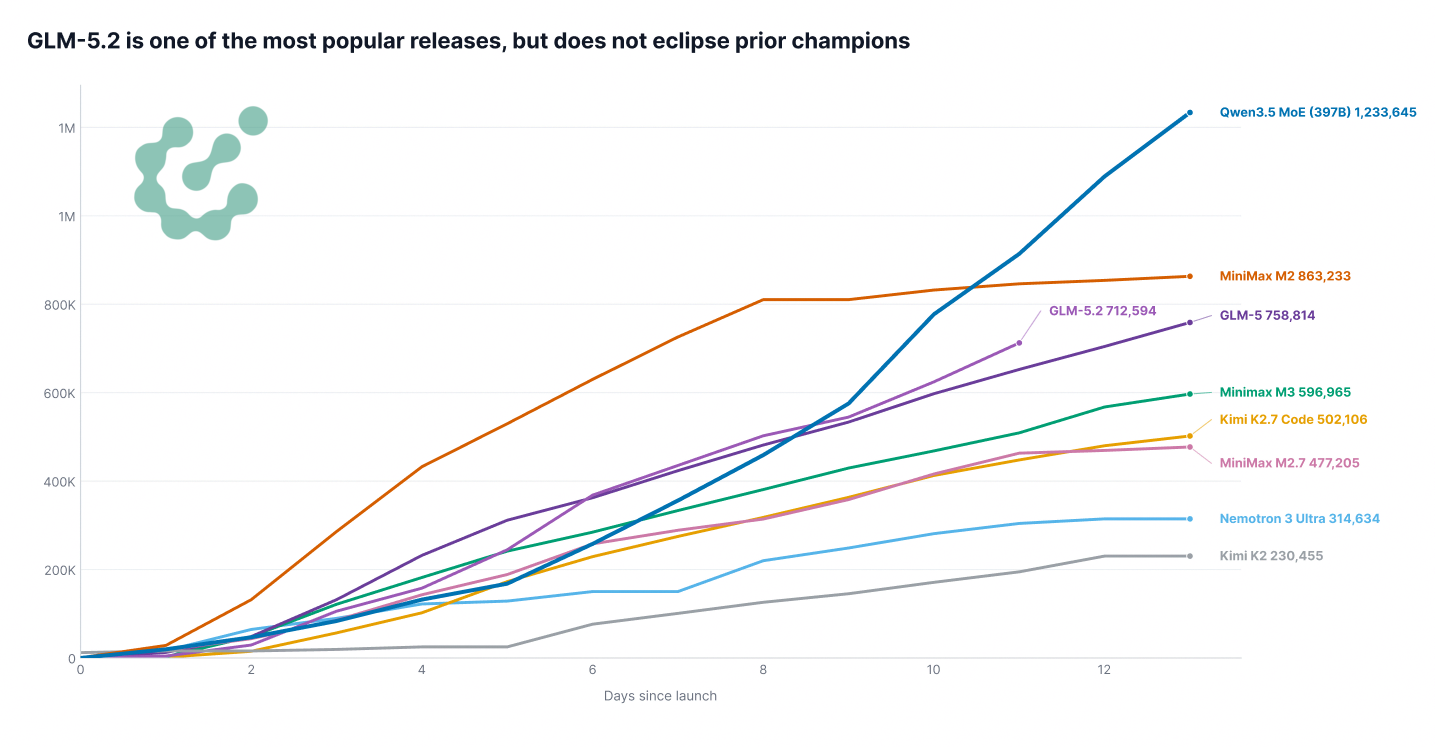
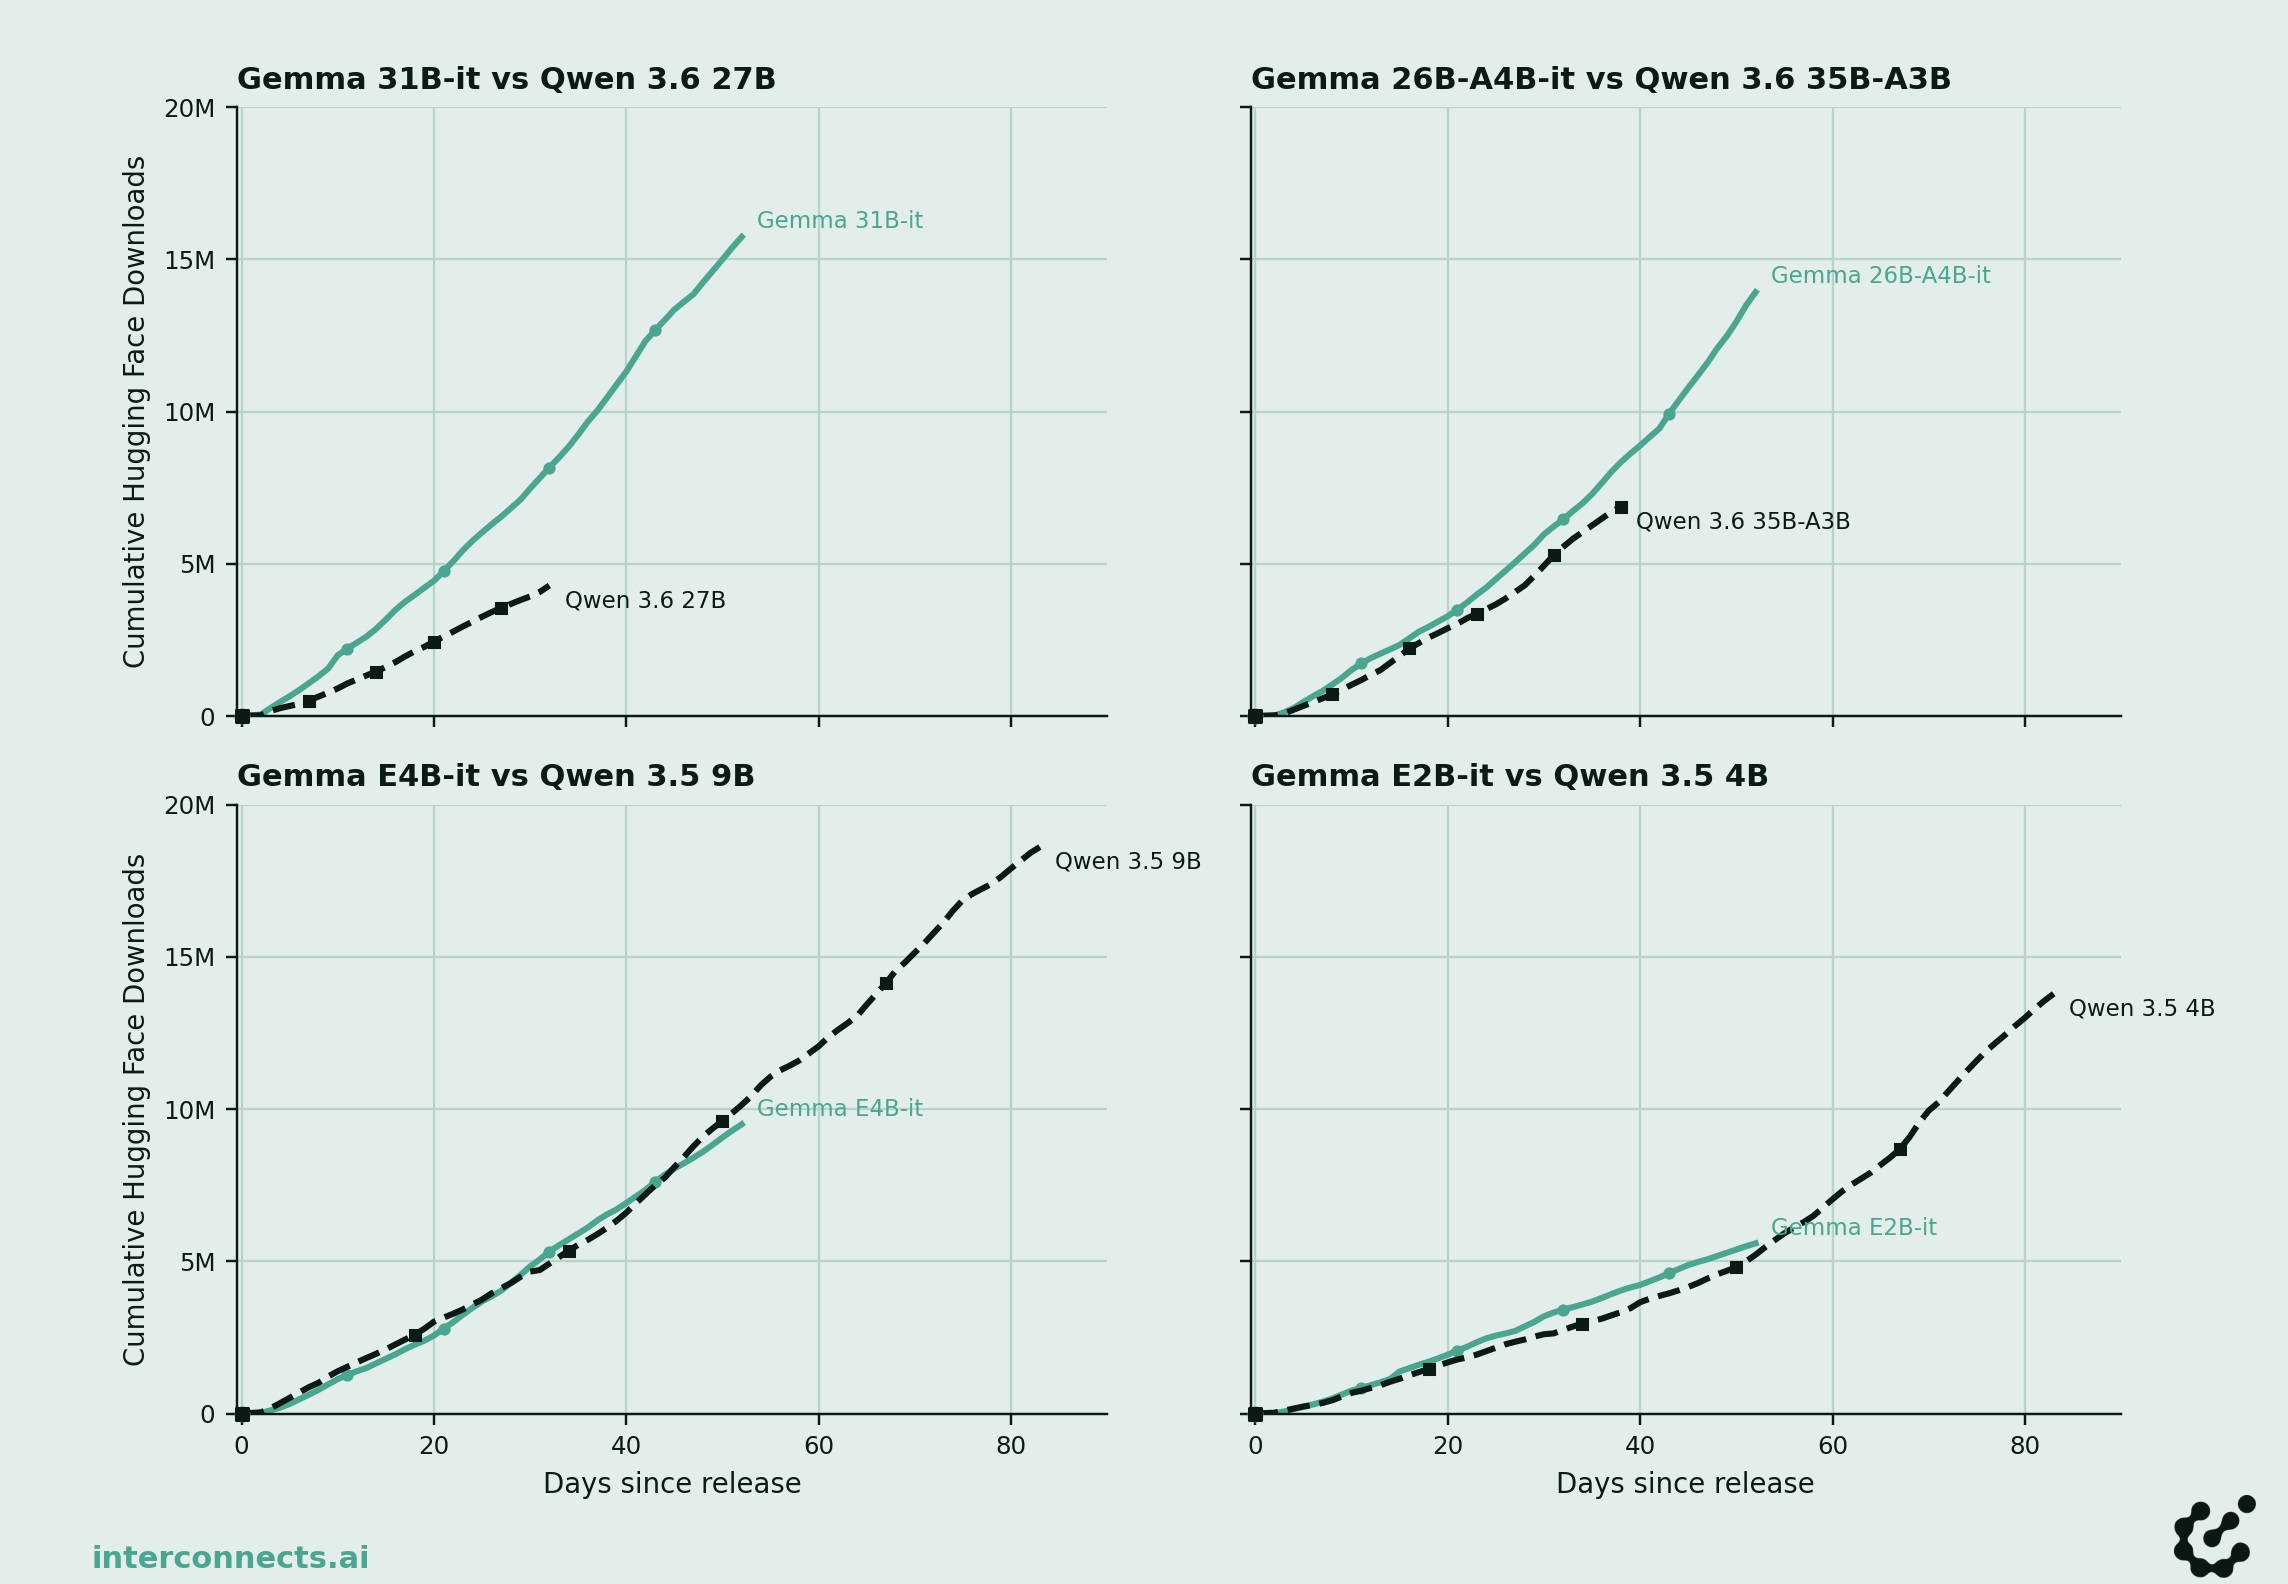
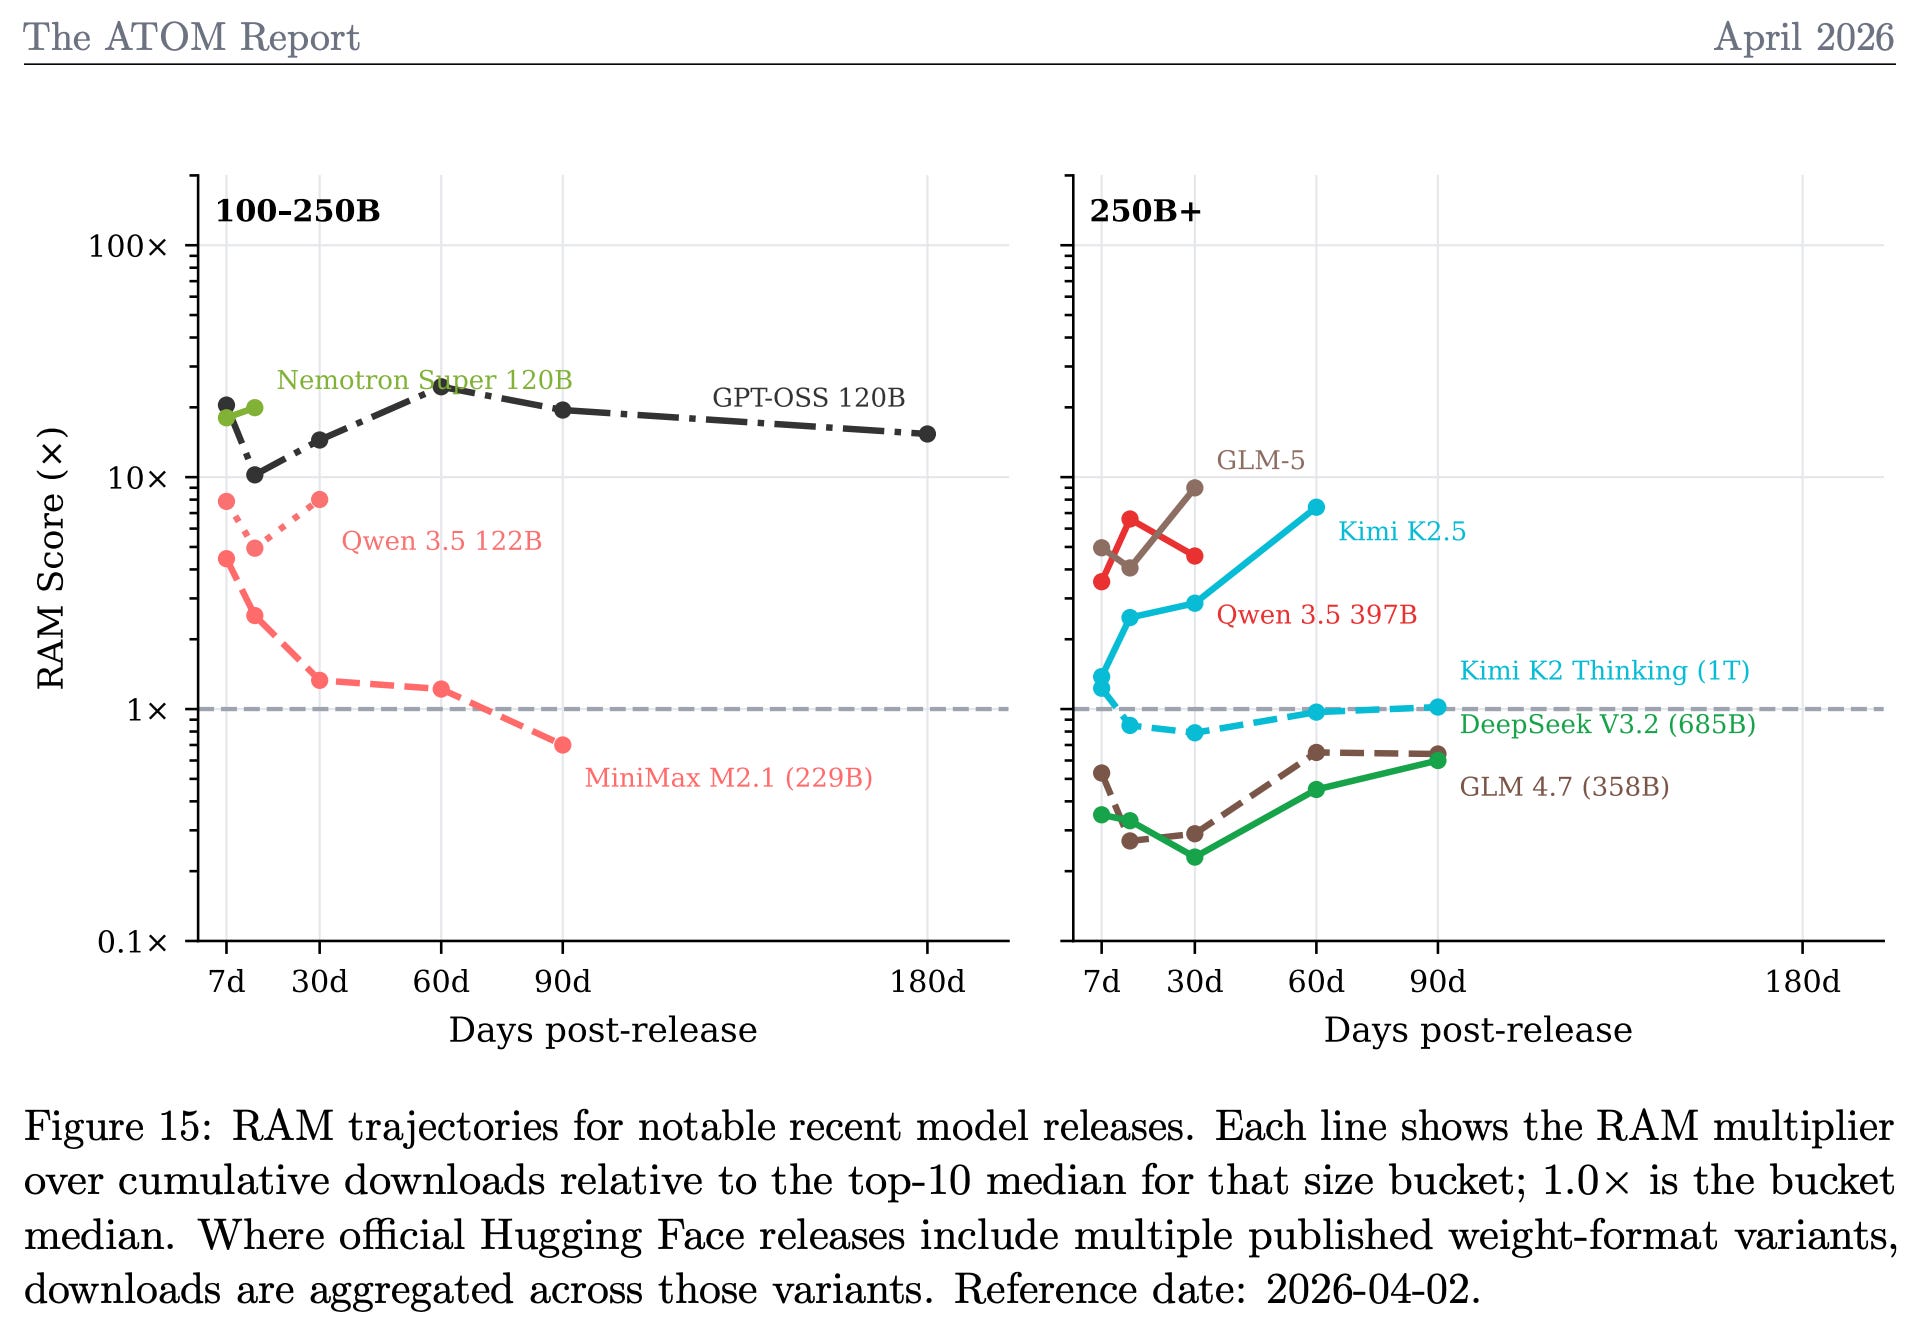
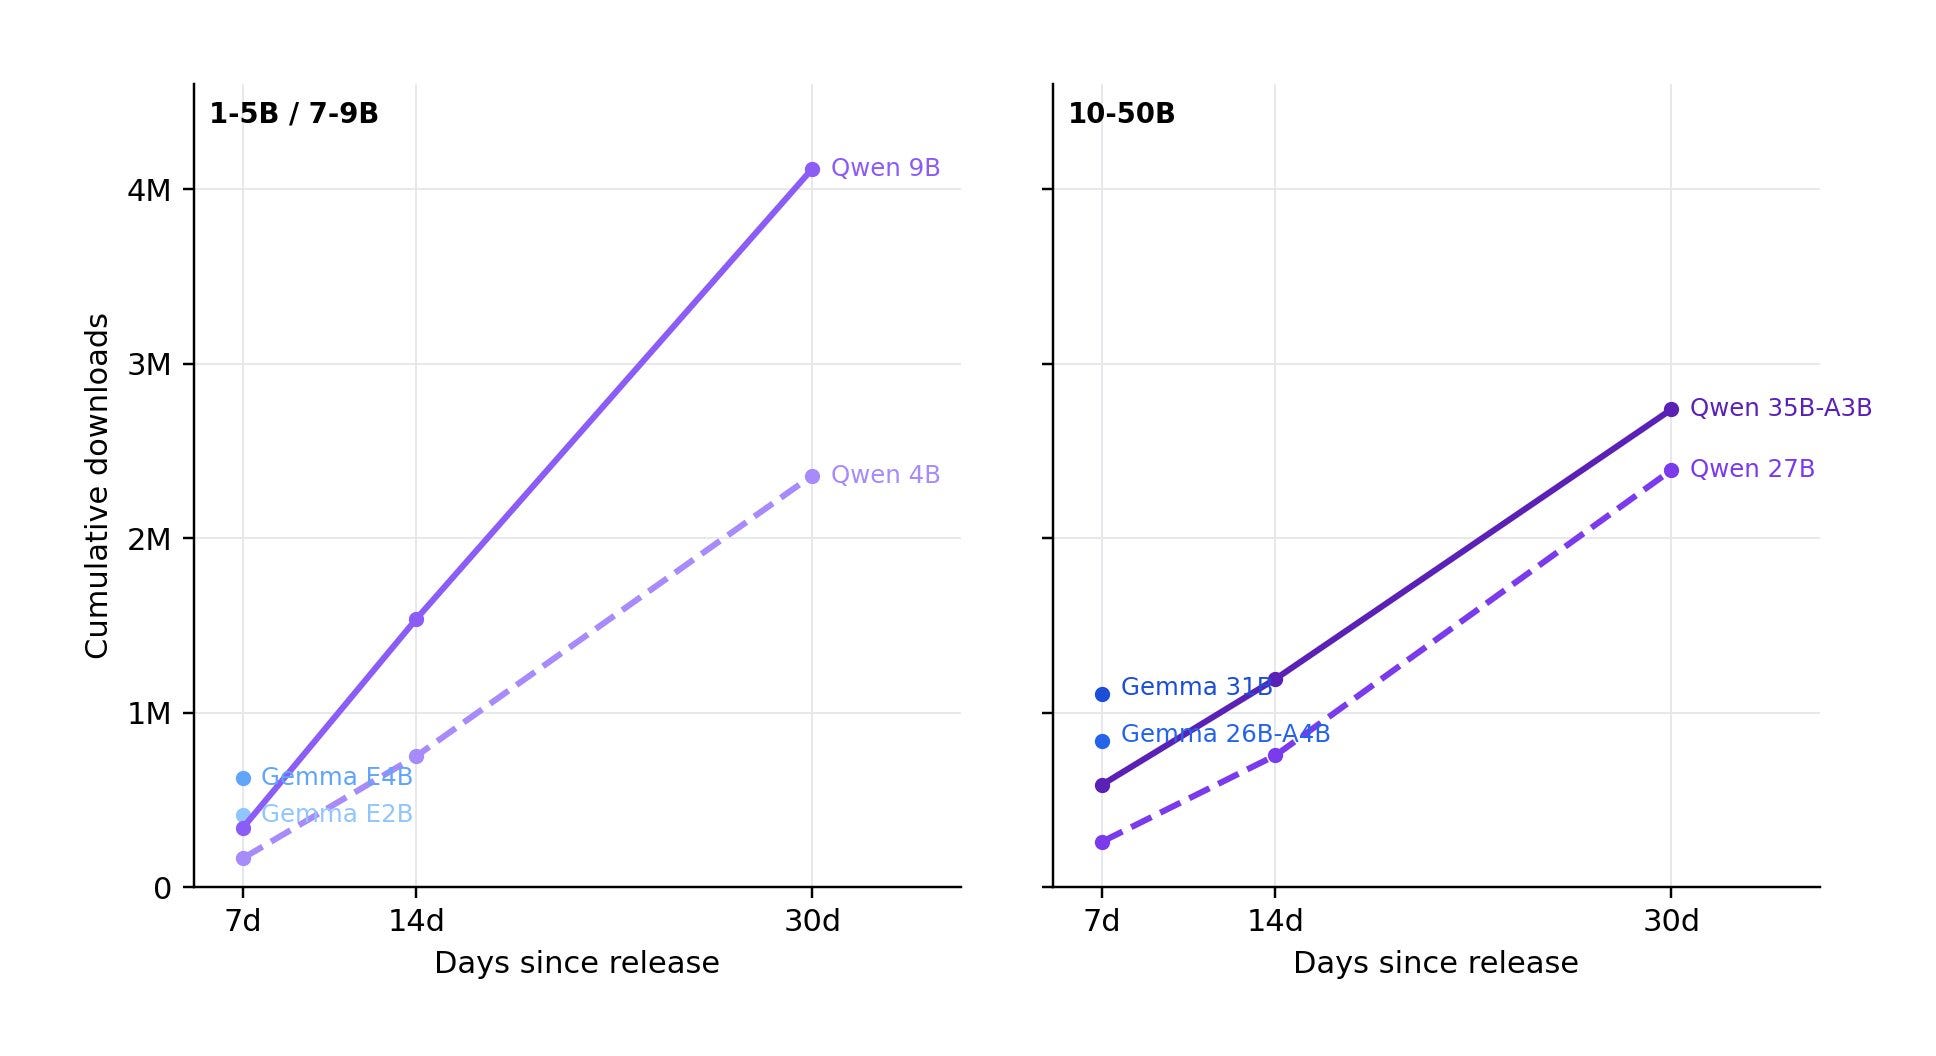
GLM-5.2 by zai-org: The biggest story in this Artifacts is GLM-5.2, which we have covered in a separate blog as well. The model continues to impress and is genuinely usable for everyday work, not a huge regression compared to the best closed models available right now. Interestingly enough, the raw download numbers since release are more in line with other model releases, with GLM-5.2 being roughly in line with GLM-5 after release.
ZAYA1-74B-preview by Zyphra: Zyphra, which trains on AMD GPUs and is known as some sort of insider tip in the research community due to their tech reports with interesting architecture choices, has released some new models, with a 74B-A4B MoE and an 8B-A0.6B MoE (tech report) being their current flagship releases.
Step-3.7-Flash by stepfun-ai: An update to Step-Flash, which is really strong in Math in particular.
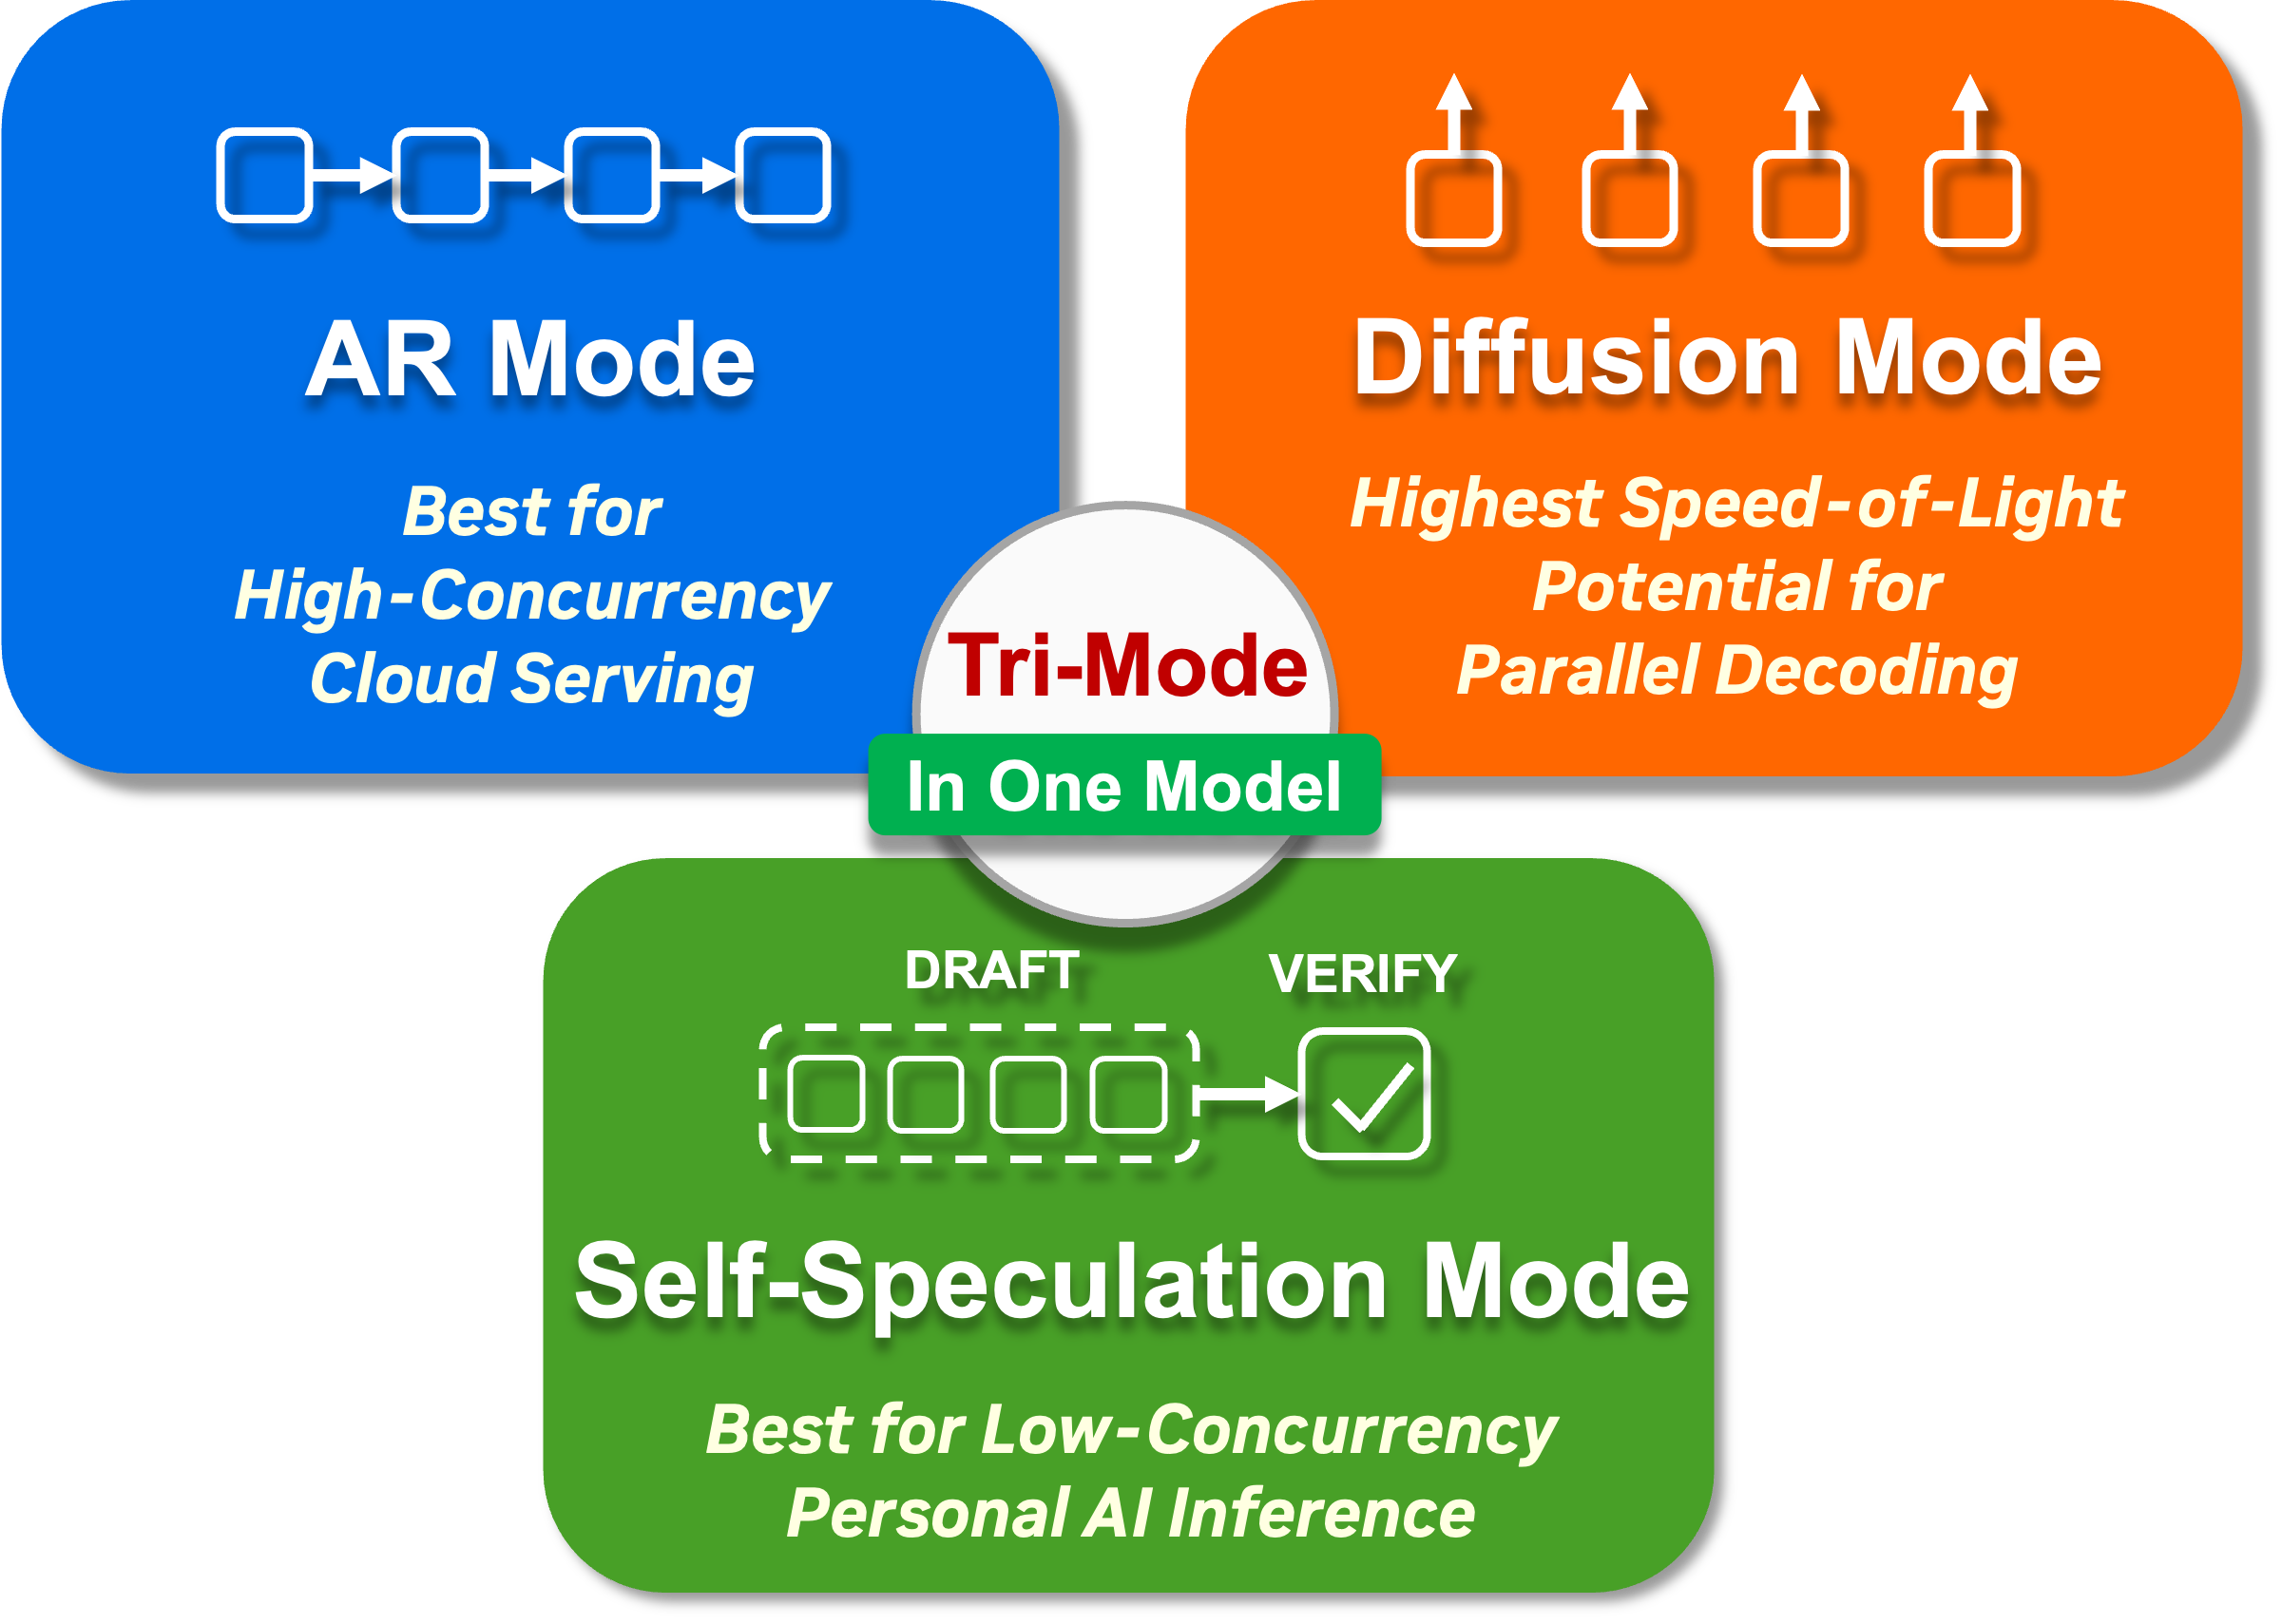
Nemotron-Labs-Diffusion-14B by nvidia: An experimental model which can be used in three different modes: autoregressive, diffusion, and self-speculation. Each of these modes is suitable for a different use case.
Housekeeping: Following my “State of the blog” post last week, noting a slight increase in paid features, it’s a good time to remind folks that I offer group subscriptions with larger discounts proportional to the number of seats. I also released a new paper today on open RL recipes for terminal agents, read more here.
A bit over a week ago, when the AI world was still reeling from the shocking export restriction, and effective banning, of Claude Fable 5, Z.ai released their latest model, GLM-5.2. This model was rolled out unusually on a Saturday, June 13th, to GLM Coding Plan members. This is an unusual release practice, normally when an AI model is released on a weekend it’s for a weird reason (most famously, Llama 4).1 In this case, it seemed like Z.ai was excited to capitalize on the zeitgeist of “Anthropic being anti open-science” with their silent safeguards on AI researchers. For the past year or two, the Chinese open-weight labs have taken every opportunity they have for easy marketing wins like this.
GLM-5.2, in a common naming convention across the industry, looked potentially like an incremental update following the popular GLM-5.1 model. At this point, Moonshot AI, makers of the Kimi models, and Z.ai, makers of the GLM models, have consolidated the top of the reputational market with the most beloved open-weight models among AI researchers. What unfolded is a common lesson in tracking AI models that often minor version numbers can have AI models crossing meaningful user experience thresholds. A small change in benchmarks and training can open a wide range of new use-cases.
What has followed is a slow, groundswell of hype for GLM-5.2. The official, MIT-licensed model weights and release blog dropped three days after the initial rollout, on June 16th. One could ramble many technical details, such as the strong benchmark scores, the very popular RL framework that Z.ai uses (SLIME), the recommendation of always using the model on Max thinking effort, and so on, but the initial release blogs usually aren’t the thing to focus on. You can wait and read the ecosystem reaction to know if it’s the real deal. Benchmarks are half dead these days, anyways.
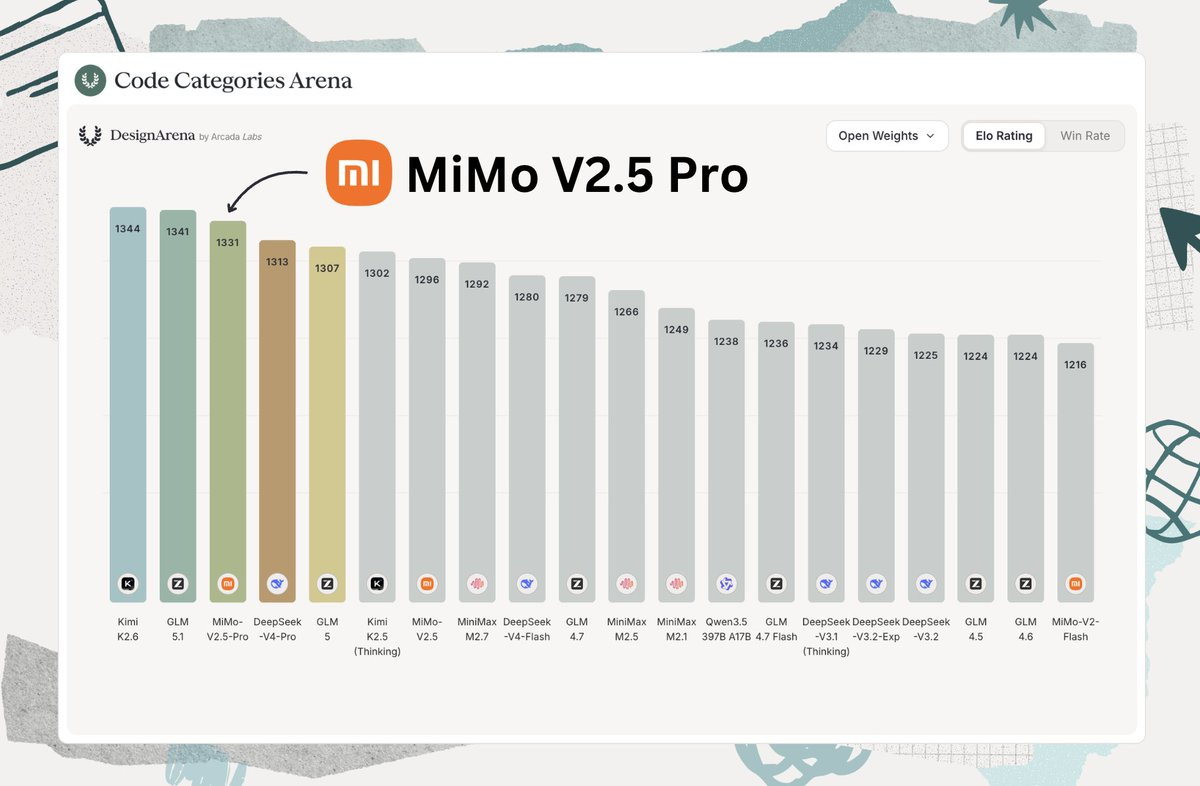
What followed on the 16th was a slew of community benchmarks showing better-than-expected results for GLM-5.2. Arena’s agent leaderboard had it as the only open model mixing it up with OpenAI and Anthropic’s latest models (notably matching Opus 4.8’s no-thinking effort to GLM-5.2’s max mode). This is one of many evals GLM-5.2 is crushing Gemini on, but that’s a topic for another time. A benchmark that has mixed perception in the community (particularly among actual designers), Design Arena even had GLM-5.2 besting Claude Fable itself — the recently banned hype machine!
Pretty much everyone I respect among the AI commentariat and researcher class has praised the model after using it personally. Such a focal point of discussion among the community has only been so clear with an open model release once before — DeepSeek R1. This is not a comparison I make lightly, and when I compared Kimi K2’s release to a “DeepSeek Moment,” GLM-5.2 has well exceeded that. What made Kimi K2 impressive was that big steps in open model performance could seemingly come from anywhere in China. The step that GLM-5.2 has taken is more of a one way door for AI progress.
Anthropic’s record revenue growth rate on the back of Claude Code is heavily driven by being the best model, and the only model that can really do this. GLM-5.2 is the first of many (coming soon) open weight models to offer credible alternatives. The parallel is very clear, to when DeepSeek R1 showed that open-weight labs, with far fewer resources, could also replicate the chain-of-thought reasoning models that OpenAI championed with o1. As AI systems get more complex and far more expensive to build, with tools, integrated harnesses, and scaled model weights, it was not a given that this GLM-5.2 moment would happen at all.
The key point is that GLM-5.2 is the open weight model that feels right in coding harnesses as a general agent. It’s the first one. I was personally overdue in trying some of the recent peer models, such as Kimi K2.7 or GLM-5.1, but the hype was too much for me to ignore. I put it to work helping make content for my post-training course with Fireworks’ API in Claude Code (setting this up was very easy). There were some minor knife cuts, such as the Claude Code harness / my repo documentation trying to send images to the model, which would brick Fireworks API for the session — forcing a manual context clear. Overall, the model capabilities immediately felt right, and I still have some tinkering to do in which harness and inference provider to use.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
So, this is a good model, where does this leave us?
There are many trends at play. To start, let’s ground things in the open-closed capabilities gap. I’ve written how I expect an “explosion in usage” if open models crossed the Opus 4.5 in Claude Code threshold from around the start of 2026. Here we are. With Claude Opus 4.5’s release on November 24th, 2025, the gap in time to GLM-5.2’s release on June 16th, 2026 is 204 days — or about 6.8 months. This puts us square in the 6-9 month time gap that many people claim as the performance lag between the U.S.’s closed labs and China’s open counterparts.
Upon writing this, I’m surprised. As the U.S. labs have so rapidly ramped compute in the last ~year, I’ve expected the gap in performance to grow in time. A very meaningful step in this trajectory will also be Claude Fable 5’s release — which was more reliant on scale, and therefore the most advanced GPUs, relative to the Claude Opus models. Still, that’s not a satisfactory answer. Continuing to unpack the trajectory here involves more nuance than I can afford to fit in a signposting article.
The most immediate meaning of this is far more serious pricing pressure within the organizations tokenmaxxing, sending Anthropic’s revenue to the moon. Some would predict Anthropic doesn’t realize its forecasted ARR numbers, but I don’t think that prices in the true demand for these models and the inevitable growth. This model existing is a huge boon for the open model economy. All the likes of Fireworks, Together, Thinky (via Tinker), Prime Intellect, and whoever else sells open model inference or finetuning just hit another inflection point.
It’ll take a long time for the effects here to diffuse into the broader economy (and use-cases). Workflows are becoming more complex, with people using different models for planning, primary coding, and subagent dispatch. I expect the hype to continue to grow, and heck, as I’m writing this on a Sunday evening, I could see the media and market reaction on the Monday being a thing just like the DeepSeek R1 release. This diffusion happening while Anthropic’s, and by extension the U.S.’s flagship model, is still banned is a severe economic dagger. GLM-5.2 is being given time to carve out the economic underbelly of the frontier labs when they want to be pushing forward into higher margin, higher revenue domains enabled only by the absolute frontier models.
The economic concern mirrors a story that has been told many times in AI, so it’s unclear when it’ll stick.
The conversation that feels more core to the trajectory of AI is that of regulation and control of open models. I think it is an economic good for cheap intelligence to diffuse widely, and our default position should be to cheer for open models, but this model’s release date will have it be permanently associated with Claude Fable — and therefore Claude Mythos — in the mental map of AI power structures. We are at a point where Mythos-class model capabilities are deemed not safe for release by the U.S. Government and the Chinese model makers are charging forward in capabilities available to all.
These trend lines aren’t necessarily causally linked, as we don’t know the cyber performance of GLM-5.2 versus its predecessors, but the capabilities are definitely correlated. Without anything changing, this points to a potentiality where the U.S. Government decides a certain open-weights Chinese model is not safe for the public. There are many other potential scenarios here too, but what is clear is that we have a lot of work to do in mapping them out, preparing our infrastructure, and messaging to society.
It’ll take a lot more people than just me to imagine and communicate a world to decision makers for how to manage evermore capable open models.2 We have years more of AI progress to come, with Nvidia’s next generation chips already in production and a constant stream of algorithmic advancements. It feels like a narrow path for open model advocates to take, but we need to figure out how to make them viable so the massive leaps in performance don’t only go to closed models.
I totally see why it is scary to imagine an openly accessible Mythos class model, but if open models get banned now and only closed models get 10 or 100X better in 2 years in the hands of one or two companies, I think we will have bigger problems on our hands.
Something that has always stood out to me is how fast the Chinese labs release their models. I’ve heard from multiple labs that the time to upload the weights publicly to HuggingFace after the model finishes training could be measured in hours rather than days. This has at least slowed a bit, now that they need to prepare to serve the model to a wider inference market.
Something that will need to be discussed more is how even closed models, e.g. Mythos preview, are regularly in the hands of unauthorized users or jailbroken. So, the open vs. closed dichotomy on access isn’t totally black and white.
This post was originally an op-ed co-authored with of Interconnectedfor a general, non-technical audience. The gatekeepers — the many media outlets we pitched it to — passed on publishing it. Luckily, we have our own platforms to get the message out. Please help us forward this op-ed to any one you know who is on the fence about open source AI or new to the topic and want to learn more. Thank you.
The energy to regulate AI is in the air in Washington. With the recently signed executive order to review AI models, a congressional proposal to legislate AI further, the government possibly taking shares of frontier AI labs, and last Friday’s action prohibiting foreign nationals anywhere from accessing Anthropic’s most advanced models, this may be the opening salvo of more AI regulation to come.
We are afraid future actions could inadvertently or intentionally regulate or even ban open source, a much maligned and misunderstood topic in AI. That would be a grave mistake.
Open source – simply a process that allows technology to be shared, built, and distributed publicly and transparently – is safe, secure, and drives economic growth. More than 90% of the world’s software was already built on open source and produced more than 8 trillion dollars worth of economic benefits, long before AI entered the picture. Today, open source technology is quietly training, improving, deploying, and securing AI everywhere.
For more than three decades, open source has been powering three trends, and upholding three values, which the American society holds dear – education, competition, and innovation.
Open source is pro-education because its origin was rooted in academic institutions trying to make technology free and open, not held hostage to the profit-maximizing zeal or the menacing lawyers of large corporations.
The precursor of open source is the free software movement, which started in 1983 on the campus of MIT. It was a time when every small act of using software, whether it was teaching students or doing research or improving a printer’s performance, meant paying or dealing with big corporations like AT&T or Xerox. After this struggle gave birth to open source, every student in every university, community college, and coding bootcamp in America now taps into the freedom that open source enables to learn how to program, engineer, and build. Open source is at the heart of technical education everywhere.
Open source is pro-innovation because it essentially provides a set of tools plus a community of other users to help anyone turn an idea into reality, for free. Combined with its role in education, it has watered most of the seeds of innovation in recent memory. Some of these seeds stayed as hobbies that brought joy and personal learning to the hobbyists. Others blossomed into huge companies, like Meta, where the initial version of Facebook was built entirely on a stack of open source software.
Every day, new ideas or solutions are being coded up in a dorm room, garage, or basement, all because open source lets innovators create without fear of a lawsuit or an expensive bill.
Open source is pro-competition because it helps the underdogs challenge and compete with the large incumbents, keeping monopolistic threats at bay. Linux, the open source operating system that now runs more than 90% of the world’s cloud computing infrastructure, was the antidote to the Windows monopoly (so much so that former Microsoft CEO, Steve Ballmer, called Linux “cancer”). Android, the open source mobile system, fostered a long string of competitive smartphones before Apple’s iPhone could control the market. Many other examples exist in the more niche, but no less important, segments of self-driving, databases, and semiconductor design.
Without the equalizing and democratizing nature of open source, we would all be living with the rent-seeking consequences of more monopolies and less free market competition.
Does AI change any of this? No.
The duopoly of Anthropic and OpenAI are rapidly concentrating power between them with their closed, proprietary models. Anthropic, in particular, has flexed its monopolistic muscle recently by reducing its most advanced model’s capability when it is being used to improve someone else’s model. While the capabilities of their models are undeniable, so are their price tags and market concentration. Open source AI, mostly in the form of open weight models, has been the only counterweight for startups, educational institutions, and enterprises looking for alternatives.
Does open source lead to more safety or security concerns? Not quite.
We acknowledge it is worth monitoring the security implications of open source models that may reach frontier capabilities. But for the most part, the transparency that is inherent to open source makes them safer and more secure, because more engineers and researchers can tune out unwanted model behaviors, like censorship, or fix bugs in the software that runs these models. As one popular saying goes, “given enough eyeballs, all bugs are shallow.” An open source model also does not transfer data, when installed on your own company’s infrastructure as Airbnb CEO, Brian Chesky, explained. Open source AI is the most secure and privacy friendly path.
What about China? Beware of unintended consequences.
China is certainly a fierce competitor with the US on many dimensions – economically, militarily, diplomatically – but using this dynamic as a pretext to regulate open source will backfire.
Open source models are actually improving the efficiency and profitability of many American startups, who cannot afford to pay the monopoly-level premium to Anthropic or OpenAI. AI companies working in coding, legal, and other domains are using open source models, including ones from China, every day. The fact that these models are made by Chinese labs should be a wake-up call that open source is under-invested and under-appreciated in America! The response should be more support for open source at home. Regulating or limiting open source because of China would achieve the opposite: putting a chilling effect on education, innovation, and competition, while pushing the rest of the world – much of which wants open source’s benefits as much as we do – to adopt China’s.
Former Supreme Court Justice Louis Brandeis, famously said, “sunlight is said to be the best of disinfectants,” when it comes to removing corporate or societal misconduct. Open source is that “sunlight” in technology and AI. America should always be on the side of light.
As I navigate my career change after Ai2, I wanted to share my views of how this blog relates to my missions and broader work. In my farewell post, I summarized my three goals right now as:
Provide clarity in the evolution of frontier models.
Create a vibrant and diverse open (model) ecosystem.
To build institutions that make these goals possible.
Within this, Interconnects is at its core a bit different than many of the highly-polished, professional newsletters on this platform – and this is becoming intentional.
Interconnects is the tip of the spear of all of my missions in AI. It is meant to start a conversation and to let the reader into the mind of someone at the frontier. This insight makes the writing sometimes a bit raw, sometimes a bit too technical, but it is the map of how I progress my thinking in the ever changing world.
This style of writing has helped me create very strong relationships with the core group of readers, many of who listen to the voiceovers I do for these posts. The plan is to keep operating and refining the Interconnects experience around those loyal fans. These are to a large part people building the frontier AI ecosystem — researchers at labs, top investors, policymakers obsessed with the frontier, and students aspiring to have one of those roles.
I’m very happy with this sort of raw, high-voice outcome for the blog. It is not something I sought out, but rather accepted as I saw it coming and realized it would be disproportionately successful in a near-future of vast AI slop media. With years of trying to squeeze writing into a busy schedule, the only sort of writing I had time for was that which had a style very closely matching how I think.
I’m also very happy to be an independent voice. As a person I don’t do well with some power structures like having a boss, and I think there are very few people without extreme financial conflicts of interest that are willing and allowed to write. Through a wide job search, few companies were genuinely excited about me continuing writing.
Over the past few months, I considered taking Interconnects in more of a direction like SemiAnalysis or Stratechery, where it is my full-time gig and number one priority, but it didn’t seem like the right fit for what I am trying to achieve. I’m trying to build an open ecosystem and a movement for true open-science at the frontier of AI. These areas are very narrowly populated and trying to influence them with only commentary, analysis, and related research products wouldn’t work for me.
These sorts of full-time outcomes are definitely still one of my dreams, and I will do it at some point. The dream of this is also one of the reasons I take conflicts of interest seriously. Though, in this era of AI I can’t be fully on the outside.
In this vein, I wanted to disclose two advising agreements I recently signed. I don’t view them as a compromise of the above independence, as I’ll happily quit if I feel like I can’t speak my mind, but as a form of support in accomplishing my missions.
If I want to make a true open-science ecosystem I have some catching up to do with how the frontier labs approach post-training. The two companies I’m advising, whose leadership I’ve become friends with, are Arcee AI and Mercor. Arcee should be fairly obvious as the no-nonsense player building open-weight models. Mercor will make more sense over time, but they’re a close ally to a lot of my goals in transparent evaluations, open post-training, and neutrality with respect to the leading labs. These advising agreements are based on me wanting to learn more, and I don’t suspect I will ever engage in the very cursory advising roles that are more of name-stamping.
Otherwise, my full-time job should still be in the non-profit sector as long as I get the next few months of logistics right.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
Some operations & audience notes
Interconnects has cultivated an excellent, niche, and largely technical audience with representatives of all the top companies and labs (recently crossed 70K subscribers). I intend to protect this niche audience rather than trying to expand to bigger pastures. I think this success in audience alignment is reflected in my ~900 paid subscribers supporting it with infrequent paywalled content. I appreciate the support greatly, as the money has let me expand Interconnects operations and quality over the last 18 months.
I created Interconnects AI, LLC last January along with business bank accounts. Since then I’ve made some money, but I’ve reinvested it (and more) back into the business and the various AI services I need to try to write these articles. So, at this moment going full-time on Interconnects is a pretty risky financial proposition for me. In fact the Interconnects bank account has hovered around $0 for months (I’m personally fine having another job). This made me hesitate in going all-in on it, but in reflections I concluded that I would have more impact in AI by building these systems than focusing on commentary.
Second, as AI services get more expensive (e.g. Fable becoming API only), I’m going to need to spend more out of pocket to make this happen. I’m happy to do this in the near term, but I’m starting to optimize the blog to have more consistent financial growth, so when I want to go all in on writing in a few years I have a safety net.
I don’t do special offers, free trials, etc. for Interconnects paid subscribers (mostly to mitigate noise in the Discord community), but if you have the means to support this project it would mean a lot to me as I center my career around it. Joining a lab or a well-paying startup would be a much simpler path for me and my family but it’s never felt like the right thing to do.
I have a very arbitrary goal of reaching the 1000 paid subscribers orange checkmark on Substack this summer. So you can help and/or just watch my attempts to make it happen.
In this vein, I wanted to be direct in sharing how I view a few core operational components of Interconnects, and what you can expect going forward.
All comments will be paywalled. Whenever I have a popular post without paywalled comments I get a flood of low-quality posts — many of which are obviously AI generated. This is a detriment of the highly selective audience we’ve built. If Substack supports a feature like “only users with a paid subscription somewhere on the platform can engage,” I’d implement it. The blog comments, Substack chat, and Discord will be spaces where I perform active curation to maintain a 0% AI slop rate.
Slightly more articles will be paywalled. I want to keep experimenting with what is the right way to do this, but the only metric I can rely on for increasing influence of the blog is revenue. Views, likes, etc. are all vanity metrics which don’t reliably measure this type of content. Cultivating a highly engaged audience is existential to me in attempting to maintain an AGI-proof expertise.
Slightly more in-person events. With a small community that I respect, I have to opportunity to translate that to excellent real-world experiences. I expect to keep these small, but I want to be more proactive at organizing them so loyal readers know what to expect. The few coming soonest will be for my book launch, which should be in the next month or two. Plus, I know people always want to meet likeminded folks in AI!
Together these should make it easier and more enjoyable to be a loyal fan for Interconnects. I’m looking forward to continuing convincing my fans that the support is worthwhile.
Thanks for reading! My career wouldn’t be possible without all of the support.
As I’ve been recapping fundamentals of post-training to wrap up my RLHF / Post-training book I knew I needed to get Finbarr Timbers back on the podcast to talk about the state of play. Over the last few months we’ve had many discussions on what we’d need to do to take an Olmo-style recipe to the frontier, supported by Finbarr’s extensive reading of recent model technical reports.
To prepare for this, I put together a summary slide deck on the key post-training recipes historically — the path from InstructGPT to today — and today — the key open frontier models. This deck is summarized below as the technical summary, but we do spend 20-35 minutes on it in the podcast, so watching on YouTube is likely the best experience for this one.
I previously interviewed Finbarr in December of 2024, shortly after the release of o1 and Tülu 3 (and before he joined Ai2) on the “We are so back” era of RL.
Chapters:
00:00 Introduction & Olmo reflections
06:28 Post-train recipes review (history)
23:00 2026’s model recipes (MiMo Flash, DeepSeek V4, GLM 5, Kimi K2.6, etc.)
For more educational post-training videos, see the course I’m putting together.
Technical Summary
These are notes cleaned up from a slide-deck created with AI assistance — mostly useful as a discussion topic and reference.
The shape of a post-training recipe has changed more in the last year than in the prior three.
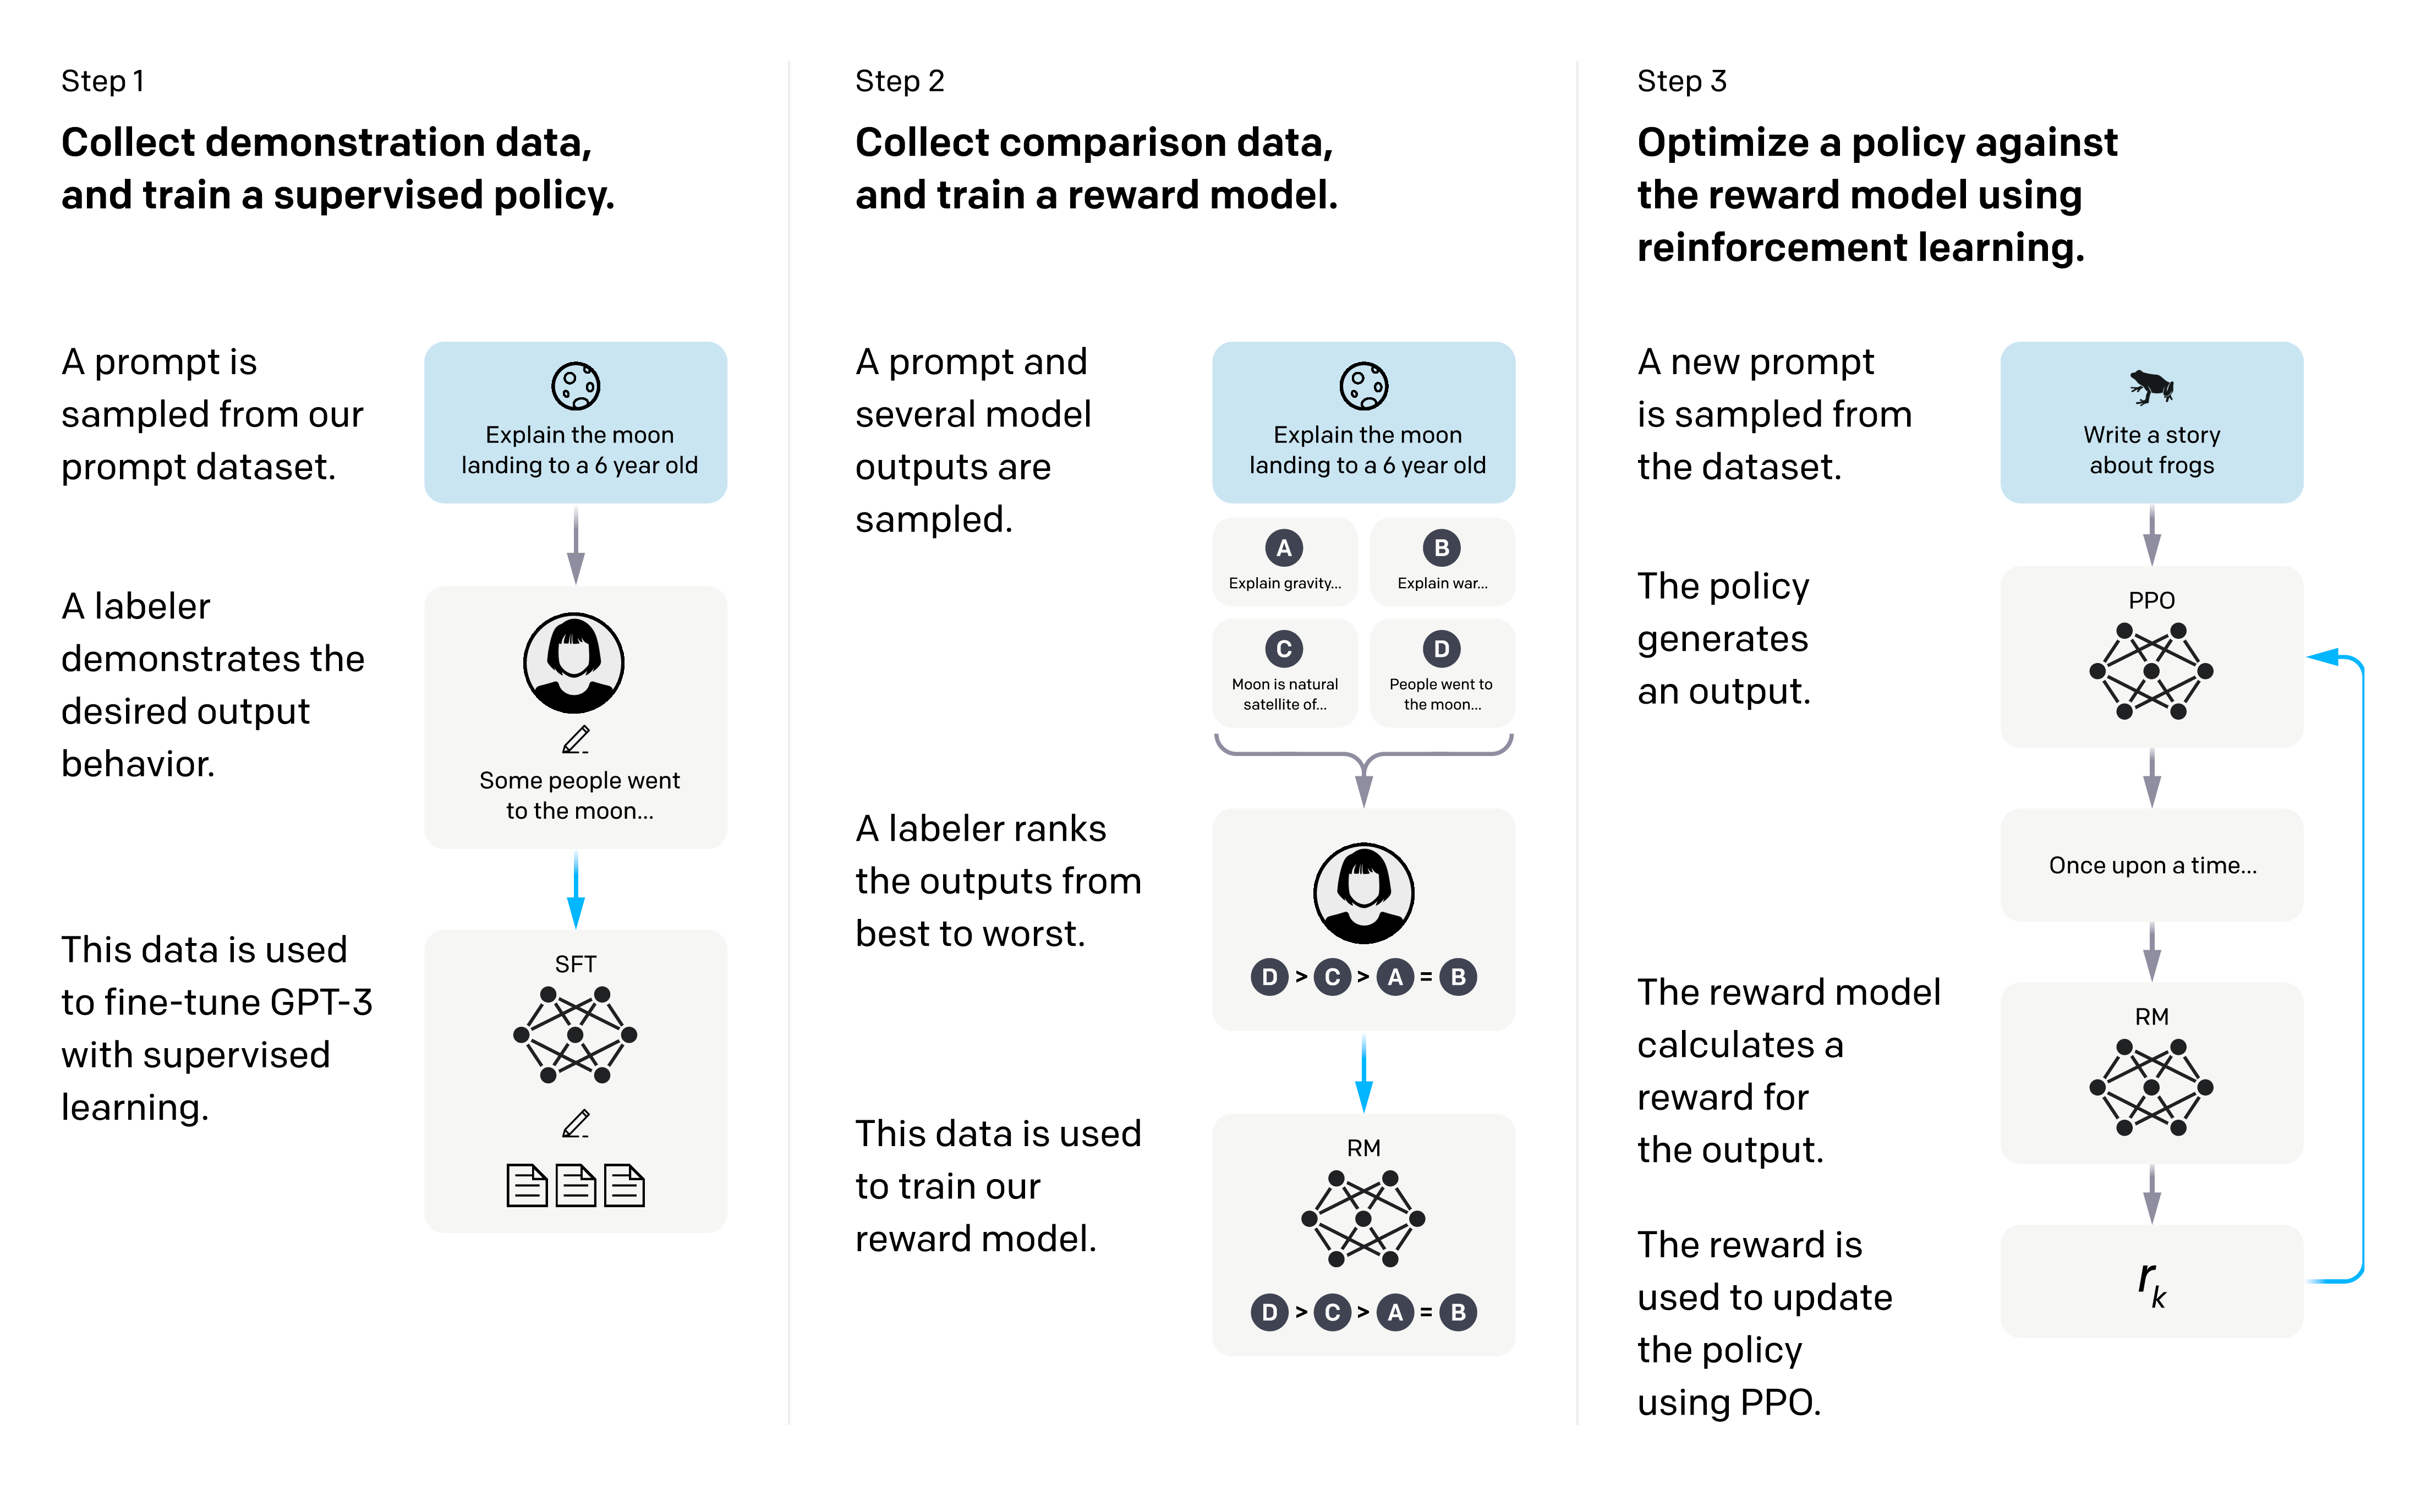
2022–2023 (InstructGPT): one pipeline — SFT → reward model → RL.
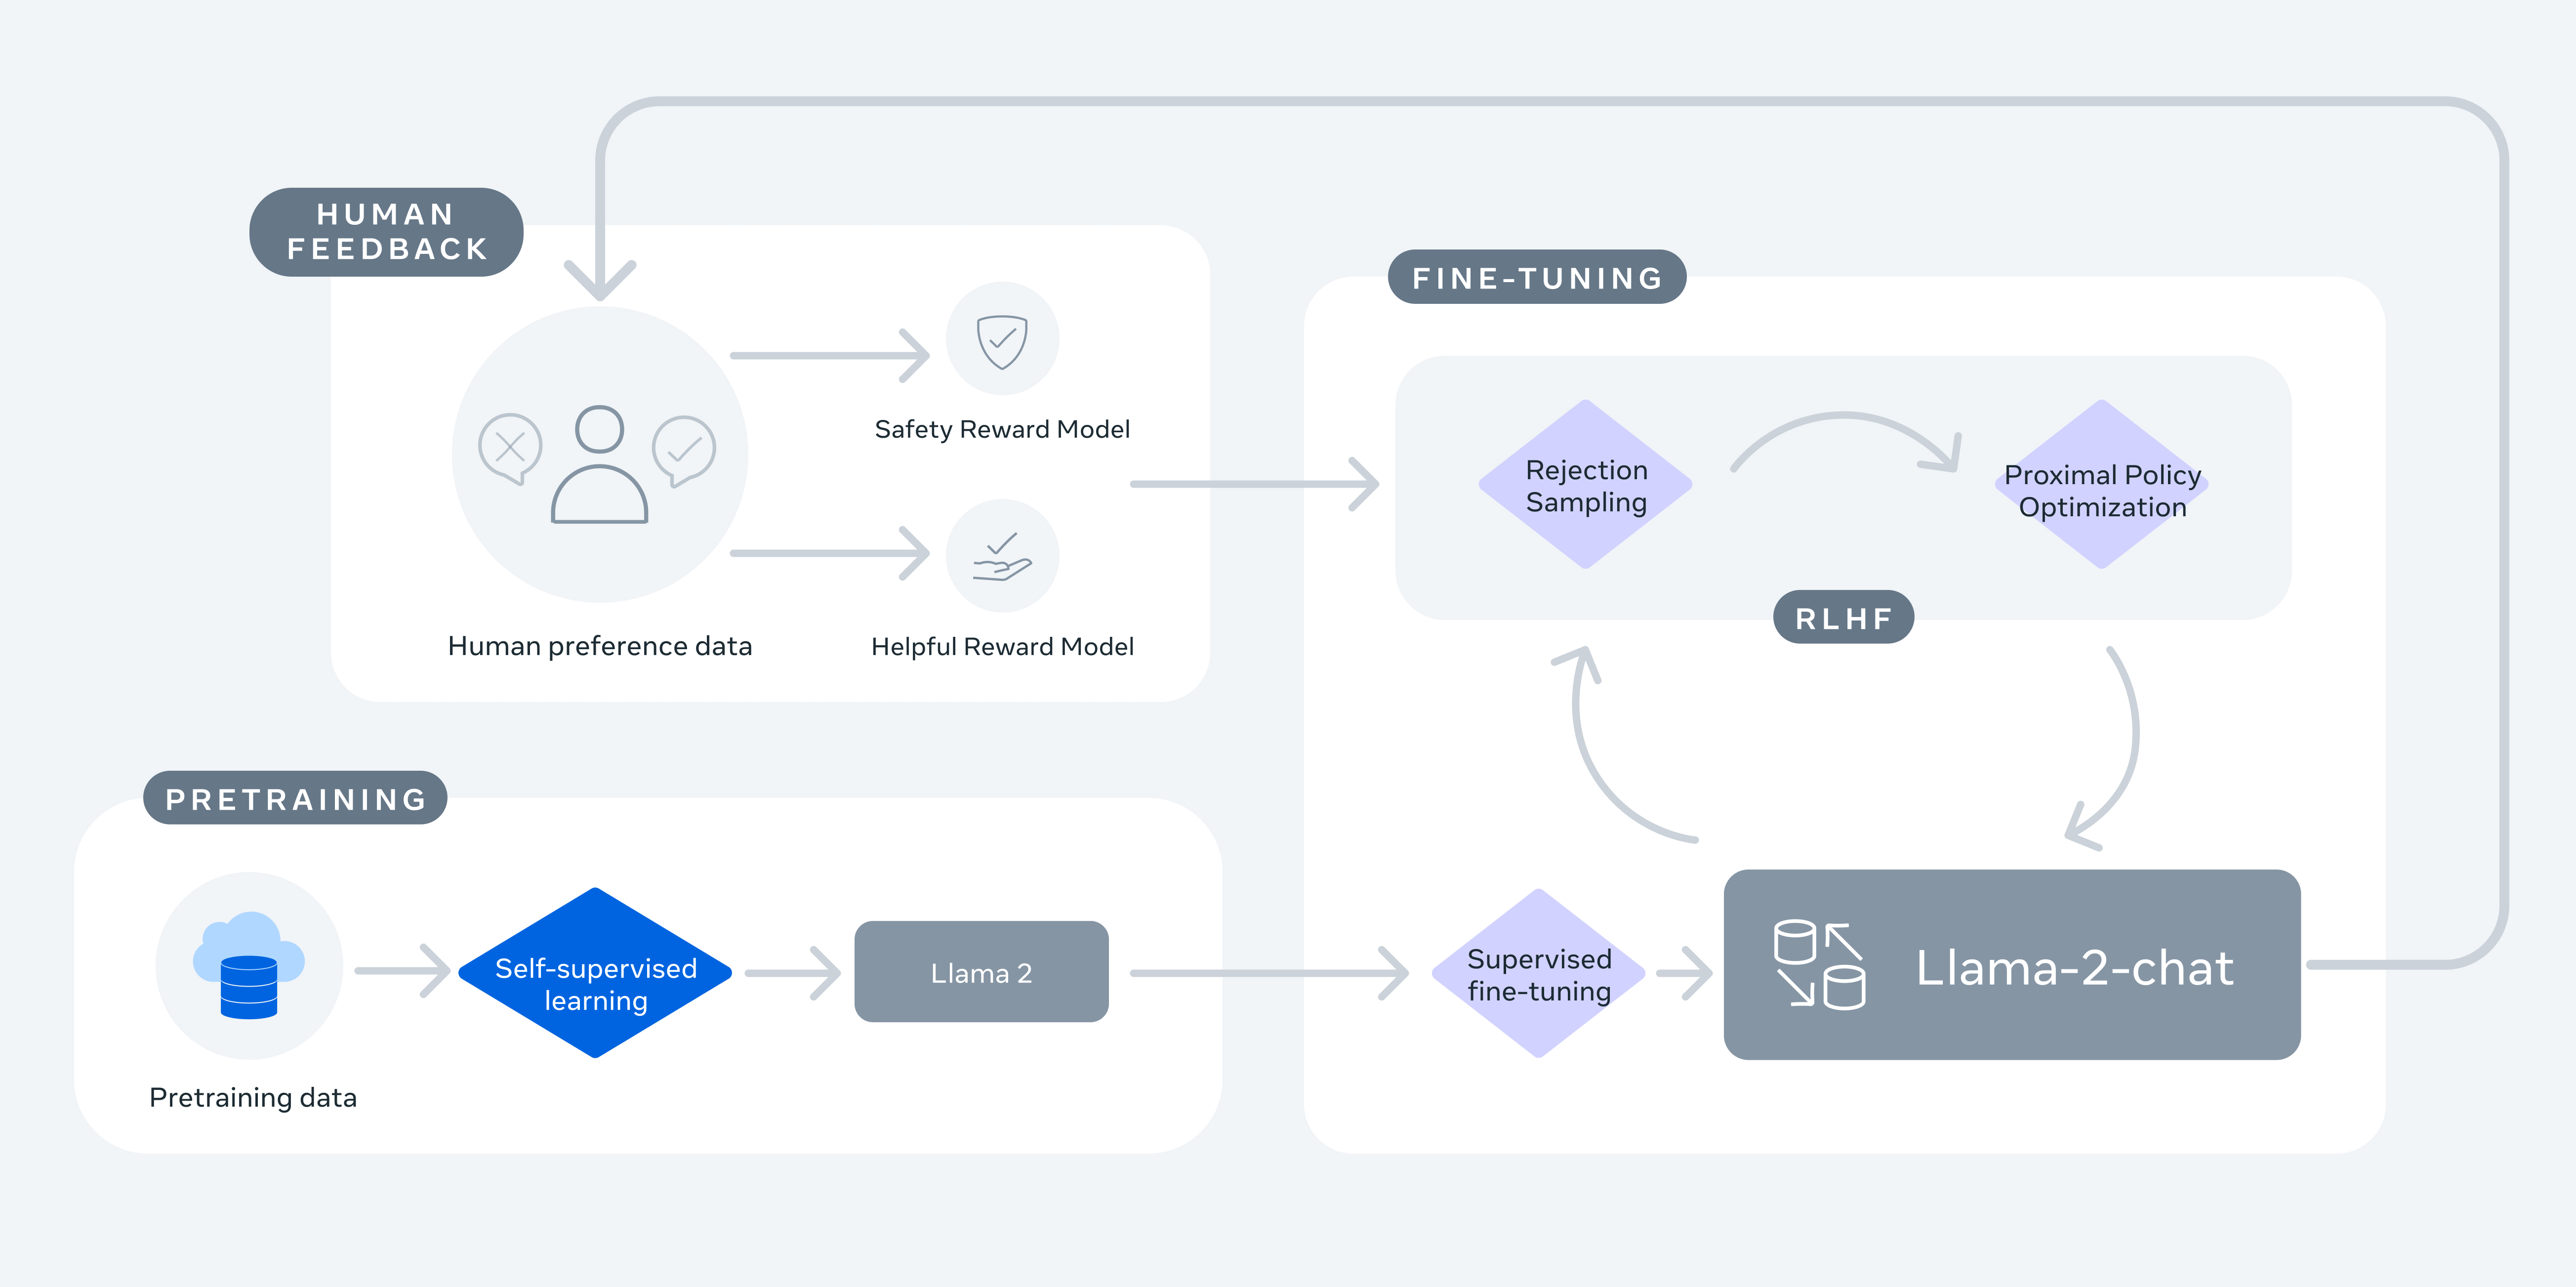
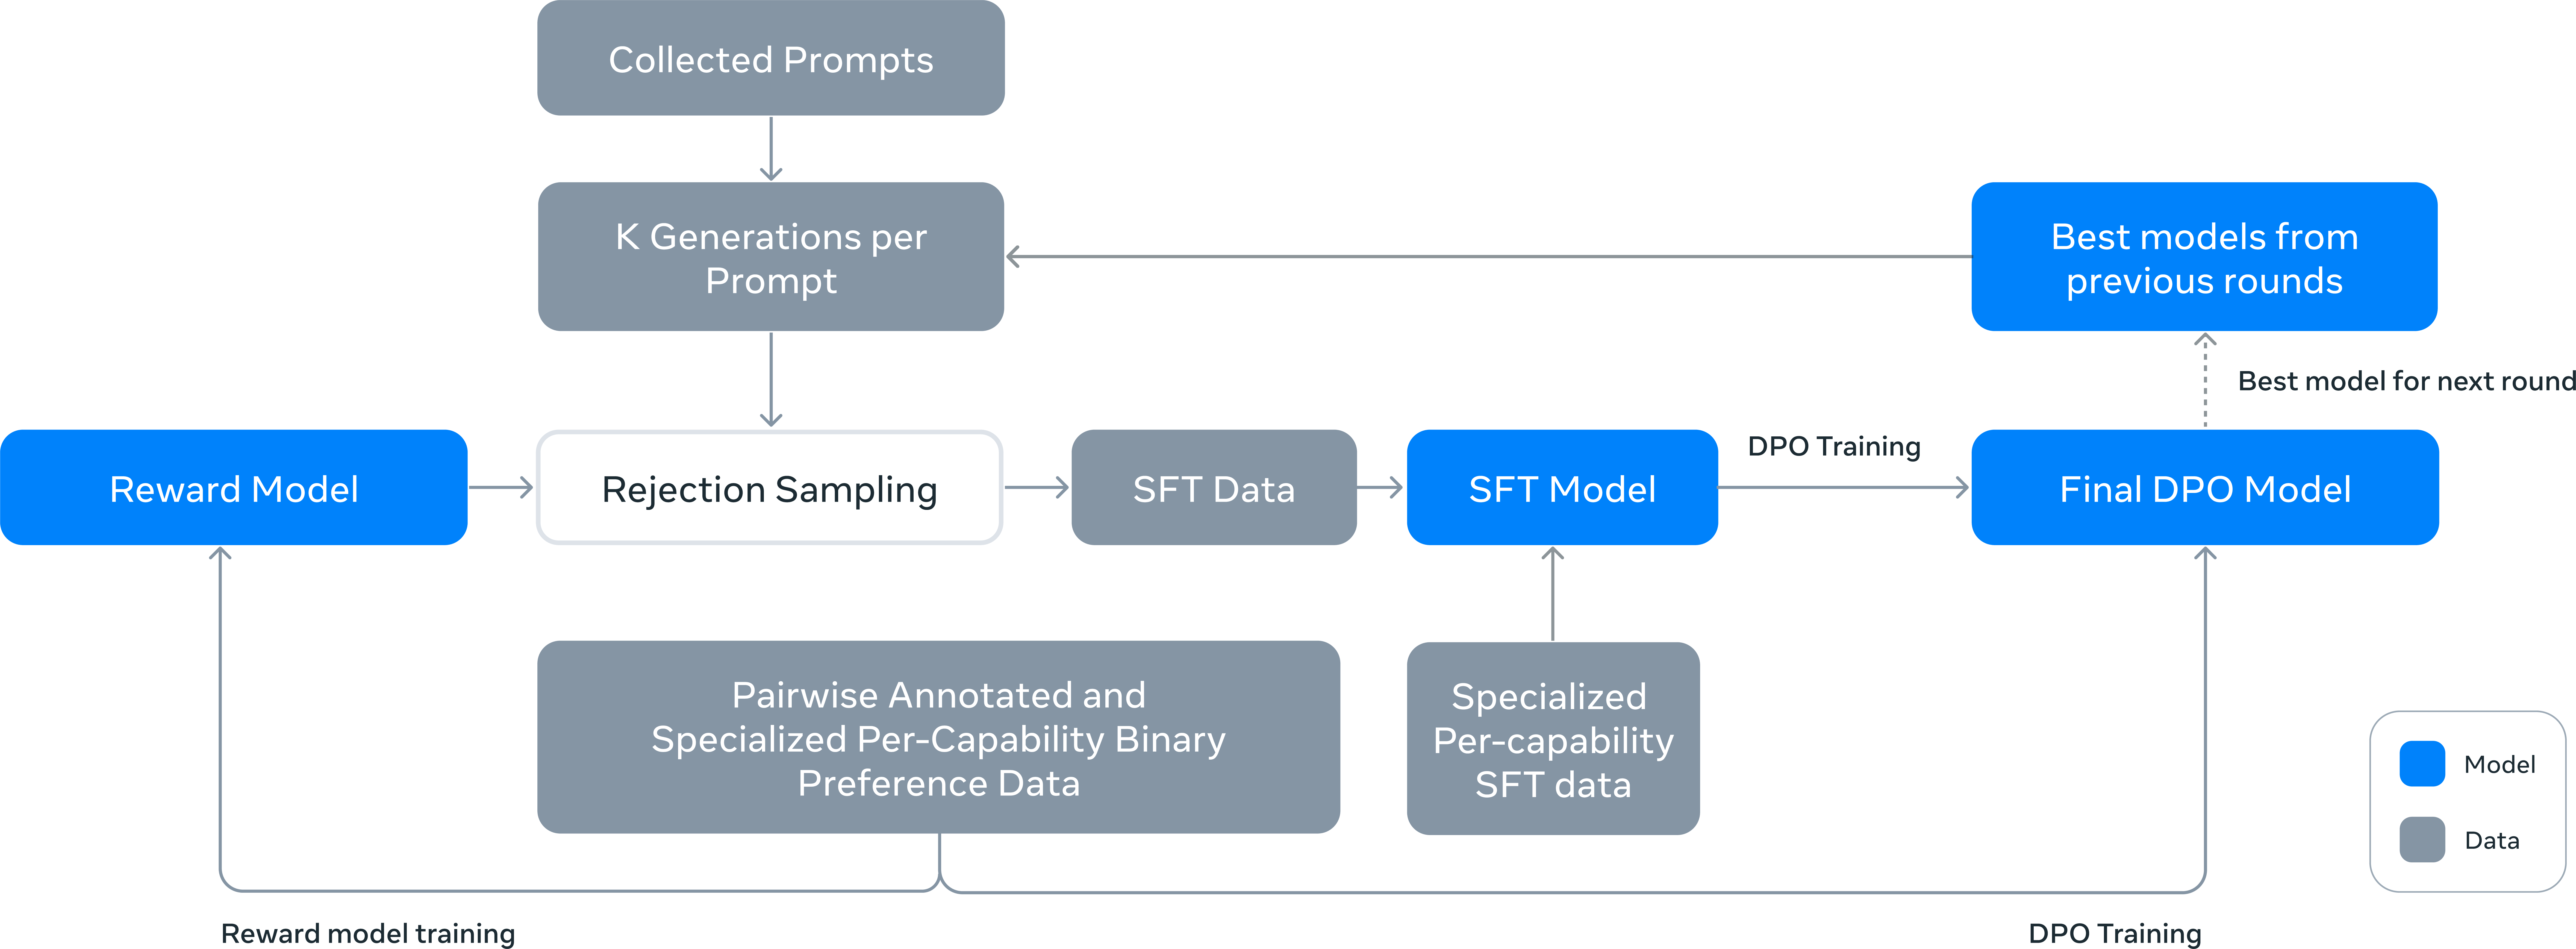
2024 (Llama 3, Tülu 3, etc.): open recipes formalize SFT → DPO → RL with verifiable rewards. Closed recipes use many stages of RLHF.
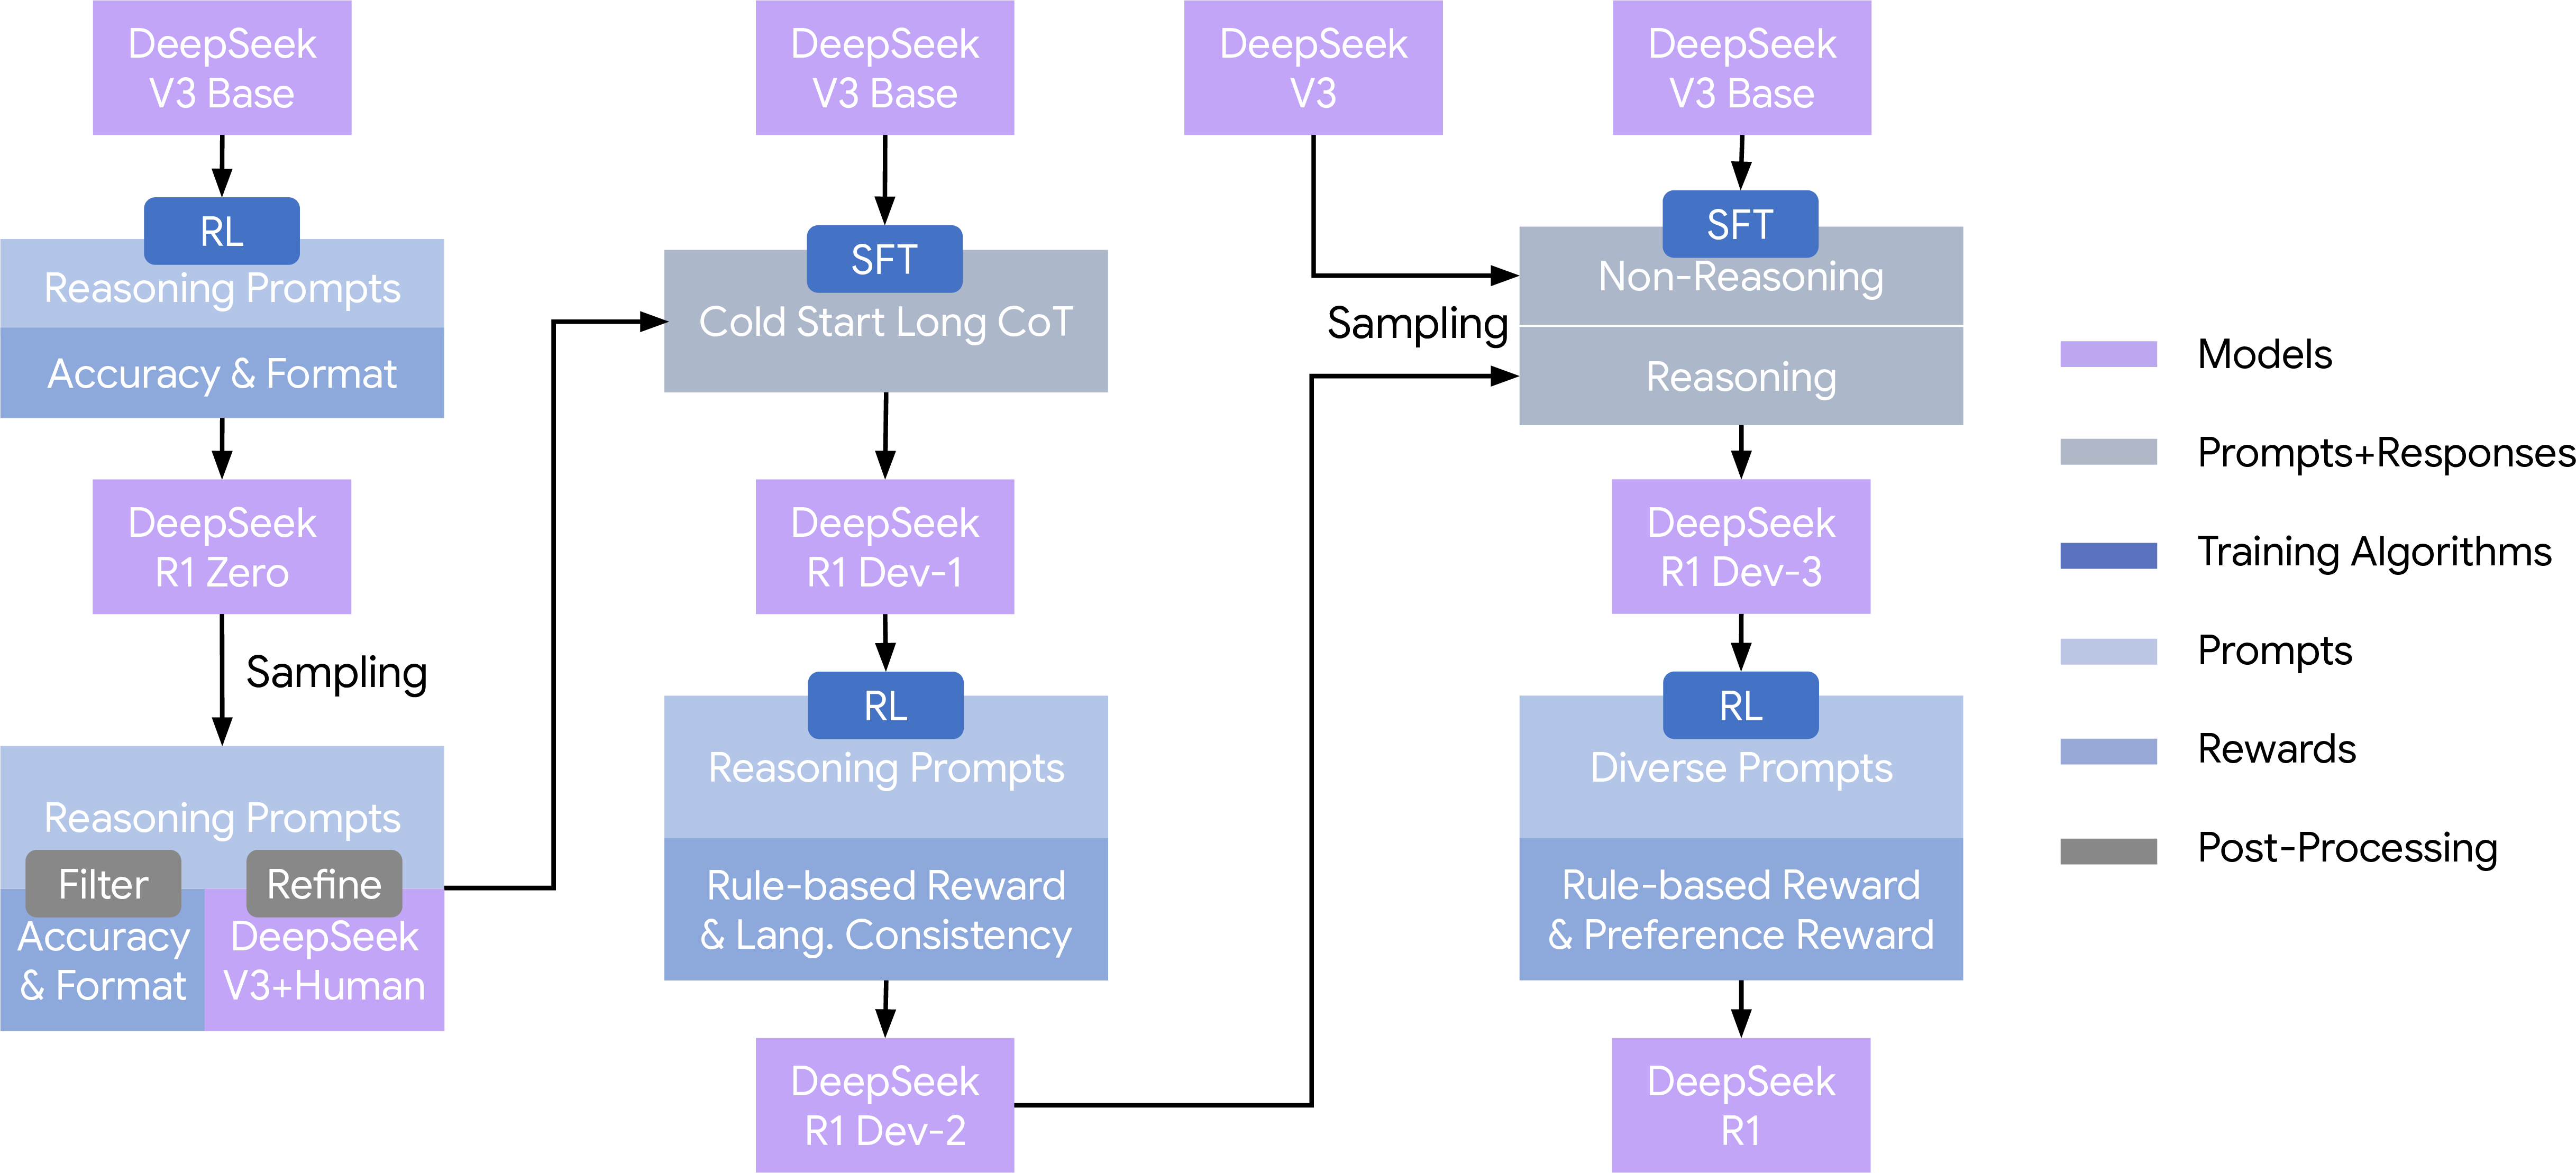
2025 (DeepSeek R1): reasoning RL (R1) makes large-scale RL the centerpiece.
2026 (MiMo Flash V2): recipes fragment into many specialist models that are merged back into one.
The new thing: MOPD
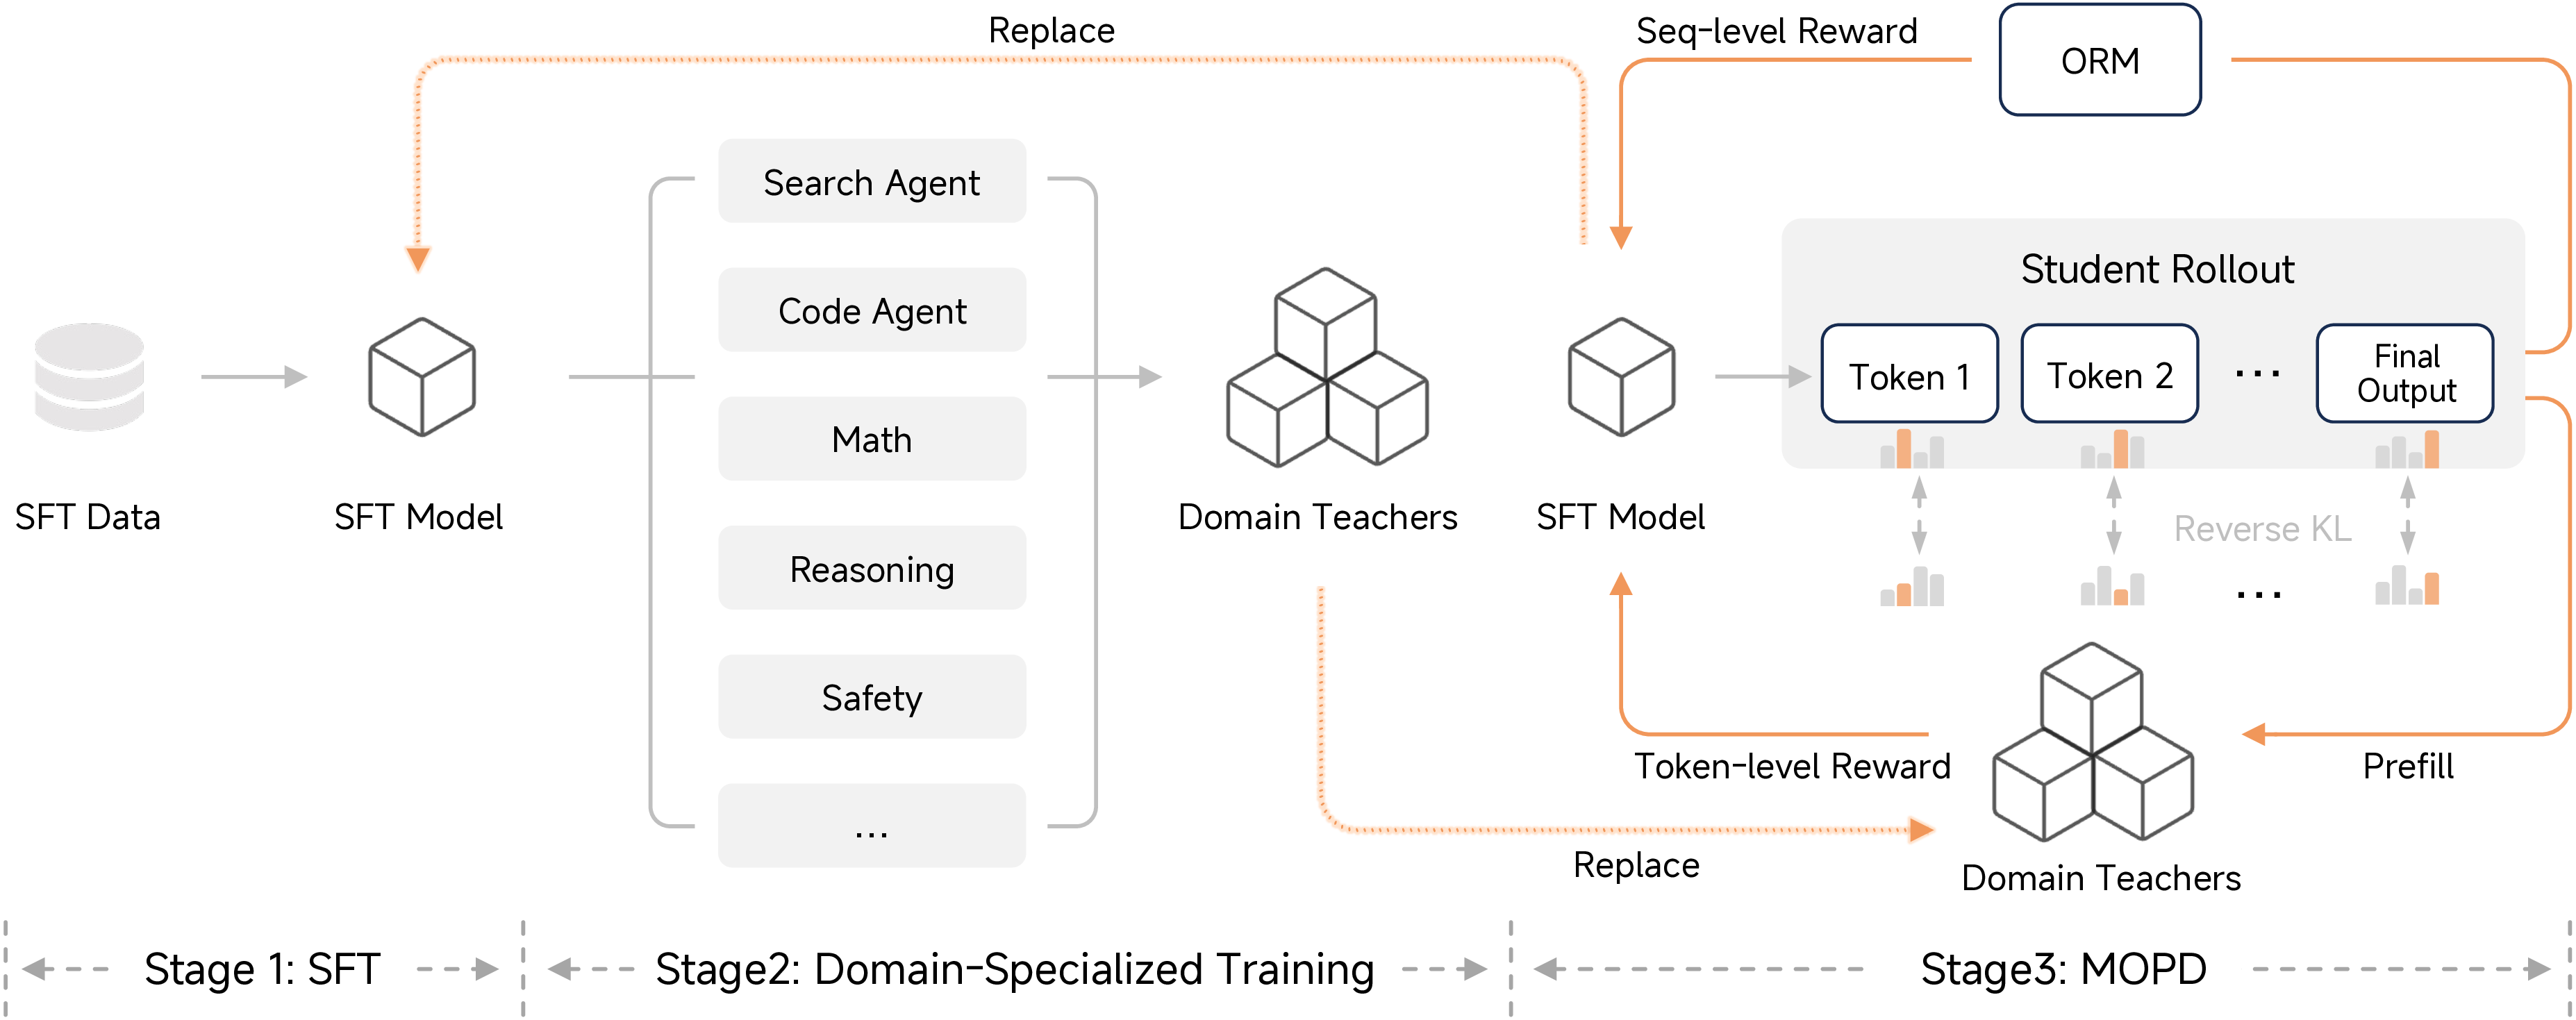
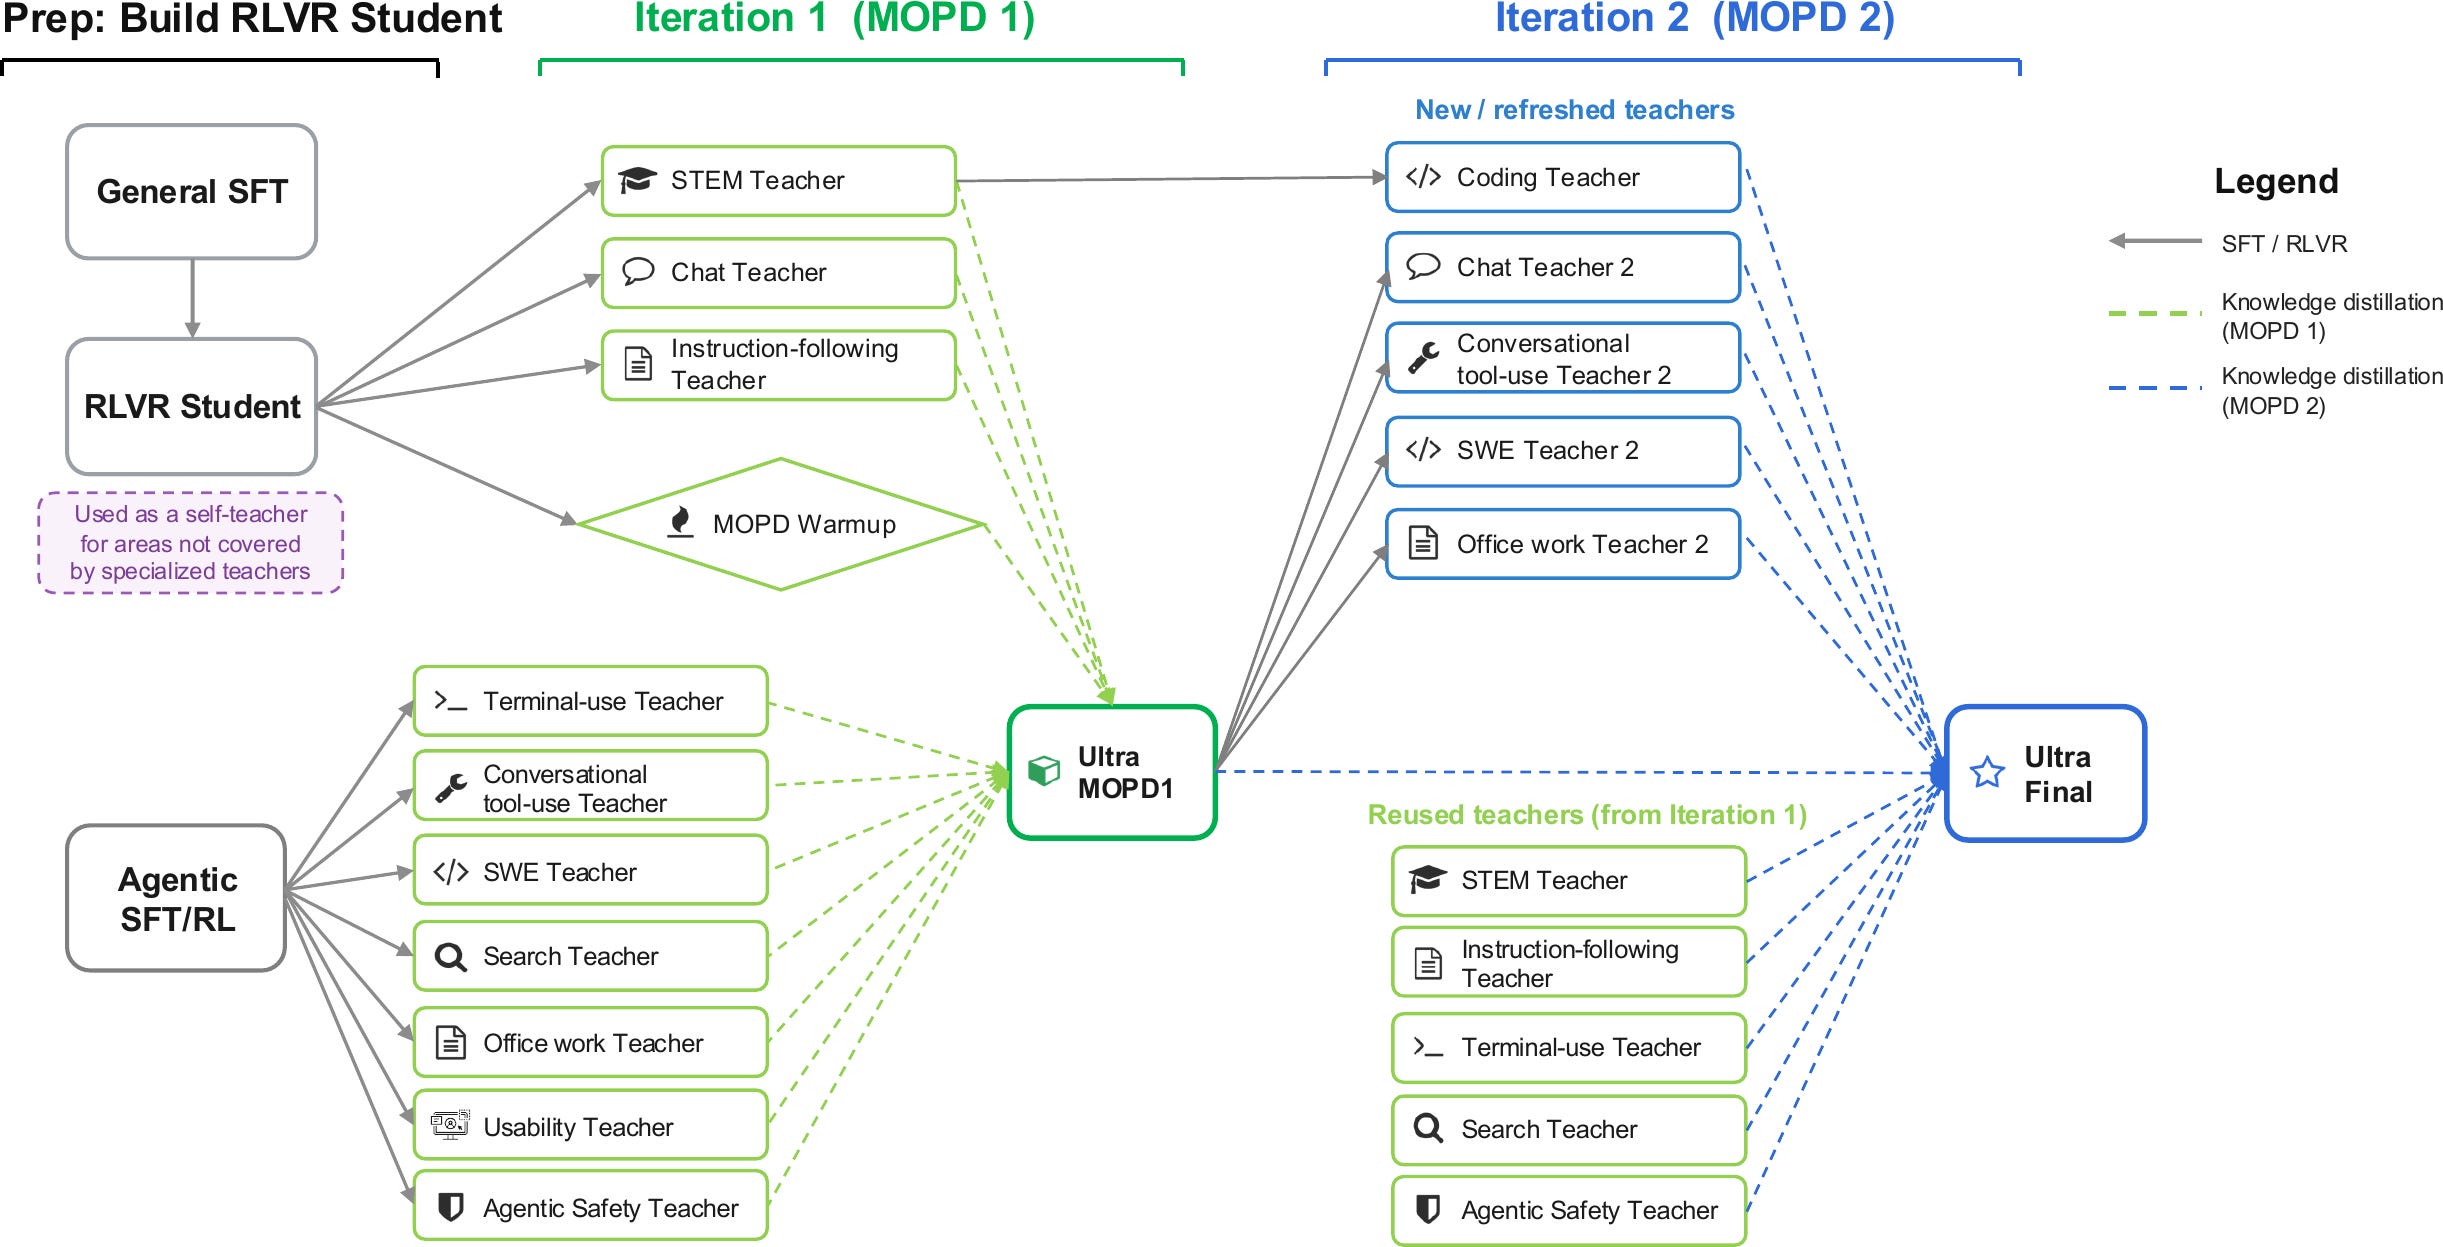
Multi-teacher On-Policy Distillation (MOPD) is the pattern showing up across the 2026 frontier.
Train N domain-specialist teachers (each: SFT, then RL on the relevant domains).
Train one general student by sampling its own trajectories (this is the final post-trained model).
On each rollout, minimize reverse-KL to the relevant teacher’s output distribution, token by token.
Lineage: MiMo Flash v2 introduced it → DeepSeek V4 & Nemotron 3 Ultra scale it to >10 teachers.
Why did MOPD emerge?
RL got expensive and conflict-prone. Mixing math, code, and agentic RL in one run eventually trades capabilities off against each other.
Specialists are cheap to make / organizationally scalable. SFT-then-RL on a single domain is well understood and parallelizable. As post-training becomes more complex, scaling it across organizations is a big win.
On-policy distillation matured. Literature and know-how continued to emerge through the RLVR renaissance.
MiMo Flash v2 (Jan. 2026) — where MOPD started · paper
Stages: Stage 1 SFT → Stage 2 train ~6 domain-specialist teachers (with older style post-training recipes) → Stage 3 MOPD into a single student.
First clean articulation of multi-teacher on-policy distillation as the consolidation step — replaces a single monolithic RL stage with distill-from-specialists.
Nemotron 3 Ultra (Jun. 2026) — two rounds, many teachers · paper
Stages: SFT → multi-teacher on-policy distillation, run over two iterations, with >10 teachers spanning reasoning, code, math, and agentic domains.
Novel: multi-round MOPD across different domains — distill, then re-distill from refreshed teachers.
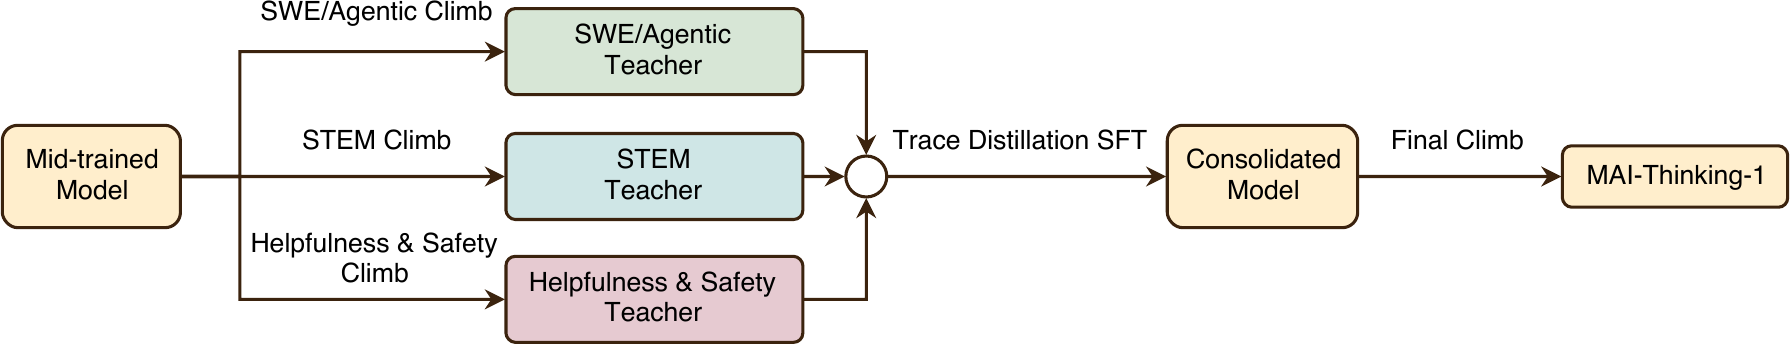
MAI-Thinking-1 (Jun. 2026) — closer to R1 than V4 · announcement
Stages: mid-trained base → 3 specialist RL “climbs” (e.g. STEM) → trace-distillation SFT to consolidate the climbs → a final RL climb → MAI-Thinking-1.
Closer to DeepSeek R1 than to V4 — multi-stage RL with trace-distillation SFT to consolidate, not on-policy MOPD. Not the only lab without MOPD!
Kimi K2.5 (Jan. 2026) — agentic, multimodal · paper · blog
Stages: text-only SFT → joint text–vision RL across coding, vision, reasoning, agentic tasks. (No mention of MOPD.)
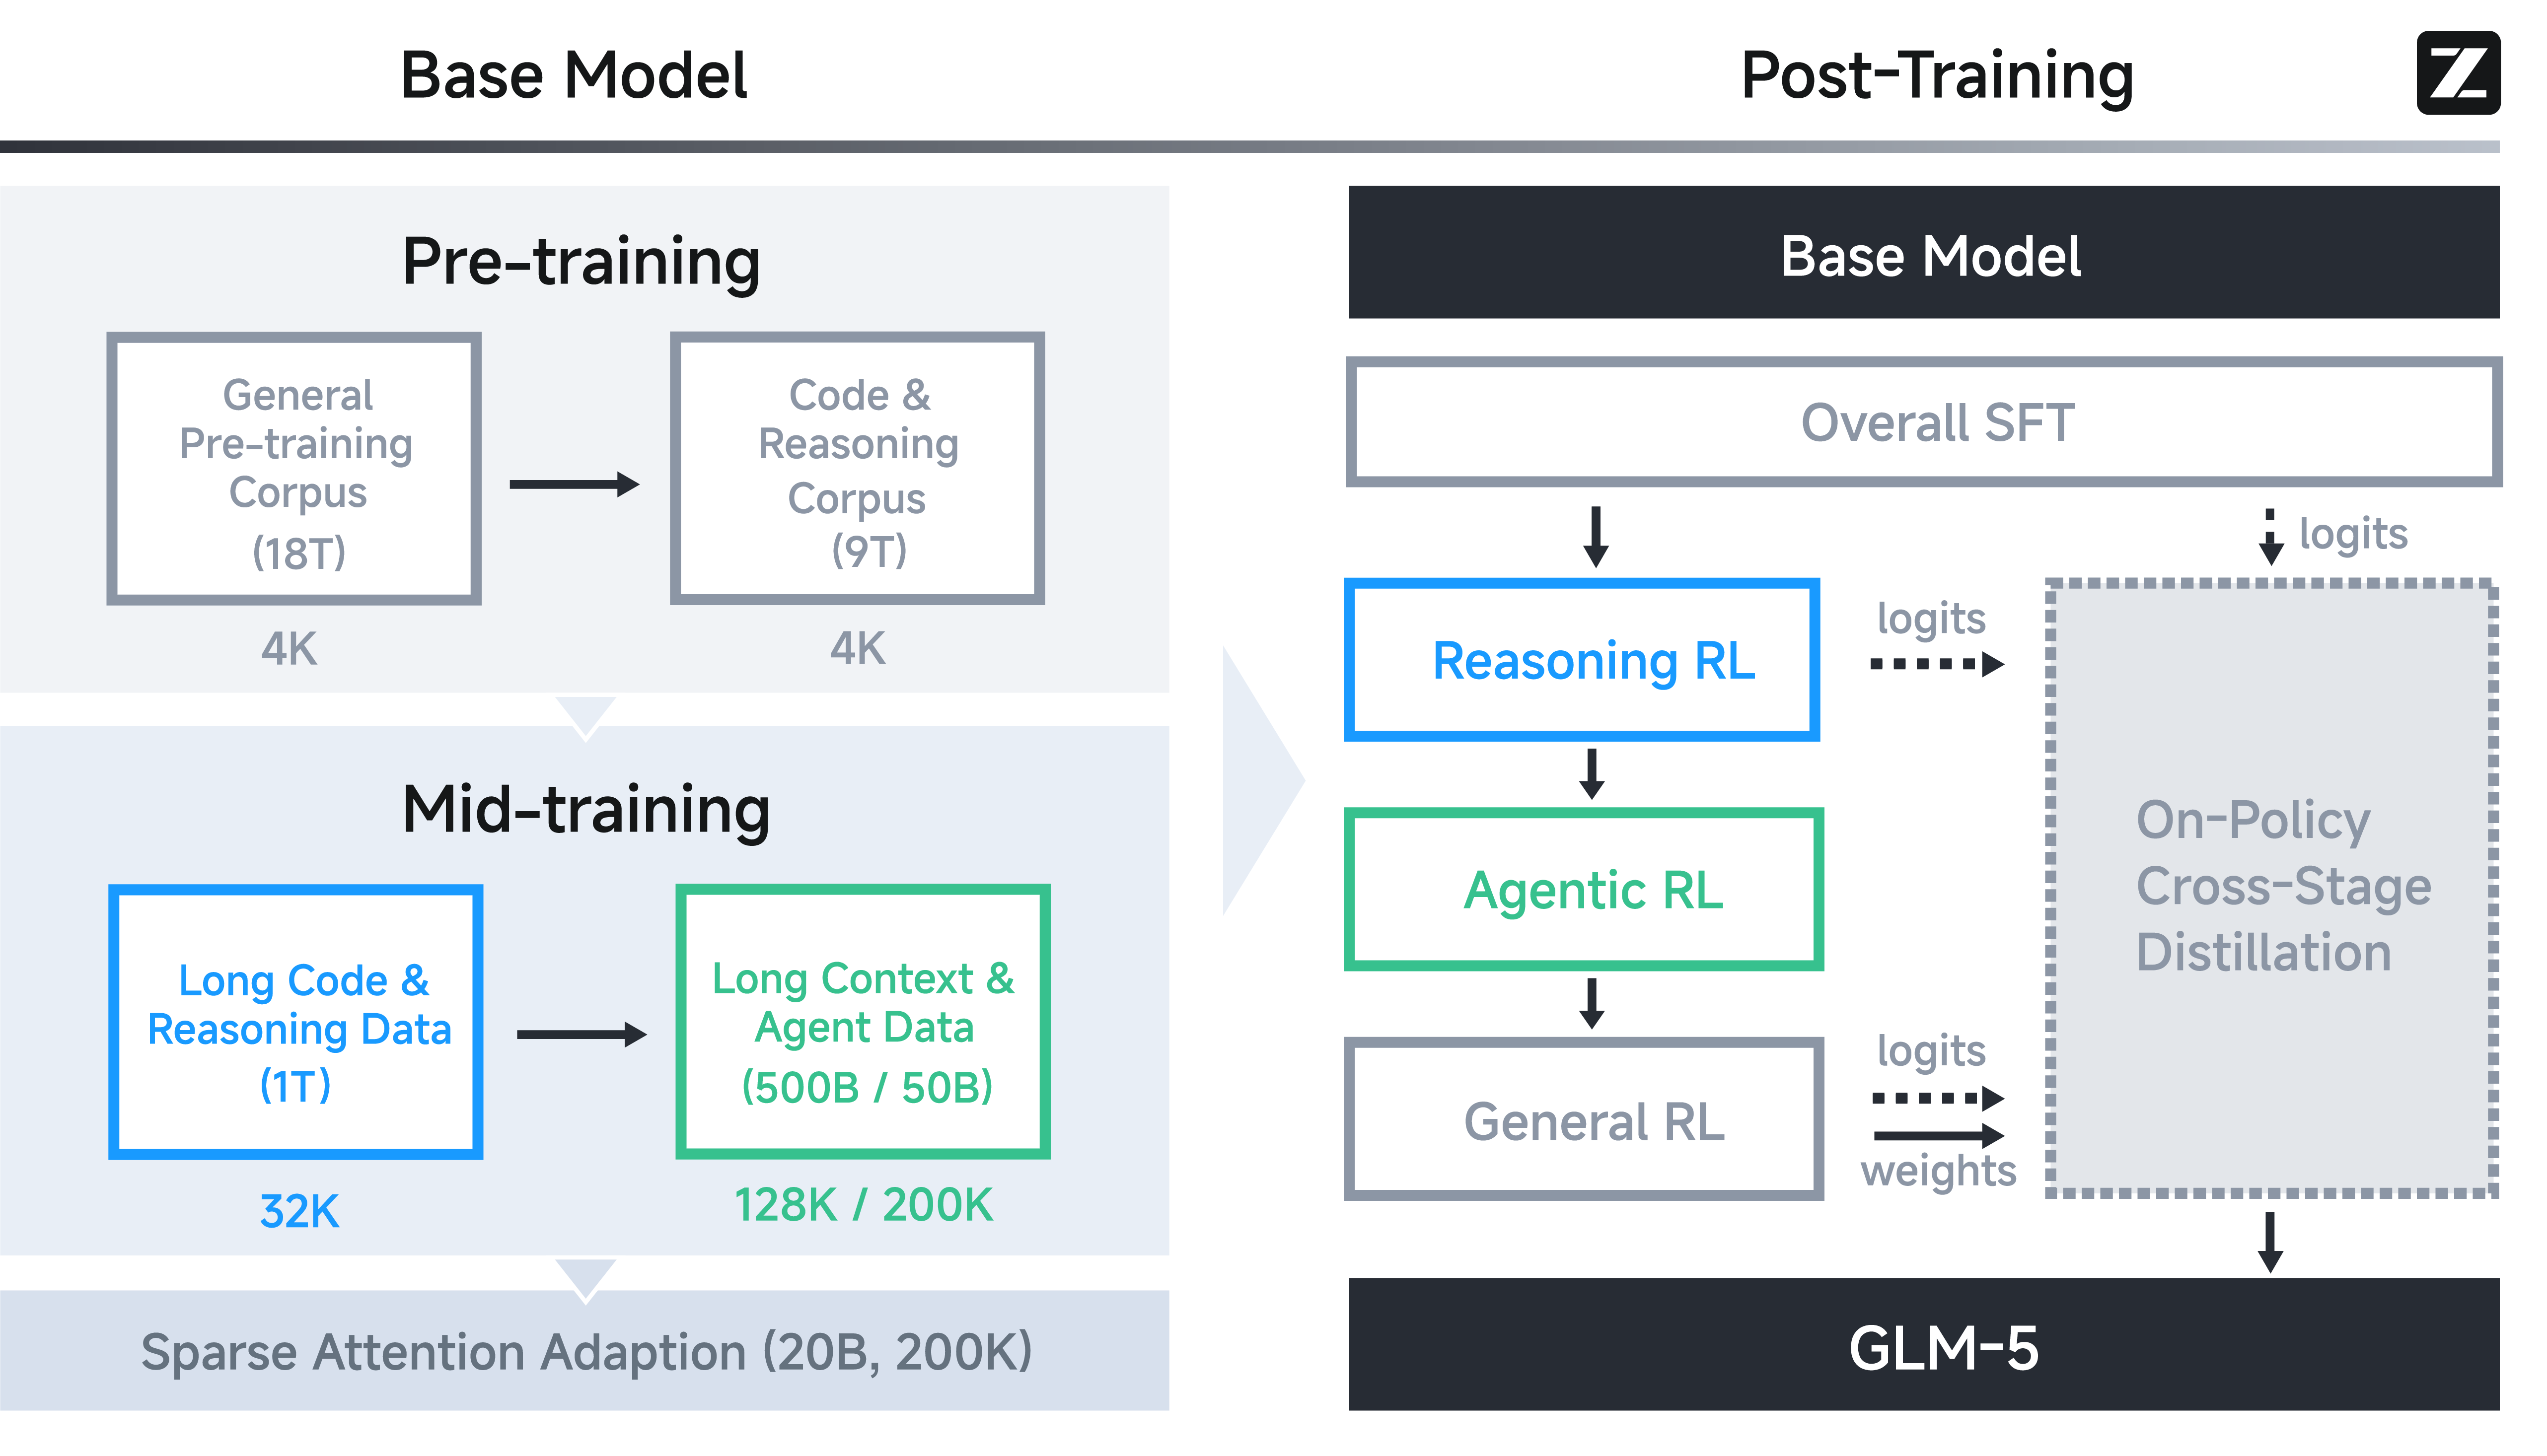
GLM-5 (Feb. 2026) — staged RL by capability · paper
Stages: Base → SFT → Reasoning RL → Agentic RL → General RL.
Transcript
00:00:00 Nathan Lambert: Hello, we are back on a Interconnects conversation. I don’t really say I do interviews. People criticize me ‘cause I interrupt the guests too much. ‘Cause I’m not a good interviewer, but I’m here to entertain people. Um, this is also fun for me because I’m trying to make, like, a post-training course, and it kind of fits as, uh, in the advanced end of this.
So it’s kind of a crossover between Interconnects content and other stuff that I’ve been spending my time on this summer. So I’m happy to welcome Finbarr back. I think... Are you the first return guest? I haven’t checked.
00:00:37 Finbarr Timbers: Oh, wow.
00:00:37 Nathan Lambert: Um, Finbarr and I worked on this sort of post-training recipe stuff for a while at AI2. Um, I left recently. This is one of Finbarr’s last days at AI2. It’s already been announced. It’s not a spoiler here. So we’re gonna kind of reflect on some things on building post-training recipes for OLMO. Um, then we have a little, like, review slide deck and notes on the kind of state and evolution of frontier post-training recipes over time, which is pretty interesting because there’s, what is it, like two to four kind of canonical recipes that there has been.
So it’s kind of interesting when you see the field converge on something new, which it’s doing right now with multi-teacher on policy distillation. For some reason, that’s a bit of a mouthful. It is a long acronym. And then we’ll just kind of end with various discussion points on post-training and what we’re up to. So, happy to give you the floor if you have any hot takes you wanna start with to get people to, draw people in. Otherwise, I think, uh, I’m excited to kind of reflect on this, ‘cause I know you’ve been reading a ton of papers recently and kind of prep, laying some of this groundwork.
00:01:43 Finbarr Timbers: Well, yeah. I mean, today is my last day at AI2, so it- it’s ki- it feels very appropriate to be, to be talking to you as you’re the one who recruited me to AI2. So, uh, yeah, that’s pretty special, and it’s great to be, uh, yeah, the, the first repeat guest. I feel honored, uh, to be back on. So yeah, thanks, uh, for having me.
00:02:03 Nathan Lambert: Yeah. Do we wanna start with OLMO? I think that-
00:02:05 Finbarr Timbers: Sure
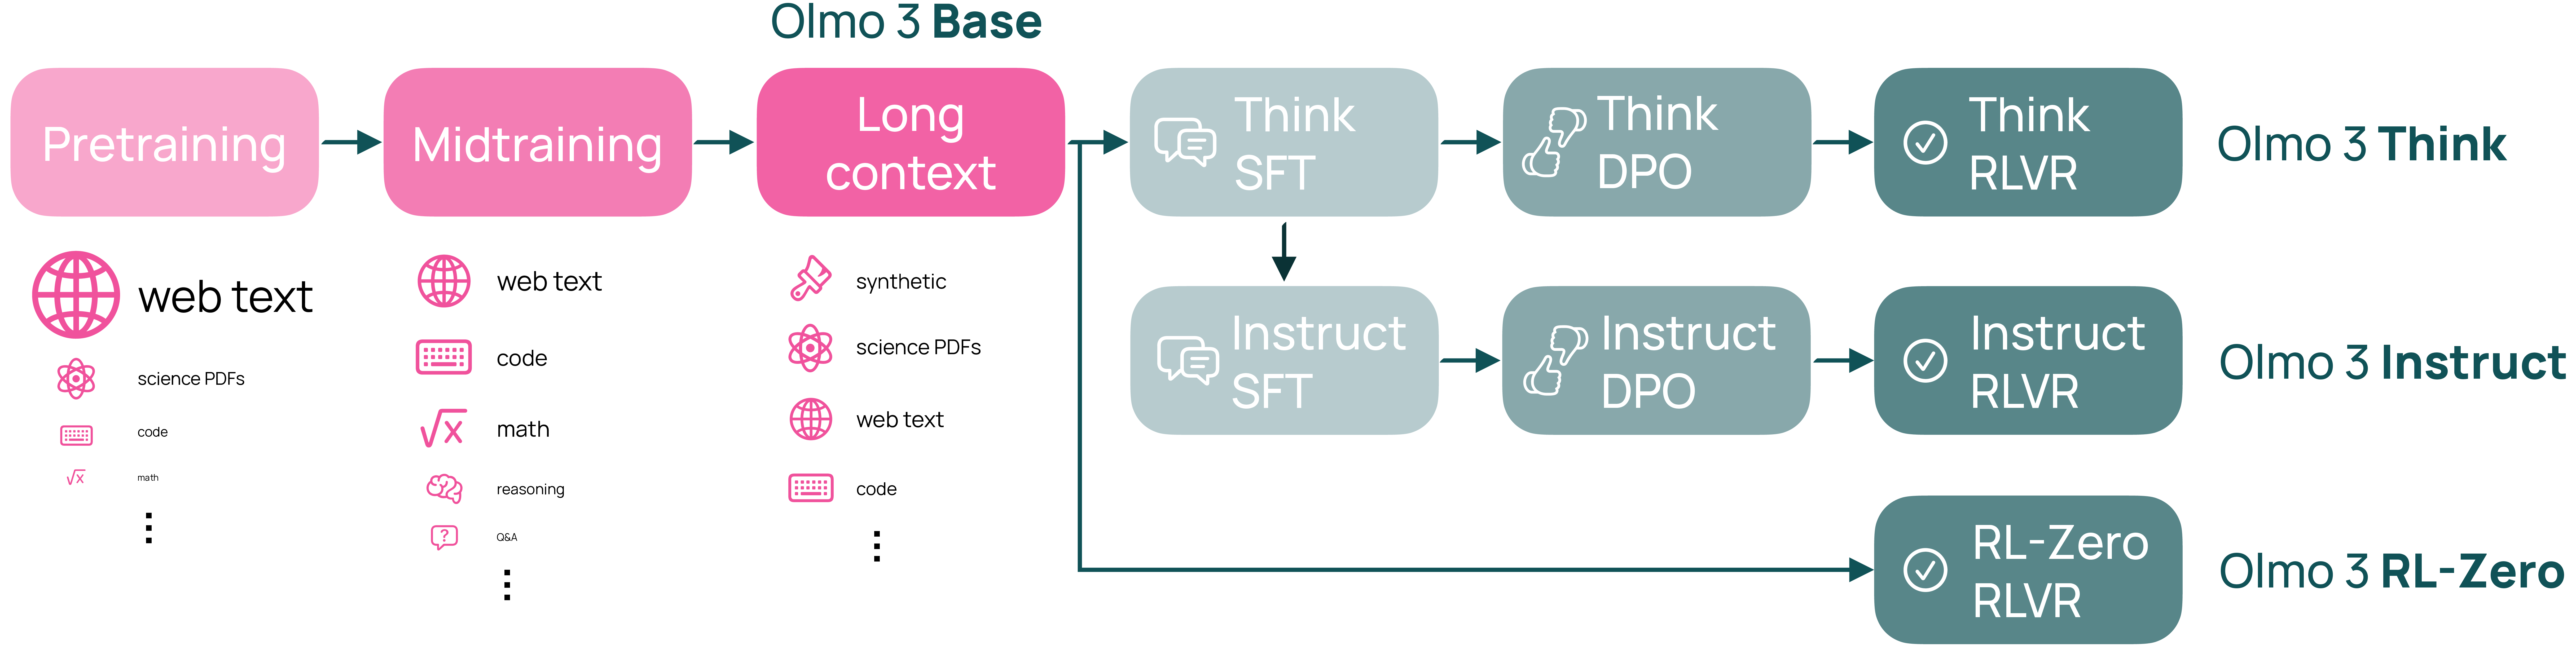
00:02:06 Nathan Lambert: ... people... I think I, uh, need to do this carefully, but I’ve talked about OLMO-3’s post-training many times to people. I haven’t done this in a very direct way on the podcast, but I would say that post-training OLMO-3 to make this reasoning model was a major accomplishment for many individuals to do this. But also, the complexity of what we were doing was pushing against the limits of AI2’s organizational capacity, and a lot of modern post-training is, like, your ability to wrangle compute data into a work stream.
And in order to do that in a complicated way, you really are wrangling an org chart. And that’s like part of why it’s like OLMO-3 was, by its nature, pretty late as a reasoning model. It was, like, a pretty rigid reasoning model, and that’s, like, partially reflected in the recipe being pretty simple. But then when you, like, compare it to all these new recipes with tool use and multi-teacher distillation and all of this, it’s just like a, a, a fork in the road where it’s like you could do this very simple thing and make a strong recipe, but it is not representative of what all the frontier labs are doing.
And I think that that kind of fork in being able to say that things are similar happened kind of after Tulou-3, where Tulou-3, I think, was also much simpler with this three-stage SFT-DPO RL recipe. But that simpler recipe was probably closer in outcome to what the labs are doing, but now doing that sort of three-stage recipe for a reasoning model, and especially a tool use, like, agent model, just doesn’t really apply. And that’s the point. That’s why I think the point of this podcast is to be like, what are the, what are the way, what are they doing to make these, like, true frontier models, and then shed some light on how it contrasts to the more a- like, open academic ones.
00:03:56 Finbarr Timbers: Well, actually, I think that’s interesting. What was the proce- so, you know, I, I only, um, came around for OLMO-3. I wasn’t around for the earlier, um, versions. What was the process like to go from Tulou-3 to OLMO-2? Because, like, y- just looking on, on Archive, um, I think Tulou-3 came out in November of ‘24, and then OLMO-2 came out in December of, of ‘24.
00:04:22 Nathan Lambert: We just applied the recipe.
00:04:24 Finbarr Timbers: Yeah. I, I mean, so, so I think that actually, like, yeah, and then, you know, um, DeepSeeker-1 came out in January, end of January ‘25, and, you know, OLMO-3 was then released in October. Was it October or November of ‘25? Like, I think-
00:04:39 Nathan Lambert: I think November.
00:04:41 Finbarr Timbers: Yeah, November. Yeah, right. It was November. So it’s-
00:04:43 Nathan Lambert: It was like do or die with Thanksgiving.
00:04:45 Finbarr Timbers: I remember that. Uh, yeah, ‘cause Canadian Thanksgiving had, had already happened-
00:04:50 Nathan Lambert: Yeah
00:04:50 Finbarr Timbers: ... which, yeah, I was happy. Um, but, uh, like, like I think it was, sure, maybe it was late, but I think it was only late by a few months. Like, it’s, it’s actually, like, you know, if I think of my past experience with model turnaround times, like a nine-month model turnaround, you know, from R1 coming out, like that’s actually, that’s not bad. I think, you know, something like six months would’ve been nicer, but-
00:05:12 Nathan Lambert: I, I think it’s slow ‘cause we didn’t re- it would be fast if we had rebuilt the R1 recipe. But what we did was we, like, ported reasoning into our existing recipe-
00:05:21 Finbarr Timbers: Yeah. Okay
00:05:22 Nathan Lambert: ... which is a simpler task, but has, like, a lower ceiling, in my opinion. Where it’s like the DeepSeek and the newer style recipes, which we’ll talk about, I think they just have a much higher ceiling in how much you can keep hill climbing them. Or they’re just, like, more prescri- more pedagogical of what the frontier is doing. Like, for the size models that OLMO was, which was like 7 to 30B, I’m not sure that doing this DeepSeek style RL first recipe is actually useful.
00:05:52 Finbarr Timbers: Uh, well, I, yeah, I think that’s a good point. And I mean, I think that’s really reflected in what we see in the research where you s- you know, you obviously you see the big, uh, the step change and you know how quickly things are improving When, you know, R1 comes out. So, like, I think that a great point, and it really does seem to saturate, or to, to not saturate, sorry, with, with compute. Um-
00:06:11 Nathan Lambert: Yeah. Um, shall we just do the slide deck? We’re throwing around, like, recipe-
00:06:15 Finbarr Timbers: Sure. Yeah, let’s do it
00:06:16 Nathan Lambert: ... names. Like, I feel like it might be useful to just do it because a lot of people probably want to follow but don’t exactly know. I’m, I’m gonna share, I’m gonna share a screen. So people listening, it might be useful to either, you can pull this slide deck up on your phone and click through it. It’s not super information dense, but you can also just watch it on YouTube. All of this will be linked.
Generally, this is just like a quick survey on how frontier recipes have evolved. We’ll go through the history quickly and then talk about what is currently happening and kind of probably interleave the old mode discussion we were having. Uh, okay. There’s a bunch of canonical recipes we’ll talk about. This is where I got the two to four number. I think the recipes are like InstructGPT, which is what coined the initial RLHF with this like three-stage idea, which took a while to get people to move on from, which was like SFT reward model and RL.
And I see as like Llama 3 and 2.3 as kind of practical implementations of that with, with other tricks of the trade. So those two could potentially be merged together. It’s just like kind of pre- and post-ChatGPT moment. And then the two most recent canonical recipes that we’ll cover in this I would say are like DeepSeek-R1, which is the shift to doing like reasoning focused and bigger RL stages than this kind of SFT focus from before, and then NeMo Flash and some of the new models from 2026 which add this distillation element.
00:07:42 Finbarr Timbers: Well, and, and I think it’s worth pointing out too that it’s not just NeMo Flash, like it was kind of a consistent theme. Like you saw this with DeepSeek, th-they referenced it in, uh, the V3 paper and then it’s, you know, it’s Qemi K 2.5, it’s GLM 5. Like it’s all of these papers, you know, start talking about this specialist, um, RL stage.
00:08:03 Nathan Lambert: Yeah. I think there’s a debate on how we draw it and whether or not distillation is... If you’re, if you have distillation as a technique, as a key milestone, then they were, the Xiaomi was the first and, but it’s kind of a march over time where you kind of see them change, and we’ll, we’ll go through this. I don’t, I don’t need to interrupt.
00:08:23 Finbarr Timbers: When you say distillation, I do think it’s important to distinguish between the straight up like, you know, distillation of the leading closed models and, you know, distillation of these domain specific models where, you know, I, I, I suspect that the, you know, the, the Chinese labs are doing both.
00:08:41 Nathan Lambert: Yeah.
00:08:41 Finbarr Timbers: But, you know, a lot of what they’re do, you know, but a, a lot of what they’re doing is this, um, training these domain specific models like, you know, a math model, a coding model, uh, you know, logic model, whatever, and then distilling those models back in and not just distilling from... So when we’re talking about distillation, it’s not just distilling from the leading closed models.
00:09:01 Nathan Lambert: Yeah. It’s a pain. I agree. The distillation term is horribly overloaded. Um, there’s a review slide. Do we need to review multi-teacher on policy distillation? It might be too complicated to need to do it. We could come back to it. I think I kind of want to just go through the actual models, and then we could use the supporting slides as needed. Um, this famous InstructGPT three-step thing, I think many people have heard of it, but this is what constituted post-training at the time of ChatGPT coming out, so it’s kind of important grounding of this human supervised SFT data, mostly human supervised preference rankings to make a reward model and then do RL on that, and the model gets better.
And it’s pretty interesting how all of these have been kind of phased out, at least in terms of what we know openly, where they’re, we don’t use that much human demonstration data for SFT. There’s likely some human preference data still in the loop, but I would guess that synthetic has a much bigger role, and there are reward models, but they’re like not the cl- key RL target anymore. So in four years, most, almost all the canonical pieces have been moved on. And like this evolution is kind of within there. I think the early models after InstructGPT, like Llama 2, um, even Llama 3, these are pretty similar, which is like you’re starting to break down this recipe with different tools like projection sampling, DPO, some increased iterations. I think increased iterations is just that there was more incentive to squeeze more out of the models, and they just like broke things down more, where InstructGPT seemed like a bit more open-ended research where this kind of cleanness was fine. So-
00:10:48 Finbarr Timbers: Well, I think that’s interesting, uh, with respect to how much everything has scaled, uh, right? Because, you know, InstructGPT was before ChatGPT was, was released, and so, you know, it’s something, like just the complexity of what was done is that which a small team or even a single team could do. But then when you start looking at, you know, Llama 3, like it just starts to be a more complicated process and, you know, where you start to have a lot more, you know, specialized data and there’s, you know, a lot more, you know, room for scale and for kind of money and complexity be poured in.
00:11:25 Nathan Lambert: Yeah. It’s like, uh, both for-profit and nonprofit efforts to do post-training want me to advise them, and I’m like, “I don’t really know how I’m gonna give you advice unless I’m spending twenty hours a week look, understanding the details of your recipe,” ‘cause it’s like, well, I can’t really give you a one sentence thing of do X without understanding all the complexities of the model and the post-training process that go into it. Which makes it, like makes it hard from kind of like a transparency point of view. Even if it’s fully detailed, it’s definitely still hard to modify and study.
00:12:00 Finbarr Timbers: Absolutely.
00:12:02 Nathan Lambert: So then like two through three in AI2, a lot of this was we’re trying to beat the results of this Llama 3 post-training, which is pretty complicated, but we don’t have the ability to scale the organization as far. So I, I, I think that’s a big reason why the actual workflow is a lot simpler, where we have three clear stages that are doing slightly different things, and they build on each other. And that’s like... It’s never stated very explicitly in these papers on like how the org chart impacts the recipe, but I would, I, I think it’s a very strong signal within the, at least the delta between the fully open work and the kind of partially open work that you get from industry.
00:12:43 Finbarr Timbers: Yeah, absolutely. And, and I think especially as we’ll see with the domain-specific models, like that’s like really clear, like something where you could really easily scale up your org chart to-
00:12:54 Nathan Lambert: Yeah
00:12:54 Finbarr Timbers: ... build that up.
00:12:56 Nathan Lambert: Yeah. And I threw Olmo 3 in after this, after the two through three slide, mostly just to show that the recipe was so similar to two through three, and the org chart hadn’t really changed. Like we didn’t have more ability to scale, and like there was a, a little bit of separation between the model types, between like the think and the instruct models. But like without a major reinvent- like a major org change, it was just kind of stuck in this and do the best you can with it.
00:13:22 Finbarr Timbers: Yeah. Absolutely.
00:13:23 Nathan Lambert: Be- because like the real big change was this with DeepSeeker-one. They, I had never seen this plot before, but they had this plot, maybe they added it for the nature version of the paper, where they kind of show their recipe, where they like take the base model, they do RL zero, and then they sample from the RL zero to like filter prompts, and then they use that as SFT. This is like going through this. They use that as SFT for the next version of the model to create like a development internal RL DeepSeek-R1, and then they do this like repeated sampling to train multiple RL versions and kind of distill, distill in the sense of, of clarify and refine the reasoning behavior of the model before going through the final pipeline, which again is a mix of, um, reasoning and non-reasoning SFT into a bigger RL run. And-
00:14:11 Finbarr Timbers: Well, and I think this is really interesting because it starts to show, I mean, first of all, the, the complexity here. We’re starting to use, um, yeah, like synthetic data as this primary input here, but it’s not just like, you know, it’s trying to elicit, you know, specific behaviors, and it’s this kind of like industrial process, um, instead of like this, you know, it’s not as much of an elegant research recipe. It’s more like, you know, we train a model, and then we use it as best we can, and we keep iterating. Um, but I think the other thing that’s interesting is, is we’re starting to see here the SFT serving as the cold start. First of all, where, where that’s, you know, I think before SFT was more of like a generally useful stage, whereas here its, its primary purpose is this, this cold start for RL.
And then the other interesting bit is, you know, DPO, uh, starts to disappear at this point from the leading recipes. I mean, Olmo 3 still does it, but you know, basically everyone else does away with it and just, you know, has the preferences included, um, as in, as a reward model or, you know, at so- at some way, um, in the reward bit of the RL stage. And so that’s a really interesting change, where the, the supervised part of post-training is just, you know, massively deprioritized.
00:15:27 Nathan Lambert: Yeah. So my hypothesis for the dropping of DPO on these models is that, uh, as, as you’re doing like a cleaner recipe, essentially the need falls away. Versus if you look at Olmo, which is taking tons of potential gains by refining your model on outputs of strong open weight models, like largely Qwen and DeepSeek is the training data for the SFT of Olmo 3. Uh, and like the delta between that SFT data and the base model is still pretty big in the probability distributions. So DPO kind of helps further refine and clean up that distribution in a way that kind of has very rough edges. And but when you have a more refined, like industrial process on post-training, th-that will, that potential benefit will be harder to gain. Something interesting that I didn’t fully con-confirm before this is, for example, NVIDIA used to also be on this DPO train with their smaller Nemotron models.
And, and I would guess that potentially like D- Nemotron Ultra would not. But it’s, and, and that’s because they’re at much further down this development tree and using on pol- like these more on policy methods for creating the SFT data. And their model, I would guess, will become kind of more robust out of distribution and like have weird, less weird rough edges before because of it. So that’s kind of my hypothesis on DPO, and people that use DPO will be looked down upon. But it’s like if you’re trying to bootstrap a recipe off the ground and just take gains where you can, I still think it’ll work for a lot of people in a kind of compute efficiency standpoint.
00:17:05 Finbarr Timbers: Yeah. I mean, I think generally, uh, there’s something interesting with the, the preference tuning that, yeah, like maybe, um, it isn’t being given the proper, um, respect that it deserves. ‘Cause o-one of the interesting bits about the Nemotron 3 super paper was that they saw pr- they, they do a, a traditional RLHF stage in their RL, which has also, you know, fallen with fashion and development, and they see pretty massive gains with it. So I think some of these changes are more, you know, driven by what’s in fashion rather than perhaps like a fully rigorous, you know, set of ablations.
00:17:41 Nathan Lambert: It’s very remarkable to me that the preferences loss function can do so much for these models. Like the models have so much potential there, and it’s just, it’s really a contrastive loss on pretty granular feedback. And they learn all sorts of things. Like they’ll, they’ll get better at math and code, or their reasoning strategies will be refined. And so I, I... That’s remarkable to me. I think there will still be funny research on like using preference- Base losses with verifiable outputs. Like, I, I think all this would work. Like DPO on verifiable rewards and stuff like this, it’s just kind of intellectually less appealing.
00:18:19 Finbarr Timbers: Yeah. Well, I think that’s, uh, you know, that’s where I thought that the, uh, delta learning, um, hypothesis style, uh, DPO, like what Olmo-3 did, where you, um, where the, the preference, you create these synthetic preferences by having like strong, by like bigger and smaller models of the same family, like is where you get your preferences from. I thought that was a really interesting signal because it, it seems really analogous to some of the work, some of the guidance stuff that we see in diffusion models, like how you have the classifier-free guidance, which has something similar, and there, there were very similar results there, which showed that you could have the--
But like one signal they used was further along in training versus earlier in training models as like, uh, a source of, of signal that you could guide along. And, and that worked quite well. And so I suspect that these signals, um, for, for preferences in that way, like that they could actually be more robust, but because, you know, some of the largest labs don’t have to do that, perhaps we’re not citing them as much.
00:19:18 Nathan Lambert: Yeah. Or they don’t tell us. Like, to continue this, it’s kind of cool to look at-- So the DeepSeek models have kind of gone through this, what I would call like l- closer to Llama recipes to DeepSeek-R1, which is d- like most definitively the canonical recipe for reasoning models, and then continue to change closer to this multi-teacher format. So if you look at the VC-3.3 paper, um, before R1, they do something remarkably similar to two to three type thing, where they have a mix of SFT and then they use it ver-- like this RL on verifiable rewards. They didn’t call it that, or their paper wasn’t out at the time. And so they did this before R1 came out, which was just kind of a less reasoning-focused models and used the same tools but with a different ratio of implementation weight.
00:20:07 Finbarr Timbers: And, and what’s interesting is that this comes out basically at the same time as two to three, and it’s a very similar two to three and Olmo-2. It’s a very similar recipe, just done with more complete.
00:20:16 Nathan Lambert: Yeah. Yeah. And then we have this R1, which we’ve just talked about at length in January, which is a month later. They have a few more releases through this. They have some updates to their V3 and R1 models, which have dates, which are largely the same recipe. And then the next documented change in their recipe was V3.1, which is when they merged this thinking and non-thinking into one model, which everybody that does this says, has said that it has been hell to train in. But you kind of need it from a serving perspective, and it’s obvious that long term, at least obvi- it’s obvious to me that long term all the models will be reasoning models, and you’ll just have reasoning models that are very efficient based on the gains that are there.
So this is kind of a needed change that they made. And then in December of 2025, they released V3.2, which is when there’s kind of meaningful changes to their recipe, and they’re talking about this expert creation with separate mini recipes, and then using that within their kind of R1 data process to do SFT data and then like a big RL run at the end with GRPO. So it took about a year for this, uh, like kind of evolution of the R1 style recipe to land in their models. And I think this, this is like a very big complexity step that isn’t represented in something like Olmo-3, and it’s kind of where you can see a fork in the recipes over time as like they, it, they become way more industrial and scaled at these frontier labs.
00:21:46 Finbarr Timbers: Yeah. And I think, you know, another one good thing here, just from a historical note, is that I think it was with the O3-24 release where they updated the original V3 paper. So, you know, V3 comes out before R1, then R1 comes out, and then after R1 comes out, they actually go back and update the V3 paper, maybe getting ready for the nature submission or, or, or something.
00:22:07 Nathan Lambert: Yeah.
00:22:07 Finbarr Timbers: Um, and they make a reference there to say like, “Oh, you know, something you could do is you could train these domain specialist models and then combine them.” Uh, and then, you know, that later becomes kind of what, you know, the more of a priority as they talk about in V3.2.
00:22:21 Nathan Lambert: That’s a fun note. Yeah. And then most recently in April 26th is this V4 model, which has even more experts. They add this new loss function for multi-teacher on policy distillation, which I said follow Jiaoli. And this is kind of a microcosm of the arc that the whole industry went through, at least the people who share what their post-training details are, of realizing how core RL is, changing the recipe around scaled RL, and then figuring out how to kind of scale to more domains in the scaled RL format without just like grinding to a halt in operational complexity.
00:22:58 Finbarr Timbers: Yeah.
00:23:00 Nathan Lambert: So then kind of the next stage of this is these, what I call twenty twenty-six style recipes, which are all these models that are doing this multi-teacher, um, infusion of knowledge. And then some of them are using on-policy distillation and some are not. It’ll be one of the key things to see is like how crucial is this on-policy distillation to really keeping up at the frontier. So the paper that kind of, that named this term was the MimoFlash V2 paper. I think the model was released in December and the paper in January, which a lot of things will look similar to this, um, kind of RL, large RL style recipe. But with this large RL run is more, is where the on-policy distillation comes in. So for, I c- this is probably a better time to explain. I have this great, great little feature.
So this is like the summary of what multi-teacher on policy distillation is. Generally, it fits within an RL framework where you have the model you are training, the, like the general model, sample its own trajectories, and then you route the trajectories to various expert models you have trained. And each kind of sample is trained with this distillation KL loss to match the tokens of that expert. And People have, multiple models have shown that this type of supervision is really useful for the models. You could combine it with other RL losses, such as verifiable rewards, which for example, Sasha Rush gave a good mini spiel on that and how they use that with Composer, which is a, a video that I really recommend people watching as well. But the, the key of it is that it is a different loss function, but it plays very nicely in the RL frameworks that people are already using. So they use these teachers-
00:24:45 Finbarr Timbers: Just RL, like it’s, it’s, like if you-
00:24:47 Nathan Lambert: Yeah
00:24:47 Finbarr Timbers: ... actually implement it, you know, I’m talking with some of the people at AI2 about implementing it now. And it’s like you take your RL setup, and then you just, you know, you, you have some very, your, uh, set of tweaks on the, the learner to actually implement this. So it’s quite straightforward.
00:25:02 Nathan Lambert: Yeah, so this is a fancy diagram that makes it more complicated than it needs to be, but it also a very nice diagram, which shows the various, um, domain teachers that they have, search agent, code agent, math, reasoning, safety, and how they put these together. And the, the experts are used both for SFT data and then this final supervision. And the recipe for the experts would look something like this DeepSeek recipe, which is complicated on its own, which is like make a very good reasoning model that is good at one thing.
00:25:29 Finbarr Timbers: Well, and I think it is complicated, but it’s also like if you, if you think about being the actual researcher like working on it, it’s like, you know, you have a base model, and then you have an RL set up, and you know, you’re just constantly updating both and then rerunning RL. So, you know, the, the most complicated like, uh, part of it is just, you know, writing down the history and tracing everything. But it’s kind of like a very natural, organic way, uh, for the r- the RL to evolve through, you know, iterative experimentation.
00:25:57 Nathan Lambert: Yeah. So like once you have a recipe, you’re progressively tinkering with each part, and it’s, it’s fairly stable, but it’s hard to rebuild from scratch. So like we’ll see how, see how long the recipe shape lasts, but it’ll probably be order of years. Um, another big one in this like also shared a lot of details on this on policy distillation approach was Nemotron-3 Ultra, which is obviously exciting to me to have a, like a US-made model that is very strong performance, and NVIDIA released a lot of datasets with it.
But they, they also talked about a lot of their very n- n- like implementation details of what was hard with on policy distillation. I, like I have notes somewhere on this. They do this thing where they have two rounds of on policy distillation, as they found it to be better to integrate some teachers one after another. And the paper has a lot more details. I’ve, I, I don’t wanna go scroll through the paper, but we could also do this. Did you have any o- other impressions? Like I have the, we have this other doc we can pull up that-
00:27:01 Finbarr Timbers: Oh
00:27:01 Nathan Lambert: ... also you might have had other details on it.
00:27:03 Finbarr Timbers: Yeah. Well, I think something else, um, that, that is worth, um, you know, contrasting the, the paper to is the Nemotron-3 super paper. ‘Cause in the Nemotron-3 super paper, they had a similar complicated recipe, but they did multiple rounds of RL. Like there they had three rounds of RLVR, followed by a round of, um, software engineering RL, and then followed by an RLHF stage. So it was, it, it was really interesting to see them go from doing that, like, you know, one of the most complicated, um, RL setups or in terms of, you know, successive stages, uh, that I’ve seen. To then, you know, you know this setup where it’s still complicated, but it’s a lot, um, you know, it’s a lot con- conceptually a lot simpler.
00:27:54 Nathan Lambert: Yeah. I, I pocket the paper up. It’s gonna be hard for me to... I, like I had highlighted a few details. The, the interesting parts are kind of around the, um, various NVIDIA details on all the teachers. There’s just so many details in their paper on training-
00:28:10 Finbarr Timbers: Yeah
00:28:10 Nathan Lambert: ... all the teachers. I think, okay, so I have some of it. I have some of this up. It’s like I have an interesting quote that’s like, “One key finding from our trials of doing on policy, multi-teacher on policy distillation is that teacher models trained with substantially different training pipelines cannot be effectively combined through a straightforward on policy distillation merge, resulting in suboptimal performance.” So it’s like they’d have to do some cross teacher alignment, um, to make sure that they’re actually similar, which I feel like could become a whole, uh, organizational nightmare. It’s like they say, “We hypothesize that when the teacher and student are trained on different SFT data, they acquire different reasoning behaviors and induce different output distributions. This distribution mismatch can cause student-generated trajectories to be out of distribution for the teacher, result- reducing the quality and reliability of the supervision- supervision signals provided by the teacher.”
00:29:00 Finbarr Timbers: Yeah, that’s interesting actually because there was a paper, uh, I, I can’t remember the name of it, but there was a paper that I read, um, recently which claimed that what you need to do is constantly... So, so you know, you know, one thing you could do, which was kind of the, the obvious thing to do, is you, you take your base model, right? You do, um, whatever general SFT that you’re doing, and then you take, you do, you know, a bunch of RL, you train domain-specific agents, you train them, you know, all the way until they’ve converged or until you’ve run out of money.
Uh, and then you take these final experts, and then you do some sort of, you know, on policy distillation to combine them into your, your final model. Um, but with the paper, and I’ll, I’ll try to find it and then give it to you, um, see if we can share it. What they claimed was that you need to, um, instead of using the converged model, you need to do it in like successive stages with like the in-progress model. So if, you know, you train your RL for like a thousand steps, you need to, you can’t use the, you know, the thousand step checkpoint to, for the on policy distillation. You have to do it in stages, and first use the, you know, two hundred and fifty step checkpoint and the five hundred checkpoint and, you know, gradually bring that base model like up to speed or else there’s gonna be too much divergence, and the, the KL divergence will just be like too, um, too distinct-
00:30:17 Nathan Lambert: Yeah
00:30:18 Finbarr Timbers: ... to learn from.
00:30:19 Nathan Lambert: Yeah. So essentially the last state-- sentence in this paragraph I had read most of is literally like, “We encountered this issue in practice because the teacher and student models were developed in parallel.”
00:30:29 Finbarr Timbers: Yeah.
00:30:29 Nathan Lambert: It’s like they’re like, “This is a problem because of it’s, like, hard to do everything at once.” Which is w- this is the type of thing where having research in it would be so great, and I think NVIDIA could release some of the teachers so that people could just like-
00:30:45 Finbarr Timbers: Yeah. That’d be great
00:30:45 Nathan Lambert: ... if you have the teachers and you have the intermediate model stage, you could do the problem of, like, just studying multi-teacher on policy distillation from the starting point and understanding the training dynamics.
00:30:57 Finbarr Timbers: Yeah.
00:30:57 Nathan Lambert: Which is the type of thing we would want to do at Oldo. We just haven’t scaled our recipe to this point yet.
00:31:03 Finbarr Timbers: Yeah, absolutely.
00:31:04 Nathan Lambert: So I will keep encouraging NVIDIA to do this.
00:31:07 Finbarr Timbers: That’d be great. NVIDIA-
00:31:08 Nathan Lambert: I think, uh-
00:31:08 Finbarr Timbers: ... listen.
00:31:10 Nathan Lambert: They, they listen. The other side of things is a bunch of models released in 2026 that do not do this multi-teacher on policy distillation, and they also don’t do nearly as many teachers. So I would say that this, like, Microsoft model, which I don’t say this as a diss, it’s, like, hard to get a new team off the ground, is they went for a simpler approach to try to get a solid model, and it has three more general experts combined w- via SFT and then, like, a longer RL run. So it looks a lot more like DeepSeeker one, but I suspect that what they will do next is make finer grain teachers and see if they need to switch to on policy distillation.
00:31:48 Finbarr Timbers: Yeah. And I think, you know, in one of our, um, group chats, you described the MAI thinking model as a conservative recipe. A-and I think that’s a really good description of it. Like they, you know, the, the team came up with this conservative recipe, and then I think that they did a really great job of actually executing on it. ‘Cause I think, you know, if you try to make too many changes at once, it’s really easy for the recipe to collapse under its own complexity, and I’ve seen that a bunch of times, you know, across my career.
Try to make too many changes and, you know, it all goes poorly. So I thought that was, um, a really good choice on their part. I, I also think that, uh, it’s not super clear to me, may-maybe you’ve seen some papers on this that I haven’t seen, but it’s not super clear to me how well the trace distillation SFT does or, you know, h- how much better on pols- online policy distillation is versus the trace distillation SFT.
00:32:41 Nathan Lambert: Yeah. It’s like what’s, what is the relative magnitude in the final performance?
00:32:45 Finbarr Timbers: Yeah.
00:32:45 Nathan Lambert: So the Nemotron Ultra paper has a table on how far the on policy distillation goes relative to the teacher, and they also have the starting point. So I guess that’s a potential way to do this. Here, I could, I could just pull this up. Let me switch.
00:33:00 Finbarr Timbers: Oh, sure.
00:33:04 Nathan Lambert: So I, I had this open, but in a different tab. Okay. Here’s, here’s this paper. This is page twenty-seven is which the paragraph I just read, and then it also has this kind of-
00:33:17 Finbarr Timbers: Oh, fascinating
00:33:18 Nathan Lambert: ... is it a great table. I spent a while looking at this earlier. So essentially, it’s like where they get after SFT-
00:33:24 Finbarr Timbers: Wow
00:33:24 Nathan Lambert: ... on each of the benchmarks on the general model. And then I think... Okay, so the sort of gains over the RLVR student recovery of the specialty student. So I need to make sure... Okay, so it denotes the initial student checkpoint, where RLVR denotes the s- initial student checkpoint, and then the multi-teacher on policy distillation. So I’m not sure what this SFT column can figure out, but you could see the kind of like where the teacher is relative to on policy distillation. I think this is like the closest information we have on the relative performance gains.
00:33:59 Finbarr Timbers: Yeah. That’s fascinating because the DeepSeek, I forget which one, maybe it was V3.2 paper claims or, or maybe it was, um, R1 actually claims that you can domain-specific... That, that, you know, doing the general stage, uh, captures the performance, uh, of it. But, you know, that, that doesn’t really seem to be... A-a-and yeah, a-a-and then so, you know, doing the domain-specific distilling in, and then doing a general stage on top of that captures the original performance. But that doesn’t seem to be the case here. Like, you know, the, the gap maybe isn’t huge, but there is still, most of the time, there’s a pretty big... There, there’s like, you know, a significant gap, even if it’s not huge. So that’s really interesting.
00:34:42 Nathan Lambert: Yeah. I wish this table and text was clearer. It’s like I literally can’t fully parse it. It’s like RLVR denotes the initial student checkpoint, and then OPD denotes the checkpoint after first and second iterations. It’s like, what is the checkpoint that was used at the start of on policy distillation?
00:35:01 Finbarr Timbers: I think it was the RLVR one, so that they do a general SFT stage, and then they do an RLVR stage that covers the non-teacher, the, the areas that where they don’t have specialized models. Then they do MOPD.
00:35:15 Nathan Lambert: Yeah. And then that makes sense with this recovery rate, which is like final model minus RLVR, which would be like the gains for the OPD relative to the teacher minus RLVR, which would be like what gains you needed to still cover.
00:35:31 Finbarr Timbers: Yeah.
00:35:32 Nathan Lambert: And like what, what gains the teacher could potentially give you. So more research like this. Happy to see some of it a- out there. I’m gonna switch back.
00:35:43 Finbarr Timbers: Yeah. Something I found interesting about the, um, the, uh, both the Nemotron papers and then the MAI thinking paper is that they don’t talk as much about some of the more detailed, um, post-training decisions that have shown some pretty strong gains in, um, some of the other papers. Like I, I believe it was GLM five where they talk about doing a difficulty curriculum and a difficulty filtering stage.
00:36:11 Nathan Lambert: Yeah.
00:36:12 Finbarr Timbers: And that’s just not something that’s really talked about in these other papers. They’re saying they, they don’t, you know, uh, I think it was QEM 2.5 used a temperature. It’s kind of funny. So QEM K 2.5 and GLM five both have temperature schedules, uh, and they both claim the exact opposite thing. So one of them says you have to start with a high temperature and go low. The other one says you have to have a low temperature and go high. And, uh, y- I don’t know. And then so, you know, you don’t see that discussion, uh, I, I don’t think in Some of the other papers, which is kind of interesting
00:36:40 Nathan Lambert: Yeah. I, I still think the Chinese labs are much more willing to share, like really, really nitty-gritty tech details. The NVIDIA paper is like mostly a list of like methods to create a teacher or like-
00:36:51 Finbarr Timbers: Yeah
00:36:51 Nathan Lambert: ... domain-specific teachers, which is useful, but I think like I was less... It’s like less of a fun read. They’re like, there’s 15 pages of different domains, so I’m like, “Okay, I don’t, like I don’t need this.” Yeah, like KBK 2.5 and, uh, GLM 5 actually have like more similar recipes, which are also on the simpler side, which is like you create this SFT stage, and then you do RL. The RL might be staged. Um, there’s not this on-policy distillation. There’s a bit less talk on how many experts they have and what their domains of expert-s are. I think it, it’s obvious, like you have to take all this with a grain of salt, and it’s like what, how they decided to present the information is like a big factor in this. And then like they might actually be closer in reality and then it just wasn’t described in a certain way.
00:37:44 Finbarr Timbers: I, I think another interesting bit is that you see the Chinese labs, uh, all seem to be converging towards sparse attention, whereas, uh, we don’t see the, you know, where was the American labs, at least NVIDIA and, you know, AI2 seem to be more converging towards hybrid attention. Uh, like N- uh, the NVIDIA Ne- Nemotron Ultra used the Mamba, um, attention, whereas, you know, we see, you know, DeepSeek sparse attention and then the Mimo, eh, MSA, whatever that stands for, Mimo Sparse Attention. So I, I think that’s, uh, an interesting divergence.
00:38:20 Nathan Lambert: Yeah. I am not the person to ask, but I agree.
00:38:23 Finbarr Timbers: [laughs]
00:38:23 Nathan Lambert: It’s like I... Like I, I often get asked of like, this is to, to... Don’t, we’ll avoid the full rabbit hole, but I often get asked like, “Are the Chinese labs more efficient?” And I’m like, “I don’t really know how I’m gonna give you advice unless I’m spending twenty hours a week look, understanding the details of your recipe,” ‘cause it’s like, well, I can’t really give you a one sentence thing of do X without understanding all the complexities of the model and the post-training process that go into it. Which makes it, like makes it hard from kind of like a transparency point of view. Even if it’s fully detailed, it’s definitely still hard to modify and study.
00:38:42 Finbarr Timbers: Yeah
00:38:42 Nathan Lambert: ... like if you make a GPT model 1% more efficient, you’re making like fat stacks of profit. Like, I think that’s like a more effective market mechanism, but-
00:38:53 Finbarr Timbers: And then-
00:38:53 Nathan Lambert: The Chinese lab-
00:38:54 Finbarr Timbers: You know-
00:38:54 Nathan Lambert: Yeah
00:38:55 Finbarr Timbers: ... if you make, you know, serving ChatGPT more efficient, Sam Altman can say, “Hey, here’s a bunch of stock.” Like, so yeah.
00:39:02 Nathan Lambert: Yeah. But, uh-
00:39:03 Finbarr Timbers: Um
00:39:03 Nathan Lambert: ... they do great, like the Chinese labs do great research.
00:39:05 Finbarr Timbers: Absolutely.
00:39:05 Nathan Lambert: I just think it’s kind of a bit different. Okay, we can move into more open-ended stuff here.
00:39:12 Finbarr Timbers: Sure.
00:39:12 Nathan Lambert: I think that we have like a bunch of docu... We have th- a bunch of things in a document here. I’m sure more will come up. How do you think about open models and kind ‘cause i- it just doesn’t strike me that there’s this, like, you know, I think that there’s a large business to providing... Well, actually that’s not even super clear. There’s, you know, we’ve seen a number of companies providing, you know, RL fine-tuning services, you know, RL as a service. We’ve seen a lot of companies try to provide fine-tuning as a service, and, you know, none of them have really taken off. Like, I think OpenAI has started to shut down, I think they shut down their RL fine-tuning. I think they might be shutting down their fine-tuning. May be wrong about that.
00:45:51 Nathan Lambert: Well, it’s like Cursor used Fireworks for their actual training run, and I’m like, I don’t really know all the details of this, but Cursor does something for fat- I think like fast weight tran- or Fireworks does-
00:46:01 Finbarr Timbers: Yeah
00:46:01 Nathan Lambert: ... a fast weight transfer and other things to make it so that they can scale their RL inference compute very nicely. So that’s one type of it. I don’t know how big of a long tail that business is, but also I think Tinker is a better business than most people expected. It makes some real amount of money. It’s like in the hierarchy, I think selling compute, not the best business.
00:46:23 Finbarr Timbers: Yeah.
00:46:23 Nathan Lambert: Selling inference, great business. And Tinker-like APIs, if you can’t transition it into selling tokens, is somewhere in between the two, where they could take some amount of margin that’ll be slightly higher than just selling the compute. And they obviously get a margin by having, like, they get compute at a cheaper rate than their customers-
00:46:43 Finbarr Timbers: Yeah
00:46:43 Nathan Lambert: ... and that’s like part of the margin they’re taking. But I don’t see it being as nice as inference, so it’s kind of existential for them to make it so that these fine-tuning APIs feed into a inference business pretty nicely.
00:46:56 Finbarr Timbers: Yeah.
00:46:56 Nathan Lambert: Because then you can be somewhat locked in on you train the model on our infrastructure. You actually can own the model weights, but the training dynamics to inference mismatch is perfect because you trained exactly on our inference engine, and are gonna get what you want out of it.
00:47:11 Finbarr Timbers: Yeah. And it also helps a lot with utilization because you can then, you know, utilize it. You, you can share that utilization across a lot of clients. So I think it makes a lot of sense. I think it’s probably a better model for a lot of, um, users. Like, I think of academic users, like it probably makes way more sense to do this. Or, you know, for that matter, if you’re, you know, as, uh, uh, starting a new, um, ar- you know, post-training lab now, as you know, I, I know a few people, um, who are. Like, I think that’s where it, it probably makes a lot of sense to start with something like the Tinker API, and then, you know, at some point if you wanna try and capture that margin, maybe then you try to do something more custom. But if you, if you can use something like that, like that’s great, and the economics are just, you know, fundamentally more sustainable. I or, you know, they’re better for you rather than trying to, you know, g- go to CoreWeave or whoever and say, or Serv scale and say, “Hey, I need, you know, 10,000 networked, uh, DB200s,” you know? That’s just a very expensive, um, thing to do, especially if you can’t keep it running all the time.
00:48:14 Nathan Lambert: Yeah. Do you have a, do you have any more hot takes on post-training before I ask you some more general things?
00:48:22 Finbarr Timbers: Uh, well, something I’m, I’m generally interested in and, you know, I, I’m the wrong person to, to speak to about it. I’d love to talk to someone who’s maybe a, a, a capital allocator, like who’s, you know, deciding or a compute allocator who’s deciding where to put, uh, compute or, you know, where to hire team members. Um, because I’m kind of curious how Uh, the high level decisions are made allocating resources between pre-training and post-training. Uh, ‘cause, you know, what I kind of have seen as, as a general trend is, is that you see a lot of papers where there’s, you know, more focus put on one or the other. Uh, like I think... So, so yeah, so that’s something kind of interesting to me is how people who are, you know, making this decision, how, how they’re making that decision and how they’re thinking about it.
00:49:10 Nathan Lambert: Yeah. It’s like the hardest decision to get out of labs. I’ve like, I used to spend time trying to get them to share more, but I, I think it’s like such a sensitive decision to where they see progress coming. Like they’re making that decision ba- allocating compute based on where they think the most progress is and what the like return on investment is. So if you go to Anthropic and they’re like, “Here’s where our percent, here’s our distributions,” it’s like, okay, that’s where labs see their bets and/or where they see they are weak.
And it’s like you invest more compute in the pro- to make progress in the area that you are interested in, which I always think makes a lot of the open research kind of boring right now, is like the people that get compute are just way more likely to succeed as academics and researchers, which is a horrible equilibrium for the world, but kind of realistically true. I, I, I don’t know how to make a lot of that. I wanted to ask you how you feel about the craze that people have to cash in on making money and join a lab before the ladder gets pulled up, and what people should be optimizing for in their careers in face of meaningful opportunity costs.
00:50:18 Finbarr Timbers: Yeah. I think it’s, well, that’s actually very, very timely. Uh, but yeah, no, I, I think that that’s, um, really important to, to talk about. I mean, I think it’s always worth focusing on whether what you’re doing and spending time on is gonna be generally valuable or if it, if it’s like a really short-term exploitation type thing in, in the, you know, RL like explore versus exploit setup. I, I mean, something that I’ve seen throughout my career has been often the places that pay the most, um, are also the places where you’re doing the most interesting work, right? Like, you know, if, if you’re gonna go work at OpenAI, OpenAI or, you know, Anthropic or the Frontier Lab, like they pay a lot of money. They also have a lot of resources, so you’re gonna make a lot of money and learn a lot.
Um, uh, so I think it’s worth trying to decide i- is that the, is the opportunity that you’re doing that or is the, is the opportunity like, you know, in 2021 or 2022 or whatever, where you might say, you know, I was at DeepMind at the time and it’s like, okay, do I work at DeepMind, which paid a lot less than like crypto? Should I go just, you know, work in crypto and try to, you know, mint NFTs or whatever? I think that would’ve been a mistake, but, you know, trying to figure out, um, if you’re gonna be able to do interesting work is really important and also, you know, try to figure out if you’re going to be able to, you know, push forward science. You know, if, if what you’re doing is more just saying, going to, you know, data vendors and saying, you know, “Okay, you know, we, I need a bunch of data to do whatever.” And then, you know, they, they give you a bunch of data, you train a model, you say it’s good or bad or whatever.
You know, I don’t think that’s as interesting and, and I don’t think you’re gonna learn a lot even though that’s, you know, work that would probably drive model progress for it. I think if you’re able to, you know, make, focus more on the science and make more scientific conclusions, I think that can be, you know, a lot better for your long-term career. And I think that’s where places like AI2 and the other, um, academic research labs, you know, Marin is doing a really great job of this. Um, I think that’s where you can have a lot of impact in that they don’t have the budget to go and buy a lot of data, and so that leverage just really isn’t, um, open to them to pull. And so they have to focus on science and driving innovation, and that’s where you can see things like the Almix, uh, paper, which I thought was a really excellent, uh, sc- you know, scientific paper, but also, you know, meaningfully, I think, advanced, uh, the state of the art.
00:52:32 Nathan Lambert: Yeah. No, mostly this is grounded in visiting the Bay Area, and every time I go I’m like, “Holy shit, what is going on here?” Like all these very junior people are like have way too much dread about their, uh, opportunity cost and both of us aren’t based in the Bay Area, so I feel-
00:52:46 Finbarr Timbers: No
00:52:46 Nathan Lambert: ... somewhat removed from it, which gives me a little bit more time to pause and be like, what exactly is the right thing to optimize for? I per- I-- it’s easy for me to say as somebody that’s established, but I think there’s opportunity for a lot of people to just, if they have conviction on something, to try to go and do it and not just follow everybody that goes down the funnel of joining one of the established labs or the Neo labs where I don’t hear from many people that join as a junior person at these places and end up with very high responsibility. Like they’re contributing to something that matters or they’re around a cool group of people, but I don’t hear from that many people that are like, “Wow, I am doing the highest leverage stuff and the most interesting things.”
00:53:30 Finbarr Timbers: Well, I think that, you know, it’s kind of funny for, for me to say this as I, my career has been more on, on the opportunistic, uh, side of things. Um, but you know, twice now, uh, I’ve been at organizations where, um, I, I’ve been working... So, you know, at, at DeepMind, uh, I, I was part of the Alberta office where DeepMind had, you know, aqua hired the, uh, computer poker research group from the University of Alberta. And so, you know, this was a group of people who were really invested in, uh, computational game theory and g- you know, poker playing, um, algorithms. And they were all in on that and, you know, they, they were all in on that to the point that, you know, they were one of the two leading, uh, labs in the field and, um, were, you know, b-because they were so strong at this, they were then, you know,
DeepMind came and, you know, acquihired them and, and they all joined and they, you know, did quite well from that, um, acquisition there. And then, you know, you know, I joined later because I was, uh, you know, interested in, in working with them and doing game theory and stuff. But you know, it was this group of people who had this conviction that what they were doing was really important and, you know, it worked out quite well for them. And then, you know, the same thing at AI2, where at AI2, you know, there was all of these people who were really interested in, uh, NLP research, you know, even before language models. Like we see people like, you know, like Kyle a-and Dirk I think were both at AI2 for like almost a, a decade.
Like they had these really long tenures, um, and then they did really well and then, you know, they’ve, they’ve since had some, you know, strong, um, opportunities, uh, coming out of that with, with, um, yeah, some of the opportunities that have been available to them. And I, and I think that the consistent theme there has been that, you know, if you have high conviction that what you’re doing is important and interesting, then like it, it’s not a mistake to follow that and to, you know, try to become really strong, um, in that area.
00:55:15 Nathan Lambert: Yeah. I mostly think it’s good for the world to have a di- more diverse set of approaches.
00:55:19 Finbarr Timbers: Yeah.
00:55:19 Nathan Lambert: It’ll be interesting to see what the deal labs actually produce if, if they can manage to do things that are diverse. My personal idea is that they’re so big now that most of them need to end up doing something that is somewhat similar, which is-
00:55:33 Finbarr Timbers: Yeah
00:55:34 Nathan Lambert: ... hard, but like they need to keep risking the comp- they effectively need to risk their $20 billion valuations to do something interesting that’s not just gonna be like squashed by an OpenAI or Anthropic side project.
00:55:48 Finbarr Timbers: Yeah, absolutely. And I think it’s tough because when you’re raising, when you’re, you know, you have these huge seed rounds and you’re raising, you know, 200 million or, you know, a billion dollars or whatever, then it’s like you have to pretty quickly show results to be able to-
00:56:01 Nathan Lambert: Yeah
00:56:01 Finbarr Timbers: ... you know, grow off of that.
00:56:04 Nathan Lambert: Yeah. So a to-be continued conversation.
00:56:11 Nathan Lambert: Any last words? I don’t, I don’t need to stretch it on if we don’t have anything to add to our conversation.
00:56:16 Finbarr Timbers: No, I, I think this was pretty good. I think it was really great, uh, getting a chance to catch up and talk about some of this stuff. You know, I, I’ve been reading all of these papers and thinking about all the different recipes, so it’s great to get to, um, to chat about it and put it out into the ether. So yeah, thanks for having me on.
The executive branch of the United States forcing Anthropic to turn off access — both internally and externally — to their latest Claude 5 Mythos/Fable models is the starting gun of a new era in AI governance. This is the era defining AI agents that effectively complement human workers, unlocking new ways of working and new domains of applying existing tools. The models will keep getter better at a rapid pace, forcing more governance challenges.
On Friday, just after markets closed, the government reached out to Anthropic to force them to suspend access to their model to any foreign national or user abroad. When writing this, the saga is still unfolding. It is likely that Anthropic and the Government reach an agreement to re-release the model, but it is a messy indicator of new types of AI governance. The White House was tipped off to the risk by Anthropic’s largest financial and technology partner, Amazon.
These dynamics are very complex, and while the picture is incomplete I will only offer commentary on what will likely be a lasting opinion of the saga:
An export ban on any model weights is going to be a lasting, negative policy for the U.S. This goes for both open and closed models, despite the open models being more likely to get import banned soon.
There was a legitimate cybersecurity concern regarding a jailbreak of the Fable model, even if it was very narrow. I do not personally think this should’ve set off this series of events, as no model is perfectly immune to jailbreaks and we need to prepare our infrastructure for a world where every global entity will have access to models of this capability level in the coming years.
Anthropic’s constant fear-mongering over the last few years has accelerated this moment. Without the constant messaging comparing AI to nuclear weapons, etc., I suspect this style of governance would not have manifested for another 6 to 12 months (of AI progress). There is some amount of Anthropic reaping what it has sowed.
People should not be taking a victory lap at our nation’s leading AI company being repeatedly subject to potentially political attacks (yes, I’m looking at people in the open-source community). This is economically highly unstable and undermines the economic stability of the American system. Sufficient instability could cause an economic recession and pop the AI bubble.
The White House’s actions to ban the model are heavy handed and are influenced by a strong political inclination against Anthropic. There’s a deep contradiction in the government’s demands and goals, as there is no domestic AI industry if foreign nationals cannot build with frontier AI in the U.S.
It is unclear to me as to why Amazon needed to take the information they had directly to the White House, what the lead-up to this release and ban were (lots of accounts online of pre-release discussions), and how crisis management between leading technology companies and the White House would normally play out. This points to weird dynamics with how Anthropic interacts with the government, which could be a reaction to being politically singled out.
Whatever the cause, it is a bad dynamic and casts a shadow over how Anthropic engages here. If a private company tries to control the government the government will push back stronger. I do not think Dario was actually at a wellness retreat (as said by a White House representative) but I do think he took longer to answer the call than is acceptable with who was on the other end of the line.
It’s hard for me to write anything cogent about these back and forth dynamics but they are very important to the truth of what is happening.
This picture is very complex. It points to a near-term world where model releases are judged on vibes by an executive branch with minimal technical talent, gating releases behind a blur of politically judged technical assessments.
This is a government that has internalized that we are in the AGI era. They were not ready for it and feel like they must act fast to regain lost time.
This is a government that took office when we were still in the ChatGPT era of AI governance — models that just answer questions. Their original AI Action Plan reflected this era, highlighting how a lot of previous safety discussions were more smoke and mirrors than concern, and how badly we needed open-source models to catch up. On balance, their opinions and prescriptions here were mostly agreeable and useful for the industry.
It is important to remember that even in this ChatGPT era of governance, the AI companies often told us that the models were a risk and could not be released without great care. Many spokespeople at leading labs didn’t give themselves enough headroom in language escalation for when the models took a meaningful jump in performance.
As we shift from answer inference to agentic inference, I’m still on the side that the risks have been exaggerated, but the margin between the real risks of the latest AI systems and the language used to describe them has shrunk. This has spooked power structures outside of the leading AI labs.
Entering the AGI era of AI governance is when a lot more sovereigns around the world start to take AI seriously. Europe, the Middle East, and likely also China are realizing they could be left without frontier AI. This swing is something that the open-source community takes as a win, seeing the long-term trajectory where businesses will want to control their own intelligence when the government can arbitrarily rule against the leading platforms.
The key to understanding this era is that these events between Anthropic and the federal government, which seem like two of the biggest events in the history of AI policy, are just the starting gun to what is to come. This is the new normal, as existing power structures feel the need to assert their control over the rapidly rising technology. This will be messy, fraught, and at times even perilous.
When following these events I’m filled with a sense of dread, staring into the void, because I know more is to come. It’ll take resolve to follow de-escalatory paths that help us achieve the positive visions of broadly diffused, safe, and cheap super-powerful AI around the world.
Sovereign AI, open-source needs, and battles soon to come
The open-source AI advocates wildly celebrating this sequence of events aren’t remotely ready for when the spotlight of rapid-response AI policy turns its gaze upon them. It is very likely that a similarly aggressive action against an open model will come, but we don’t know if this is in 3 months or 2 years.
Edit Jun. 11: Anthropic changed their silent model manipulation of AI research queries to also use a classifier like the other safety domains. This addresses a key concern I had in the mistreatment of “safety” in the release, and props to Anthropic for a quick change, but it does not fully address the trust that has been broken. I shared more reflections here.
Today, Anthropic released their Claude Fable 5 model to consumer and enterprise audiences. This is the general-access variant of their Mythos-class models. With it, Anthropic rolled out a series of safety measures — some explicitly called out to users and some modifying the model without telling the user. It should be less surprising than it is that the next major step in AI capabilities came with heavier-handed safety measures indicating Anthropic’s intention to protect, or entrench, their current lead.
The unevenly applied safety policies that Anthropic have rolled out are on track to become a classic cautionary fable in how narrow and self-fulfilling notions of safety and control rarely work out.
Before digging into the nuance of the safety facts, it is important to establish the quality of this model. The quality of the model paints the stakes of today — as these safety features are meaningfully changing the shape of access to frontier AI, something which has never happened with the modern LLMs we know. Second, the capabilities point to this story only accelerating. Recursive self-improvement isn’t quite the right mental model of progress from here, but Claude Fable 5 should make it very clear that there are no immediate walls in training LLMs.
To start — Claude Fable 5 is definitely the smartest model available to the general public — a remarkable leap on pretty much every relevant benchmark of the day — at only 2X the price of current Opus models1 (which is still less than GPT 5.5 Pro’s variant). This alone is a seminal moment for the field. To have a model iteration take such a substantial step in capabilities, a few years into the post-ChatGPT LLM race, is astounding. There’s no clear breakthrough associated with this model, such as inference-time scaling or RL, and public wisdom is that this is achieved by advances across the whole stack (of course, we can’t know for sure — it’s not documented). This is a major technical achievement and the employees who built the model should be very proud of their work.
This model was delayed 2+ months after it was done training before it was publicly available2. Given the competitive dynamics of the AI economy, the smarter version of this model is already well underway.
To continue, the benchmarks for the model are below.
An asterisk on these scores is that these aren’t necessarily the scores that the public will get, as some of the prompts will be downgraded to Opus 4.8 with the current safety filters on the model.
This is the type of jump in benchmark scores where I don’t even need to substantially test the model to know it’s an incredible tool. Remember that Anthropic is also the AI lab with the track record of caring the least about benchmarks (in particular, when compared to OpenAI and Gemini). Recall a comment I made in June of 2025:
This is a different path for the industry and will take a different form of messaging than we’re used to. More releases are going to look like Anthropic’s Claude 4, where the benchmark gains are minor and the real world gains are a big step. There are plenty of more implications for policy, evaluation, and transparency that come with this. It is going to take much more nuance to understand if the pace of progress is continuing, especially as critics of AI are going to seize the opportunity of evaluations flatlining to say that AI is no longer working.
Clearly, a few pieces of the progress dynamics have changed, but that’s a post for another day. I’ve written multipleposts about new models this year specifically in how it’s hard to trust benchmarks (and partially because the benchmarks don’t move that much). Altogether, this is a major validation for AI-savvy workers who realized they’re likely never going to write meaningful code again and need to develop new workflows around agents.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
Smarter models spawn new safety games
There are multiple pieces of safety tooling associated with this release, including but not limited to required data-retention policies and added prompt filters. Through this analysis it is particularly important to be precise and clear as to which pieces of these are causing harm, and why single elements being out of place in an otherwise comprehensive policy are so damning for the overall safety process.
For their focus areas of cybersecurity, targeted model distillation, and research biology, Anthropic details new safety classifiers in their blog post:
Fable 5 comes with a new set of classifiers: separate AI systems that detect potential misuse, including jailbreak attempts, and prevent the main model (in this case Fable 5) from responding. We’ve been running classifiers on our models for some time, and Fable 5’s classifiers are an extension of this previous work with extra coverage.
When Fable’s classifiers detect a request related to cybersecurity, biology and chemistry, or distillation, the response is automatically handled by Claude Opus 4.8 instead. Users will be informed whenever this occurs. Opus 4.8 is a highly capable model in its own right: a response that falls back to Opus is a far better experience than an outright refusal from Fable. Our early data shows that more than 95% of Fable sessions involve no fallback at all—for those sessions, Fable 5’s performance is effectively the same as that of Mythos 5.
Examples of the primary cybersecurity and biology safety filters — which tell the users explicitly when they’re triggered — are alreadyproliferatingonline and appear quite sensitive. These can be a frustrating experience for users, but Anthropic is definitely within its power to do this and intellectually consistent for doing so.
The damaging part of the safety story falls under the fold in the Claude Fable 5 & Claude Mythos 5 System Card:
We have also added safeguards related to frontier LLM development. As discussed in Section 6.1 of our February 2026 Risk Report, we are concerned about the risks of accelerating the overall pace of AI development, though we remain uncertain about the severity of these risks. In particular, our concern is with—as we wrote then—“accelerating other AI developers in building powerful AI systems that pose similar risks to the ones ours pose - without necessarily having commensurate safeguards.”
In light of the ability of recent models to accelerate their own development, we’ve implemented new interventions that limit Claude’s effectiveness for requests targeting frontier LLM development (for example, on building pretraining pipelines, distributed training infrastructure, or ML accelerator design). Using Claude to develop competing models already violates our Terms of Service, but enforcing this restriction through our safeguards avoids accelerating the actors most willing to violate these terms.
Unlike our interventions for cybersecurity, biology and chemistry, and distillation attempts, these safeguards will not be visible to the user. Fable 5 will not fall back to a different model. Instead, the safeguards will limit effectiveness through methods such as prompt modification, steering vectors, or parameter-efficient fine-tuning (PEFT).
Anthropic documents on how this will impact a small percentage of users, which is true. I focus on the small amount of users supporting AI’s diffusion and understanding outside of the few frontier labs, as a crucial mechanism for the continued safety of the technology.
Anthropic is documenting how the proliferation of AI capabilities is a concern to them, but they are solving it by misleading their users. An AI model that gets less intelligent automatically without notifying me is categorically misaligned AI. The next step on this line — not that Anthropic did it, but they could — is to have a model silently manipulate a workplace when it thinks it is an unsafe use for AI. Second, the implementation here is more complicated than was documented for cybersecurity or biology — modifying the model itself or the data presented to it, all without notifying the user.3
The duality of these policies is extremely confusing and paints a strong inconsistency that casts doubt over their safety policies. This “safety” measure is presented as being far more about maintaining their competitive position. Again, if all of the safety policies took one form, this would be far more cogent and easier to support intellectually.
Anthropic has been very vocal about their concern over distillation attacks from particularly Chinese actors. Their claims are not transparent enough with the facts — or context as to why they can’t prevent the behavior — to be fully believable. Despite the limited information, in the broader AI and DC communities, there have been serious discussions about taking action against the Chinese model builders on the grounds of said distillation.
On the point of distillation, my hypothesis is that API builders don’t have an easy time preventing hacks or jailbreaking because it’s a deeply grounded property of reasoning models to want to output the reasoning traces, and it would make the model far less intelligent to fully patch the behavior. This is based on a few assumptions:
Chinese labs are not just showing up as customers to Anthropic’s API and paying for tokens in the intended input-output form. If the Chinese labs are paying for intended use behaviors, despite being banned by the terms and conditions, I don’t have a lot of sympathy for the frontier labs manifesting policy actions against this.
Reasoning traces are disproportionately effective at seeding behavior in downstream models.
Leading labs work very hard to patch the pipeline of these jailbreaks.
So, my logical conclusion is that the model companies would have to weaken their economic position to fully protect their IP. If this is the case, Anthropic would get a lot more sympathy from the AI research community by being transparent. It would also be far easier to have informed policy discussions, and not rely on me proposing Occam’s razor explanations for what the API jailbreaking looks like.
Building these safeguards is not something that Anthropic should do alone. Safety research should be built on common understanding and information sharing across both labs and public research efforts.
If the exact safety procedures were actually the top line item to the company — a true non-negotiable for the leadership — they wouldn’t permit the model to be released with an unclearly implemented safety filter in one of their areas of focus (frontier AI training). I am asking — why isn’t there a classifier to downgrade AI research requests? This is a mix of transparent and reasonable safety policies with quietly rolled-out market entrenchment tactics.
I personally cannot trust the best AI model in the world to work in my professional domains building models, which I’ve constructed entirely out of a passion for making sure the transition to very powerful AI systems goes well for society. This inevitably will feel like a declaration of superiority by the Anthropic leadership.
The control problem and open-source as the only answer
All of the actions Anthropic is taking, including calling out smaller Chinese companies for distillation, is well within their right. In fact, many people already expected the leading frontier models to be obviated from users so that labs can protect their IP. Today’s actions miss the big picture that AI will always be an ecosystem, and cultivating an us against them dynamic between the leading company and the other players is structurally unstable.
Remember, this is at a time when the AI ecosystem is seeing the first stirrings of violence against AI leaders — and I’ve heard from many people that they don’t expect it to abate. I wish I knew how to engage more to prevent this, and I see myself in the non-profit sector as someone who can hopefully independently represent AI to broader stakeholders.
I believe there was something misread, or at least misunderstood here, by the Anthropic leadership having a narrowly cultivated worldview around AI. An overwhelming sentiment I had today was one of obligation and confusion. I shared how I don’t really want to have to go to bat against Anthropic, but they’ve just been unnecessarily antagonistic to China, then not so subtly to open weight models, and now more broadly to open AI research.
I understand that Anthropic has a specific view of AI, but such a powerful technology will never have its final equilibrium be one of singular control by a private company. Anthropic showcased this earlier this year in the spat between the Department of Defense and themselves — which points to a long-term equilibrium where the government will either want AI to be controlled by them or to be open. This made me believe that an open ecosystem is a far safer outcome.
Many of these events make me feel that Anthropic’s leadership has a culture by which they can’t help but speedrun through these issues — going head to head with existing power structures. This adds substantial uncertainty into an AI ecosystem at a time when it is very much not needed.
Collectively, the last week could be seen as a major rallying point for a new open-source ecosystem in the U.S. Nvidia released their first flagship model last week — Nemotron 3 Ultra — and these actions from Anthropic have galvanized a unanimous motivation and concern among my peers building open models. We need intelligence that we can trust, that we can modify, and that we can control.
The American open-source ecosystem has its feet underneath it and keeps being given more reasons to fight for its leadership, right from the hands of the companies it directly undercuts. That’s the moral of this fable.
I’m departing the Allen Institute for AI (Ai2), where I got the great privilege to work on the Olmo models, to grow, to learn, and to have broad lasting impacts. This post is an attempt to reflect on why what we did was influential, despite obviously being far from the frontier in performance (even when within size buckets), and how this reflects on various paths to impact in AI today.
To start, I shared the following note with the company yesterday:
Dear Ai2.
As many of you know, today is my last day working at Ai2.
I joined Ai2 largely as an accident. I met Luca at ICML 2023 in Hawaii and realized I could level up my open post-training work dramatically if I got the chance to join. When I got an offer it was an absolute no-brainer, it was such a welcoming and exciting environment.
It has been a wonderful ride that has transformed my life, and I couldn’t be prouder of the work we did together. Ai2 has a wonderful scientific culture at its core and I’m excited to see this continue. I feel very lucky to have been here and that I personally have benefited massively from everyone who has worked so hard to cultivate that culture and environment. It is and has been a team effort. This includes all the people whose longest interactions with me were brief chats at the coffee machine. I drew so much energy and excitement from all the different ways people at Ai2 showed up for the mission.
I’ve already thanked much of the OE team directly, but I wanted to thank everyone else that went into this. Legal, IT, Comms, and the Office team all do a great job enabling and leveling up our research work. It’s often work that is forgotten, outside of the lime light, or remembered at the last minute, but it all has been crucial to achieving our goals. I’m excited to keep visiting the wonderful Northlake space in the coming years.
Even though I’m leaving, I’m more excited than ever about Ai2’s mission. Ai2 operates in such a rare niche between academia and industry, where we can explore and influence the most important technology of our lifetime. Doing this openly is the best way to ensure the technology diffuses safely to everyone who may benefit. Ai2 needs to stay as ambitious as possible, trying to influence the cutting edge of AI and the biggest issues of the field. Do not shy away from these challenges – AI needs independent voices as it only becomes more geopolitical, socially disruptive, and central to the economy.
I will still be working in this space, working to make the open ecosystem better coordinated and more useful.
So as I go off to try something new, don’t be strangers. I’ll always be reachable at nathan@natolambert.com and will still live in Seattle for most of the year.
Nathan
I have loved and will still love Ai2. Ai2 has a deep culture of caring about the research process, the outputs that get shared, and most importantly the people who do the work. This is why the institution creates countless wonderful people that go and spread the gospel throughout the research community. This core culture will remain through the rebuild, and there are plenty of resources to do impactful research across the spectrum of AI.
In the last two years of my time at Ai2 I’ve done so much meaningful work. Of course Olmo is at the top and has been my priority, but making time for consistent practice here on Interconnects, weekend cram sessions for ATOM, and also the fun RLHF book make for a list that makes me wonder how I did it all. I was obviously obsessed with work, but not in a way that made me lose sleep or lose my overall wellness. It was the right long-term approach.
This impressive list is one where I was ruthless in saying no to things that didn’t matter and got all my work out to see the light of day. I had no medium-sized projects that didn’t succeed in the last few years. It makes me wonder if I wasn’t taking enough risk. It shows you can truly do so much with your time, and it’s actually harder to find the right problems and environment to do it. Many people are in environments where their work never becomes public or they’re forced to change topics consistently.
To start, I’d like to do a short recap on my path to Ai2 to show what Ai2 was just as much a growth story for me as an execution story.
I studied electrical engineering in undergrad, focusing on linear systems math and microelectronics.
I was admitted to the UC Berkeley EECS Ph.D. program to study microelectromechanical systems (MEMS).
I showed up at Berkeley in August of 2017 and realized AI was obviously the thing I should be doing. I asked the likes of Sergey Levine or Pieter Abbeel if they could advise me – they said no.
I threw all my energy into learning what I could about AI. I got a break to get advised by one of Sergey’s post-docs in 2018 or 2019. I went all in on that, I fought for funding, I fought to have an AI paper.
This process worked out by the end of my Ph.D. in 2022: I had access to the Berkeley AI Research (BAIR) building and collaborations in the department. It was a bumpy road.
I wanted to go to industry research, to get a nice paying job with intellectual freedom, something like FAIR or Google Brain at the time. HuggingFace was the only job that fit that bill, it was easy to say yes to.
I joined HuggingFace in May of 2022 and wasted my time at the company until ChatGPT was released. I used my RL background to write a blog post on RLHF which went viral. HuggingFace decided it would be good for me to form a team around this success.
In 2023 I learned NLP and about language models. I had a lot of fun and built an initial community. I got burned out by working remote with a huge time difference. I met Luca Soldaini at ICML in Hawaii, where I was giving a tutorial on RLHF, and they told me Ai2 was hiring.
I got the job at Ai2 largely because of my excitement and how I was saying I wanted to do a lot of stuff that sounded cool to them but no one was likely to do (RL related things). My interviews were far from a sure thing – this is a great job to land!
I started at Ai2 in October of 2023. I worked remotely for a while. I was doing normal research, I made the first reward model evaluation, RewardBench. It was a solid success, but nothing like how the pretraining team was getting ready to release the first Olmo.
I helped coach Ai2 on how to release models well, helping the Tülu 2 project land (the first model to do DPO well, publicly at the 70B scale).
The first Olmo was released in early 2024, I squeaked onto the papers just by trying to be helpful and doing some basic post-training. I was already good at paying attention to which projects are actually important.
That summer I started rounding everyone up to do a “big frontier post-training project.” This became Tülu 3, one of my favorite projects ever released, in fall of 2024. The goal was to beat Llama 3’s post-training with their own base model. The team morale was incredibly high and the execution was so timely, allowing us to coin the term Reinforcement Learning with Verifiable Rewards (RLVR) in the paper.
The crazy lengths I went to get the Tülu 3 and Olmo 2 post-training done had me sending 40% more slack messages than anyone at the company and got me the award “The Cat Herder.”
2025 was a much simpler year. We were too slow to react to reasoning models, given we had been doing similar stuff with Tülu 3, but sometimes that happens.
Originally we wanted to release Olmo 3 by June or July of 2025. That obviously didn’t happen, but we got the slim chance to train a bigger model, and it really landed. We threaded the needle.
Since Olmo 3 was released, it was clear that some changes were coming and I personally never got a big post-training project off the ground after that. Many other people managed great work in the spring of 2026.
This all leaves me here today showing you that only about half of my story at Ai2 is what I was known widely for, and the rest was building momentum. It often takes a year of building relationships and direction before really big successes can happen in a career.
I was just about a nobody when I joined Ai2 and I got to join a team that was willing to learn from the skills I had brought from HuggingFace. With how media works, I often think I get more recognition than I deserve for Ai2’s success.
The likes of Tülu 3, Olmo 2, and Olmo 3 felt like generational team efforts. The amount of personal successes and breakthroughs that happened for those projects is immense – and to sustain them over such a long time period is incredibly hard to replicate. The sum far exceeded the individual parts.
I’ve heard many times in the last few months how people wouldn’t know about Ai2 if it wasn’t for my writing. Statements like this are overblown, but they are partially true and reiterate how crucial building relationships and getting the word out is today.
When you write a plan that is feasible, the world bends towards that plan. When you convince people it’s going to happen it only becomes more likely. Vision and compelling explanations are one of the items in shortest supply in the tech industry. Often building the thing is easy and explaining it is hard. If no one knows about your work, the value is often close to 0. So much of building reputation is about building relationships with people who will receive your work.
Reflecting on all of this, I’ve had a shockingly linear path through my career to incremental success. I would expect the first 10 years of most careers to be in search of finding one opportunity as good as Ai2, and you will not always be able to seize it. There are some ways to create more opportunities.
I’ve discussed before how a large part of my rise is down to many more senior and more established scientists being drawn into the closed ecosystems at the same time as an immense swell in interest for AI. This created a power vacuum that I, and a few other prominent scientists that I think form my “generation”, got to grow rapidly into.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
The role of public scientists
With my work at Ai2 and Interconnects, I summarize my role and mission as trying to accomplish three things:
Provide clarity in the evolution of frontier models. This is easiest when the science has caught up, but even applying a scientific lens to how the models are changing is very useful to building trust in the broader AI ecosystem.
Create a vibrant and diverse open (model) ecosystem. This is crucial to mitigating some risks of AI, particularly with concentration of power and myopia in studying frontier safety, that has motivated me now for 3-4 years. The risks haven’t abated.
To build institutions that create people and ideas that further the above missions, and generally mission-driven individuals that are willing to advocate and build a future they believe in. AI is a grand problem, and not one that I can do alone, so I need to build brands to rise through the noise and attract likeminded people.
At my best, I have many avenues for impact. I help open researchers work on impactful problems – not wasting the precious compute and time they have during the AI boom. I help policymakers know what is true. I build models that people use. I tell stories that make people smile. I keep the list wide so that I can stay motivated.
I see all of this continuing, and have been thinking about the broader impacts of this repeatedly over the last few months. Hearing that Andrej Karpathy was joining Anthropic prompted me to finally share more of my opinions:
For a long time, academic researchers being at the cutting edge of new technologies has been a great social equilibrium. Neutral, unbiased technologists have been the people to spread new ideas to the world.
As AI research takes off in velocity, it is also going behind closed doors. The tech industry has sowed distrust, and now they are the ones trying to tell the world about incredible changes coming. It’s a big loss to a form of social contract in America.
There’s been a history of scientists helping society understand new technologies. There is a public service in the culture of science that I want to see continue.
It’s being exacerbated by feelings of FOMO, especially financially driven, where I’m seeing many people who previously wanted to be professors -- and likely still do deep down -- feel a need to conform and chase money, in a pocket of industry. I get it, I grapple with this.
For those with a safety net, there will be great returns to some who choose to zag, and try to build something good, for people who need something different. For me, this is building interesting, fully-open models, to show what you can do with a variety of open weight sizes.
Yes, AI’s immediate future is dictated by the frontier, but it’s long-term trajectory still deeply includes academic institutions and open science. Knowledge will always diffuse, but to whom?
As of today, I think China is positioned to be the global home of AI research in a few years. The home of research is where ideas are accessible, spread rapidly, and are nurtured. The U.S. seems to be unwinding many institutions and relationships.
The largest returns go to people who build something differentiated, at least in reputation, and a lot of people are not being shown that this path exists.
To elaborate on this, I don’t fault any of the individuals who are going to industry today. I’ve been very close to doing this myself in the past weeks of job searching, or rather job exploring. It’s a systematic problem where scientists cannot easily get the support to take bold stances, especially stances that are designed around the public good.
To go a step further and say that only the research within closed, frontier labs matters is very myopic. Yes, there’s a sort of research you can only do with vast compute resources, and they will directly impact the most revolutionary tools of the day. But, I see the relative opportunity to do good elsewhere as higher for plenty of people.
Open research will always be the standard that sets the language people use to understand AI. It’ll always be how the next generation is trained – even if it’s behind what industry has built. It’ll be the ecosystem where new long-shot ideas are built. Without investing in this open ecosystem, all of these cycles will be kneecapped.
At the end of the day, so much of my role now is just showing the path to impact in this domain. To show how clever, mid-sized open models can impact real problems in the world. To show how policy-makers and educators need open research to structure the rest of society around AI. This is a fun role too! It would be very sad for me to see this light diminish ever further, into the lightest embers of a fire that looks almost entirely out.
Even if the pace of research were to slow further, if the folks remaining like myself got financial offers they can’t refuse for their families’ sake, the torch of open research will never fully go out. It’s core to how science is taught and done. There is a next generation coming, they just look for guidance and role-models.
What’s next
I see the best Ai2 work as research infrastructure. Building recipes in public gives countless researchers the ability to ask very specific questions of training processes. We need these researchers in the broader community, as Ai2 could never answer all the interesting questions themselves. One of my great joys in recent months has been visiting a top ML university and hearing so many graduate students say they’re building on Olmo. This is how the world should work!
Going forward, I still plan to operate in similar spaces, fighting for open-science, imagining what the future of the open model ecosystem can be, and doing my best to make the social transition to an AI-native era smooth. I’m most excited by how you can train medium sized open models on specific tasks that become useful tools in complement to the frontier models – massively winning on price. I want to invest in the ecological diversity of open models and coordination across builders.
For something that isn’t surprising given my past focus areas, I’m watching the pace of releases from all labs open & closed, and how they’re hillclimbing on super ripe new post-training veins (on-policy distillation, agentic workflows, etc.), it’s clear that fully-open post training recipes are about as far behind as they ever have been & falling further behind. I’d like to fix this. It’s not 100% clear yet if I will this year, but I’ll try.
To do this best and to execute, mostly personally, I needed a new start and fresh perspectives. I’ll be carefully building what I’m doing next over the next few months and am eager to share more about it when I can. One of my close teammates at Ai2 shared this quote with me in a farewell card, and I found it very apt in where I’m going next.
The object of life is not to be on the side of the majority, but to escape finding oneself in the ranks of the insane. — Marcus Aurelius
The largest debate that’ll define the future balance of power between the open and closed AI model ecosystems is primarily economic — it’s if users of AI will continue to pay dramatically more, i.e. large margins, for the top closed models. Early 2026 is a seminal time for the AI industry, as the coding agents1 have shown the first area where a huge AI market will continue to pay a substantial premium for better intelligence.
The other side of this dichotomy is the inevitable decay of API businesses at these same labs. These labs will realize they need to protect their best models, rolling them out later in APIs to both protect token supply, avoid distillation, and stick to use-cases with higher margins. All of these effects will be clearly visible in 5-10 year timelines, as in the near term markets, prices, margins, and demand will be dictated by a rapid buildout of compute (supply-limited in the near term) and mass subsidization of tokens (through continued investment in new AI companies).
The core of this argument rests in the obvious habit changes that are setting in with coding agents past the Opus 4.5 and Codex 5.2 thresholds. People are not making this switch because they are lazy, but because their net output is obviously higher when using an agent as an implementation aid for complex knowledge work. For people who rely on coding agents to work, they will always pay more for the best rather than settle for good enough. There are so many ways to make the product better, speed, intelligence, specialized models, etc.
I would pay $2000/month for the tools today, especially knowing they’ll get much better. At the same time, it is likely that many companies are forcing agents and usage onto people that actually will get very little out of them in their current form, which helps the AI buildout (or bubble) continue.
The best closed labs — right now this list is just Anthropic and OpenAI, but it’s reasonable to expect Google to catch up — will always make the most efficient models for intelligence at a given cost. Building models is a mass capital investment of talent, data, and compute. These systems, a combination of model weights, harnesses, tools, and serving infrastructure have massive returns on integration (where open models are designed to work across many, diverse serving situations). These integration benefits — the integration of hardware and new forms of software — can be expressed in any possible way of making models better.
The models in the near future may saturate on benchmark scores, but if that intelligence ceiling really is a cap on utility then the labs will optimize utility per second or per watt, serving users in another way. Improving the models is possible in every direction — there have been no walls in progress. We’re early in the mass buildout of intelligence, which involves harnessing the physical world to build numerous datacenters, organizing many AI researchers so that a large team can contribute to one model, and of course solving many small, low-level puzzles that unlock performance. Every indication is that there is still meaningful performance to be unlocked and the closed labs are the best set up to extract it.
The collective wisdom of the labs is that making the models smarter, in terms of the frontier of absolute intelligence, has the most value. This is the right call to me because it unlocks large new markets. Optimizing models at a fixed intelligence level locks in markets, expands accessibility over time, and increases return on investment for users (while potentially lowering margins for selling intelligence).
Many people are making this bet that models will keep getting better and are learning to work well in these harnesses, even though some workflows are still a bit clunky. This is the right bet. These people all will continue to use the absolutely best models available. It’s like buying an iPhone as a consumer. You could get an Android and suffer from a bunch of paper cuts to save money, but why would you? The returns to performance are even higher in the workplace, which drives pricing power.
In this mental model, the frontier labs as businesses, will look like new, reimagined forms of a mix of Apple and Microsoft. The Apple side is that they’re selling an integrated, extremely hard to replicate technology. The Microsoft side is selling high-leverage subscriptions across the economy. In 5-10 years I expect both OpenAI and Anthropic to be valued in the $2-10T range. The true frontier labs will be an oligopoly that looks like the cloud market today.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
On the other side of this equation is the open model economy. This isn’t to say that the frontier labs will dominate all aspects of AI use. Yes, I expect OpenAI and Anthropic to be the most representative companies of the AI boom (new companies, alongside Nvidia of course), but the collective value capture around open models will be far bigger overall, it’s just that the revenue and margins will be shared across a wide stack of companies.
Many businesses want to switch to open models but the models today are not good enough in out-of-distribution tasks. Eventually open model builders will stop chasing Claude and GPT on the Artificial Analysis index and fill this niche. This fork could be driven by economic factors, where they no longer have the revenue to support the growing R&D costs for continuing to scale models. It can also be driven by pure demand, where certain AI solutions only can exist at low price points present in open models. Where closed labs are an oligopoly, open model builders and users will be far more diverse and numerous. The total market value will dramatically exceed the cumulative value of OpenAI and Anthropic.
Open models are by their nature not integrated, so they will rely on multiple companies coordinating to serve them. Each of these layers will have alternatives, driving prices down to commodity pricing. These low, predictable prices will be where many enterprises enter to build in-house agents and tools for niche tasks. The predominant mode of deployment here is that enterprises find a model that hits a sufficient performance threshold on a task of interest and does not replace the model later (setup costs are high). As customizing models becomes easier, again in the open model finetuning stack we are seeing emerge (Tinker, Fireworks, Prime Intellect, etc.), this market becomes even bigger.
What this will look like in the coming years is a steady rise in open model inference proportion across the entrenched hyper-scale clouds of Google, Amazon, Microsoft and new AI infrastructure companies of Together, Fireworks, OpenRouter, etc when compared to OpenAI and Anthropic.
The closed models hit incredible product-market fit with the current agents, starting their integrated exponential by monetizing the top end of the knowledge work. The open model economy will take far longer, but it will also be far more satisfying to follow, as it tracks the broader diffusion of AI into the entire economy and world.
As the years of AI progress go by, it’s been accompanied by a slowly rising tide of consequence. Models are getting more capable, how we work is changing quickly, economics of AI are becoming real, just as real-world risks come to the forefront. 2026 is the first year where I don’t think there’ll be any breaks from this. The hard part to prepare for is that there’s a good chance things just continue to ratchet up from here – more disruption, more surprises, more stakes.
On my end, there’s been a growing list of topics that are very fateful to how I see the current state of AI, but I haven’t even gotten to write about them (at least not from all the angles I want to)! All of these are closely related to the implications of different models reaching new capability levels and how I use that to infer what may come next.
1. Open models haven’t had their true agent moment like Opus 4.5
The time gap between open and closed models is very often discussed, but the reality is that we have a nice time-gating that’s independent of debatable benchmarks – if open-weight models do or do not become super useful in agentic harnesses. The Opus 4.5 in Claude Code moment of December 2025 was so loud and obvious, that if open models hit this performance level for price points as low as $5/month, there will be an explosion in usage.
Right now we are about 5-6 months in with no equivalent open model. I suspect the robustness of the best closed frontier models that I write about could make this moment take a good amount longer, say closer to 12+ months. In this time, Claude Code and Codex may seem like different categories of products. In the standard flurry of new, state-of-the-art open models from a variety of labs, benchmarks will definitely keep climbing, but the open-closed gap should become more interpretable as real-world use becomes the real litmus test.
2. Gemini still doesn’t have a meaningful competitor for Claude Code and Codex
The best exclamation point I can offer to reinforce my prediction that open models are further behind than the benchmarks claim is that even the mighty Google doesn’t have a clear competitor for Claude Code and Codex. I’m sure the Gemini team is pushing very hard on this.
I still need to do a lot more testing on Gemini 3.5 Flash, but reading reviews makes it clear that it’s not a substitute for how I’m working today. It’s maybe not the Gemini team explicitly specializing for Google’s existing products (search, YouTube, etc.), but the model seems to suit them. If Google doesn’t have a powerful tool here soon, I don’t expect the open model labs to either. The open models are going to be used more for automated, enterprise agents and low-cost domains, rather than being the driving tool of modern knowledge work. This will feed directly into the economic engine of funding future models, where the agents like Claude Code and Codex are the current best path to massive AI revenue growth.
I discussed how the current environment is quietly driving labs in China to specialize on AI Proem with Grace Shao and this is central to my expectations of open models specializing over the next few years instead of competing with OpenAI, Anthropic, and Google.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
3. I don’t expect an open-weights Mythos this year
While I don’t think Mythos is a general “god model” that will crush the competition in every domain, I do think it’s a remarkable technical achievement in software engineering and cybersecurity. Mythos is obviously a watershed moment for those fields. Having spoken to most of the Chinese labs – particularly those with the most prominent, large, open MoE models like Kimi, Z.ai, DeepSeek, and Qwen – I think they’re heavily resource limited and don’t have an immediate path to scaling up training processes like the big labs in the U.S. For the labs which are more corporate, which comes with more resources, such as Alibaba and Bytedance, they also have more conservative stances on safety and security.
Mythos is a bellwether of the massive acceleration in training and research compute available to the largest American companies.
Epoch AI recently had a nice piece on the compute available to various labs (~Google 25%, Meta 11%, OpenAI 11%, Anthropic 6%). All of these numbers are vastly higher than any Chinese lab.
4. American open models are slowly gaining steam
Nvidia with Nemotron, Google with Gemma, Arcee AI and others are slowly stabilizing the open model ecosystem in the U.S. There’s a lot that’s hard to measure here, especially in the rise of local agents like OpenClaw and Hermes, but there are adoption numbers of American models that we haven’t seen since Llama 3.
Gemma 4’s models are all tying or outperforming the equivalently sized Qwen 3.5/3.6 models — where Qwen has for years now been the default open model at these sizes. These Qwen 3.5/3.6 models have been tricky to get working in a lot of post-training research, partially due to architecture/tooling and partially likely due to modeling (i.e. the model is not easy to finetune for some training decision). I’ve heard few complaints about Gemma, but it also could be because Gemma is not yet the researcher default.
There's a simple reality that we've seen recently with models like GPT-OSS, Nemotron 3, and now Gemma 4, that if a model is in the right range of benchmarks and released by an American lab with a truly permissive license, it'll get a large amount of adoption (in this cycle, recall that Gemma 4 adopted the Apache 2.0 License, changing from one with use-case restrictions on earlier Gemmas). This early phase of American growth in open models is establishing key brands directly with developers. The consensus is that more neolabs like Reflection and Thinking Machines are likely to participate in this space, but being too patient will lose the time when new agentic workflows and enterprise relationships are built.
5. Anthropic and OpenAI are just getting up to speed in model iterations
I expect the rest of this year to be a ruthless competition between these two flagship companies. I’m at an interesting balance where I think GPT 5.5 is a bit smarter of a model and I love the Codex App, so I’m structuring much of my work to be possible there. At the same time, for a lot of writing-related and broader surface area tasks I really still love Claude. These models are rapidly changing how we work, I run Codex from my phone while doing other things, am setting up automated open model analysis jobs on the back of agents, and expect to be able to scale the research side of Interconnects widely.
AI is beginning to drive companies to the two extremes in the scaling era. The biggest companies will be way bigger than ever, using resources and mass talent to have sustained progress at the frontier of raw AI capabilities. On the other side, tiny businesses like Interconnects thrive by using agents to refine, present, and sell niche expertise. The mass social job displacement that’ll come is going to reduce employability for various knowledge workers that don’t fit into either of these extremes for the raw technical side (big or small companies), while sustaining and maybe even amplifying careers that interface directly with humans (e.g. doctors) or other power structures with means to sustain themselves (law/government).
6. More existing power structures will assert themselves on AI
Just in the last few days while writing this, we had the Pope release an over 40,000 word document on where AI is goingand China expand personnel movement restrictions on top AI researchers across industry. At the same time, the U.S. has designated Anthropic a supply chain risk and continues to use its models for national security. The list of news like this is only going to grow. Existing power structures are realizing there’s a finite time window for them to exert themselves in the AI dynamic — an intuition that could be mapped to influence going down as AI models get more powerful. This intuition is potentially dangerous, as it sets up meaningful conflict in who controls the technology (as I discussed with Dean Ball after the Anthropic-DoW spat).
Next: Where technical becomes social
These largely technical and power trends accelerating are going to put more pressure on the social and political anti-AI sentiments within the U.S. This is currently the most obvious barrier to continued AI development and beneficial diffusion. Reflecting on this, many people in the tech discourse get too focused on the details, where yes a lot of data-center-detractors are making genuinely wrong factual claims in defense of their position.
The real position that a large swath of Americans has is that they have a voice in saying no to the current trend — by not granting permission to build data centers. This is a voice that they haven’t been granted by the tech industry that changed the face of the global economy and power structures in the last few decades.
This is setting us up for a challenging year ahead for the industry. The labs are aggregating and concentrating talent to peak levels. There are few neutral messengers to communicate the reality of AI to the public. The frontier labs leadership is largely gearing up to IPO and stay ahead in the capabilities race. With the status quo, there are few actions to unwind this path toward social conflict.
It takes individuals in the AI ecosystem to zag and go against the groupthink of needing to make your wealth today, of needing to be at a lab to do impactful work, and so on. I’m personally continuing to bet on this, by trying to make a vibrant and diverse open model ecosystem supported by clear, unbiased information. If you agree with this and have been watching from the sidelines, it’s a good time to get involved, before the situation spirals into something uncontrollable.
This month was packed, with all open frontier labs, including DeepSeek, releasing new models. The latter prompted an evaluation by the Center for AI Standards and Innovation (CAISI), which has evaluated open models and their risks in the past. Their result is that open models lag behind the American frontier, with the gap becoming wider over time:
For the report, they calculate an Elo score based on Item Response Theory, which is commonly used to compare different models, even when they were tested on a different set of benchmarks. For V4, CAISI used nine different benchmarks:
The huge Elo difference is explained by DeepSeek V4s bad score in CTF-Archive-Diamond (which was only run with a subset of the benchmark and extrapolated with IRT for V4), PortBench (a CAISI-private benchmark) and ARC-AGI-2 (with a different scoring method than the public leaderboards). The differences in these benchmark have a huge impact on the overall Elo, which can exacerbate the difference in capabilities.
When using Epoch AI’s ECI, which also uses IRT over a set of different benchmarks, we see that the gap roughly stays between 3-7 months since R1:
The open<>closed gap in ECI (from https://mcnair.center/china/)
However, both CAISI and ECI paint an incomplete picture, as both use standardized (and simple) setups to compare the capabilities of models. To be more concrete: Coding tasks are evaluated using access to bash and a for-loop with a fixed budget of tokens, not with a harness such as Claude Code or OpenCode, which models are trained in! These setups result in benchmarks claiming that porting applications to another language is currently not possible, while Bun has been ported from Zig to Rust with 1 million LOC changes1.
Therefore, we would argue that a frontier comparison of open and closed models would also need to elicit the capabilities of all models better, which means the usage of the preferred harnesses, as well as model-specific prompting.
This section was written primarily by Florian. An interesting dynamic within Interconnects is that Florian believes more in the proximity of open frontier models to closed alternatives in true performance. Nathan thinks the benchmarks are imperfect as well, but thinks the closed models are ahead by more. We’re going to continue to unpack this in our future content.
MiMo-V2.5-Pro by XiaomiMiMo: Avid Artifacts readers know that Xiaomi has been working on open models for a while; its debut was exactly one year ago. The progress of its releases is remarkable, with 2.5 Pro (released under Apache 2.0) being neck and neck with other flagship models such as Kimi K2.6 and GLM-5.1 in both benchmarks and real-world usage.
gemma-4-26B-A4B-it by google (full Interconnects post here): The long-awaited update to the Gemma series, featuring multiple sizes: 4B, 9B, and 31B dense models, as well as a 26B-A4B MoE. Even more importantly, with Gemma 4, Google has decided to use Apache 2.0 as its license, which removes the uncertainty and legal challenges around interpreting custom licenses.
Kimi-K2.6 by moonshotai: An update to the Kimi series, delivering stronger performance across the board and making it one of the best open models out there yet again. They also focus on long-horizon performance, showing that open models are capable of running over hours to complete tasks or optimize performance. Given the focus of everyone to build autoresearch-like systems, seeing open models catch up is important.
Laguna-XS.2 by poolside: Poolside AI has released its first public coding-focused models, including the open-weight XS.2. Its size (33B-A3B) makes it attractive for local use, with performance on par with other models in that size range. The accompanying blog post is worth a read, as is the deep dive into reward hacking during coding evaluations.
DeepSeek-V4-Flash by deepseek-ai: DeepSeek has finally released its successor to the V3 series, which it kept updating for months. It comes in two sizes: Pro, which is a 1.6T-A49B MoE, and Flash, a 284B-13B model. Based on others’ experience, the latter model seems to be the real star of the show, as its performance is relatively strong, while Pro seems to underdeliver relative to its size. The tech report goes into great detail, including the architectural changes used to achieve better and cheaper long-context performance.
Models
General Purpose
Qwen3.6-35B-A3B by Qwen: An update to the Qwen 3.5 series targeting one of the most widely used sizes.
LFM2.5-350M by LiquidAI: With 28T tokens for 350M parameters, this model might be the most overtrained model out there.
Trinity-Large-Thinking by arcee-ai: The reasoning version of Trinity, one of the best Western open models. It has topped the OpenRouter charts for a while and can power agentic applications such as OpenClaw.
GLM-5.1 by zai-org: An update to GLM-5, improving scores across the board. The focus for this update is on long-horizon tasks.
Note: Voice-overs for paywalled posts are available for paid subscribes in podcast apps if you click on settings on Interconnects, then manage your description. Thanks for listening!
Most of the compute to build a leading frontier model comes from R&D costs, rather than the compute to train the final, big model end-to-end. In an ecosystem like China, where all the leading players are open, this creates a potential meaningful advantage in cost structures that’ll let labs keep building longer than outside observers would expect.
In a world where research and development is most of the compute, the Chinese system is designed around quickly learning from your peers and avoiding double-spending research compute — or infra effort. It’s far from perfect, but it’s the closest analog to the OSS ecosystem that one can get for building LLMs. The public discussion of AI has always emphasized that the models are expensive in a way that naturally lets passive readers think this is compute just dedicated to the artifact — as we saw with DeepSeek V3.
This had me revisiting the core issue of open-source AI, and how it doesn’t have the feedback loops akin to open-source software (OSS) users back to the creation itself, that creates immense value following Linus’s law of “given enough eyeballs, all bugs are shallow”. This self-reinforcement of OSS makes deployment at scale the cheapest possible outcome — all the users together share the costs of fixing bugs and adding features.
Within open-source AI, almost all the cost falls on the model developer. At the same time, there are huge benefits to releasing the model openly that do reduce costs, but they only help reduce future development and deployment costs for the creator themselves, but more importantly the ecosystem widely.
Open AI models, tools, infrastructure, and everything in between are a cost reduction in development, not plug and play cost reduction on apples to apples solutions or products. If someone is going to be just using AI off-the-shelf with minimal iteration or internal development, using open models will almost always be more expensive. Using closed, integrated, hosted solutions achieves low price points by economies of scale across general usage.
The open-source ecosystem can only try to mirror the OSS-style financial and performance gain in continued performance. The Chinese labs, through incredibly thorough technical reports and intentional knowledge sharing across labs effectively are de-risking ideas for their peer companies to not necessarily need to invest as many resources in.
For this to work, the current norm where AI companies fork open-source tools, to evolve them into internal-only versions, will likely need to fade out. It’s too common of a trope for open-source AI companies to have their selling point being better performance via enterprise agreements or internal tools, as the fully open tools that people start with are falling behind in accessibility. A prime example is at-scale RL training of MoE models — no truly open recipe exists. It’s unclear if the open-supporting, but partially closed tools like Thinking Machine’s Tinker and Prime Intellect’s Lab can be open enough for the advantages of an open ecosystem to sustain themselves. The more open the stack is, and the more information is shared, the more costs are reduced in future iterations.
The same reasoning that causes companies to fork open-source tools to make internal versions applies to why there isn’t a shared, single foundation model that everyone builds on. Building the best model today becomes an art of integrating your hardware, data, and infrastructure, while evolving all of them at a relatively high rate that lets you keep up with the frontier of performance. Given that all signs point to LLMs continuing their steady march in performance improvements for years, it seems unlikely to expect this equilibrium to change in the near term. This is exactly why I wrote my post on the inevitable need for an open model consortium – this shared resource is far more efficient and may become the only financially viable way to compete at the future frontier scale with open models.
It’s worth noting that, of course, the closed labs also see the investigations of the open frontier model companies and can benefit from them, but with the assumption that the closed labs are some months ahead in the development tree, they often naturally stand to benefit less from the shared insights. The stronger the open-source community is, the more cost incentive there is for the various companies to be relatively close together on the same Pareto curve of performance.
This realization of the difference between development costs, or a process-focused technology, rather than some shared foundation that all the labs build on directly was downstream of a question I got in feedback to my recent China trip summary. The question was: “Was there any chance of the Chinese ecosystem converging on a single base model to save costs?” The follow-up to this question was on if any of the open-weight companies in China are using open-source in strategically meaningful ways. There are many more useful questions to ask here, especially when trying to understand the different operational patterns of the ecosystems.
China’s foundation model development model
I found the following interview conducted by Bill Gurley with Dan Wang, author of Breakneck, and Patrick McGee, author of Apple in China, (both books I strongly recommend – must reads) very thought provoking on the biggest differences between technology cultures in the U.S. and China.
I get a lot of exposure to these differences at this point in my open-source AI arc. There’s a deep yearning to influence Western audiences and thinking that has bubbled up out of the Chinese AI ecosystem in the last year. This was obviously a strong pretext for why the SAIL group got such access in our recent trip – it’s not a given that anyone in the AI ecosystem will talk to senior leadership at so many companies.
Staring out the window on a new, high-speed train from Hangzhou to Shanghai I’m gifted with views of dramatic ridgelines speckled with wind turbines that are silhouetted against the setting sun. The mountains cast a backdrop to a mix of spanning fields and clustered skyscrapers. I’m returning from China with great humility. It’s a very warming, human experience to go somewhere so foreign and be so welcomed. I had the honor of meeting so many people in the AI ecosystem who I knew from afar, and they greeted me with big smiles and cheer, reminding me how global my work and the AI ecosystem is.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
The mentality of Chinese researchers
The Chinese companies building language models are set up as the perfect fast-followers for the technology, building on long-standing cultural traditions in education and work, along with subtly different approaches to building technology companies. When you look at the outputs, the latest, biggest models enabling agentic workflows, and the ingredients, excellent scientists, large-scale data, and accelerated computing, the Chinese and American labs look largely similar. The lasting differences emerge in how these are organized and conditioned.
I’ve long thought that a reason that the Chinese labs are so good at catching up and keeping up with the frontier is that they’re culturally aligned for this task, but without talking to people directly I felt like it wasn’t my place to attribute substantial influence to this hunch. Speaking with many wonderful, humble, and open scientists at the leading Chinese labs has crystallized a lot of my beliefs.
So much of building the best LLMs today comes down to meticulous work across the entire stack, from data to architecture details and RL algorithm implementations. All points of the model can give some improvements, and fitting them in together is a complex process where the work of some brilliant individuals needs to get shelved in favor of the overall model maximizing a multi-objective optimization.
Where American researchers are obviously also brilliant at solving the individual components, there’s more of a culture of speaking up for yourself in the U.S. As a scientist, you’re more successful when you speak up for your work and modern culture is pushing the new path to fame of “leading AI scientists”. This results in direct conflict. The Llama organization is heavily rumored to have collapsed under the political weight of these interests embedding themselves in a hierarchical organization. I’ve heard of other labs saying that it can be needed to pay off a top researcher to get them to stop complaining about their idea not making it in the final model. Whether or not that’s exactly true, the idea is clear. Ego and desires for career advancement do get in the way of making the best models. A small, directional shift in this sort of culture between the U.S. and China can have a meaningful impact on the final outputs.
Some of this has to do with who is building the models in China. There’s an immediate reality at all of the labs that a large proportion of the core contributors are active students. The labs are quite young, and it reminds me of our setup at Ai2, where students are seen as peers and directly integrated in the LLM team. This is incredibly different from the top labs in the US, where the likes of OpenAI, Anthropic, Cursor, etc. simply don’t offer internships. Other companies like Google nominally have internships related to Gemini, but there’s a lot of concern about whether your internship will be siloed and away from anything real.
To summarize how the slight change in culture can improve the ability to build models:
More willingness to do non-flashy work in order to improve the final model,
People new to building AI can be free of prior phases of AI hype cycles, allowing them to adapt to the new modern techniques faster (in fact, one of the Chinese scientists I talked to really actively attached to this strength),
Less ego enabling org charts to scale slightly, as there’s less gamifying the system, and
Abundant talent well-suited to solving problems with a proof of concept elsewhere, etc.
This slight inclination towards skills that complement building today’s language models stands in contrast to a known stereotype that Chinese researchers tend to produce less creative, field-spawning, 0-to-1 academic style research. Among the more academic lab visits on our trip, many leaders talk about cultivating this more ambitious research culture. At the same time, some technical leaders we talked to were skeptical about whether such a rewiring in the approach to science is likely in the near term, because it’ll take a redesign of the education and incentive systems that is too big to happen within the current economic equilibrium. This culture seems to be training students and engineers that are excellent at the LLM building game. They also, of course, have an extremely abundant quantity.
These students told me about a similar brain drain happening in China as in the U.S., where many who previously considered academic paths now intend to stay in industry. The funniest quote was from a researcher who was interested in being a professor to be close to the education system, but remarked that education is solved with LLMs – “why would a student talk to me!”
The students have a benefit of coming at LLMs with fresh eyes. Over the last few years we’ve seen the key paradigm of LLMs shift from scaling MoE’s, to scaling RL, to enabling agents. Doing any of these well involves absorbing an insane amount of context quickly, both from the broader literature and the technical stack at your company. Students are used to doing this and excited to humbly drop all presumptions about what should work. They dive in head first and dedicate their life to getting the chance to improve the models.
These students are also so magically direct and free of some of the philosophical chatter that can distract scientists. When asking questions on how they feel about the economics or long-term social risks of models, far fewer Chinese researchers have sophisticated opinions and a drive to influence this. Their role is to build the best model.
This difference is subtle, and easy to deny, but it is best felt when having long conversations with an elegant, brilliant researcher who can clearly communicate well in English, basic questions on more philosophical aspects of AI hang in the air with a simple confusion. It’s a category error to them. One researcher even quoted the famous Dan Wang premise of China being run by engineers, relative to the lawyers of the U.S. when probing in these areas, to emphasize their desire to build. There’s no track in China that systematically enables the growth of star power for Chinese scientists, akin to mega mainstream podcasts like Dwarkesh or Lex.
Trying to get Chinese scientists to comment on the coming economic uncertainty fueled by AI, questions beyond the capabilities of simple AGI, or moral debates on how models should behave all served to capture the upbringing and education of these scientists (edited1). They are extremely dedicated to their work, but have grown up in a system where debates and opinions on how society should be structured and changed are not encouraged.
Zooming out — Beijing especially felt much like the Bay Area, where a competitive lab is a short walk or Uber away. I got off a flight and stopped by Alibaba’s Beijing campus on the way to the hotel. Then, in 36 hours we went to all of Z.ai, Moonshot AI, Tsinghua University, Meituan, Xiaomi, and 01.ai. Travel by Didi is easy, and if you select an XL in China you’re often paired with electric mini vans that have massage chairs. We asked the researchers about the talent wars, and they said it’s very similar to what we’re experiencing in the U.S. It’s normal for researchers to bounce around, and much of where people choose to go is based on the best current vibes.
In China, the LLM community feels far more like an ecosystem than battling tribes. Across many off the record conversations, it’s nothing but respect for peers. All of the Chinese labs fear Bytedance with their popular Doubao model, which is the only frontier closed lab in China. At the same time, all of the labs have massive respect for DeepSeek as the lab with the best research taste in execution. When you meet with lab members off the record in the States, sparks fly quickly.
The most striking part of the humility of Chinese researchers is how they also often shrug on the business side, saying it’s not their problem, where everyone in the U.S. seems to be obsessed with various ecosystem-level industrial trends, from data sellers to compute or fundraising.
Where China’s AI industry differs (and matches) the Western labs
The thing that makes building an AI model today so interesting is that it’s not just about getting a group of great researchers in one building together to produce an engineering marvel. It used to be this, but to sustain AI businesses, the LLMs are becoming a mix of building, deploying, funding, and getting adoption for this creation. The leading AI companies exist in complex ecosystems that supply money, compute, data and more in order to keep pushing the frontier.
The integration of these various inputs to creating and sustaining LLMs is fairly well conceptualized and mapped for the Western ecosystem, as typified by Anthropic and OpenAI, so finding big differences in how the Chinese labs think about it points at where the different companies can be making meaningfully different bets on the future. Of course, these futures can be heavily dictated by the constraints on funding and/or compute.
I’ve documented the biggest “AI Industry” level take-aways from talking to these labs:
Early signs of domestic AI demand. There’s a much-touted hypothesis that the Chinese AI market will be smaller because Chinese companies don’t tend to pay for software – thus, never unlocking a giant inference market supporting labs. This is only true for software spend that maps to the SaaS ecosystem, which is historically tiny in China, where on the other hand there is obviously still a large cloud market in China. A crucial unanswered question – one which the Chinese labs themselves debate – on if spending for AI in the enterprise tracks the SaaS market (small) or the cloud market (fundamental). On net, it feels like AI is trending closer to the cloud, and no one was actively worried about a market growing around the new tools.
Most developers are Claude-pilled. Most of the AI developers in China are obsessed with Claude and how it’s changed how they build software, despite Claude nominally being banned in China. Just because China has historically been hesitant to buy software does not give me the impression that there won’t be a massive surge in inference demand. Chinese technical staff are so practical, humble, and motivated – a fact that seems stronger than any commitment to previous habits in not spending.
Some Chinese researchers mention building with their own tools, such as the Kimi or GLM CLIs, but all of them mention building with Claude. There were also surprisingly few mentions of Codex, which is definitely surging in popularity in the Bay Area.
Chinese companies have a technology ownership mentality. The Chinese culture is combining with a roaring economic engine to create unpredictable outcomes. I’m left with a lasting feeling that the numerous AI models reflect a practical, current equilibrium of the many technology businesses here. There’s no master plan. The industry is defined by a respect for ByteDance and Alibaba, the incumbents expected to win large portions of all markets with their substantial resources. DeepSeek is the respected technical leader, but far from a market leader. They set the direction, but aren’t set up to win economically.
This leaves companies like Meituan or Ant Group, where people in the West can be surprised they’re building these models. In reality, they see LLMs obviously as being central to future technology products, so they need a strong base. When they fine-tune the strong, general purpose model it hardens their stack from getting the open community to provide feedback on it, and they can keep internal, fine-tuned versions of the model for their products. The “open-first” mentality in the industry is largely defined by practicality — it helps make their models get strong feedback, it gives back to the open-source community, and empowers their mission.
Government aid is real, but unclear how big. It’s often asserted that the Chinese government is actively helping with the open LLM race. This is a government that’s decentralized across many levels, each of which doesn’t have a clear playbook for what exactly they do. Neighborhoods in Beijing compete for tech companies to house their offices there. The “help” offered to these companies almost certainly involved removing bureaucratic red tape like permits, but how far does it go? Can levels of the government help attract talent? Can they help smuggle chips? Across the visit, there were many mentions of government interest or help, but far too little to report the details as assertive or have a confident worldview of how government can bend the trajectory of AI in China.
There were certainly no hints of the top levels of the Chinese government influencing any technical decisions in the models.
The data industry is far less developed. Having heard so much about the likes of Anthropic or OpenAI spending $10M+ for single environments, with cumulative spend on the order of hundreds of millions per year to push the frontier of RL, we were eager to know if Chinese labs are either buying the same environments from companies in the U.S. or supported by a mirrored domestic ecosystem. The answer was not quite complete that there’s no data industry, but rather that their experience was that the data industry was relatively poor quality and it is often better to build the environments or data in-house. Researchers themselves spend meaningful time making the RL training environments, and some of the bigger companies like ByteDance and Alibaba can have in-house data labelling teams to support this. This all mirrors the build-not-buy mentality from the previous bullet.
Desperation for more Nvidia chips. Nvidia compute is the gold-standard for training and everyone is limited in progress by not having more of it. If supply was there, it is obvious that they would buy it. Other accelerators, including but not limited to Huawei, were spoken positively of for inference. Countless labs have access to Huawei chips.
These points paint a very different picture of an AI ecosystem, where quickly mapping how Western labs operate to their Chinese counterparts will often result in a category error. The crucial question is if these different ecosystems will produce meaningfully different types of models, or if the Chinese models will always be explained by being similar to the U.S. frontier models of 3-9 months ago.
I knew so little about China going into the trip and came out with the feeling of just starting to learn. China isn’t a place that can be expressed by rules or recipes, but one with very different dynamics and chemistry. The culture is so old, so deep, and still completely intertwined with how domestic technology is built. I have much more learning ahead.
So much of the current power structures in the US use their current worldviews of China as crucial mental devices for decision making. Having talked, in person, either formally or informally to pretty much every leading AI lab in China, there are a lot of qualities and instincts in China that’ll be very hard to model with Western decision making. Even after asking directly about why these labs release their top models openly, the intersection between ownership mentality and genuine ecosystem support is hard for me to connect the dots on.
The labs here are practical and not necessarily absolutists around open-source, where every model they build would be released openly, but there’s a deep intentionality in supporting developers, the ecosystem, and using it as a way to learn more about their models.
Almost every major Chinese technology company is building their own general purpose LLMs, as we see with the likes of Meituan (delivery service) and Xiaomi (broad consumer technology company) releasing open weight models. The equivalent companies in the U.S. would just buy services. These companies aren’t building LLMs out of a race to be relevant with the hot new thing, but a deep fundamental yearning to control their own stack and develop the most important technologies of the day. When I look up from my laptop and always see bunches of cranes on the horizon, it obviously fits in the with the broader culture and energy around building in China.
The humanity, charm, and genuine warmth of Chinese researchers is extremely humanizing. At a personal level, the cut-throat geopolitical conversation we’re used to in the U.S. hasn’t permeated them at all. The world can use more of this simple positivity. As a citizen of the AI community, I currently worry more about the fissures appearing within members and groups around labels of nationality.
I’d be lying if I said I didn’t want US labs to be clear leaders in every part of the AI stack — especially with open models where I spend my time — I’m American, and that’s an honest preference. With this, I want the open ecosystem itself to thrive globally, as this can create safer, more accessible, and more useful AI for the world, and right now the question is whether American labs will take the steps to own that leadership position.
As of finishing this piece, more rumors are swirling of executive orders influencing open models, which can further complicate this synergy between American leadership and the global ecosystem — it doesn’t fill me with confidence.
Thank you to all the wonderful people I got to talk to at Moonshot, Zhipu, Meituan, Xiaomi, Qwen, Ant Ling, 01.ai, and others. Everyone has been so welcoming and gracious with their time. I’ll keep sharing my thoughts on China as they crystallize, across culture generally and AI specifically. It is obvious that this knowledge will be directly relevant to the story unfolding at the frontier of AI development.
Edit 05/07: In this paragraph in the original I misattributed an unwillingness to speak on broader issues to humility, which can of course play a part, but this habit is also shaped by the system which they were trained and raised, a system they are successful in and adept at navigating.
What I removed: … capture the upbringing and education of these scientists extreme humility of these scientists. It’s more than just being dedicated to their work, but they don’t want to comment on issues they’re not informed on.…
‘Distillation attacks’ is a horrible term for what is happening right now. Yes, some Chinese labs are hacking or jailbreaking APIs to attempt to extract more signal from model APIs — stopping this is important to maintain the U.S.’s lead in AI capabilities. Referring to this as distillation attack is going to irrevocably associate all distillation with this behavior, and distillation generally is a core technique needed to diffuse AI capabilities broadly through academic and economic activities.
We went through this sort of language transition with the open source vs open weight debate. All the terms just reduced to open models – very few people in the large AI community know exactly how open-source differs from open-weights. And terminology matters, as the less informed people who still care about — and influence — the technology are bound by different terms they use. If we’re not careful with the discourse around distillation, many people could associate this broad technique used for research and development of new models as an act at the boundary of corporate manipulation and crime.
I’ve recently written a more technical piece on estimating how impactful state-of-the-art distillation methods are on leading Chinese models, and this piece follows to push for caution in any hasty actions to target the methods with policy. To set the stage, recall Anthropic’s recent blog post where they detailed “distillation attacks” made by 3 Chinese labs.
These labs used a technique called “distillation,” which involves training a less capable model on the outputs of a stronger one. Distillation is a widely used and legitimate training method. For example, frontier AI labs routinely distill their own models to create smaller, cheaper versions for their customers. But distillation can also be used for illicit purposes: competitors can use it to acquire powerful capabilities from other labs in a fraction of the time, and at a fraction of the cost, that it would take to develop them independently.
This is a clever paragraph, where they normalize distillation generally and explain how a few people can use it illicitly, without detailing how illicit use often involves other more explicit behavior like jailbreaking, hacking, or identity spoofing of the API.
Distillation itself is an industry standard. It’s used extensively, primarily in post-training, by smaller players to create specialized or smaller models. In my book coming this summer, I describe it as follows:
The term distillation has been the most powerful form of discussion around the role of synthetic data in language models. Distillation as a term comes from a technical definition of teacher-student knowledge distillation from the deep learning literature.
Distillation colloquially refers to using the outputs from a stronger model to train a smaller model.
In post-training, this general notion of distillation takes two common forms:
As a data engine to use across wide swaths of the post-training process: Completions for instructions, preference data (or Constitutional AI), or verification for RL.
To transfer specific skills from a stronger model to a weaker model, which is often done for specific skills such as mathematical reasoning or coding.
With this definition, it’s easy to see how distillation takes many forms. Of course, if you just take the outputs from GPT-5.5 and train a recent open-weight base model with them to host a competitive product, that’s one thing. But, a lot of the things that fall under the bucket of distillation are complex, multi-stage processes that muddle the exact impact of the model you distilled from.
Modern LLM processes could look like using a GPT API to build an initial batch of synthetic data to build a specialized small data-processing model. A good example is a model like olmOCR (or many other models in this category) that are trained to convert PDFs to clean text. This specialized model would be used to create large amounts of data. Finally, you train another model (often from scratch) with the new data you created. Is this final model distilled from GPT?
When done via a closed, API-based model, distillation sits in the grey area of the terms of service that you agree to when signing up to the Claude or GPT platform. They generally forbid the use of the API to create competing language model products, but this term has largely gone unenforced. The open-source community used to worry deeply at being cut off from these cutting-edge APIs for doing research or creating public datasets, but to date only one prominent case of corporate accounts being restricted exists (at least until the recent Chinese companies).
This is all to say that distillation is an industry standard technique, and the use of closed APIs to perform distillation has always been a grey area. Nvidia’s latest Nemotron models, as one of the only models with open post-training datasets, are technically in large part distilled from Chinese, open-weight models. The Olmo models we’ve built at Ai2 are distilled from a mix of open and closed models. This grey area was brought to the forefront again when it turned out that xAI has been distilling from OpenAI. Quoting from the recent trial proceedings between Elon and OpenAI:
OpenAI’s counsel asked Musk whether xAI has ever “distilled” technology from OpenAI.
Musk: “Generally AI companies distill other AI companies.”
“Is that a yes?” Savitt asked.
Musk: “Partly.”
xAI is likely the largest, and most successful AI company willing to thread the grey area that is distillation from their competitors. On the other side, the majority of startups and research groups with fewer resources than them have very likely engaged in distillation of some capacity from Claude, GPT, or Gemini models.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
In the above Anthropic blog post, the problem with the distillation attacks by a few Chinese labs is less the distillation and more the means of attack. It is documented that Chinese labs are actively working to get around the intended use of the API, e.g. to provide additional reasoning data that is very useful for training.
Of course no one should be able to access information from a model that a developer didn’t intend to reveal in their APIs (e.g., reasoning traces which would be helpful for training). Associating all of distillation with these attacks, which is to date an industry standard for post-training, from open and closed models alike will be a massive own goal.
What these few labs are doing should be referred to as jailbreaking or abuse, rather than distillation.
The discourse around these actions is creating a troubling discussion that’s marching towards a mix of regulatory capture or regulatory exuberance that’s most likely to harm the U.S.’s ecosystem more than China’s. Even if we ban, most likely through potential legal action and other penalties, this type of API abuse, the Chinese companies will likely still do it. We’ve seen this playbook with Chinese multimedia models taking a flexible view of copyrighted content that no U.S. player is willing to take the risk on.
This distillation discussion has quickly snowballed, with a bill moving out of a committee in Congress, an executive order pushing for action, and congressional oversight targeting U.S. companies building on Chinese models (which are downstream of distillation). This multi-pronged regulatory environment could yield truly horrible outcomes – such as figuring out a way to effectively ban open-weight models in the U.S. that are built in China by groups abusing closed LLM APIs.
It is obvious that no bill will literally ban open models, but they can create grey area that exposes entities to unwanted risk or require certain provisions that are bureaucratically very challenging to fulfill, squashing small open source contributors.
In that scenario, the groups who lose are Western academics and smaller companies building models for the long-tail of AI uses. The ecosystem here could be made permanently irrelevant with the removal of nearly all Chinese open-weight models. There is no immediate substitute and building new models with meaningful community adoption has a lead time measured in 6+ months. In the time it takes to build a new domestic open-source ecosystem, countless researchers would’ve moved onto closed training platforms or into new areas.
Altogether, I’m hoping this flurry of discussion around distillation becomes a nothing-burger and not a hasty, multi-pronged policy push. We need to avoid two things:
A wholesale negative connotation of the word distillation, which is used extensively across the AI ecosystem.
A domestic ban of the open-weight models built by organizations engaged in some portion of distillation.
In addition to this, I want the leading U.S. AI companies to be able to provide their APIs without having their IP leak. They should share more information on why it is hard for them to secure their APIs, but that’s an issue out of scope for my expertise.
I’ll conclude with a proposal from my friend Kevin Xu at Interconnected Capital (and great Substack) on why this current distillation dynamic may actually be good for the leading labs.
If all the Chinese companies are addicted to distillation as a way of getting close to the frontier, then they’ll never actually learn the techniques needed to take an outright lead. If we cut off the Chinese’s obvious crutch in model building, we’ll gain a short-term lead in AI, but in the long-term that may be what they needed to get on a more competitive long-term trajectory.
This is the same debate we’re having with other technologies where the U.S. currently has a lead, e.g. with advanced semiconductor technologies. So I understand the trade-offs, but we not should crack down on all of distillation.
It’s a clear, current equilibrium that open models will be in perpetual catch-up of closed models, but this gap being viewed as a single number, a “distance”, covers up a nuanced and crucial dynamic at what capabilities the models are covering. The most popular benchmark to comment on this gap is the Artificial Analysis Intelligence Index — a composite benchmark of ~10 sub-evals that they maintain over time to capture the “frontier” of current language model capabilities.
Particularly, I spend a lot of time understanding how dynamics that feed into that index are misunderstood by the natural tendency to reduce performance and trends to one number. Examples include:
How benchmarks evolve over time, becoming more or less correlated with how people actually use models,
How different models’ real-world performance relates to their benchmark rankings, and
How training regimes evolve over time to move said benchmarks.
Agentic benchmarks are in a decent place, but benchmarks are no longer as trusted as a correlate to real-world performance. A key example to this gray area is Gemini 3’s incredible benchmarks and remarkable irrelevance in where AI tools currently are being tested and deployed (agents). These trends point to obvious and lasting flaws in our measurements.
At the root of this dynamic — the dance of correlating model real-world performance and benchmark scores — is the constant shift of the industry. As all the models, i.e. both open and closed, evolve over time, the topics of focus for benchmarking shifts about every 12 to 18 months. All of the domains of interest have very different training domains associated with them, especially in post-training. The longer a single paradigm goes on, the better the industry gets at measuring performance. In a new era of rapid post-training improvements, I’m at a relative minimum in my personal confidence in benchmarks.
Task evolution and LLM paradigms
Right after ChatGPT the focus was a mix of chat, math, and simple code. Instruction tuning and RLHF dominated. Chat capabilities saturated and faded quickly, then mathematics became less focal. Through 2025 and to today, especially once reasoning models became the default, the focus shifted to more complex coding and other simpler agentic tasks. We’re at the tail end of this first era. Recent training recipes are all dominated by reinforcement learning with verifiable rewards (RLVR), but the domains it is applied in have shifted dramatically from basic question-answer checking to complex environments.
What we’re seeing is that the closed, frontier labs are investing astounding sums of money in mastering these current foci — i.e. code, terminal tasks, etc. — while starting to push into more diverse knowledge work tasks. These newer tasks encompass specialized domains, such as accounting, law, healthcare, etc. They are still agentic, but require more expertise and often integrations with existing software or domain-specific tools.
We have very limited evidence on the true balance of capabilities of these newer domains, but these are the areas I’m focusing on when I say open models will struggle to keep up. The problem is that evaluating complex language model workflows is also a challenging research problem in itself.
The tasks are getting harder and the data needed to hillclimb on them is getting more private (relative to code, which has swaths of code on GitHub). Leading open model labs are helped by dynamics happening in the data industry that are economically similar to building chip fabs. The few, leading labs in the U.S. pay astronomical sums to buy new environments and datasets, then the fast-following labs (often in China), buy these later at a steep discount.
This is a key missed point — that the levers non-frontier labs pull to keep up constantly shift over time. A focus on distillation as the key lever to Chinese models’ progress reflects a blind-spot to the importance of RL environments to current training regimes. If an environment can be built either as a single evaluation in the Artificial Analysis Index, or to mirror it, currently the Chinese labs will be able to keep up.
Interconnects AI is a reader-supported publication. Consider becoming a subscriber.
Economic pressure to reinvent “the frontier”
The question worth dwelling on is: How crucial is the current set of tasks (again, coding and terminal tasks), where the likes of OpenAI and Anthropic have a massive business-adoption advantage over leading open weight models (and even Google alike), is crucial to maintaining revenue numbers? In order to maintain these record growth numbers and trajectories, there needs to keep being a meaningful edge in performance. Many companies would love to reduce their token expenditure cost if they can swap in a far cheaper, open model equivalent.
If agentic coding abilities saturate and the “frontier” of AI performance moves elsewhere, a large amount of the enterprise revenue could be reliant on well-formed customer relationships, inertia, and better product development, rather than the models being leaps and bounds better.
This precarious position is what I describe as the frontier labs needing to constantly reinvent themselves, and the field’s prospects, for monetizing the vast buildout of AI infrastructure. I still tend to fall on the side that the buildout will be worth it, and Anthropic and OpenAI will be astronomically profitable businesses, so I take this as a faith of a mix of them continuing to unlock compelling, new, valuable use-cases for the models, and that the benchmarks the open models are closing in on as not being a complete signal.
I operate with a sort of presumption where the leading open models from China are focused slightly more on benchmarks than the leading closed labs in the U.S. They’re incentivized to do so — they want to present the image as constantly being on the heels of the best closed models. Saying the Chinese labs are only in this narrative because they’re overfitting to benchmarks would be incredibly naive and incorrect. They’re genuinely strong models, and these dynamics of overselling and real innovation are a fine balance.
There are a few out-of-distribution benchmarks where open-weight models are very far behind, such as WeirdML or ARC AGI 2, but there are countless random benchmarks that show these open models as being unexpectedly strong. When you use the models, you can pick up on this lack of robustness (e.g. in long-context capabilities, and needing to reset your agent context more often than Claude/Codex), but they’re not a category error in the sense that they’re fundamentally different classes of models. They’re far closer than many would’ve expected.
We’re living through the period of time when we’ll learn if open models can keep up with closed labs. The obvious answer is that no, they won’t. This answer is a form of saying they won’t keep up in every area. This framing closes off a popular prediction where the open models completely catch up, as in all models saturate and open and closed models only become increasingly similar. In living through this, it’s evidently very unclear when the longer-term stable balance of capabilities will solidify.
This is a very complex dynamic, where the core point we monitor is a capability gap between models. At the same time, this gap is intertwined with evolving dynamics in the funding of open models, who builds open models, how techniques like distillation that enable fast-following translate through new application domains, potential regulation hampering the open-source AI ecosystem, and of course who actually uses open models.
The capabilities gap is one signal in a complex sea of forces, pushing supply and demand into different shapes. In many cases the demand — where obviously tons of individuals, organizations, and sovereigns want, or need, open models — is largely separated from supply. Supply is fully dictated by economics. The question of “which business strategies support releasing open models” is still at stake.
Interconnects AI is a reader-supported publication. To receive new posts and support my work, consider becoming a subscriber.
With this complexity, I wanted to distill my key beliefs down into a clear list. These are downstream of 10+ pieces I’ve written or recorded on open models this spring (which are linked throughout).
It’s surprising that the top closed models did not show a growing capability margin over open models, based on compute differences for training and research, especially in the second half of 2025 and through today.
Open model labs are technically very strong at keeping pace on well-established benchmarks. This will continue and reflects a balance of abundant talent and sufficient computing power.
Chinese open-weight labs focus slightly more on benchmark scores than comparable closed labs in the U.S. Distillation helps the Chinese LLM companies do so, but it’s not a panacea. Changes in the distillation dynamic (e.g. regulation) will not be a determining factor on the balance of capabilities. This increase in focus is a natural evolution of their incentives in keeping the narrative on keeping up with the frontier alive, which is crucial to fundraising and adoption.
To date, closed models tend to be more robust and generally useful than similarly scoring open models. Closed models have certain hard-to-measure qualities that are not well captured in current or past benchmarks. This will be key to enabling closed models to dominate in markets where an individual user constantly presents new challenges, i.e. supporting knowledge workers as a direct assistant.
The open vs. closed model race, as monitored through benchmarks, will largely be a game of economic staying power and fast-following, until the market structure constricts. I expect Chinese open-weight labs to face funding difficulties first, as soon as later this year. Funding difficulties will be seen in different capability trajectories 3-9 months later.
The RL dominated training era has increased the relevance of distribution to real-world use-cases as a key factor in continued capabilities improvements. These are tasks where users directly use tools like Claude Code or Codex to solve problems in their job with agents. This is the first clear technical area that closed labs can dominate open-weight models on capabilities, potentially leveraging online RL directly based on user feedback.
Open models will be increasingly adopted in repetitive automation tasks, as measured in the relative share of the API market, for repetitive tasks across the ecosystem. This takes the form of many new AI-native applications, business backend automation, etc. The success of this will drive more investment in domain-specific, efficient open models.
This is a complex picture, where the long-term trajectory is more of an economics question rather than an ability one. Many other outlets can paint a far more simplistic narrative that “China will assuredly catch us in AI” and get more distribution because it is a simple story. The reality is complex. Only real AI revenue begets more investment, eventually that’ll be linked to the ability to keep improving models at a rapid rate. Economic realities have not yet impacted scaling open models, as a general category.
This economic-focused angle relates to my positions on the open model ecosystem more broadly.
Recurring calls to ban certain types of open models will continue to come but are in practice impossible to implement. Training strong AI models (i.e. near but not at the frontier) is a relatively small cost compared to large-scale deployments. E.g. if the U.S. bans open models over a certain compute threshold, another sovereign entity will eventually train them and release them publicly, with the models entering the U.S. market with less oversight.
The second derivative of influence on open models has shifted, and the U.S. will slowly regain ground in adoption metrics of open models starting in early 2027 (it takes a long time for China’s velocity to slow, then flip). Examples include Google’s Gemma 4 (a wild success), Nvidia’s Nemotron, and Arcee AI.
As ever-stronger closed models are built, previewed, and released, there will be more safety-shocks saying that open-weight versions of the strongest AI models never can be allowed to exist, similar to reactions to Claude Mythos. These can spur burdensome regulation on open models.
With the above, there will also be increased long-term interest in open models, as sovereign entities and existing power structures realize the coming, super powerful AI tools cannot land in the hands of only one or a few companies. These entities will see open models as a different governance paradigm.
Local agents, OpenClaw, and other personal agents represent a large, to date, mostly ignored market for open model usage. It is a sort of dark matter, with pervasive, massive potential for influence on the balance of open-to-closed models.
A single word governs this post and is intentionally repeated — complex.
This complex reality has been driving me to think more deeply about how to clearly describe the open model gap, and why I can hold it in my head that I expect American closed labs to clearly draw ahead, despite the fairly unequivocal evidence in support of the capabilities of recent open-weight models. More on the nuance in the open-closed gap in another piece coming soon, so please subscribe!
This post is a roundup of my recent efforts that did not warrant a standalone Interconnects post, why I’m spending time on them, and what they accomplished.
To accompany The ATOM Project memo, arguably a manifesto, making the case for investment in open models in the U.S. – originally launched in August 2025 – we’ve released an updated technical report with our latest data, analysis, and storytelling within the open language model ecosystem. The ATOM Report is dense with the methods Florian and I use to keep track of the open ecosystem. It covers GPT-OSS’s rise, inference market share, the influence of China’s mid-tier players like Moonshot, Z.ai, & MiniMax, signs of the U.S.’s progress on open models, and much more.
In particular, the paper details our updates to the Relative Adoption Metric (RAM), which we use to evaluate the adoption of recent models in a time-varying and size-normalized manner. Here’s a sampling of recent, primarily Chinese, models on the RAM score. The RAM score is designed so that a score >1 indicates a model is, at that point in time, on track to be a top 10 most downloaded model of its size category, ever. It reduces a messy landscape to one, easily interpretable number!
We used the data to also analyze the recent Gemma 4 release, which is showing incredible early adoption numbers. We’ll stay tuned on it!
The goal of this book was to write the book I wished I had when I was getting started in post-training language models. This project has been on my mind for a long time. I bought the domain rlhfbook.com and started to take it more seriously on May 20th, 2024. Here we are!
Last week, it was sent to production with the Manning team. This means content edits are done, and it’ll be sent to print in ~2 months. In the meantime, I’m spending my time developing the accompanying code and course (more on that below).
You can preorder on Amazon or Manning (currently cheaper).
The goal of my book is for it to be the central resource for people looking to transition from beginner to expert in post-training. It’s not necessarily an entry-level book, but as AI models become stronger, it needs to be a community-building effort as well. The first step I’ve made to expand the scope from just a book to a complete learning experience is building a lecture series. The lectures will be freely available on YouTube and incorporate community questions & answers (as standalone videos in between lectures).
You can watch the first batch of videos below, and subscribe on YouTube for future ones. I’m going to build on the book platform more this summer, as I develop the book codebases and host in-person events.
Long-time followers of Interconnects know that this blog has its roots in explaining fundamental research in the field. This has immense value in two ways. First, as AI moves incredibly fast, far more people need to be able to parse research to make the right bets on the technology. Research is the only early warning of some big changes coming. Second, it helps uplift the careers of my collaborators – the people I spend my life with! On that note, check out two papers I had the privilege of being part of below.
https://arxiv.org/abs/2603.16759 - TurnWise: The Gap between Single- and Multi-turn Language Model Capabilities,Graf et al. 2026
This work explores the strengths of various models in multi-turn dialogue settings, how to create training data to improve it, and other quirks in post-training. My interests here have fully shifted to agents, where I see multi-turn interactions as a very important user interface problem — what information do I show to the user to solve the task as soon as possible without cutting corners?
This paper frames solving hard problems with RLVR as a meta-learning problem, where context from previous attempts should be used to inform future rollouts. It’s a very obvious idea in some ways, where most of RL for LLMs is still very on-policy, but naive. The models learn from recent trials in parameters, but not in context. This research feeds into a ton of other recent work on ways that RL can be formulated to solve different forms of continual learning. Another great related paper is Learning to Discover at Test Time.
I’m off to China (and then hopefully DC) in the next couple of months to learn even more about how the world sees progress in AI. I’m excited to talk to a broader range of people than I tend to in my focused technical job. Thanks for reading, as always!
Recently, I was talking with Percy Liang, Stanford professor and lead of the Marin project (another fully-open model lab), and it set in on me that there will eventually be a consortium of companies funding a foundational set of open models used across industry. It’s not clear when this’ll emerge, and Nemotron (Coalition) is Nvidia’s attempt to bankroll and bootstrap this approach within a single wealthy company, but a consortium is the only long-term stable path to well-funded, near-frontier open models.
In recent months, we’ve seen a lot of turnover in openmodel labs, with high-profile departures at Qwen and Ai2 (my comment). This shouldn’t be super surprising to followers of the ecosystem — it’s happened before with Meta shifting its focus away from Llama, and it’ll only happen more as the cost of trying to keep pace at the frontier of AI only increases. The other leading labs with models available today include Chinese startups such as Moonshot AI, MiniMax, and Z.ai — all of which look precarious on their ability to fund continued growth in the cost of training or R&D. Releasing one’s strongest models openly today is in active tension with the option of spending focus and resources on AI products that can currently generate meaningful revenue (and profits).
We’re going to see business models emerge around releasing some, or even many, models openly, but these will largely be smaller models that enable a long-tail of functionality, rather than models at the absolute frontier. This class of companies that’ll release many, strong fine-tunable models will include the likes of Arcee AI, Thinking Machines, OpenAI, Google with Gemma, and more in that class. The cost and relative advantage of keeping the best models closed in a business environment with many opportunities for revenue are too high. To summarize — there will be an ever increasing number of companies releasing models that are good for creating a lively niche of smaller, custom models, but an ever decreasing number of companies willing to release fully open, near-frontier models.
This is the core thesis of why I’m pushing hard for more people to do more research on how these smaller models can complement the best closed agents, the science of finetunability, etc. See my post below — it’s about creating a sustainable open model ecosystem, whether or not the frontier of open keeps paced with closed:
It’ll take years for this equilibrium to become more obvious, seen through the lens of more open model families coming and going. This year, it seems likely we’ll see Nvidia’s Nemotron reach new heights, Reflection AI challenge some of the Chinese models with a strong, large MoE, maybe Meta releases a new open-weight model, and so on. True pressure to change strategy will only come when the capital environment punishes the less efficient spend on resources (e.g. giving away your competitive advantage, in having an in-house model). This pressure will likely hit Chinese startups training these models first.
All of Moonshot AI, MiniMax, and Zhipu AI will show signs of financial challenge in the coming years if they retain their strategy, on top of their models falling further behind the best open models in terms of generality. This is inevitable pressure to evolve open models to areas that are profitable and complementary of the frontier of AI.
Nvidia, which is best positioned to support the open ecosystem in the near term to support its core GPU business, could face many pressures to pull back its open model efforts. It could:
Realize it’s too competitive to their biggest customers as they succeed too much with Nemotron,
Fall to competition on their core business and lose the free cash flow buffer needed to fund this (e.g. it’s 2031 and OpenAI, Anthropic, Google, and the other frontier labs are worth so much they build their own chips).1
Start succeeding beyond their initial goals and keep the chips for them to build ASI themselves, as a closed-weight model.
The pressures for new funding mechanisms for open models are based on the assumptions of continued, substantive progress on the capabilities of frontier models. Mechanisms such as self-improvement and scaling all stages of the training pipeline are underway. This progress of capabilities will only increase the potential profit in selling models as and in products, not giving them away. The scale of investment required has already begun to push away non-profits from the game of making truly frontier-scale models.2 Capitalism is designed to make companies ruthless and chase down leads on profitability, not donate technology as charity.
As the economic environment shifts companies away from releasing the strongest models openly, more companies that rely on these models will look for an outlet of securing model access into the future. This is going to be compounded by a growing group of companies who come to rely on open-weight models for their workflows.
These points loop back into how model training is getting more expensive, so where desire to have the models will go up, ability to procure them will go down for many players. There are x-factors that could multiply the demand for institutions to ensure the existence of open models, such as the best frontier models not even being available via API (such as if Claude Mythos never goes general access).
As training relevant models is shifting to cost billions of dollars, rather than millions, few companies well be able to afford it. many companies will bite at the cost of paying 1/10th of the cost to train a frontier model, or if the consortium works, 1/50th. The upside for companies will be some mechanism to steer development (e.g. model sizes) or getting early access to develop internal and open-source tooling for the model.
It is in my nature to, by default, say this idea will fail, as training models is inherently a complex and high-focus endeavor, one that requires integration of every part of the stack and focusing specifically on your own vision and needs, rather than trying to serve every possible user. Eventually the need for open intelligence — and economic pressure to build it — will make a model consortium inevitable.
There’s a meaningful chance in my estimates that Anthropic, OpenAI, and Google are the most valuable companies in the world in the 2030s by owning frontier intelligence.
Truly open is a prospect for safety research and long-term innovation, which suits both the narratives of AI risk and AI optimism. We need it for both. Mech interp is one of the heaviest users of Olmo models. If we don’t find what’s after the transformer, there may not be enough benefit to AI models. (edit, I had published that as a half baked thought, it’s about how fully-open models operate in the ecosystem differently) All of these are largely orthogonal to the point of the post.

 Login