In 2025, seven-month-old startup Axiom solved all 12 of the problems Putnam exam (scoring 8/12 in the time limit) a prestigious undergraduate math exam. The 12/12 score is better than the top undergraduates (110/120) and the closest AI system that reported a result (DeepSeek 103/120), although it is unclear what the people and other systems would have scored with more time. Nonetheless, the Putnam exam is legendary for its difficulty, with the median score typically being 0 or 1 points. Taken by itself, this seems like a minor feather in the cap of AI; one of a long series of accomplishments by AI systems in elite competitions with humans, starting with Deep Blue beating Kasparov.
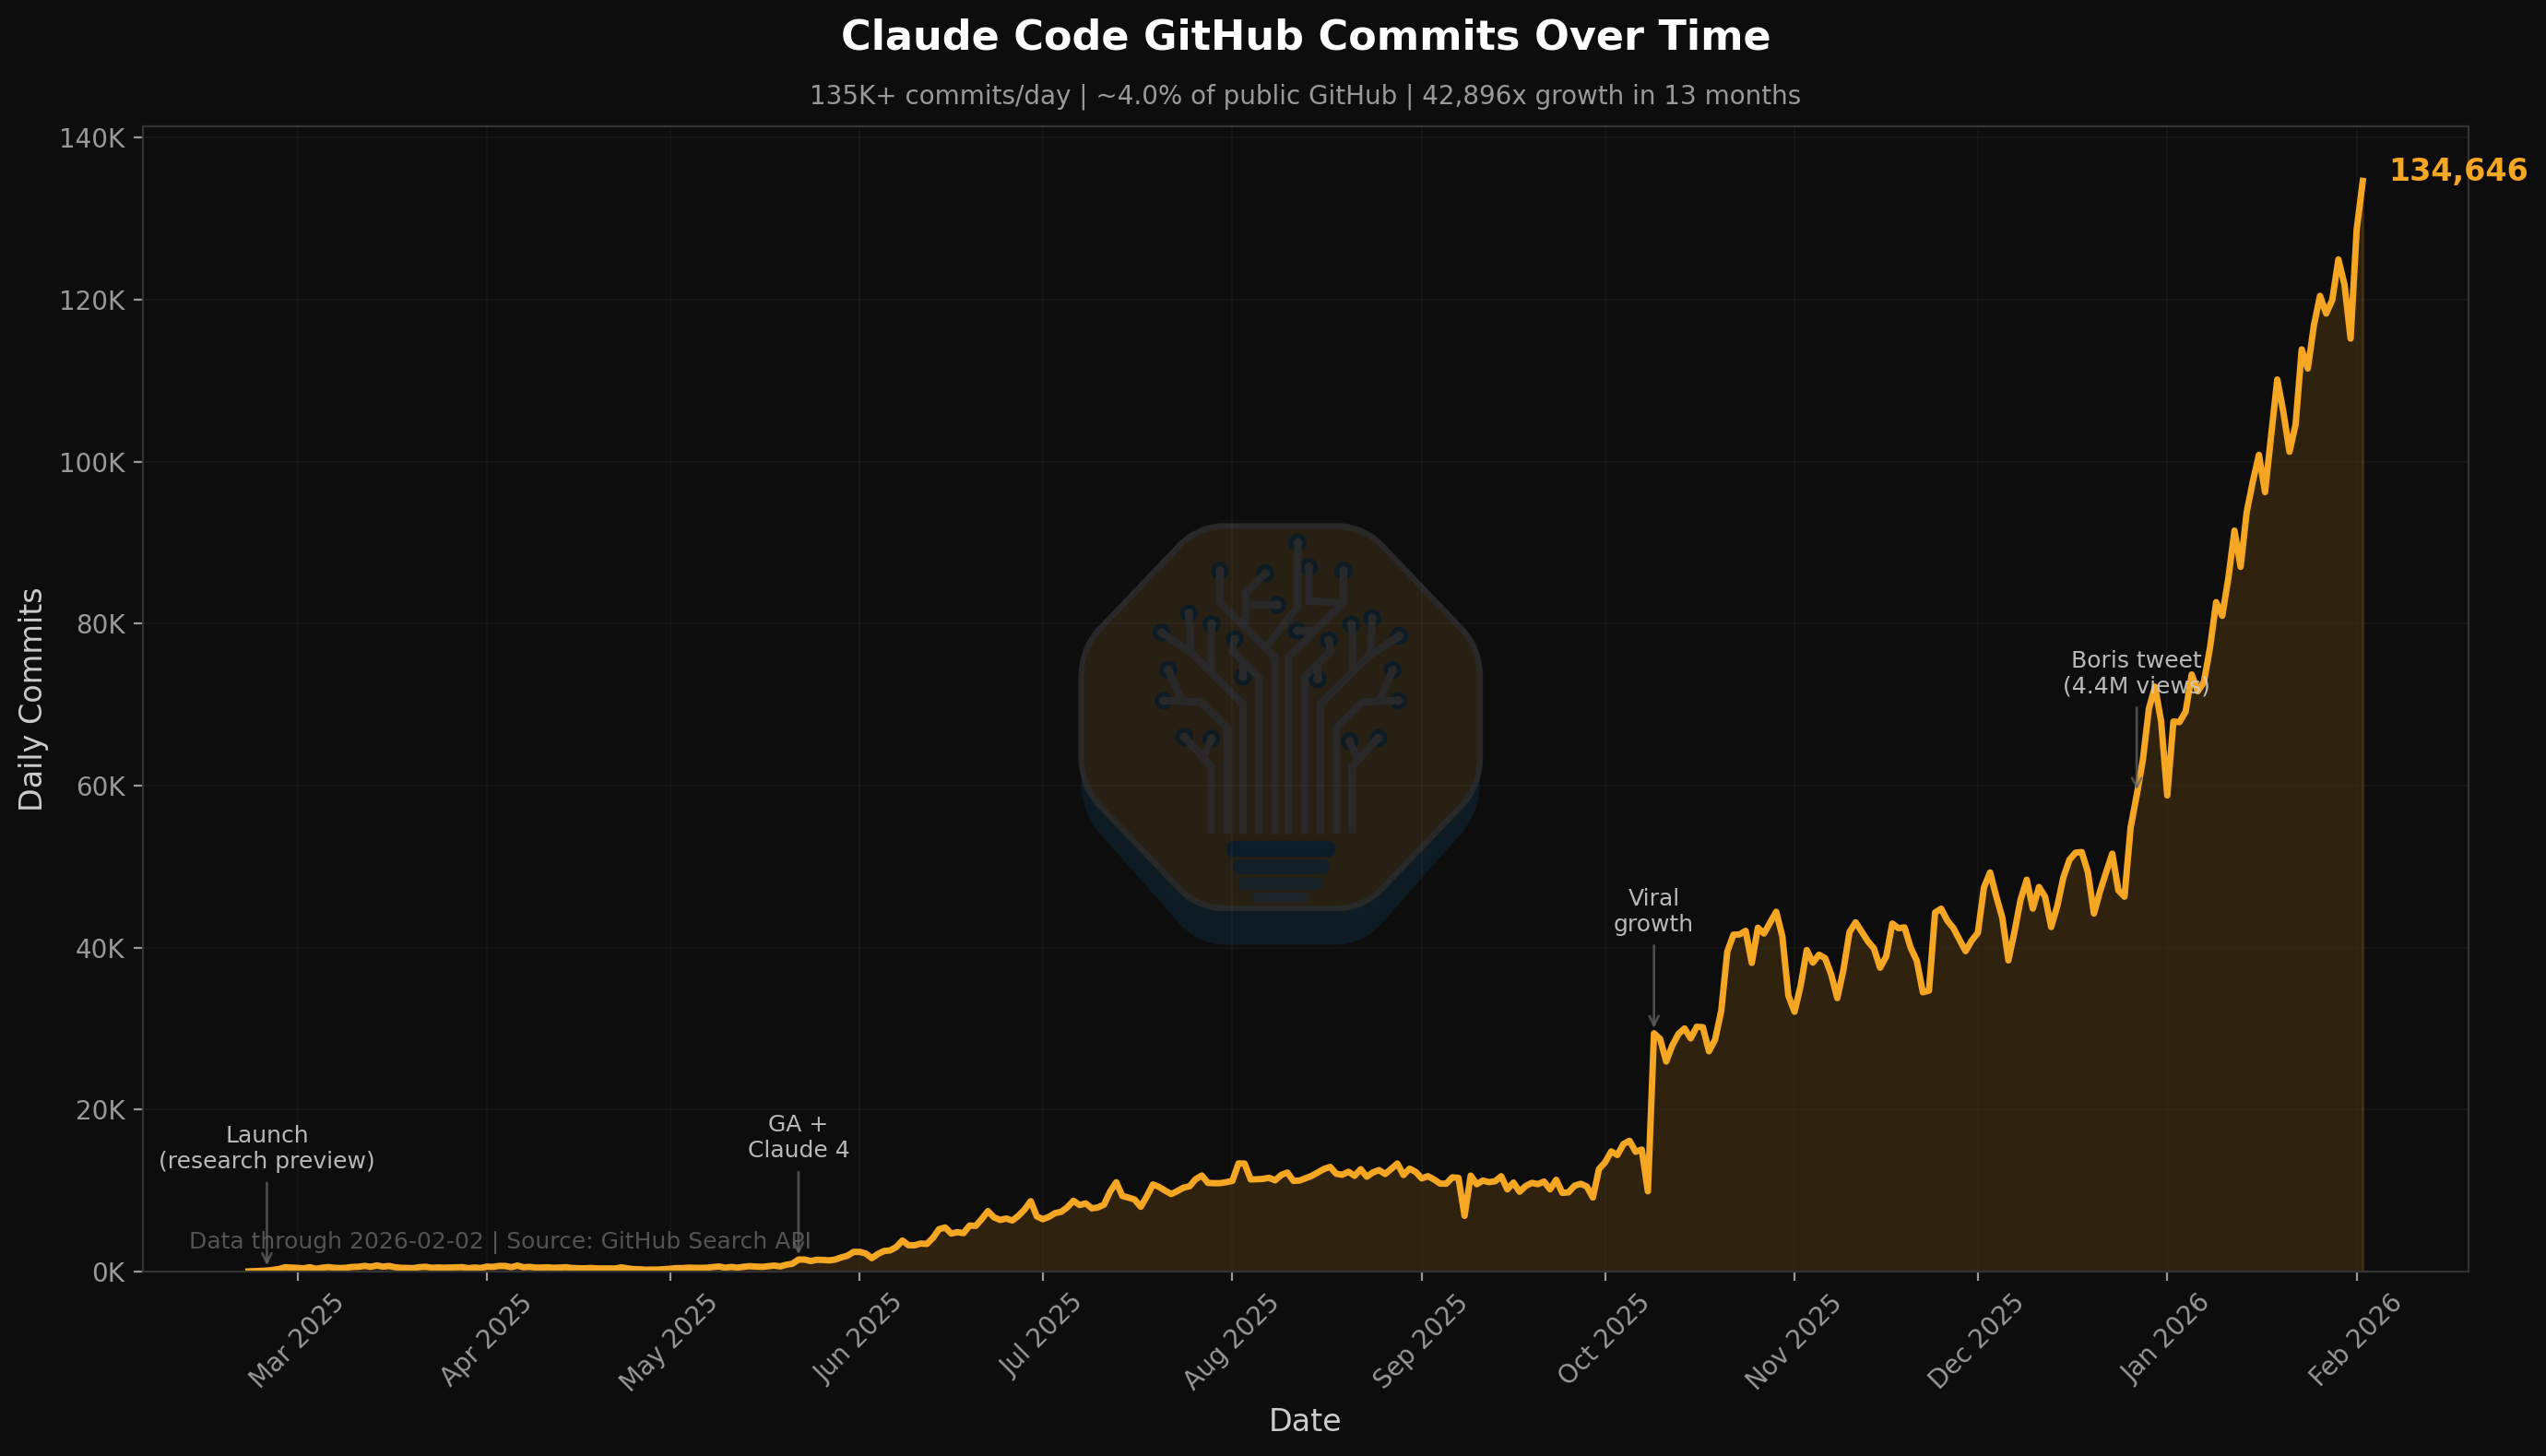
Fast forward to mid-2026, and Claude Code and Codex are setting the world on fire. In 2024 Anthropic’s bet on code and enterprise looked like a more pragmatic niche play vs. OpenAI’s better models and massive consume scale. Today, Amodei’s all in bet on acceleration via code (images and video be damned) seems prescient.
Despite Anthropic’s growing momentum, however, Axiom CEO Carina Hong sees coding ability as a necessary but not sufficient milestone on the path to AGI. Code arguably pushes the jagged frontier to the point of super intelligence in some domains outside of coding, but there are surprising gaps (link) that Carina believes will bottleneck AI progress. (Stats on math benchmarks).
The informal bottleneck
“Verified AI” sounds like eating broccoli1 and paying taxes, but to Axiom it means something very different. “Verification to me is about scaling brilliance, compounding brilliance,” Carina told us.
It actually took a while for me to understand what she means by this (sounded like marketing-speak until it clicked). Carina brings up the legendary mathematician Srinivasa Ramanujan (“The Man who knew Infinity”) to illustrate this point. When G.H. Hardy finally persuaded Ramanujan to formally prove theorems instead of relying on his (formidable) intuition, it reportedly improved his own capabilities. This is presumably because formally proving things forced Ramanujan to articulate the details in a way that open up new lines of thinking, etc. This is how you “compound” in math — building on solid rather than shaky foundations… also known as Axioms.
But formally proving things also allowed others to benefit from his intuition: the proofs are way of communicating an intuition and persuading others that the intuition is correct. This is scaling (more people use the result) and compounding (people can learn from and build on his work).
This is the core insight that lets us understand the approach Axiom is taking.
Verified Generation
There are two ways that Verified AI shows up: in training and in inference.
But a quick detour: to a first approximation, “Formal Verification” means using type checkers (like for TypeScript, C++ or Rust, but more capable) to verify mathematical proofs that are meticulously specified using a language like Lean2. It takes a lot of work to translate an “informal” proof (albeit one that most people would not remotely call “informal”) in to a Lean proof3. Axiom themselves have open sourced groundbreaking work with AXLE - their toolkit of interactive Lean applications for exploring, validating, and manipulating mathematical proofs.
You can imagine how this would be (very) useful during Reinforcement Learning: instead of relying on best guesses based on statistics (GRPO, RLHF, etc.), you can just verify the proof is correct using a Lean verifier. This is obviously a much stronger reward signal, akin to compiling code and testing it (which is what is typically done with RL on coding).
The catch: LLM are not (currently) very good at proving things with Lean.
Enter Axiom: While they have not officially reported benchmark numbers besides the 12/12 Putnam result, Carina reports that they have achieved a very impressive 99% (187/189) ProofGen on the Verina codegen benchmark. This benchmark is to generate code and proof of correctness for a series of problems. For context, OpenAI o3 (the last known OpenAI run) achieved 4.9% on this benchmark.
Based on the sparse benchmarking, it’s hard to say how the frontier labs are currently doing outside the annual IMO milestones, but Carina suggests that they still are not training to generate Lean proofs directly, rather relying on informal proofs.
Time will tell if the frontier labs’ current approaches will close this gap.
Scaling and compounding
Carina’s Ramanujan analogy is pretty direct. Better proofs → better Lean generation → better RL. A stronger signal means higher sample efficiency and higher maximum performance. Great!
Scaling is pretty clear too: once I have proved something in Lean, the quality of the output is basically4 as high as if it came from a human, so my high quality training set has grown in a way that an informal rollout corpus cannot. I can trust my Lean proofs.
Compounding is also clear: now all of future inference and training can build upon those proofs.
On the other hand, a model trained only using statistical signals like GRPO during RL lacks the sample efficiency, maximum performance and compounding corpus that a system that uses formal verification benefits from.
All roads lead to verification
Broccoli and taxes notwithstanding, verification has shown up in a lot of our conversations. In the domain of physical systems, recall Applied Intuition:
“I think [verifiability] is probably the hardest problem right now, because the as the models get better, it can be harder and harder to find the faults on the system. And so the problem of doing proper eval to find those faults, that problem also keeps getting harder as the models get better.”
In theoretical physics, we recall Alex Lupsasca:
“…now that we’re in this regime where you can just get ChatGPT to tackle thousands of questions at the same time, it will return proofs for a significant fraction of them. Now actually the onus is back on the humans to verify all the outputs. And so, yeah, as that becomes a bottleneck, I think formalizing math and automating verification will become more valuable.”
Verification is, in fact, the key differences between AI for science and AI for computation: in science you to have to actually test (verify) your hypothesis by performing physical experiments. Lab in the loop systems like Radical AI and Lila build around exactly this premise (we have recorded episodes with both of these teams and will release them soon!)
And yes, formally verifying critical systems such as flight control, nuclear power plants and pacemakers is a growing focus as the software and hardware that run them becomes more complex.
Carina believes so strongly that AGI requires verified generation that she makes the unqualified claim that “We do not believe there is any other possible future.”
Expensive to produce, cheap to verify
Lean proofs are hard generate, but they can be easily shown to be correct or incorrect. But how do you know that the proof you created maps correctly to the problem you care about? As Carina puts it: “Anything that can be specified can be proven. Humans are bad at specifying everything we want.”
Are we now in the specification business? Check out the episode to hear Carina’s take, as well as:
Why hardware verification is a killer app
Details on the AXLE open API and recently released Discovery toolkit
The Erdos debacle
The OpenAI GPT-f diaspora
Full Video Podcast
Timestamps:
0:00 Intro: The $200M Series A and the Math Startup Thesis
4:52 Verified AI: Scaling Brilliance, Not Fixing Lousiness
13:42 Axiom’s System: Lean Data, RL, and the Putnam Perfect Score
22:12 Mathematical Discovery — Before the Conjecture
25:12 Rice’s Theorem, Incompleteness, and Practical Limits
30:42 Code With Proof — The Verina Benchmark
37:57 Proof Trees, Context Windows, and Scaling Limits
43:57 Markets, Moat, and the Business Case ($1.6B valuation)
55:27 Personal Origin Story: Oxford, UCL Gatsby, Stanford Law
1:00:57 The Erdos Controversy and the Difficulty of Search
1:06:02 AlphaZero for Math, Self-Improvement
1:08:47 Startup Advantage and the OpenAI GPTF Thread
1:13:17 Axle API — Open Infrastructure for Lean at Scale
1:20:47 Collaboration, Polymath, and Human Attention as the Bottleneck
1:22:21 Founding Story — Obsession, Law School, and Julie Zhuo
1:26:17 The Bigger Vision — AGI, Science, and Transfer Learning
1:35:02 Bottlenecks, Fragmentation, and the Field’s Future
Formal verification also includes model checking (TLA+, SPIN), SMT-based tools (Dafny, F*, Why3), and refinement-type systems (Liquid Haskell) — many of which don’t look much like “type checking a proof” from the user’s perspective even when there’s a similar logical core underneath. It also gets applied to software and hardware correctness, not only pure mathematics.
This is an understatement. Most theorems remain informal because formalization is so hard to do. There has been a great deal of effort to formalize the most important proofs, with mixed results.
We’ve informally heard that Satya is a listener to LS for a couple years now, but it was still absolutely surreal to meet him and do a live pod at Build, together with our friends at No Priors, the leading VC AI Podcast that we also greatly admire!
Satya’s adaptation of the Bill Gates Line for positioning Microsoft as the Frontier Intelligence Platform — customers must gain much more value from the Microsoft ecosystem than Microsoft itself, by building on multi-model harnesses like OpenClaw and Scout, drawing on the full enterprise context exposed by context layers like Work IQ (heavily dogfooded by his C-suite), and building up private evals and traces as a new form of Token IP
AI ROI: On one hand, enterprises are having difficult conversations around Tokenmaxxing and Layoffs, and on the other hand, there are serious re-evaluations of the End of SaaS since the Build vs Buy equation has changed so much. Our previous SemiAnalysis guest had… interesting comments on Microsoft’s position on this as the ur-SaaS titan, and Satya had great answers
Making the Impossible Possible: Kevin Scott’s inspiring framing around what the most ambitious version of applying AI and technology at large to business and social problems, like education and social impact.
Enjoy!
Full Video
Transcript
Voiceover: Welcome swyx, Sarah Guo, Elad Gil,, and Chairman and Chief Executive Officer of Microsoft, Satya Nadella
Sarah Guo: Welcome to a crossover episode of No Priors and Lane Space with Satya Nadella. Um, congratulations on an amazing build. No, thank you so much, and it’s great to be with both of you. I listen to both of you or b- both the podcasts all the time. It’s great to be on it.
Thank you so much. [00:01:00] So you’re just talking about, um, these amazing, uh, announcements from across the Microsoft estate all morning for, I think, three hours. What is the, uh, what’s the most important reflection or takeaway you have?
AI as an Ecosystem Platform
Sarah Guo: I, I’d say there are, uh, perhaps the, the biggest one for me is let’s sort of conceptualize this more as an ecosystem play as opposed to a single model or even a single platform, right?
Satya Nadella: I mean, you know, whatever I... At least for me, having grown up at Microsoft, having seen, whatever, four major platform shifts, uh, I sort of fall into that, um, uh, camp where a platform is defined by fundamentally its ability to create more value about the platform versus what’s captured in the platform. And so if you, you view what’s happening right now, I think this morning’s keynote was how can any company, whether it’s an AI native company or a traditional enterprise company, participate as a first-class participant where they can point to AI they created, [00:02:00] right?
It’s not that they don’t use other people’s AI. Of course they will. But to me, what’s the path? What’s the recipe? How do I do it? What does a stack look like? What does the tooling look like? What is valuable? How do you do that? That’s it. That’s sort of our job to do. Yeah. Ecosystem strategy is, uh, very complicated, right?
Sarah Guo: Because you end up building certain components, partnering for certain components, supporting them. You just announced this big suite of models. Like, tell us a little bit about the, uh, training strategy for Microsoft now. Yeah.
MAI Models & Training Strategy
Sarah Guo: So, so the thing that we wanted to do with the MAI models was to build, and as Mustafa talked about, first of all, a great lineage, right?
Satya Nadella: Starting with pre-training, uh, with very good data quality, uh, doing all the ablations, making sure because in, in some sense it’s becoming even harder to build a clean lineage model just because there’s so much stuff out there, uh, that you truly need to ablate out to be able to have a fantastic [00:03:00] pre-trained model.
In fact, that’s one of the challenges of a lot of the open weight models is they look great on one benchmark or two, but they’re not great on practice. So that’s why, in fact, even in the RFDEs are, they, they are pretty gone really excited about these MAI models because how the heck can a small five B model hill climb?
Uh, and it goes back a little bit to what I think is ultimately the key thing to do, which is try to pursue finding that cognitive core. Uh, so to me, starting with a clean lineage- Then creating that ability for companies to be able to use this, right? Not just as a generalist, but to create their own specialist by building this hill climbing scaffold around it, right?
So it’s not just the model, but you have a hill climb scaffold around it, then you will start building your RLE. You will start collecting the traces. Most importantly, you’ll have private evals because we know all the evals out there are good, interesting, [00:04:00] but they’re not really that critical- They’re work, yeah
Swyx: at this point because they all can be maxed. And so the point is each company will have its own private eval. And so that end-to-end platform story around our models is sort of, uh, what I think is interesting. And then the one other thing, Sarah, since you brought that up, is I do feel there’s a new frontier.
Satya Nadella: Like people talk about the frontier and are you operating at the frontier. Um, interestingly enough, if you add a little temporality to it, you can use, let’s say, in, in, in fact, the, the Lando Lakes demo we showed was pretty cool. We used, whatever, GPT-55, right? Then you collected a bunch of traces, and then you took a 5B reasoning model and achieved higher.
Sarah Guo: Uh, so that is another aspect of what it means to appear... uh, you know, operate at the frontier Yeah. I, I think, uh, I first of all have to congratulate you on basically building a frontier neo lab inside of Microsoft in two years. Um, I’m wondering, you know, you have all this AI strategy that you’re rolling out.
Lessons from Two Years of AI Development
Swyx: I’m wondering, what do you know now that you wish you would tell yourself two years ago where- or two or [00:05:00] three years ago? Three years for the Jensen partnership, two years for, uh, MEI. Yeah, I mean, I think the, the thing when, that I reflect quite a bit, right, which is sort of obviously I got into all this when I got excited by the, the scaling laws paper and, you know, when, you know, even the OpenAI partnership came about when those folks said, “Hey, we’re gonna really throw a lot of computer transformers.”
Satya Nadella: Uh, and they’ve helped. I- the thing that I always look back and say, “Wow, these things, uh, do have capability that they’re climbing up.” W- I mean, this, you know, this crude way of saying it is intelligence is log of compute kind of works. Now what I think we underestimated perhaps is the real-world complexity of deploying these so that they actually deliver the value in the real world, right?
So the outcomes as measured by any benchmark is interestingly important, but the true eval is when people out there are able to do unique things that they only can value, and it’s very [00:06:00] measurable, right? That I wish we had sort of even, like, had more in our consciousness, right? Which is as an industry.
Sarah Guo: Because right now I think when people say, “Wow, I don’t want a token max,” it’s an artifact of us not having thought ourselves as an industry that we are using tokens to create value every step of the way. So I think that’s kind of what I wish we had gotten there, but I’m glad we are here.
Real-World Value & Use Cases
Sarah Guo: What are some of the use cases that you’ve seen that have created the most value for your customers?
Because I know that people talk a lot about code, and I think it’s pretty clear that that’s something that’s having very large scale impact. Are there other areas that you find in common that your customers are really benefiting from? Yeah. I think, yeah, to your point, obviously coding is now got... But it’s interesting, by the way, Elijah, to even talk about the coding, right?
Satya Nadella: Which is coding has worked so well that we now have to rebuild the IDE, right? I mean, it’s kind of nuts to see what we sh- launched is like, oh my God, I have these hundred agent sessions. I... The cognitive load it transfers back to me as a human is so [00:07:00] excessive that now I need a new UI. Uh, oh, by the way, I, like the, the chat as the only artifact was also impossible, so that’s why we need a canvas.
So it’s kind of interesting for all the things about where is software needed or where is UI needed, uh, you kind of need that even for code, right? In a fully agentic world. But that said, one of the things that we are starting to see, we started seeing with co-work, but even some of the work we, we showed with auto com- uh, um, autopilot Right on what you see with claws is a good one because if you sort of think about a lot of human capital is doing the glue work, right?
If you now can augment that with tokens/agents that are long-running, durable, right, then your ability to scale even what is still judgment and glue work gets amplified like coding does. Uh, so you can... Like, I’m positive that six months from now we’ll all be saying, “Oh, wow,” like, all through ni- the night there was a bunch of stuff that [00:08:00] all these autopilots that I have working on my behalf with my delegated authority, so to speak, right?
I can... Sort of given even my identity, did a bunch of work, then of course I’ll need my new ADE to say, “Well, what did you do?” Like, I might... “Did I do this work?” And so on. So I think that that’s where compressing of workflows, uh, completing of tasks, uh, that’s where I think a lot of the value gets created. I think you raised a really interesting point, which is there’s the actual agent that’s doing the code, and then there’s a harness around it, and that’s the environment, that’s the context, that’s everything you’re setting up as a developer around actually a coding agent.
The Harness Concept for Enterprise AI
Sarah Guo: What is the harness for the enterprise? Is there an equivalent concept for broader productivity work, or how do you think about that concept sort of generalized? That’s right. So, so in some sense you kind of want the harness to define the models, the, the data, uh, and the tools, and so that you have a loop across those three.
Satya Nadella: And so what we are trying to, first of all, make sure is each of our products that we build, right, whether it’s GitHub Copilot or the security copi- the, the [00:09:00] stuff we showed with MDASH or even the discovery for science, it doesn’t matter, all of them are multi-model harnesses, um, with tools access so that you can do this progressive, uh, disclosure of tools even so that they’re token efficient.
Uh, and then you’re feeding it with very rich context because that’s sort of the other hard lesson we have learned in the last two years is, oh my God, the amount of work you need to do to prep the context layer, uh, such that your plan can execute in the most efficient way is where the magic is. So we have, in our case, we have the GitHub harness, which essentially we’re using across all our products.
It’s available in Foundry, and we are open, like you can use your Llama harness, whatever. Or you can use the, um, uh, you know, any open harness or any harness of yours and train with your tools and multiple models and your context. And so that’s the pitch. Because right now a lot of dialogue is, um, “Hey, if I train the harness plus tools and the model together, you get [00:10:00] evals.”
Elad Gil: And what we are proving out is... And the best example of that is what we did with MDASH, right? Because when it launched, uh, it found bugs or vulnerabilities that were not found by Mythos Uh, and so there is existence proof, I would claim, that you can have a multimodal harness, uh, that can in fact be more, uh, performant in the real world So a premise behind the, uh, training at the independent frontier labs is really, you know, we’re gonna have these models, and we’ll have an API business, and we’ll support enterprises and startups.
Sarah Guo: But
Platform Strategy & Developer Ecosystem
Sarah Guo: a first-party product, be it productivity or code or search, drives the majority of revenue. That’s a different value equation than you’re describing, I think, with the Microsoft ecosystem. Uh, if, if that’s the case, tell me if it’s the case, uh, ‘cause obviously you have first-party products and you have enablement products.
Satya Nadella: Um, what is the role of the develop- Like what is gonna be hard and the set of skills and the value capture the developer has in that world? Yeah. So I think that there’s always [00:11:00] gonna be the case that someone who is super successful in- as a platform builder can also have first-party products. It was true with Windows.
It is true, uh, with, uh, the, the SaaS side and the cloud side as well with us and others and so on. But the thing that is, is it should not be a limiter to other people achieving that same success, right? That I think is the core difference, which is the, the network effects this time around, around intelligence are such because they learn from data, and not really lots of data.
It’s just a few samples that you have to see to understand what’s novel about something. So that’s why the game becomes how to protect. So that’s why I would say every company, having private evals may be the biggest IP, right? Think about it, like what’s that private eval that you can then use even a frontier model to hill climb on and not leak the traces may be one of the biggest [00:12:00] drivers, uh, of IP.
Like, so in other words, another te- acid test is you have an eval that’s private. You’re using, uh, a g- a Model A. Can you switch it to Model B and e- you know, climb up? If you can, then you’re in control. If you can’t, you’re not in control, and that’s where even the harness decision becomes super important, right?
swyx So therefore, having an open harness, letting all models come in, having your evals, your context, your tools help you hill climb, I think is the skills that an AI native startup needs, a SaaS company needs, or every enterprise needs. Yeah, I think in, in a very real way you are ... Microsoft historically is an operating systems company and th- then become a cloud company.
Maybe like the third act is that you’re a harness or evals company. Whatever w- ... whatever the, the sort of conglomerate of concepts that you wanna put together. Um, and, and I think like enabling every company to have like frontier intelligence or what- what- Yeah ... I forget the, the [00:13:00] exact term that you used, um, is the, is the mission, right?
Satya Nadella: That’s it. Like that is, that is the platform promise, that you build with us, you will get your intelligence, uh, for your data. That’s it. That ... To, to me, that is the ... Like if there was one tagline, uh, for this entire developer conference is- Can everybody operate at the frontier with their frontier intelligence, right?
To me, that is so important because otherwise it, I, I don’t know how you achieve stable equilibrium, right? Which is how do I then go and say, “Well, my company is gonna have a terminal value because I now know how to continuously compound-” Yeah ... on top of what’s a platform that gets better,” right? So when, like Windows obviously came out, Adobe built, Autodesk built, uh, or even like take what Jensen said.
We built DX and he built, you know, CUDA on top of it. Um, right? I mean, I always say to Jensen, “God, I got the short end of that,” right? “I wish, uh, we had recognized it.” But nevertheless, but that, that idea that you can build a platform layer [00:14:00] that someone else can then extend out, um, and build their own intelligence layer in this case, I think is everything, right?
Without it, why have a developer conference? I can just come and have you all sort of just worship at the altar of one model. Yeah. But that’s not a developer conference. Uh,
IP, Evals & Company Value
swyx: backstage we, we had a discussion about what is IP or what is the, the value in a company. It used to be the length of, uh, human experience at a company, and now it’s this other thing which is the evals, the, uh, experience in sort of applying agents to the company. Can you... I just want you to like flesh that out a bit more ‘cause- Yeah ... it was very insightful.
Satya Nadella: It’s a great way to frame it, right? Because yeah, at the end of the day, every company is gonna have both the human capital that is still gonna be super valuable, uh, because humans, uh, and their ability to find the gaps that exist at all times is going to be the way we all will create value, right?
I mean, so I’m definitely in the camp that this is going to be about expressing new forms of human agency and ambition even as token capital goes up, right? So let’s say a cor- any corporation [00:15:00] has lots of tokens and lot of human capital. The question is how do you compound the two? So if you have a... Like if you take in Teams I have a bunch of agents doing work and a bunch of humans doing work, and the traces between those, that is really important context of how that enterprise is creating value.
Then that goes back to train not a generalist model, but to train the company veteran agent, uh, right? That is super valuable again, right? Which is when a company goes says, “It should in fact go onto the balance sheet,” is how I think about it, right? That’s so... In fact, there may be... Like human capital was never possible to go put on a balance sheet, uh, because you didn’t know how to capture the tacit knowledge.
swyx: Whereas now I think you can with the agents that have learned through the h- through, through time, through all the traces. Uh, so that’s what at least we think will happen. I, I think the SEC is gonna have to have accounting standards- ... for token, uh, expertise Uh, y- y- you’re talking about the equilibrium [00:16:00] state, um, and a stable equilibrium where companies have this compounding value and can see terminal value for themselves.
Future of SaaS & Business Models
Sarah Guo: Another challenge to, you know, the considered equilibrium of, okay, there are applications and workflows that are sort of common to a vertical or a horizontal. Um, and this was, like, the generation of SaaS companies and, you know, Microsoft has lots of SaaS properties as well. And then there are things that are very specific to every enterprise that they’re differentiated against.
Elad Gil: Um, I’m sure you have heard much and participate in much of the debate about the end of software because all these workflows are, are cheap to generate now. Um, do you think the equilibrium looks different between what agents get built- Yeah ... in enterprises versus in their vendors in the future? Yeah. So I think what’s happening there is, see, we, we had a particular way we captured, um, I would say workflow in apps, right?
Satya Nadella: Because we built a, a data model, right? We schematized some part of some business process. Mm-hmm. We then built a bunch of business logic. Yep. And then we put a bunch of UI [00:17:00] on top of it, right? So that’s kind of what every SaaS company- And a little configuration. For, like, 20, 20 years that was the plan.
Right, that- Yeah ... and that was it. So interestingly enough, now you kind of get to re-litigate that vertical stacking, right? So I still think, for example, that data model that you built underneath every SaaS application is super good, right? Like, why reinvent it? Like, I, I, my general ledger better be a general ledger.
I don’t need new schema creation. No. Uh, in fact, that entity relationship, uh, is actually pretty good, robust thing that I want to feed. And you want it to be stable. That’s right. Yeah. Then same thing with business logic, right? If, if you look at, uh... We have this product called Power BI, right? It is like dashboards galore people created.
The beauty underneath that dashboard is a very rich semantic model, right? Someone took the pain to create a dashboard and do all the measures, and you want that. That’s business logic, right? I want that to be available to me. So I think the [00:18:00] challenge of the SaaS business model is we packaged one way. We now have to learn how to unbundle these things and rebundle in new ways and discover new business models, right?
I mean, if you look at it, d- what’s happening today with Microsoft 365 is a great example, right? We have this thing called Work IQ. In fact, like, what we are realizing is, oh my God, like, you know, if you look at... In fact, there’s a pa- historical parallel too, right? We sold first Exchange and SharePoint and, uh, you know, before Teams, we had a thing called Lync Server and what have you, and we thought, “Oh, that’s all gonna move to the cloud.”
But little did we realize that, um, the number of people who will use servers in the cloud is 10X, 100X, right? Because people were not buying servers, they were just buying a subscription. Mm-hmm. The same thing is now happening with M365 because with Work IQ, we have exposed what is perhaps the most important database in a company that never got used as a database because it was only captive to our apps.
Mm-hmm. Right? It, it was all email operated on it, Teams operated [00:19:00] on it, Word, Excel, PowerPoint, SharePoint. But now, like this is one of the coo- coolest things I get to do with Work IQ. I go to a GitHub repo and I say, “Hey, I attended a bunch of design meetings last week related to this repo. Can you capture all that and tell me what changes I should make?”
I mean, think about that, right? It literally can go look at all those transcripts, come back with a plan to change a code base, right? Previously, you could never have thought of using M365 for something like that. So the value creation opportunity now in the agent world is in fact 10X more, but it does require us to have...
Sarah Guo: For example, there’s going to be usage around M365, right? Which is going to be perhaps more than even the e- end users and we have to even re-architect. Like, in fact, like what I use to serve an inbox or a mailbox cannot be used to serve an agent. Uh, and so that’s sort of what we are doing.
Pricing Models: Per-User, Consumption & Outcomes
Sarah Guo: I don’t believe in, like, permanent business models for any of these domains, but in the [00:20:00] near term, do you have a prediction between, uh, you know, outcomes-based pricing, token-based pricing?
Elad Gil: Enterprise bundles Yeah. The way I- I think about this is always we’ve had... Like, let’s even take the per-user pricing. Mm-hmm. The per-user pricing is really an artifact of someone creating a budget needing certainty, right? Because it’s the most important thing. Like, somebody wants a budget- Mm-hmm ... they need a per user.
Satya Nadella: And, and per user is just a set of entitlements to usage, right? That’s kind of what it is. And so the way is, if the first bundling will be take some usage, bundle it into per user stacks and, you know, then sell subscriptions. So subscriptions I think are gonna be there, per user is gonna be there. Then the next big thing will be consumption.
So people will say, “I want consumption.” And it’s also possible that people will say, “I don’t even want to pay for any of the subscriptions or the consumption’s outcome.” Mm. But remember, most people love outcomes until they have an outcome, because once you have an outcome, it’s like giving away royalty, [00:21:00] right?
Mm. I mean, like I, I’ve talked to customers who love, you know, outcome-based pricing, and I say, “I’m all in,” until they, “Oh my God,” like, “what are you talking about? You’re sharing in my outcome? No, no, no. I want you to go back to per-user pricing, and I want you to consumption price,” right? So I think that debate will go on.
Uh, but and all, all, all of these business models have a particular time and a place versus one to rule them all. And if anything, if you’re a SaaS vendor or you’re a platform vendor, having that flexibility... And quite frankly, we face this with GitHub, right? We just recently announced a per-user pricing on GitHub because little, you know, we- GitHub Copilot was constructed at a per-user level before we understood even, uh, the intensity of usage of agents, right?
It was an interactive way for a developer to use code complete, maybe tasks. It was not like, oh, I launched 10,000, you know, agents that are going on all day, right? So that is what the adjustment is about. So now that we really want, there will [00:22:00] always be a per user, but there will have to be a consumption meter.
Durability of SaaS & Build vs Buy
Sarah Guo: How do you think about the durability of SaaS more generally? One thing I’ve observed is in a lot of enterprises internally, there will be teams that almost have agent euphoria. They’re so excited about the explosion of things they can build that they’re trying to rebuild a lot of applications or going to their SaaS vendors and saying, “We’re not gonna work with you anymore,” or, “We’re considering an internal project.”
And it seems like in six to nine months, maybe some of those people will come back and say, “Actually, we, we can’t rebuild everything.” How do you think about what’s durable in this world and what isn’t? Yeah, it’s a... It... I think we have to go through one full budget cycle on this to really see the, um- Uh, the sort of the emergence of the equilibrium, because at the end of the day, there’s marginal cost to even generating the app, right?
Elad Gil: In, in fact, there can be even a, a simple way to say it, like if you should always acquire something if the marginal cost of building and maintaining, uh, something on your own is higher. Uh, right? That should be like it’s a quantifiable- Yeah. Right? A quantifiable thing. And [00:23:00] the maintenance part is important, right?
Even, like you got to remember like, hey, you know, all the security stuff that now AI will find, you better fix them too fast. Uh, of course, there’s a coding agent to help you with, but then that burns tokens, right? So whose responsibility is it? It’s kind of like a, a cycle that you’ve got to think through.
And I think we have gone through the excitement that I can generate a lot of software. I think the next thing would be what software do I really want to generate? Mm-hmm. What software do I want to use from others? How do I compose these two into some agentic workflow that I have agency over, right?
Sarah Guo: Because I think there’ll be very little tolerance for anybody who’s inflexible, uh, at the vendor level. Uh, but at the same time, I think that anyone who has got that flexibility shows up, delivers the value, will be back at again, right? We’re selling software, uh, but with just different business models, in fact Uh, speaking about building software, um, one of my favorite moments from, I think, a previous build maybe one or two years ago was they had a b- they, they...
Swyx: There was a section of you building your [00:24:00] own software. I’m curious if you’re building anything now. Yeah. So I, I think the... You know, first of all, let’s face it, right? Building software has made it possible for even the incompetence of a CEO of a company- ... like ours, uh, you can build, so thank God. But that said, I, I, I, I do feel that, you know, something like, um, GitHub Copilot to me, and especially the new Sessions app or the new app, has just made it so much more possible for you to have agency over artifacts that you felt you couldn’t touch before, right?
Satya Nadella: So to, for me as a CEO, even to go to a code base, uh, to be able to learn about it, like I remember joining Microsoft long back, you know, first and then you say, man, everybody had to go in and look at, you know, whatever, Cutler’s, Malik, or what have you to learn how to do good C, uh, C++ code. Um, so now that ability to be more full stack up and down is so good, but that doesn’t mean every one of us should be doing the same thing.
The question is: [00:25:00] how do you then have the ability to inspect things, learn things, see things, um, I think is just so much more. And so to me, what I’m building a lot of is these long-running Foundry agents. Uh, right? So there’s autopilots. So the easiest thing is, to me, I think I just built one, uh, even last week, where the idea was, hey, can I have an agent that is continuously monitoring essentially my own chief of staff autopilot, right?
We’re gonna have that obviously in, uh, Scout. That’s what, uh, uh, we showed. But it is so easy and trivial to build. I took Work IQ. I said, “Take Work IQ, go, uh, and build a Foundry long-running agent.” Uh, store all the memory in, um, uh, using Ray Fin, right? Basically at my backend as a service. And lo and behold, it built it, and not only built it, I could say publish to Teams, and it published the damn thing to Teams.
Sarah Guo: So the ability, uh, to have a, you know, some end-to-end project like this complete is just pretty [00:26:00] miraculous. How do you think, uh,
Future Engineering Roles
Sarah Guo: that impacts the different types of engineering roles that exist in the future? Because right now I think there’s, you know, a dozen different types of engineers that you can be, from QA, front end, et cetera.
You know, there’s a big swath. I’ve heard some people argue that in four or five years we’ll basically end up with four engineering roles. It’ll be people who are managing agents, it’ll be four deployed engineers or FDEs, it’ll be security engineers, and then people working on large scale infrastructure for a small number of services, and then everything else just collapses into the agentic world.
Satya Nadella: Yeah, I- Do you think that’s a correct view of the world? Yeah, I mean, I think, I think we’ll have to experiment our way through it. But what you said is what... There are some very at scale things. At LinkedIn, they did structurally change- Mm-hmm ... uh, and it, you know, basically built up a new discipline called full stack builder, right?
So they went and said, “Hey, let’s bring, uh, people from design and product management, front end engineering, all put them together.” Uh, but also have an edge, right? It’s not like the design person still doesn’t have the design edge, or the front end [00:27:00] person doesn’t have the front end edge, but you can give yourself bigger scope in roles so that you’re not confined to one role.
Um, and then r- equally, infrastructure has become very critical, right? So in other words, like, I mean, RLEs, I mean, one thing we’ve realized is even for the Excel team, for example. Mm-hmm. Building the RLE in which a reward can be learned is actually one of the hardest sort of infrastructure problems.
Mm-hmm. Uh, and so you kind of need even new talent, right? Distributed systems people even in what was considered an end user app team, uh, because it’s a different skill set. So yes, infrastructure, science is the other one, obviously. Um, so I think we’ll see how these evolve, right? Where’s the s- real... I mean, always the world will have a bunch of specialists.
Okay. Um, you know, I think the generalist role is going to be the most exciting, right? Because the leverage of a generalist- Mm-hmm ... um, is where we are going to see the maximum returns, right? When, when you said, “Hey, are you coding?” I’m now a gen- Like, what... I’ve basically translated [00:28:00] knowledge work Right?
Which I did, where I created a Word document or a spreadsheet, or even, uh... And now I can build an app, right? It’s in the same sentence. Uh, right? That idea that, “Oh, wow, my generalist skills have gotten higher leverage,” I think is what we’re gonna see across the board. Music to the ears of CEOs and VCs that are, like, a little dangerous and a lot of- Golden age for idea people
Sarah Guo: idea people. Yeah. Uh- With a lot of agency. I- if you take that idea of personal agency and you just zoom it out to the organizational context, um, uh, my partner Mike Renall, who, uh, actually started his career at Microsoft, just wrote an essay where one of the big takeaways is i- it’s an age where you can be much more ambitious, and you need to be, given the pace of the environment and how quickly, actually, users and companies are open to adopting new technologies.
Satya Nadella: Um, how do you think about... I, I feel silly asking this of somebody running a, you know, trillion-dollar-plus company already, but
Ambition & Making the Impossible Possible
Satya Nadella: how do you think about how Microsoft can be more ambitious now? It’s a great question. Um, I [00:29:00] think, um- I think the, the thing in these type of transitions is to have a conceptual model of how work can change to go after outcomes that you could hardly imagine previously, right?
In fact, Kevin Scott has this nice line, right, which is, um, when you can make the impossible... Like, when you’re making hard things easier, that’s sort of one point of leverage. But true ambition is about making the impossible possible. So now the thing that is missing a little bit in all of our organizations is what is that new conceptual model of what can we build?
What was impossible and what can we build? And I’ll give you one example of this, right, which is I take great inspiration from sort of the people who were managing the Azure net- network. And they came to the... This was from even last year. You know, we were scaling. You saw that I, I [00:30:00] talked about sort of how we built in the last 15 months more Azure capacity than we built in the first 15 years.
I mean, it’s crazy. Wild. Yeah. Right? It’s pretty wild. And it’s the same team. So they saw that and they said, “Bob, this just ain’t gonna work if we don’t reconceptualize our work.” So they built... Essentially they said, “Our job is not to do Azure networking. Our job is to build the agentic system does, that, that does Azure networking,” right?
These are the folks managing the 500-plus fiber operators managing the VAN, right, all over. And fiber operations ultimately is a physical operation. Things get cut, things get, uh, you know, have to be repaired. You know, we have fancy words called DevOps and so on. Basically, emails are coming in and you gotta go respond to them, take care of it.
So they built this agentic system. They even have a character for it. It’s called Miles, and it sort of does all this stuff, right? They started sort of screaming for more tokens and so on. And so they were saying, “Look, uh, we don’t need a headcount. We need tokens in order to be able to [00:31:00] manage, uh, our operation.”
That reconceptualization- Mm-hmm ... of what their work is, right? They, they basically took their work and made it meta, right? That meta work is now their new work. Mm-hmm. Right? In the ‘80s, if somebody had come to us and said, “4 billion people are gonna get up in the morning and start typing,” my model would’ve been, we need 4 billion typists?
But we’re not doing typing, we’re doing knowledge work. So that, to me, I think is it, right, which is whether it’s Microsoft or whether it’s any organization, is to give ourselves permission to do new types of metacognition, meta work, using these new tools to change the outputs that matter, uh, and then really make the impossible possible.
Sarah Guo: So completing that dot or the, the connective tissue across those, I think, is where a lot of the enterprise value will get created.
Data Center Build-Out & Community Impact
Sarah Guo: Should we talk about data centers? Yeah, please ask. Oh, okay. Well, uh, uh, w- we-- this leads nicely into the data center build-up. I always think, I- I just-- I’m just impressed at the sheer scale of the [00:32:00] build-out from Microsoft, but also everyone else, that this is redefining what it means to be a hyperscaler.
And I just feel like that, that, that is at unprecedented scale on finances, uh, on the way you run the company, but also the communities that are, that are impacted. Um, yeah, just talk a bit more about what you’re seeing on the ground, like when you visit your- Yeah, I think there are two aspects of it.
Satya Nadella: Obviously, the, the build-out is, uh, extraordinary. Um, you know, nothing like this has happened, and it’s great to be, uh, one of the participants in it. Uh, but you brought up the other part, right? I think at this point it’s clear that unless we as an industry, uh, are very principled about ensuring that the benefits of all the stuff we’re talking about are felt in real ways, uh, at the community level, right?
Because this is not just a, a campaign, um, right? It has to be real, where people are saying, “Look, this is not ch- changing the prices on energy for me.” In fact, if anything, it’s bringing down prices because long term there’s going to be a better [00:33:00] grid, there is going to be more energy. Water consumption is, in fact, not sort of, uh...
In fact, water is being replenished, right? You gotta really, you know, educate folks on truly what’s happening, the cl- uh, the closed loop systems we are building. We have to invest in the training, the jobs, the tax base. In fact, the least talked about stuff is the amount of jobs that get created during construction, after construction.
What’s the tax base that’s there in the community? And, and all this has to be real. Um, and, and if that is the case, then we will have permission. If it is not, we won’t have permission. It’s as simple as that, right? Which is, uh, we, we... I think we have to take it as an industry pretty seriously. Uh, I think it’s good for communities to be skeptical, ask the hard questions, for us to do the hard work, earn that.
Um, but at the end of the day, if there’s-- if we can really be the produ-- Wait. I’ve always felt like in human history, if you use a lot of energy but also create a lot of value for society- The story has been fantastic. If you don’t [00:34:00] do that, it’s not been that great. And this time around, I’m a firm believer that ultimately if you do have a token economy that drives productivity, that drives economic growth, that drives broad spread, um, you know, participation, better health outcomes, um, then I think we’ll be in a great place.
Sarah Guo: Uh, and that’s at least what we all have to be focused on. Yeah. It, it makes me think actually that with all these initiatives that you’re doing, might be e- easier to see ROI in the communities first before in enterprise. Yeah. I, I mean, I think both sides. Yeah. In fact, it comes back together. It has to be the people in the communities are going to be employed, are going to be participants, uh, in the real economy, right?
Satya Nadella: That’s I think the question is. Like, if we- if the broad economy is doing well and the communities are doing well, the dots get connected. It’s sort of the market forces are such that we will connect the dots. And that I think is it. Like, you ought to be able to see the evidence. You can’t be about o- any one company, uh, but it has to be broad economic growth and broad [00:35:00] ec- you know, community permission.
Elad Gil: Yeah. I guess I wanna talk about
Societal Impact & Optimism About AI
Elad Gil: what you’re most optimistic about currently or what have you most updated your personal models on regarding societal impact of AI? So you’re saying what’s the, the, the- What have you updated most on in terms of societal impact of AI? Yeah. I think the, um, the p- the most, um- Critical thing is the first question we even started with, which is we need to tell the story and make it real that everybody has a real shot to participate as a first-class participant in this new economy.
Satya Nadella: Right? That’s kind of, I think we- in the next 12 months, 18 months, we need a way for people to say, “Oh, wow, I get it.” Right? There’s going to be tremendous capability, tremendous amount of infrastructure, but I can see what is going to happen, whether it’s the benefits like health outcomes or my ability to create a startup or my ability to run my [00:36:00] local sort of, uh, store more efficiently.
It’s just happening, and I see that, uh, benefit myself, right? That to me, you know, earning that permission in a path-dependent way, we can’t wait. See, the one thing, Eli, that I’ve now learned is I think the world is gonna be very skeptical of tech and tech companies that say, “Trust us, we’ve got it. The g- future is gonna be glorious.”
Sarah Guo: Uh, you kind of have to deliver tangible benefits. Um, and quite frankly, politicians winning elections, uh, because they have advocated for that. That will be at least my adjustment because without it, um, thinking that somehow... Because it’s too important this time around. It’s too much of the economy for it not to be the case So one very simple framework I have for, you know, what are, what is gonna be the broad benefit of AI, um, beyond the communities just working in technology, are, are sort of wealth creation- Yep
it’s [00:37:00] gonna happen in a ton of different companies, startups and large companies. Then you have healthcare. Uh, you, you had amazing demos today. There are companies like Open Evidence. I think that is happening. Um,
Education & Future of Learning
Sarah Guo: education seems like another one that’s an- Yep ... obvious good where we haven’t seen as much impact as I’d expect.
Swyx: Do you have a hypothesis on why that might be, or if it’ll come? Yeah, I mean, I think this is where, again, how we think about education, how... You know, recently I met with, uh, the founders of Alpha School and learnt a lot about what they were going and going about, and it’s fascinating to listen, uh, to how to even rethink- Mm
Satya Nadella: uh, what does education really look like. Because I think it’s actually very important. Mm. Uh, and I’m not saying anything traditionally being done is less important, right? I was even looking at the, uh... It’s fascinating to see. I, I, I forget the which Stanford class it was, uh, the, the Asian guidelines for CS something.
Mm. Uh, because you still need people to learn. Uh, like it was an interesting AI class that they were making sure people were learning how to apply softmax appropriately versus saying, “Hey, fix my training run.” Mm-hmm. Uh, so I think learning concepts is important. It’s going to [00:38:00] be, uh, critical. But the way we create the incentives, what are the credentials, how we value those credentials, what is the employment opportunity for those credentials?
So I think that there’s a complete change that has to happen, uh, given the way to get to information, way to educate yourself, way to continuously keep yourself updated has changed so much. So I think interestingly enough, maybe the next big startup and success story could be someone who builds a new university, um, or a new, um, pedagogy even of how to get someone to go through a curriculum and find economic opportunity, uh, that’s highly valuable.
Well, that has felt, uh, perhaps impossible for a long time, but it’s a great note to end on and something that might be possible. It’s still possible. Yeah. Thank you, Satya. Thank you so much. Thank you. Yeah. I appreciate it. Thank you all.
This is an impressive lineup, especially considering that the Microsoft-Inflection deal that set up MAI only happened 2 years ago, and that these are all from-scratch pretrains. MAI today is by no means an unqualified frontier lab, but it is a good tier 2 neolab with obvious incentives to support domain specific finetunes (as opposed to the frontier labs who have ~all killed finetuning).
The star of the show was the 100+ page MAI tech report, which the research community is giving glowing reviews:
You can catch up on all the rest of the announcement in the excellent Verge recap, and the tweet summaries below:
Top Story: Microsoft Build recap, and new MAI model technical details
What happened
Microsoft used Build to position itself as both an AI platform company and a frontier-model lab, pairing broad product launches with unusually detailed disclosures about its new MAI model family.
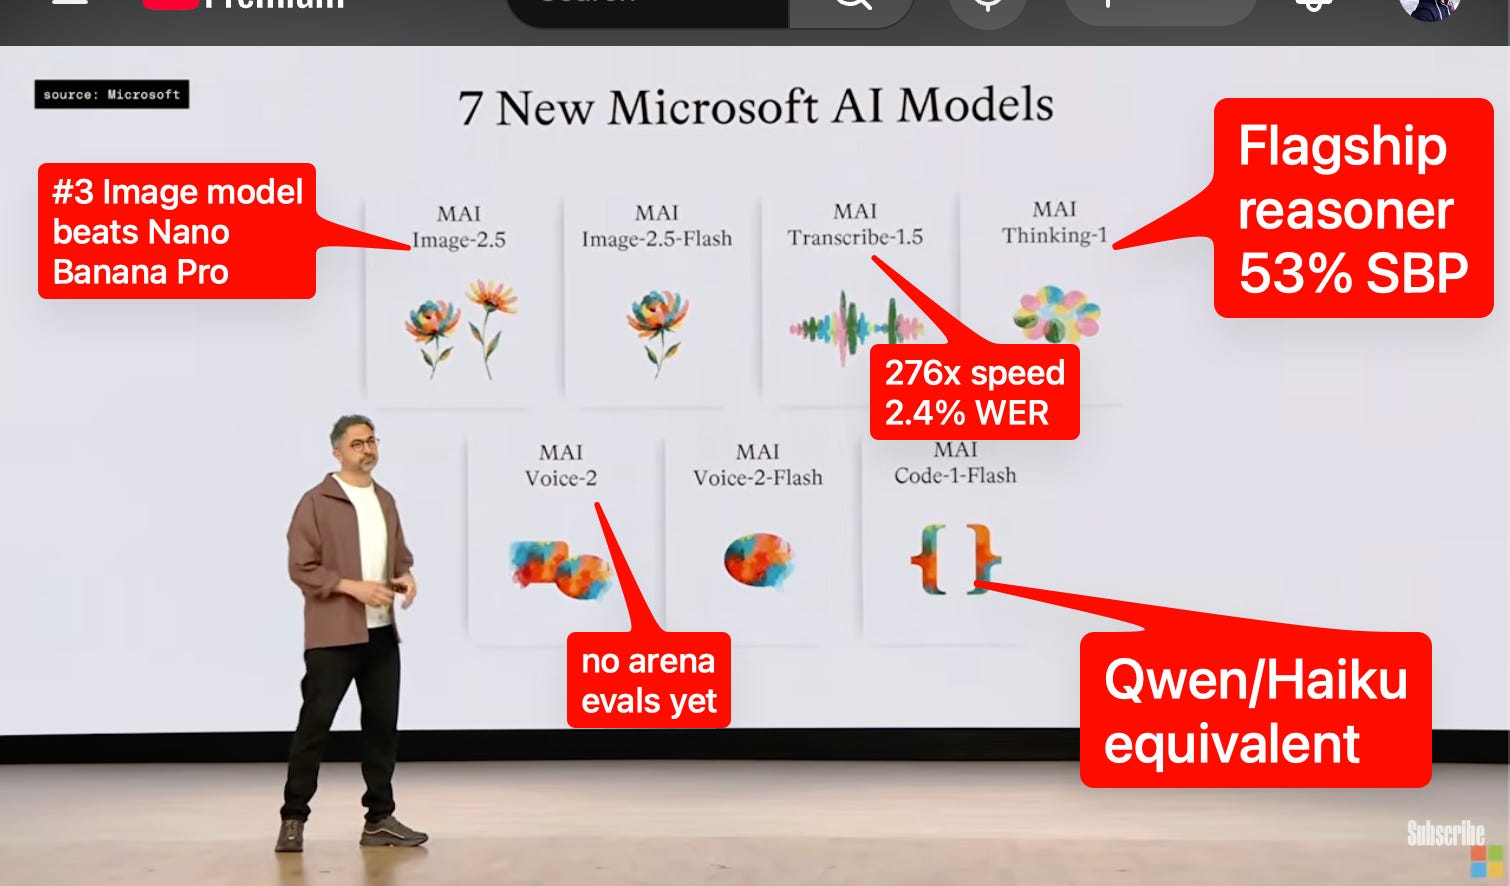
Microsoft AI announced seven new MAI models spanning reasoning, code, image, speech transcription, and voice, led by MAI-Thinking-1, MAI-Code-1-Flash, MAI-Image-2.5, MAI-Transcribe-1.5, and MAI-Voice-2 according to @MicrosoftAI and @mustafasuleyman
The flagship reasoning model MAI-Thinking-1 was presented as Microsoft’s first reasoning model, built with clean data lineage and zero distillation from third-party models in posts from @mustafasuleyman, @baseten, @tuhinone, and @HannaHajishirzi
Microsoft also emphasized local AI and agent-native Windows: Build messaging highlighted secure execution layers for agents, a new Surface RTX Spark Dev Box, Windows AI access to the broader Windows GPU install base, and concept hardware such as Project Solara/Scout, summarized by @yusuf_i_mehdi, @TheTuringPost, @kimmonismus, and @kimmonismus
Build also included a major GitHub Copilot app push as the “desktop home for agent-native software development,” with canvases, cross-device continuity, and tighter GitHub agent workflows, from @pierceboggan, @lukehoban, and reactions from @techgirl1908
Microsoft introduced Web IQ, a new grounding/search API stack for AI agents, claiming the APIs already power “nearly all AI agents and chatbots in the industry today, including Copilot and ChatGPT,” via @JordiRib1
Satya Nadella framed Build as an ecosystem moment rather than a single-product launch, while Mustafa Suleyman framed it as the output of Microsoft’s internal “hill-climbing machine,” in @satyanadella, @mustafasuleyman, and reaction from @nrehiew_
MAI model family: disclosed facts and technical details
MAI-Thinking-1
Microsoft described MAI-Thinking-1 as a 35B active parameter MoE with a 256K context window in @mustafasuleyman
A separate summary from @scaling01 says the model is a 1T@35B parameter model, pre-trained on 30T tokens, and trained using 8192 GB200 GPUs; this appears to be a reading of the technical report rather than Microsoft marketing copy
@kimmonismus similarly summarized it as a mid-size MoE with 45B active params, but this conflicts with Mustafa’s own 35B active figure; the more authoritative figure in the tweet set is the official 35B active number
Microsoft claims 97% on AIME 2025 and 53% on SWE-Bench Pro, with blind human raters on Surge preferring it overall to Sonnet 4.6, from @mustafasuleyman and @asadovsky
Microsoft says the model is optimized on MAIA 200, with 30% better performance per dollar and 1.4x performance-per-watt gain versus GB200 when running MAI models end-to-end, per @mustafasuleyman
Microsoft and partners repeatedly stressed no third-party distillation, “clean data lineage,” and enterprise-controlled fine-tuning with “100% eyes-off” post-training data through Baseten, in @baseten, @tuhinone, and @MicrosoftAI
MAI-Code-1-Flash
Microsoft introduced MAI-Code-1-Flash as a fast coding model for VS Code and GitHub Copilot CLI, first announced by @pierceboggan and later highlighted by @mariorod1
Official Microsoft messaging via @mustafasuleyman says Code-1-Flash achieves 51% on SWE-Bench Pro despite having just 5B parameters, positioning it near Haiku-class size/cost
A competing summary from @scaling01 describes it as a 137B parameter MoE, 256K context, trained on 10T+ tokens, and “stronger and more efficient than Claude 4.5 Haiku.” That likely indicates 5B active parameters rather than total parameters; the tweets do not fully reconcile this distinction, but together imply small active footprint within a much larger MoE
Availability at launch was highlighted as GitHub Copilot / VS Code-first, per @scaling01 and @mariorod1
MAI-Image-2.5
Microsoft launched MAI-Image-2.5 and a Flash variant, claiming both reached #2 on leaderboards, with @mustafasuleyman saying they surpass Nano Banana 2 on image editing
Independent leaderboard accounts supported the high ranking: @arena reported #2 in Image Edit Arena with score 1401, +10 points over Nano Banana 2, Grok Imagine, and ChatGPT Image Latest HF
@arena further said MAI-Image-2.5 “advances the Pareto frontier,” meaning no model at its price tier scores higher on that benchmark
Distribution partners quickly followed, including @OpenRouter and @fal
MAI-Transcribe-1.5
@ArtificialAnlys reported MAI-Transcribe-1.5 as an unusually strong speed/accuracy point on the STT frontier: ~276x realtime, 2.4% AA-WER, #3 overall on its leaderboard
The model supports 43 languages, including English, French, Arabic, Japanese, and Chinese, and supports keyword biasing for rarer terms such as names and medical terminology, per @ArtificialAnlys
Pricing was reported as $6 per 1,000 minutes of audio via Microsoft Foundry in @ArtificialAnlys
OpenRouter also listed the model among the three MAI launches it brought live the same day in @OpenRouter
MAI-Voice-2
MAI-Voice-2 appears in Microsoft’s “seven models” umbrella and in OpenRouter’s availability post at @OpenRouter
The tweet set contains little technical detail on Voice-2 itself beyond launch/availability
Technical-report details that mattered to researchers
Why the report stood out
The dominant technical reaction was that Microsoft released an unusually detailed frontier-model report: @eliebakouch called it “one of the most transparent for a model at this scale,” @nrehiew_ said it “could really serve as an updated textbook for LLM training today,” and @stochasticchasm called it a “gold mine”
Multiple readers highlighted that the report disclosed pipeline details, scaling ladder methodology, data curation, infra metrics, and MFU numbers; this level of specificity is what drew praise from @ethanCaballero, @eliebakouch, and @nrehiew_
Pretraining and data
A major technical claim repeated across commentary is that MAI-Thinking-1 used no synthetic data and no distillation, not only in post-training but throughout the disclosed pipeline, from @eliebakouch, @stochasticchasm, and @HannaHajishirzi
@eliebakouch says the report explicitly notes data from Common Crawl plus private sources, with targeted sub-pipelines for different domains, heavy extraction/dedup work, and an intentional choice of no synthetic data
The report’s internal private NLL set used for scaling decisions was summarized by @eliebakouch as:
50% code
17.5% STEM
17.5% math
10% general knowledge
5% multilingual
@eliebakouch says architecture promotion in the scaling ladder was based on an Efficiency Gain (EG) metric: how much extra compute the baseline would need to match the candidate’s loss
The same thread notes ablations at roughly 100/200 tokens per parameter, described as around “Chinchilla optimal” for the setup, while also remarking this differs from dense-model heuristics due to MoE structure in @eliebakouch
Post-training / RL
The most discussed technical choice was that Microsoft appears to have started RL from a checkpoint with no prior reasoning exposure, which several readers found notable. @stochasticchasm called this a “very interesting decision,” while @stochasticchasm reacted to graphs suggesting a jump from <20% AIME25 to >95%
@HannaHajishirzi described the “climbing from scratch” recipe as simple recipes, rigorous science, self-distillation, patience, and great infra
@soldni characterized the process as “climbing with no distillation, like the big boys do”
Some independent readers inferred from the report that synth data remains very valuable for agentic performance in the broader field, even if Microsoft deliberately avoided it here; see @stochasticchasm
Data curation / judges / DSPy GEPA
A detail that got substantial attention from the DSPy/late-interaction crowd: Microsoft reportedly used GEPA / DSPy-optimized LLM judges in pretraining data curation and quality scoring
Microsoft reportedly disclosed exact MFU across iterations, which multiple readers said is rarely shared at this scale, per @eliebakouch
@scaling01 summarized the run as using 8192 GB200 GPUs
@eliebakouch singled out a reported ~40% higher throughput per watt-type figure as “pretty impressive and bullish on microsoft chips,” though this may refer to rack-level budget or serving configuration and was not fully unpacked in-tweet
Microsoft’s official framing connected model design to MAIA 200 custom silicon and emphasized better performance-per-dollar and performance-per-watt vs NVIDIA GB200 in @mustafasuleyman
Build’s broader Windows/local-AI narrative also centered on hardware specifics such as:
1 trillion parameters running locally on DGX Station
Reactions also pointed to local runs of large models, e.g. @kimmonismus on RTX Spark running a 120B parameter model locally
Build product/platform recap beyond the models
GitHub Copilot app and agent-native development
GitHub unveiled the GitHub Copilot app, pitched as a desktop surface for agent-native software development by @pierceboggan
Key themes included:
canvases for bidirectional work between users and agents, per @Techmeme
continuity across CLI, mobile, web, local, and cloud, per @lukehoban
a growing role for GitHub as the center of agent workflows, reflected in @techgirl1908 and @OrenMe
Copilot CLI also got an experimental terminal UI with tabs, built-in feedback/rubber duck, prompt scheduling, and voice input, per @GHchangelog
Windows as an agent runtime
Microsoft’s Windows org framed Build around “faster developer execution, a secure execution layer for agents, and unmetered intelligence that runs locally on device,” per @yusuf_i_mehdi
Several posts stressed that Microsoft wants Windows to be the trusted execution platform for agents, not just Azure
@TheTuringPost described Project Solara as a platform for agent-first devices, with concepts including:
a desktop AI companion
a wearable badge with cameras, microphones, sensors, and secure authentication
@kimmonismus saw these as handheld/desktop devices for controlling agents and compared them to expectations people had for standalone OpenAI hardware
@kimmonismus separately highlighted Microsoft Scout as an “always-on personal agent for work”
Web IQ and search for agents
@JordiRib1 announced Microsoft Web IQ as a suite of AI-native grounding APIs for web pages, news, images, and videos
His framing is important context: classic search engines were built for humans, but Microsoft believes future search demand will come from agents, potentially 1000x more queries than human search traffic
He claimed Web IQ was re-architected from Bing’s stack for quality, latency, and token efficiency, and that it already powers major chatbots including Copilot and ChatGPT
Foundry and open-model distribution
@jeffboudier said Satya cited 11,000+ models available in Microsoft Foundry, of which 10,928 come from Hugging Face
This supports Microsoft’s parallel identity at Build: both a first-party model builder and a large multi-model hosting/distribution platform
Build messaging around datacenters and compute
Several observers noted Build discussion around data center expansion, community backlash, and Microsoft’s argument that AI infra can expand without raising electricity costs to local communities; see @kimmonismus and @kimmonismus
@scaling01 highlighted Mustafa saying AI compute will grow 1000x in the next 3 years, taking today’s rough 5e27 FLOPs frontier scale to 5e30 FLOPs by 2029
@mustafasuleyman summarized the company’s philosophical theme as “Humanist superintelligence”
Facts vs. opinions
Factual claims in the tweet set
Microsoft launched seven new MAI models at Build: @MicrosoftAI
Official metrics for MAI-Thinking-1: 35B active MoE, 256K context, 97% AIME 2025, 53% SWE-Bench Pro, and blind human preference over Sonnet 4.6: @mustafasuleyman
Official metrics for MAI-Code-1-Flash: 51% SWE-Bench Pro, 5B parameters as stated in tweet copy: @mustafasuleyman
MAI-Image-2.5 ranking claims were independently echoed by @arena
MAI-Transcribe-1.5 speed/accuracy details came from independent benchmark account @ArtificialAnlys
Microsoft released a 109-page technical report: @eliebakouch
Opinions / interpretations
“Microsoft is training serious models now?” from @teortaxesTex is an interpretive reaction to the model/report quality, not a standalone fact
Claims that the report is “one of the most transparent” or “an updated textbook” are opinions from @eliebakouch and @nrehiew_, albeit shared by many readers
@kimmonismus and @TheTuringPost framed Build as a strategic shift from cloud-only AI toward local reasoning/agents; that is analysis rather than official wording
Posts claiming Microsoft “leaked” Anthropic Mythos FLOPs, including @swyx and @scaling01, are speculative interpretations of a slide, later contested by the same cluster of commenters
Some saw MAI-Thinking-1 as proof Microsoft is becoming a genuine frontier lab rather than just a model reseller or application layer, e.g. @teortaxesTex, @echen, @NandoDF
Enterprise/platform supporters liked the clean-data-lineage, fine-tunable, eyes-off post-training data story, especially Baseten/Microsoft’s positioning around ownership and control: @baseten, @tuhinone
Some commentators were careful on benchmark interpretation. @kimmonismus noted Microsoft appeared to compare to Sonnet 4.6 generally, with Opus-level comparability only on SWE Pro
@iScienceLuvr specifically appreciated reporting on health benchmarks such as HealthBench Professional and MedXpertQA rather than only coding/math
Skeptical / opposing views
A subset questioned whether all numbers and comparisons were being interpreted correctly, especially around active params and external-model comparisons
The most visible skepticism concerned the apparent Mythos FLOP “leak”. @iScienceLuvr suggested it was probably just an estimate, not a leak; @scaling01 later argued the original 6.1e27 FLOP figure was unrealistic and supplied a lower alternative estimate before posting a correction in @scaling01
There was also implicit skepticism in the field about whether zero synth / zero distillation is the right long-term recipe for best agentic performance, as noted by readers emphasizing synth-data deltas elsewhere, e.g. @stochasticchasm
Context: why this matters
Build’s announcements matter because they suggest Microsoft is no longer content with being only:
Azure/OpenAI’s cloud host
GitHub’s developer surface
Copilot’s application shell It is also trying to be a first-party frontier model developer with its own model family, silicon stack, and post-training platform
The clean lineage / no distillation emphasis is strategically significant. It addresses enterprise concerns around IP provenance, future controllability, and dependence on external labs
The local AI emphasis matters because Microsoft is tying AI strategy to Windows and device distribution, not just to Azure. Build messaging repeatedly pushed the idea that reasoning models, planners, and agents can increasingly run on-device, not only in the cloud: @TheTuringPost, @yusuf_i_mehdi
The 109-page report matters because frontier-model transparency has generally been shrinking, especially around data, infra, and training methodology. Multiple researchers explicitly noted the disclosure level is uncommon at this scale: @eliebakouch, @nrehiew_
The Build recap also showed Microsoft trying to integrate all layers of the stack:
models: MAI family
chips: MAIA 200
cloud: Azure + Foundry
OS: Windows agent runtime
developer UX: Copilot app / VS Code / CLI
retrieval/grounding: Web IQ
hardware form factors: Solara / Scout concepts
This combination is why several observers described the event less as a normal dev conference and more as a coordinated move toward an agent platform spanning cloud, edge, OS, and custom models, e.g. @satyanadella, @mustafasuleyman, and @TheTuringPost
The “Mythos FLOPs leak” mini-story
During/after Build, some users claimed a Microsoft slide inadvertently revealed training compute for Anthropic’s rumored Claude Mythos, with @swyx asking if Mustafa had leaked the FLOP count
@scaling01 estimated the slide implied 6.1e27 FLOPs with a confidence interval based on pixel measurement, while @kimmonismus noted that would be around Gemini 3.1 Pro-scale compute
That interpretation was subsequently challenged by @iScienceLuvr, who argued it was probably an estimate, and then by @scaling01, who posted a lower-range model-based estimate of 3.37e26 to 1.46e27 FLOPs and later said the original numbers were bogus in @scaling01
The episode is useful mostly as context: Build’s compute/scaling messaging was detailed enough that people started trying to infer competitor training budgets from presentation materials
Developer tools, agents, and coding workflows
OpenAI launched Sites in Codex, letting teams turn ideas/docs/plans into deployed internal websites/apps with auth and dynamic data, first for business/enterprise users, in @OpenAI, @TheRohanVarma, and @gdb
OpenAI also expanded role-specific Codex plugins across sales, data analytics, creative production, product design, and public equity workflows, with access to 62 apps and 110 skills, from @OpenAI and @OpenAIDevs
GitHub’s Copilot app and Microsoft’s Build push around agent-native software development were central to the day’s tooling news: @pierceboggan, @lukehoban, @GHchangelog
Anthropic shipped a CLI for Claude Platform and upgraded Claude Code’s /fork to run a background agent with exact context + prompt cache, in @ClaudeDevs and @ClaudeDevs
Nous launched Hermes Desktop, a local/native desktop surface for Hermes agents, in @NousResearch, @Teknium, and later Tailscale/Ollama integration notes from @Teknium and @ollama
Cognition launched Devin Desktop, positioned as an agent-neutral desktop for managing local/cloud agents and handoff between local planning and cloud execution, in @cognition, @ScottWu46, and @russelljkaplan
Models, local inference, and routing
H Company launched Holo 3.1, a local computer-use model family based on Qwen-style architecture, with checkpoints from 0.8B to 35B and formats including NVFP4, FP8, and Q4 GGUF; a popular summary cited 79.3% on AndroidWorld for the 35B model in @TeksEdge, with launch tweet from @hcompany_ai
Perplexity announced hybrid agentic inference for Perplexity Computer, splitting work between local models on-device and frontier cloud models for privacy and token efficiency, in @perplexity_ai and @AravSrinivas
OpenRouter data shared by @ttunguz showed open-weight models at 69.1% of token volume, versus 30.9% for closed models
Commentary around model routing as a key future abstraction came from @ClementDelangue, @garrytan, @matanSF, and the counterpoint from @glennko, who argued enterprise production reliability makes generic routing harder than enthusiasts suggest
Local-AI UX improvements also appeared in Hugging Face’s hardware compatibility checks and oMLX’s native macOS app release from @m_newhaus and @jundotkim
Research and evals
Google DeepMind announced Co-Scientist, a Gemini-based multi-agent hypothesis generation system for science, claiming collaborations that helped identify liver fibrosis targets, ALS approaches, and genetic leads for aging, in @GoogleDeepMind, @GoogleDeepMind, and @GoogleDeepMind
The new Crafter / CraftEditor work on editable scientific figure generation drew attention as a five-agent workflow for producing and refining figures plus raster-to-SVG conversion, in @HuggingPapers, @_akhaliq, and @TheTuringPost
Tilde Research introduced Wall Attention, a RoPE-free attention method with diagonal forget gates, claiming training at 4k and generalization to 200k+ tokens plus Triton kernels and strong decode throughput, in @tilderesearch
A robotics vision encoder claiming +22.5% real-world OOD success by encoding dynamics-awareness rather than relying on static-image pretraining was posted by @jbhuang0604
New evals/benchmarks of note:
PaintBench for precise image editing, where best model reached only 17.1%, from @itskaixu
VSTAT for video state tracking, arguing frontier MLLMs remain weak at tracking evolving world state, from @PinzhiHuang and @sainingxie
Data Agent Benchmark for enterprise data workflows, from @sh_reya
Inference, infrastructure, and agent systems
Harvey + LangChain shared work on cheap verifiers for legal agents, showing DeepSeek V4 Flash could preserve 94–96% agreement with Opus 4.7 while reducing cost 18x in per-criterion mode and ~1000x in batch mode; for 3,200 RL rollouts, verification cost dropped from $18,000 to $18, in @harvey, @hwchase17, and @nikogrupen
W&B relaunched Weave as agent-first observability with integrations across common harnesses and automated detection of failure modes, in @wandb and @neutralino1
Prime-RL integrated Mooncake Store with vLLM for cross-node prefix / KV cache reuse, pitched as key for agentic rollouts, in @m_sirovatka
Together detailed serving optimizations for MiniMax-M3, citing 81–125% throughput improvements via KV-block-major sparse attention, paged decode, optimized index scoring, and multimodal preprocessing, in @togethercompute
MiniMax itself highlighted 1M context, native multimodality, desktop-computer operation, and MSA reducing attention’s share of decode time from ~30% to ~5%, in @MiniMax_AI
Ecosystem, hardware, and industrial capacity
Westmag emerged from stealth to build American robot actuators and drone motors, with $11M raised led by a16z and participation from Founders Fund, Lux, NFDG, Menlo and others, in @boxcardavid, @packyM, and @oyhsu
PyTorch noted NVIDIA adoption of OpenMDW-1.1, a permissive AI-model licensing framework, across four open-model families in @PyTorch
Martin Scorsese publicly demonstrated narrow, preproduction use of FLUX for storyboarding with Black Forest Labs, framed as exploratory and complementary to hand-drawn work rather than generative replacement, in @robrombach and @TheRundownAI
I’m excited to work with Microsoft once again as the presenting sponsors of the AI Engineer World’s Fair!We’ll streaming live from MS Build today for a special crossover pod with our friends at No Priors and the one and only Satya Nadella. However we did not hold back with this interview - we asked all the burning questions about uptime and Copilot that we know you have in your minds. Lets go!
For almost two decades, GitHub has been the home of software, where both open source and closed flow, through commits, pull requests, reviews, actions, etc.
This ecosystem flourished as open-source maintainers and contributors would continue shipping code for the benefit of the community. However as coding agents began to ship mass quantities of code - growing 1400% in 2026, it marked a new era that was both extremely exciting and challenging for GitHub.
While these agents help more people ship more projects, they also significantly increase the floor of how much code is shipped, how often it is shipped, how many people commit code, and basically orders of magnitude multiples in every dimension of GitHub infrastructure:
Now GitHub inevitably experiences more pressure on their infrastructure which was originally designed around human developers moving at human speed. This has resulted in a very publicly notable uptime story:
So it begs the question of whether current systems around code can absorb what AI produces. Can CI/CD keep up when every idea becomes a build? Can open source maintainers survive floods of AI-generated slop contributions? Can GitHub preserve the human social contract of software while becoming the operating layer for agents?
Which brings us to the perfect person to answer these questions: GitHub COO Kyle Daigle. In this episode, he joins swyx to unpack what happens when AI doesn’t just autocomplete code, but starts changing how companies operate, how open source works, how pull requests get reviewed, and how GitHub itself has to scale.
We go deep on GitHub’s internal AI workflows: micro-skills, WorkIQ, MCP, Slack, Teams, email, Copilot workflows, the new Copilot desktop app, CLI, cloud agents, and how Kyle uses agents to look backwards across company context before deciding what to do next. Kyle also reflects on GitHub’s history building webhooks, APIs, Actions, npm, Dependabot, and Semmle, why the AI era is breaking GitHub in new ways, how Actions became a general-purpose compute layer, and what Copilot becomes after code completion.
Full Video Pod
We discuss:
Kyle’s expanded role across GitHub
How AI got Kyle coding again after years in leadership
Why GitHub rolls out AI through existing workflows instead of forcing new tools
WorkIQ, MCP, Slack, Teams, email, and GitHub as company context
Why massive “mega-skills” are giving way to small, atomic micro-skills
How AI changes summarization, communications, marketing, and analyst work
Why former developers in leadership may have a unique advantage in the AI era
Kyle’s “15 agents on Saturday” workflow
How Kyle built an AI-generated executive presentation for CRO/CFO teams
Why AI changes the chief of staff role without removing the human work
GitHub Actions, webhooks, arbitrary code execution, and secure agent compute
The npm acquisition, supply-chain security, 2FA, and token invalidation
Slop forks, vendoring, and whether AI agents change dependency management
What pull requests become when most PRs come from agents
Prompt requests, vouching, AI review, and trust in open source
What counts as a “developer” when AI lowers the barrier to building
GitHub Spark, low-code, and why GitHub refuses to hide the code
14x commit growth, Actions load, databases, monorepos, and availability
Copilot’s evolution from completion to CLI, desktop app, cloud agents, and SDK
Context, memory, rules, and making GitHub “act like Kyle wants it to act”
Ambient AI, OpenClaw, enterprise security, and the new operating system for agents
What swyx should ask Satya Nadella about Microsoft’s AI future
00:07:04 Running GitHub with AI: WorkIQ, MCP, Slack, Teams, and Skills
00:15:39 The Golden Age for Former Developers in Leadership
00:17:31 15 Agents on Saturday and AI-Generated Executive Work
00:20:20 How AI Changes the Chief of Staff Role
00:21:45 GitHub’s History: Actions, npm, Webhooks, and Open Source
00:28:45 Slop Forks, Vendoring, and AI Dependency Management
00:33:57 Pull Requests, Prompt Requests, and Trust in Agent-Generated Code
00:41:21 GitHub Stars, 200M+ Developers, and the New AI Builder Wave
00:45:15 GitHub Spark, Low-Code, and Why GitHub Still Shows the Code
00:47:38 GitHub’s Hardest Era: 14x Growth, Reliability, and Scale
00:59:21 Actions as the Compute Layer for CI/CD and Automation
01:02:04 The State and Future of GitHub Copilot
01:08:24 Ambient AI, Background Agents, and the Future of the SDLC
01:13:09 OpenClaw, Enterprise Security, and the New OS for Agents
01:18:03 Build Announcements, WorkIQ, FoundryIQ, and Microsoft Context
01:21:41 What Should swyx Ask Satya?
Transcript
Introduction: Kyle Daigle’s Expanded Role at GitHub and Microsoft
Swyx [00:00:00]: We’re here with Kyle Daigle, COO of GitHub. Welcome.
Kyle [00:00:07]: Hey, thanks for having me.
Swyx [00:00:08]: You’re not just CEO of GitHub. People know you as that. You have a new role.
Kyle [00:00:11]: So I have an expanded role now. I’ve been working at GitHub for thirteen years and doing all things developer. Joined as a developer myself. And now, I’m also responsible as the CMO of Developer for Microsoft. And so all the kind of learnings and passion for developers and how we work with them and how we communicate and how we bring our products to market, we’re also bringing that expertise to the broader Microsoft ecosystem and helping every developer that uses a Microsoft product or would like to have a sort of similar experience that they’ve had with GitHub over the years. So it’s a different role in some ways, but it’s also just building on the experience that I’ve had at GitHub of just sort of tell the truth, be authentic, show people how to use it and then let the products speak for themselves. Now just doing that with, all of Microsoft.
Swyx [00:01:09]: We’ll be releasing this in conjunction with Build. You got lots of stuff planned, and we can sort of touch on that whenever it’s appropriate. I think one of the interesting things is I rarely meet a COO who’s also a CMO. I think you’re a very outward facing and you’re very confident publicly. That’s rare. Do you actually view yourself as COO? What’s What is your thing?
From GitHub Developer to COO/CMO: Building the Platform and Operating GitHub
Kyle [00:01:33]: I think for me, it’s been funny. The titles have always been, a— have always felt a little strange to me. I joined GitHub as a developer? I wrote so much of the
Swyx [00:01:46]: Let’s bring that up. You wrote the back ends?
Kyle [00:01:48]: I was going through, I was going through, some old photos, when folks were talking about how things were being built or how there was a build GitHub. I built, webhooks and worked with teams building the API, built the platform layer. Anything that integrated with GitHub, up until really twenty eighteen, I built or ran the engineering teams. And that’s kind of where my the beginning of my passion always was helping people build things, deliver them to, their customers. And so being a developer, building for developers was always super unique. In a— I think as my role expanded, it became my ability to talk to not just developers, but also enterprise customers or business leaders and have this translation layer. And then through all those years, GitHub has always operated pretty uniquely. Post-pandemic, working remotely was not as novel as it was when GitHub started in two thousand and eight. But all that expertise of running remote teams, doing it well, became this sort of bigger role, ultimately turning into the COO role of how do we operate GitHub in the way that GitHub’s always operated after the Microsoft acquisition. And kind of so on from there. So like for me, I think the— I’ve, I still code. I love coding but the problem has always been, people. It’s a much harder problem to both support our own employees, a harder problem to communicate to developers and enterprise buyers what we’re building why it matters, ‘cause those are two very different messages. And so getting to work in the mix of COO, CMO, also just being a dev, I think is what’s kept me at GitHub for so long.
AI Workflows for Leadership: Commits, Retrospectives, and Context
Swyx [00:03:40]: Apparently, you have— your commits have gone up. What’s this? What’s going on?
Kyle [00:03:45]: Rui’s called me out pretty aggressively. So I think— as you can imagine, right, you can see my normal era of being a dev In the twenty thirteen, twenty fourteen era, and then moving into management, and then ultimately the COO role. I think what you see there is me, really getting back to coding thanks to AI. I— similar to, attaching problems between how to market and how to operate a business and how to code, I find, building agents and workflows that are connecting very disparate problems to be what’s driving this. So that’s, some of it’s writing software. A lot of it is, connecting a ton of a different data sources to, help me out. But that is completely me really diving in on the AI side in trying out our tools, trying out everyone’s tools, But building for me, building for the non-technical leader, though I’m technical and how we’re, able to use these tools more than just the simple, call and response that I think a lot of the non-technical, your employers, you have to get— you have to use AI, and so everyone uses, ChatGPT or Copilot or Claude or whatever. To really get into, how is this going to help me out, it— I find that it’s not the I need to write a blog post, I need to those simple examples. Helping people find the workflows of, “Okay, I need you to go through all the PRs today. I need you to go through everything that we’ve posted online. I need you to go through what we did the last three months. Go through all of my Obsidian notes for any mentions of this then go through my transcripts at work.” We use, Teams, so, using WorkIQ, go call that MCP server, grab all the transcripts, go through all the Slack, and then build me out the plan of, what this week’s messaging actually was. That’s something that was, impossible because for me, I find AI in a what most of this launch here is actually, less building forward. It’s actually, a recursive loop backwards. I’m always looking at what had happened first. Go back through the week and tell me what we did, what worked, what didn’t work? And then tell me in the next three or four days-What would you tweak based on this sort of like looking backwards and then looking ahead a little bit? I find that to be so much more valuable, especially for like non-technical, because that retrospection is actually LLMs are very good at that. Like finding all the patterns, pulling them out, and then applying that retrospection to just a couple of days or just like a short period of time. Is all a bunch of apps that I’ve built and launched a bunch of, internal tools. I use the new, GitHub Copilot app, the desktop app with workflows. Every time I crack open my laptop, it’s running workflows for me. It’s just a ton of different stuff and of course, it all ends up on, it all ends up on GitHub.
Swyx [00:06:47]: Of course. That’s where, that’s where, stuff is hosted. Man, there’s so much to ask you. I was going to leave the how do you run a company with AI thing at the end. I have to ask one— double click one thing. You said, you are looking back at the week. You’re, you’re understanding what happens. When you say we That’s three thousand people. How?
Rolling Out AI Internally: Skills, CLIs, and Company Context
Kyle [00:07:09]: I think when we started rolling out AI internally beyond engineering, right? One of the things that I was really, passionate about is like we have to do this in a way where no one has to change how they work. I don’t want to have to teach you a tool. I don’t want to have to teach you something new. And so for us, we tried out a few tools. Most of them don’t work because I got to get you on board? I got to teach you how to use it. What we’ve actually ended up doing is we’ve built like a set of skills internally. We have we each have our set of skills, and we’ve just been distributing even to the non-technical folks, the CLI. And then effectively, we’re just giving it access to like read about everything that we’re writing. So that’s for us, that’s usually GitHub, Teams, Email, and Slack. So Teams for, video chat, generally speaking.
Swyx [00:08:03]: Teams and Slack?
Kyle [00:08:04]: so we use Teams for video communication, but we don’t use it for chat. W-we— GitHub for a long history, right? We’re always
Swyx [00:08:13]: Also Slack
Kyle [00:08:14]: Talking about ChatOps and like everything is built into Slack. Like every command, every flow.
Swyx [00:08:18]: So even though you have been acquired for I don’t know, eight years now
Kyle [00:08:22]: we still
Swyx [00:08:23]: You still use Slack?
Kyle [00:08:23]: it’s a purpose-built tool for us, and I think the reality is that moving off of it would be so bluntly expensive? Simply because all the tooling is, baked in with that paradigm. And they both have their pros and cons but they don’t work the same way at all. We still use a bunch of different tools Because it’s the purpose-built tools that We need. And then
Swyx [00:08:47]: Well, the same doesn’t go for the rest of Microsoft, presumably.
Kyle [00:08:50]: like the like various teams like operate
Swyx [00:08:53]: They make their own decisions
Kyle [00:08:54]: Various ways. I think it just matters what you’re trying to what you’re trying to do. But we do we do work across kind of every tool that we use, and then by giving everyone access to all of that context and the new WorkIQ MCP server, which is quite cool if you do live in the M365 like world. I can ask it all these backwards-facing questions, and it’s incredibly important for our teams that are working remotely. There’s a lot of stuff you miss when you’re not in an office, and we are spread out all over the world. So most of that is looking back. And then we post, we post either auto-automatically into GitHub issues or discussions, these sorts of like findings or like our industry reports. Like what’s happening this morning, today, yesterday. A little automation gets run. We’ll use the app. We might use GitHub Actions like with, our agentic workflows just to go do that run, and then we push it into GitHub, and w-we keep having a conversation. So usually for us, it’s about that sort of like looking back, looking forward on the non-technical side. And then of course for a lot of those folks, it’s also building an app, pushing it to GitHub pages or pushing it somewhere to host it et cetera. But it’s just like enabling everyone with that power of it’s going to take me a week to figure this out. Instead, we’re going “Okay I built a skill. Let’s put it into a repo. We’ll all share that skill together, and then we’ll use the CLI or now the app-” “just to run it.”
Micro Skills vs. Mega Skills: How GitHub Uses AI at Work
Swyx [00:10:26]: All right. I think, I think we’re going straight into like the team management and productivity thing. I think a lot of people are getting various levels of LLM psychosis. How do you manage the bloat of skills? Like everyone Has their thing, and they’re Like trying to promote it to the rest of their peers in their org, right? And obviously, whoever becomes a skill influencer internally becomes like an AI leader, right? Of sorts. I assume you have those.
Kyle [00:10:50]: like I think we have
Swyx [00:10:52]: And I assume it’s a mess a Yeah.
Kyle [00:10:54]: there’s like I— like I think the reality is there’s two pieces. Like first is I think that we’re ending the era of these like massive, beautiful, perfect skills that are just like not any of those things. ‘cause for a while, right every tweet every day is like go download the skills, the perfectly managed thing to do this entire workflow. And I think that like what we’ve found and what— I was just with my team, this week, and we were talking about the skill side, and we’re really talking about these like incredibly micro skills that are just doing one thing for us very well Versus a skill that’s going to do I said, that full report. That doesn’t really exist on our side anymore. It’s usually how do— like a single skill that’s going to identify the most important marketing information given any MCP server. Like this is the most important thing. Less about stitch a bunch of tools together and have it produce this mega output because then weeks go by, months go by, things change, and you want to tweak
Swyx [00:11:58]: It’s brittle
Kyle [00:11:58]: Your mega skill and you’re screwed? You can’t do that. And so now we’re really just talking about the Legos we’re using and just letting the instruction book be something we’re all putting together. Whereas I think a lot of AI skills for a while have been that mega instruction book style.
Swyx [00:12:15]: I’ve, thought a lot about Postel’s law. I don’t know if that’s a term that is, means things to folks. It’s the idea that you should be liberal in what you accept and strict in what you output, right? And I think that’s like a good framing principle for skills. This is my skills, obviously on GitHub. I feel like everyone should have like how like some repos In GitHub are special repos? I feel like we should sort of reify the slash skills and everyone like give it some kind of special presentation. Anyway, so, yeah, this is one of those like download Download anything, transcribe anything, and then you can string together the atomic skills that do one thing well Into like some kind of orchestration skill that calls other skills. I assume, does that match?
Kyle [00:12:56]: I like I think so. I think that the
Swyx [00:13:00]: Summarize anything.
Kyle [00:13:01]: Like I think the- For me, summarizing something for I do communications and PR and analyst relations and marketing and customer activities, and so my summarize everything is very different for each one of those like Contexts. What ‘Cause if I’m summarizing something for an analyst, that’s a very different thing than, probably how I’m going to summarize something for like a customer meeting or an engagement. So that’s I think like the difference when we’re talking about the like the tools I might use on Saturday or the skills I might use on a Saturday when it’s just for Kyle. Yeah, those are kind of like they have an atomic actual tool underneath or maybe skill, and then Kyle cares about X. But I think when we’re talking about work and enabling the the marketers, communicators there, it’s the atomic, this is what good summarization is, and then this is what I care about as for marketing for communications For whatever. And that I think is like the interesting matrix problem when we go from like a developer set of concerns to all kinds of different professions, is that what that word means to me is different than it means to you is different than it means to the analyst or the salesperson, and that’s where I think the matrix mess is that we’re starting to like still starting to find. It’s about these mega skills but they’re all just slight permutations, but those permutations are really important. It’s the difference between someone reading this and going “Did AI make this?” what Or “This makes total sense, and I would expect this when I’m giving a briefing to Gartner,” or like whatever else.
Swyx [00:14:37]: I think the beauty of it maybe is that you don’t have to be that careful about what goes in there. It doesn’t have to exactly fit as long as it like roughly is contained in there. I used to complain about plugin hell, basically. Like when you have a framework and then you have a hundred things that you need to integrate, everyone does like the GitHub used to be bloated full of these things. And now we don’t need them anymore ‘cause now you just use skills.
Former Developers in Leadership: AI as a Creation Multiplier
Kyle [00:15:00]: And like I think the most magical thing is the just that like I can just also crack it open. Like Like yes, I could go like change the how the plugin is coded, or like I could go do that now with AI, but I think there’s just something more magical about getting a response back and being “That’s not right,” and then you just crack the skill open, you just type English words and it’s different. That building block is just, I think very unique. Once I get everyone to kind of understand how to best how to best make those changes to get the most power out of them.
Swyx [00:15:36]: Is there a— you have a your peer group that Of people like you. Is there a common framing for Something I’m feeling is, which is true, is that is this a golden age for former developers who are now in leadership? Because you can wield the tools, you would know the right words, you’re maybe not too close to the details. Doesn’t matter. But like you’re more effective than someone who doesn’t come from that background.
Kyle [00:15:59]: I think that like the secret has always been your ability to identify patterns and solve problems, and I think that for folks that like myself that don’t code day to day anymore, that has made me successful as a developer, made me successful as a COO and now CMO. And so now that I have access to get and write code, I’m now applying that sort of like pattern finding and problem solving, and I know enough still about how to then go and say, “Oh, I want to make an app, but I don’t want to break into jail or create something that’s not going to be able to work or to be deployed scale or whatever.” that ability to apply all that additional business knowledge and still code I think is what makes that so interesting to me. Slightly different than I think some of the other like technical leaders that became business leaders and now are going back to their apps and updating them. Good for them? But I think the more, much more interesting thing is, well, now I have this whole new set of expertise over ten plus years. Why not take that and use that as a developer with these AI tools? So I definitely think that makes me more powerful, but I think that’s true for like every dev as well. Most of the dev friends I still have also have some other underlying skill and passion. There’s really talented, very kind of linear computer science software devs, absolutely. I just find that the folks that came from a different career, went to school for something else, went off and did this random thing, and then became a software dev, or were a dev, did a random thing, came back. Learning that extra set of information, learning those extra skills, and now having the power of an AI where I can crank up fifteen agents on Saturday while my kids are doing lacrosse, That’s like really powerful. And I think it gets me back to that feeling of like creation, and it’s very hard to replicate that in most other senses? That first time you build an app and you click it and you show someone that’s magical. And so being able to do that not just in code, but across all kinds of different assets that’s, that’s huge. We were doing we’re doing our every year we do our revenue planning. We talk about okay, what is it going to look like for next year? And of course as you imagine, there’s, slideshows everywhere talking about what are we going to talk about, what’s the narrative, et cetera. And so as you said I’m “Okay, well, I could probably just like build something to build this and then that way I don’t have to go build the whole spreadsheet or I have to pass it to my team.” So we went through this process, and I got all the information and used the skills I mentioned. I built like a little app just to make it so I could look at some of the information in a SQLite database, more easily. And I ultimately built this entire presentation without touching any of it and I was “Okay, I’m just going to present this to our CRO, the CFO, their teams,” without mentioning I’d built it with AI. I like built a skill to make it look very much not AI driven. Just not pretty.
AI-Generated Presentations, Human Taste, and the Changing Chief of Staff Role
Swyx [00:19:03]: Like a design. Yeah.
Kyle [00:19:03]: Not pretty. But just like very clearly not AI. Kind of like don’t do anything interesting.
Swyx [00:19:08]: That’s, yeah, that is valuable.
Kyle [00:19:08]: Just go Exactly. We did the whole thing through. It used my notes from Obsidian, it used all the context I mentioned before, the plans, and Never came up once that it was AI generated.
Swyx [00:19:20]: It didn’t matter.
Kyle [00:19:20]: Never once. D It didn’t matter. And so now I take
Swyx [00:19:23]: This is a tool
Kyle [00:19:23]: I can take that tool and go, “Look, I don’t want you to go build slideshows.” They’re just helping us share information with each other. If this thing can do it With a little bit of crafting from you and then we can look at it together, awesome. There’s no value in all that extra work. I think that the ability to, make it look humanly bad and and build a little app to, manipulate the data I think is part of, that upside for devs that are now in leadership roles. Because, the thing that I feel like I said before, this that’s all a people, that’s all a people problem. I know if you’ve used a coworker or not to build a slide deck, unless you spent a bunch of time to not do it.
Swyx [00:20:07]: I know, but like it was so, I think there’s a certain charm to just being blatantly AI. ‘Cause I think that you’re well, you’re just honest about There may be mistakes here that I cannot vouch for. So how much value is there? But anyway I think, actually the real question I want to ask is, there’s a— You were a chief of staff To Thomas. And in the pre-AI world, the that job would’ve been a chief of staff job of like Can you prep me these slides and all that? And now you do it yourself.
Kyle [00:20:35]: I still, I still have a chief of staff. Because, the difference is it’s sort of the discussion every time we have some sort of technology evolution is it’s not that the jobs the roles don’t all go away, they just change? And so yeah, I don’t have someone spending all their time building out slides for me and presentations ‘cause I don’t need that anymore. But now I need that person that is able to go and find all the different connections between humans in those discussions to help me find out, okay, I should be meeting with this group and this team, and they have an opportunity, and I’m going to be in San Francisco today, I’m going to be in Seattle tomorrow. Those sorts of human connection aspects are still incredibly valuable and has always been a big part of that chief of staff role. But now just like chiefs of staff are not opening up, letters to process, they’re doing emails. What It’s the same thing. And now they’re, they’re not building out as many of these presentations because they have the the ability to have a AI take it on for, and share that with me and great. Let’s keep moving ‘cause it’s allowing us to go faster and make better decisions more quickly.
Swyx [00:21:45]: Awesome. Well, so we can dive into more sort of, Productivity insights as you go. I did want to do a little bit of a brief history of colleague and hub. Because, we started here. And then you also involved the NPM acquisition. I did, I do want to touch upon that. And then more recently, I just want to bring up to present day where we’re having uptime issues Which transparently we’ve already Addressed publicly, but we’ll, we’ll discuss in the pod. Did I miss anything? Like what, any other major highlights? Obviously, it’s, it’s a lot of years to cover.
A Brief History of GitHub: Webhooks, Actions, Acquisitions, and Platform Evolution
Kyle [00:22:15]: No the I think one of one highlight was right before the acquisition closed in twenty eighteen, I got to launch the first version of Actions
Swyx [00:22:27]: Oh
Kyle [00:22:27]: At GitHub Universe. So it was O
Swyx [00:22:29]: They’re that young?
Kyle [00:22:30]: It was October of twenty eighteen, I think. Yeah. Yeah.
Swyx [00:22:33]: Gee, Jesus.
Kyle [00:22:34]: I got to I was the engineering leader on that project and got to launch that. And then, yeah, we did acquisitions of NPM you said, Semmle, Dependabot Pul Panda a whole bunch of things. That was a big
Swyx [00:22:47]: Pul Panda.
Kyle [00:22:48]: Abi is doing well.
Swyx [00:22:51]: DX. Holy crap.
Kyle [00:22:52]: Did well on DX. I and like that was a that was the big shift, after the acquisition. I had to join the sort of business side.
Swyx [00:23:00]: So I need to hit you on some of these things ‘cause you were there. Right? And how often do I get to talk to someone who was there? But yeah, Actions. Is that the number one source of security issues on GitHub?
Kyle [00:23:11]: Oh, sh I think that the number one source of, security issues is probably like all, the literal code in everyone’s like underlying repositories. I would say back further than that is, if you remember I had to show in this graph was this is, I’m, didn’t say this before, this is ultimately webhooks.
Swyx [00:23:30]: You yeah.
Kyle [00:23:31]: Like circa whatever it was.
Swyx [00:23:32]: It says Hookshot in there.
Kyle [00:23:32]: I forget. Yeah. Yeah, Hookshot’s in there. And so like back then, it says GitHub Services. Do you see, it says Hookshot FE for front end, and then it says GitHub Services. GitHub Services back in the old days, right? You we had a repository that was Ruby code, and you could write any Ruby code in there, and then we would execute that On your behalf As a service, and then that way if an if you were trying to integrate with something, it didn’t we would run it for you.
Swyx [00:23:57]: And of course no containers ‘cause
Kyle [00:23:58]: No, ‘cause it was
Swyx [00:23:59]: Well, no containers
Kyle [00:24:00]: Twenty fourteen. And so there was some isolation obviously, but it was mostly the separations on the server level. That’s like an example as long as the very old version of Pages, which ran on its own containerization infrastructure, not on Actions.
Swyx [00:24:15]: Which like all-time great product.
Kyle [00:24:16]: Pages powers the internet at this point to some degree. Those were places where like clearly there were no like issues like to my knowledge. But it was those things where I’m looking at and going “Okay, well we can’t be running arbitrary Ruby code,” like on everyone’s behalf. Then containerizing all of that up intoUh into actions now where yeah the containerization, is r-really good. The pinning most folks aren’t pinning it the like to a particular
Swyx [00:24:48]: Images
Kyle [00:24:48]: Sha, et cetera like their workflows, and so that’s a big that’s a big place Of pain for folks if they’re just doing similar to any dependency management, just V1 or newest or latest, I think. But, that journey from that day to “Okay, we’re just going to run all this arbitrary code, and, it’ll basically be okay,” to now, no, we have, really good containerization. We have a new, underlying, ag-agent, containerization, service. It’s like we’re using it under the hood. It’s through Azure. They recently announced it. The Azure, Dev Compute, but it’s, very fast, very fast compute to be able to, spin up your own cloud agents, or whatnot. We’re using it under the hood for some parts of the new,
Swyx [00:25:36]: Microsoft Dev Box?
Kyle [00:25:37]: No. Dev Compute, yeah.
Swyx [00:25:41]: Hmm. Not finding it just yet.
Kyle [00:25:44]: Oh, it’s, it’s in there somewhere.
Swyx [00:25:46]: All right. Well, we’ll cut that out.
Kyle [00:25:47]: Sorry. But with, Dev Compute, you can, run, really fast, spin up really, small VMs really quickly, so you’re doing a tool call
Swyx [00:25:58]: Same concept
Kyle [00:25:58]: Just do it containerize exact-exactly. So we’re using that so definitely moving that direction to protect us from every every piece of code that we’re ultimately running.
Swyx [00:26:07]: look, that grows into the full SDLC? Code hosting was just the start and and then it’s grown beyond that. Let’s talk about NPM may-maybe ‘cause I think that’s also, a very major point in the industry. I do think, it was looking for a home. It was, kind of struggling as a business, right? I don’t know, I don’t know how you would characterize that whole acquisition and how it
NPM, Package Security, and Keeping the Internet Running
Kyle [00:26:33]: like when we were talking to the team, I think the big thing for the both of us was to find a way to keep NPM, which was basically powering the internet then and way more so now to some degree running. Keep it going keep continuing to scale. It was having scaling problems, if I recall, back at that time. They were doing some rewrites. It
Swyx [00:27:00]: that’s cute compared to now.
Kyle [00:27:01]: Well, that’s the thing is like when I’m talking to folks now, there’s there’s so many more underlying uses of NPM than there were back when we had them join in with GitHub. But that was ultimately the goal. It was really okay, we used to have pages. We have, the world’s code. Let’s make sure that we can keep NPM running well for the world. And we put a bunch of time and investment into fixing some of the underlying backend, changes, some of which we talked about some of the manifest work, et cetera. And then now, really trying to bring the the security posture of NPM up to speed. But, it is a unique challenge in that every move that we make to make it more secure will break a lot of people. And security is paramount. And also, we take it very seriously. We’re, the any time that we have a problem with GitHub or we make a change that makes us more secure but hurts, there’s, a snow day for developers or a really bad fire that they have to go put out. And so we’ve, have changed the 2FA policies. We’ve changed the way the tokens work. When we find tokens that have been exposed or potentially, exposed, we invalidate them, and
Swyx [00:28:22]: I love that feature in GitHub. Yeah, it’s great
Kyle [00:28:23]: That creates issues, but, the but that’s the thing is we’re trying to push the community, forward without necessarily, doing something that is going to break the contract that’s been for 15 years or close to it or some amount of years on NPM.
Slop Forks, Vendoring, and the Future of Open Source Supply Chains
Swyx [00:28:43]: I think the— So now we’re talking about, open source and publishing. And I think there’s something here with what people are calling slop forks, which, I think Malta from Vercel is doing. And, part of me thinks, well, the way to get past any vulnerabilities, we just, let’s just get rid of the concept of NPM. And we only publish source code. And anytime you want to import it you have your coding agent look at it and then adapt whatever subset you’re going to use into your vendor it. But, the AI vendor it. Is that realistic? I don’t know. Is it— Will that solve all our security issues? I don’t know.
Kyle [00:29:24]: I don’t think it’ll solve I so Mitchell was just talking Mitchell Hashimoto Was just talking about this today, and I think that I-in some ways, it’s all all things, old or new again? Yeah, absolutely vendoring everything. Like I do I do remember twenty thirteen, twenty fourteen.
Swyx [00:29:42]: This is Yeah. Let’s, we must return to
Kyle [00:29:43]: That’s what is We were vendoring everything. We were having actual discussions around, or at least I remember we were “Should we take this full thing?” “Why is this so big? We only need this one file.” And so I do think there’s something true there where having either taking only what you need or the dependencies just getting incredibly small over time, I think will help to some degree, but it’s not going to solve the fundamental problem, I don’t think, because the vulnerabilities in an agent looking at them, there’s time and time again, there’s a million different ways in which we can convince an agent that this thing is, secure or not and pull it in. Or we can do static code analysis or runtime testing to say whether the code works or not. That is, I think, the step that needs to continue to be, invested in. The question is just on, how much scope. Should it be this enormous project that I’m pulling down, or should it be this piece? Either most companies are running some amount of security checking on the on the packages that they’re bringing in or vendoring. That I think won’t change. That’s like what advanced security does to some degree, Socket does some degree. Like everyone is doing a piece of that. How we each do that like especially when we’re talking to enterprise customers, is just like very different. No there’s no one wants one single way to do it. And I think that’s always been GitHub’s, unique position in the world. I talk a lot to maintainers, I talk a lot to folks about this. It’s we’re— we rarely start like a process and a practice and like push it onto the community. We usually wait for the sort of like RFC process socially or literally, everyone agreeing, and then we’ll cement something in. Because otherwise we’re
Maintainers, RFCs, Vouching, and the Social Layer of Trust
Swyx [00:31:35]: That fits your role in the ecosystem, yeah
Kyle [00:31:36]: We’re GitHub. Yeah, we don’t want to shape the whole thing. We want it to be figured out. But like how do you balance that like sort of Role in the industry to keep everything as secure as is possible and make sure that you’re you’re not going to be compromised as a human, ‘cause that’s usually how it all happens. And Not not create a process or lock us into a flow that you’re not going to or like Mitchell’s not going to or other open source projects aren’t going to like. That’s always been a tricky balance for us, and I think that’s something that we haven’t talked about enough is we’re not going to be able to fix everything for everyone in a way that everyone is going to like. So tell, help us, tell us what is working. When Mitchell was talking about, the Upvote, the up
Swyx [00:32:22]: I was going to bring up his thing. Yeah.
Kyle [00:32:23]: I forget what it Yeah. When he’s talking to us, I was chatting with him and talking to him about this and I put it on Twitter and we talked to, also over DM, was “We’re going to keep working.” but I think the important thing is I do actually want to hear what isn’t working for you. And as, be as specific and clear for your project as is possible. And to every piece of credit over the many years that we’ve known each other through the industry, he’s always done that and I appreciate that ‘cause there are places that we need to fix up, and we hear from him, and we’ll fix up just like we do all other kinds of maintainers. But that that process between making those types of improvements and being more secure and like creating, I forget what he calls it’s not the proof process, not the claims process. Do what I’m talking about? He has that he his projects have a way for you to kind of like,
Swyx [00:33:13]: Vouch
Kyle [00:33:13]: Vouch. Thank you. Yeah. He has like the vouch system for saying, “Hey, you should accept my PRs.” That’s been
Swyx [00:33:20]: I just built this into GitHub. I don’t know.
Kyle [00:33:22]: Well, see, but that’s the thing is that you say that and like he and his community really likes this and then I’ll go talk to other maintainers and other maintainers, globally, and they’re “No, this doesn’t work for me.” And that is the tension, but also the kind of beauty of GitHub, depending on which way you look at it is we want to help maintainers, so we create all these tools to let you have more control over how much you take in from AI and PRs. But you can also use this. What You can go use this project, and if it takes off and becomes the kind of mostly standard, then yeah, we probably wouldn’t enforce it but we would add it in because that’s the flow that we tend to do?
Swyx [00:34:02]: I hear a lot of people don’t know the history of the pull request. And like like that’s how, that’s something that GitHub standardized basically.
Kyle [00:34:08]: Yeah. It was a very messy process Like beforehand, and now the we have the benefit of it being the process? And now we have to go and Figure out the next best process or what adaptations change, or what does a pull request look like when eighty percent of your PRs are just coming from your agents and not From other devs?
Swyx [00:34:31]: Do you like the prompt request idea from Peter?
Kyle [00:34:34]: like I think that for each like each idea I think has its merits. I’m not, I’m not avoiding saying anything good or bad, but I feel like I’ve seen a version of we have that we have entire Thomas’ store. Take all the assets of what you’ve built and put that in. I think that’s got great ideas. There’s all these various permutations of the PR flow, but I think the reason why there’s not a single answer is ultimately we’re trying to codify trust. We’re trying to say “Okay, if Sean reviews this I’m going to trust it because you’re Sean or you’re the senior dev or you’re the whatever.” And right now, when we are working in a flow where an agent writes code and another agent reviews code and then Kyle goes and looks at it the trust is kind of diffuse. And most of the tools that we’re talking about are talking more about verification flows. We have more assets to look at, so I can probably say whether this is a good PR or not. But that still doesn’t solve, I think, the human problem of I’m looking at a PR and I want to know if I can trust it. And we’re still, we still tend to use human signals for that? Mitchell approving it or Kyle approving it or whatever. And so I think that’s, I think that’s why most of these options haven’t really solved it is because, it’s a social problem ultimately. It’s a it’s a human problem to review it and agree. Or you fully trust the tool and you’re imbuing that tool with full trust Which I think in some cases that absolutely exists.
AI-Generated PRs, Trust, and the Waymo Analogy
Swyx [00:36:08]: And so like in the same way that there will be a tipping point in society when we don’t allow humans to drive anymore Because machines are measurably better than Than humans. I’m looking for that tipping point, right? Like Mythos is ridiculously expensive. Someday we’ll have Mythos on a desktop. I don’t know. Will, does that change the equation?
Kyle [00:36:30]: I think it’s more I took a Waymo here, and I was on my phone and not looking around at all. There are other, self-driving, vehicles that I would not trust while, staring at the road. And I think that trust is something that is
Swyx [00:36:48]: Is this a Zoox thing? What is it
Kyle [00:36:50]: I think that is both. I think that is both. Like
Swyx [00:36:53]: There’s Zoox in this robo taxi. That’s it. It’s
Kyle [00:36:56]: Well, depending on what level Of self-driving. But, my point is sort of that I think part of that is I strongly believe that’s, a mixture of verifiable proof. Like how many accidents, how much data, and so on, and the human aspect of how I feel when I’m in this car, what it tells me, et cetera. And so that’s why I think some of the like Some of these some of our AI tools tend to, imbue me with more of that feeling of trust, even if the data says this is 100% accurate. I feel like it takes more time for us to go, “Should I trust this or not?” And that’s in the soft sense of, startups with high agency, weekend projects, and open source. And then there’s enterprises and regulated industries and everything else, and that is an even harder problem to go solve because even when it is fully verified, not only do you have to have trust from the humans on the team, you probably have to have trust from multinational,
Swyx [00:37:55]: Oh my God
Kyle [00:37:55]: Multi governments around the world and regulating agencies. And so that’s where I feel like until we tip over to your point on the sort of like human EQ side of it. I feel okay this feels okay I’ve been proven enough. Then the ball will start to roll a lot faster, where we’ll end up getting to the “Okay, we can trust this,” and feel good about it in the Most difficult of cases.
Reputation, Sponsors, Stars, and Bot Activity on GitHub
Swyx [00:38:18]: If human trust is the thing that matters, I feel like GitHub as the developer social network could maybe do more there. Like vouchers are one system But, we have star counts, and then we have Contributor rights, and that’s it. And I feel like there should be more in that space. I don’t know if there’s any other design decisions there.
Kyle [00:38:37]: I think that one of the places that we don’t really expose right now in this sort of way is, some degree of like hard trust and support, which would like for me is like sponsors is a good example of that.
Swyx [00:38:49]: Ah.
Kyle [00:38:49]: It like costs you something. To prove that I believe in your project and I trust you To some degree or I want to support you at the very least.
Swyx [00:38:56]: Solve payments for open source. Why not?
Kyle [00:38:58]: I think that I think that like as we keep moving forward, right, there’s more and more projects where I’m, adding more and more dollars into sponsors personally because I want to like support them, but I also like know of I’ve probably never met them in person, but, I know of enough of their work that I want to support them. I think the thing that I don’t love about stars or commit counts or anything else is ultimately, even with all of the various, abuse and de-spamming and deduplication work that we do or anti-abuse work that we do, these are all, not active social signals. They’re passive ones that are ultimately gamifiable. And you may trust me, but another open source maintainer may not. And on what heuristic should you be, trusting me? That I think, is kind of where some of our thinking is right now. What signal from me is most important to you? You— If you can define that potentially, honestly in an agentic workflow that’s what we see some of these open source projects do, where you have GitHub actions, and then you have like an agentic workflow that’s calling AI, and you’re setting these rules. Like if Kyle has submitted and gotten accepted PRs across any given project and has a social handle tied to his account in GitHub, and that social account’s older than a certain amount. Really complex measures that matter to you ‘cause most open source projects have that heuristic built into their heads, if not written down in the contributing guidelines. You could take that and then go apply that and then just say, “Oh, we’re not going to accept this PR.” Building something that is, I think, malleable to everyone’s needs, is a little bit better, rather than going “Hmm, this account’s too young.” Because what happens? The attackers just go and go and create a multitude of accounts, and they wait Until it ages up. Needs to have a certain amount of stars. That’s how star inflation happens. Need to have a certain amount of repos
Swyx [00:40:46]: Oh my God. Yeah
Kyle [00:40:47]: With PRs. They all just create repos and submit PRs to each other, and then they come in and do something nefarious. And so, it’s hard. It’s hard to find the measure. So I think we’re, we’re looking more at how can we provide you tools so you can kind of choose what’s best for you. And of course, we’ll give you some standards. But the trust vector, gets down to I don’t know, some version of like human digital ID like everyone’s been talking about. Like how do I prove that it’s me
Swyx [00:41:13]: Give me your eyeballs
Kyle [00:41:14]: On the internet. Give me your eyeballs. Exactly.
Swyx [00:41:18]: The I got to keep moving on Topics, but obviously I can go all day on this stuff because, I’ve been involved in GitHub and open source My entire professional career. Stars. Very superficial. Everyone knows it. But I think time to one hundred thousand stars is the fastest I’ve ever seen. Like people just reached that in I don’t know, months. And then like at the same time I don’t trust it right? Like how many of these are real or bot or like whatever. I don’t know how to ask this but like what can we do about it? Like
Kyle [00:41:49]: Just
Swyx [00:41:49]: Is stars broken? Is stars fine?
Kyle [00:41:51]: I think that there’s kind of two, there’s like two pieces. Obviously we’re constantly like trying to find ways in which like your users are producing spam, which would, I would include like be like only doing star gamification. When we find them, we pluck ‘em out and we,
Swyx [00:42:08]: But it’s like a Whac-A-Mole
Kyle [00:42:10]: It’s a hundred percent like a Whac-A-Mole
Swyx [00:42:11]: There’s no way
Kyle [00:42:11]: Now, powered by AI to be helpful. But I think more so what I’m seeing is, a lot of the like fastest time to X tends to be because we’re now inviting so many more people into like software development on GitHub That like the zeitgeist is just swarming? And it’s
Swyx [00:42:32]: It’s not just developers anymore
Kyle [00:42:33]: And it’s not you and I. Like like however you want to say like what a developer is it’s not just folks who have been coding for a very long time. It’s folks that have maybe started coding or only joined in since the AI era. And now
Swyx [00:42:44]: what’s the latest Octoverse number? I know eighty million was my lastRem- member that a number of developers on GitHub
Kyle [00:42:50]: Oh, we’re over 200 million now.
Swyx [00:42:53]: Okay. Well, so you see?
Kyle [00:42:55]: Like over 200 million developers now.
Swyx [00:42:56]: But it’s not developers, right? It’s, it’s people with a GitHub account.
What Counts as a Developer in the AI Era?
Kyle [00:43:00]: So, so this is, this is the biggest debate that I would say, everyone loves to have at GitHub at this point. From my perspective, right, I think that there’s, there’s clearly a difference between, professional enterprise developer and then developers. But I think that I think that the idea that we should be I don’t know, splitting hairs or segmenting developers in the early era of software development is, not worth our not worth the time. So
Swyx [00:43:29]: When you get into gatekeeping
Kyle [00:43:31]: 100%
Swyx [00:43:31]: What is a developer?
Kyle [00:43:31]: 100%. ‘Cause I wasn’t a developer when I started writing code? I was going to
Swyx [00:43:36]: Oh, no. I made— I cloned a thing, seven years before I learned to code. And then I and then I wrote about my learning to code journey, and people Just called me a fraud ‘cause I had a GitHub account. And I’m “Well, no, I just use GitHub, but I don’t know-” “I didn’t know what I was doing.”
Kyle [00:43:49]: I I remember that. I remember those sets of posts, and like that’s, that’s bullshit. So I fight very clearly on the line of, if you create code, if you have an idea and you create it into some way of, I’m, I’m going to run it and use the app right now, you may still use AI in that moment, but that’s okay. At some point you’re going to do the next thing. You’re going to create a big— You’re going to have to learn about this database. You’re going to fix a bug, whatever. We’re all on some same journey, and those people are also hearing about the great new agent skill package or a new CLI tool or a new whatever. And those projects are going up because you want to be a part of this moment, just like I wanted to be a part of the Ruby community when Ruby was popping off when I started becoming a developer, and now I can just click the star button. And so I think that yes, there’s clearly some amount of like spamming and game gamification that we’re working against, but I really think we’re just seeing this whole new cohort of folks that are moving from technology to technology because they’re not working on a 20-year-old software application. They’re working on a side app that they built on the weekend for their friends or for their new idea or whatever. And that’s how you see these enormous charts going up and to the right with With stars.
Swyx [00:44:59]: I think something that’s remarkable is the persistence or, that GitHub extends to those folks. Usually when I see platforms go into a new audience, they usually have to, have like a second platform with a different name that wraps the main platform. But somehow GitHub has been able to sort of persist and extend, and it’s friendly and whatever? So it’s, it’s nice.
Spark, Low-Code, and Always Showing the Code
Kyle [00:45:19]: I that’s partially why I think as we’ve tried to move into I don’t know, more like low-code-y things. We so we started working on Spark as like a way to, build an app and run it. I think that the reality is that we anytime we try to, kind of put even a veneer on top of it without when we put a veneer on top of something, we still always show you the code. That’s kind of like a tenant. We’re never going to, hide the code from you ever, because what
Swyx [00:45:52]: Why would you?
Kyle [00:45:52]: That’s, yeah, that’s the whole point? However, I think that what we learned with things like Spark is that really the value of Spark for most devs is, easy runtime. And you may have a runtime or a host that you’re going to use for that or you just build something and run it but, the package of making that even more simple isn’t really needed for folks that are trying to build software and not just trying to build, an app, which is, slightly different, a slightly different goal. So I want to get you in, I want to get you comfortable. I think the best thing for me as, someone that did not traditionally come into software dev way back, I want anyone to be able to breach that chasm and not be in the I don’t know, I feel like we’re, we’re still in an era of, STEM. I’ve got a 12-year-old and an eight-year-old, and it’s “We got to get ‘em into STEM,”? Over and over. And I like I do, I do the things that good parents do. I was “Oh, you want to do coding?” “Yes, I want to do coding.” Do coding classes. But now they’re just not afraid of doing software. And that’s, I think, the thing that’s honestly kept me at GitHub for so long. Anyone should be able to go and build a thing, just like I can go change a light switch in my house. I’m not going to go into the breaker box ‘cause I’ll probably kill myself? But, I can go change that light switch. Everyone should be able to go and say, “This fricking app doesn’t do what I want. I want it to work like this.” And that I think, is what’s kind of kept us all connected with GitHub through the years and some and during the easiest of times or in the hard times because of that opportunity of, we’re the home for all developers, and we want everyone to be able to have that feeling that we’ve had of, had an idea, I created it and holy shit here it is.
Swyx [00:47:37]: Here it is. All right, I’m going to try to do more spicy questions.
GitHub’s Hardest Scaling Moment: Growth, Agents, and Uptime
Kyle [00:47:42]: Great.
Swyx [00:47:42]: Is it an easy time now or a hard time?
Kyle [00:47:45]: Oh at GitHub? It’s a hard time. Like, it’s a hard time and also, I was just with my team and I said, “This is also, the best and most exciting time that I think I can remember at GitHub.” Because
Swyx [00:47:57]: Best of times, worst of times. It’s never one
Kyle [00:47:59]: ‘cause we’ve we were talking about Octoverse reports and, usually we do an Octoverse report once a year, and we look at the numbers, and we say, “Oh my goodness.” I was at Universe in October saying, “This was the fastest year of growth that we’ve ever had,” right? And now we’re doing more in a month than we did in a year last year.
Swyx [00:48:20]: You’re talking about PRs.
Kyle [00:48:21]: Commits.
Swyx [00:48:21]: Commits, yeah.
Kyle [00:48:22]: PRs. Kind of like you name it by roughly every measure that we’re looking at, there’s some amount of sort of growth that is much bigger, and that is breaking our system in new ways, not old ways. Like webhooks were always notoriously, unreliable over the years?
Swyx [00:48:38]: Whose fault is that?
Kyle [00:48:39]: not anymore mine, but for a period of time, I’m sure you could pull up a tweet that was “It was me. I’m sorry.” but, now, that got rewritten at a scale level that is still working and is not having problems today. Now what we’re finding isn’t just the isn’t the-The simple stuff that folks are on the sometimes on Twitter or on the internet are “Hey, why is this like this?” Sure. There’s absolutely silly problems that we shouldn’t exist. But now we’re talking about, unique, novel permission problems that happen only at a scale across all different objects or whatever, that now we have to go rewrite this underlying system. And so it’s, there are problems that yeah, caught us off guard, which I think I said. Like the growth is astronomical, but also we’re making such material progress in that I’m excited once we’re once we’ve kind of like reimagined the underlying foundation layer, or pieces of it at least, what’s going to be possible when it’s not just all of us and all the new people that are being developers and all of their agents and all the tools like working together. Because that’ll still happen in that in that GitHub tool, that GitHub community. But it’s a it’s a hard day anytime we can’t give you what you’re looking for. We have the same problem internally. We operate through github. Com. Of course, we have backups when things go down and whatnot for our own operations but we feel it too. If it’s not working it’s not working for us, and that’s kind of like the promise of dogfooding for GitHub. It’s always been true. We’re using the same tool you’re using. We’re not using a super secret version. We and so we also need it to be great for us for our customers of course for open source. And now an exponential growth of agents, Doing it too.
Swyx [00:50:32]: I wanted to load for audio listeners who maybe haven’t seen your tweets, whatever. So one billion commits in twenty-five. Now it’s two hundred and seventy-five million per week on pace for fourteen billion this year, if growth remains linear. Is that still the pace? I don’t know. It’s been a
Kyle [00:50:48]: it’s, it’s speeding
Swyx [00:50:50]: Roughly.
Kyle [00:50:50]: It’s still speeding up.
Swyx [00:50:51]: It’s, it’s April, so yeah.
Kyle [00:50:51]: Exactly. This was in April.
Swyx [00:50:53]: All right. So basically you have fourteen x growth, right? Year on year on year. And I think that’s a scaling issue. I think, I’m going to like try to really steel man this thing. People have experienced fourteen x growth. They haven’t had your downtime. And that’s like— C-can we go dig into that? Why? Like what’s the— what broke? What are we doing to fix it? Like just anything for the community to reassure them.
Why GitHub Reliability Is Breaking in New Ways
Kyle [00:51:18]: so there’s a Like I was saying, there’s a couple different places that we’ve seen the growth issues. Some of the growth issues, which is why we’re t— I was talking about pushing hard on more CPUs is in actions in particular. More tools, more agents, more PRs mean more builds, more builds mean more CPUs. And so we are expanding through not just our data center, but obviously we were talking about moving to Azure and moving to, adding an additional cloud compute because we simply need more CPUs. Not as much GPUs. We definitely need GPUs too, but now CPUs are becoming a factor.
Swyx [00:51:53]: It’s very CPU heavy.
Kyle [00:51:54]: Underneath the hood when it comes to some of the underlying services, we’ve been breaking up over the years our database infrastructure, so that way we have, more cognitive separation between our the various services. The place that we continue to have pain is in, permissioning. And so right now m-many of our permissioning layers sit into a database that we like internally call MySQL One, and old Hubbers will know what I’m talking about. And so we’ve been pulling things out of MySQL One for many years, because like and we use we use Vitess and we use other technologies to shard and we do it as one big
Swyx [00:52:31]: Famous thing, PlanetScale was born from this and
Kyle [00:52:32]: A hundred percent. Sam Old Hubber and friend. And so finding these opportunities to like break this out and then do that globally. The other thing that I think is interesting and both a unique opportunity and tricky is we also run everything I just talked about in a black box container with GitHub Enterprise Server for people that work on-prem. So we take everything I just said, and we also do it on-prem, and we also do all of that and we do it in a data residence setup for customers that need to have their data in a single location. Each of these has the unique characteristic around how we’re sort of storing that data in MySQL or in a permissioning setup. That’s where some of these outages have oc-occurred, where you’re seeing it more like across the board rather than just like the one piece
Swyx [00:53:17]: Filling the database
Kyle [00:53:17]: Isn’t quite working. Exactly. And so part of it is that. I think there’s been some other places where agents are much more or more projects appear to be moving towards monorepo versus we were going the other direction for many years in the industry. Repos were smaller, but there were more of them, and now we’re seeing the opposite. Repos are bigger, and there’s, not fewer of them per se ‘cause there’s new growth, but, we’re just seeing many more big repos. Big repos, big monorepos have always had, a unique performance problem. Because each one, is slightly different if, particularly if the underlying blobs are incredibly big Inside the repos. And so we’ve done a ton of work that you pro— like most people haven’t probably experienced, unless you’re in this case of the monorepo. But that Git, infrastructure layer improvement does help the overall, system because, many of the improvements that make monorepos work better make all repo infrastructure work better. And so, I could kind of keep going down the line where it’s another thing where we’re moving out of, We’re changing how we do j I’ll just say job queuing for lack of a better, explanation changing the underlying technologies there.
Swyx [00:54:32]: I spent two years being a job queuing guy, so.
Kyle [00:54:34]: And so it’s kind of a little bit of a little bit of piece by piece, and it’s mostly because as we were— as it was built, we built everything in a way that assumed, I guess in some ways that the size of the pipe of work was going to remain the same. There’s just going to be more people coming through each of those pipes. But instead now in places whereA git push was, generally a certain size for example, is now, no longer true.
Swyx [00:55:03]: Oh, yeah.
Kyle [00:55:03]: Or
Swyx [00:55:05]: I push a thousand
Kyle [00:55:06]: On the average. 100%
Swyx [00:55:06]: A thousand line commits like daily
Kyle [00:55:07]: Same thing with PRs. Like PRs same thing. And like we’ve talked about optimizing that and making changes where, and there were technology choices that did not work there? And it got slow, and it didn’t It was not fast. It did not do what the users wanted. And so we’ve been reeling that all out and going “Okay, that’s just not right. Let’s stop putting good money after bad and do it the do it the right way or the right way now.” So there’s It’s a it’s a lot of things, not quite when I’ve experienced scale at GitHub historically, it’s almost always two options that we’ve used. We go vertical scaling, particularly with databases, right? And we go horizontal scaling. Oh, we just have more people using this service. Great. We’re going to add more servers, and we rack them in our data center, or we use it in a cloud. And now we’re sort of in a like diagonal, where like vertical doesn’t really work anymore. Horizontal isn’t work either because we’re all We all have some CPU or GPU constraints in the world now, and now we have to go in and like crack open services that have been running for 10 or 15 years and go, “Okay, the rules of this service have legitimately changed, and now we have to rewrite them.” None of this is an excuse. This is like we’re We have to do the work. We have to make it better.
Swyx [00:56:22]: actually as an infra guy, I’m “This is like one of the most fascinating scaling challenges I’ve ever seen.”
Kyle [00:56:26]: That’s that’s, that’s the thing that’s the thing that it’s hard for Like when we weren’t talking about it publicly, and I was like I came out, and I was “Hey, I just want to explain what’s going on.” Part of it comes from a very old GitHub ethos, which is it’s our it’s our uptime. It’s down. W What I know you’re a developer, so you’re, you’re inclined to want to understand more what’s going on. But at the same time us going “Hey, this service didn’t, perform the way we expected, and now we have to go change it,” we weren’t We’re not trying to hide anything from you in that. It’s that well, that’s our problem because you expect us to be up, and I think that’s really baked into the core, origins of GitHub. And so now what we’re trying to do as a team is do all that work and just tell Talk about it more and just share you more technical details, write these blogs, write the posts, get the engineers who built it after they finish the work, just tell you “Okay, this is what we did.” I think that’s the contract that we want to bring back to the community and say, “Hey, we’re still very serious about what we’re doing. We haven’t been telling you about each piece. So let’s do that and we’re going to keep building this and scaling it in a way to support the If it’s not 14, then it’s 30 or it’s 50 or whatever the next exponential growth is going to be.”
Swyx [00:57:40]: First of all, fantastic answer. I think
Kyle [00:57:44]: And I apologize in advance if like any of that
Swyx [00:57:47]: I think it’s all nice
Kyle [00:57:47]: Is slightly incorrect just simply because
Swyx [00:57:49]: No
Kyle [00:57:49]: I’m not the I’m still in the weeds with this but it’s not my day-to-day. But like that’s the thing is we’re all looking at it to that level.
Swyx [00:57:58]: And obviously, if people want to help, they can join.
Kyle [00:58:00]: Absolutely
Swyx [00:58:01]: So like I think the that is, good. I think people also would just want to know when are, when are you through the thick of it right? Like is there Have we identified all the issues? Is this just never-ending? Is Git broken? Do we have to change the Git, protocol? Like what how much is breaking, right? It’s been a while. And so I think people do want to know What’s the path back to the reliability that everyone expects out of GitHub.
The Reliability Roadmap: Databases, Compute, and Load Testing
Kyle [00:58:30]: So like our availability in like recent few weeks has been much better than the three weeks before that or the three weeks before that and so forth. And so a lot of these improvements are still very much paying off for us. I think that we’re still working on that that database piece that I mentioned, and that just is a little bit physics a little bit of time to get it to get it fixed up. Because we have to the w
Swyx [00:58:59]: My the answer I had in my head Was call YouTube.
Kyle [00:59:03]: So YouTube ultimately is
Swyx [00:59:04]: ‘Cause they also use Vitess.
Kyle [00:59:05]: They also use Vitess. But the,
Swyx [00:59:09]: Like whoever was the guy, the scaling guy at YouTube?
Kyle [00:59:11]: Like that’s That I believe went to PlanetScale, and was a part of PlanetScale too. But like
Swyx [00:59:16]: Oh, you mean Sugo?
Kyle [00:59:17]: I think so. Yeah. And so, and so like
Swyx [00:59:19]: He’s at Superbase now.
Kyle [00:59:20]: Ah.
Swyx [00:59:21]: There’s a whole Postgres drama Thing there, right?
Kyle [00:59:25]: So like some of it’s that. I think the other piece of it is, our move to get additional compute will alleviate a fair amount of this particularly on the action side ‘cause a lot of the underlying, outages is actually related to,
Swyx [00:59:39]: I’ll tell you actions is the it’s the root of all evil.
Kyle [00:59:42]: it’s all It has its pros
Swyx [00:59:47]: Some extent
Kyle [00:59:47]: In that it’s the core It’s the core compute layer for either CI, side projects, et cetera.
Swyx [00:59:52]: Is the main money maker? Like is
Kyle [00:59:54]: Actions?
Swyx [00:59:55]: No? I don’t know.
Kyle [00:59:56]: like Actions
Swyx [00:59:57]: I pay a lot for compute, right?
Kyle [00:59:58]: like Actions is definitely a piece of the overall business, but I would say that like we ultimately also
Swyx [01:00:06]: Storage
Kyle [01:00:07]: Give away so many like minutes as part of our entitlements as that. But that’s what I was saying. Everyone’s using it. We talk about it as CI/CD, but the reality is people use it for CI/CD and
Swyx [01:00:17]: Automation
Kyle [01:00:17]: Various processing and automation, exactly. And so like part of it is also that like compute piece that is also alleviating some of our availability.
Swyx [01:00:26]: This is my abuse of, actions. I have been
Kyle [01:00:29]: Oh, yeah
Swyx [01:00:29]: I have been scraping for every day, and just like I just tell people to
Kyle [01:00:34]: Thank you for your service
Swyx [01:00:35]: Go dog because I But this is also how I track, actions all time. So anyway,
Kyle [01:00:41]: So like some of it’s going to be that. I would say that like each month I expect in the next three months, you’re going to see fewer and fewer moments where we have an availability problem Where things are going to go down, and that’s not just it’s stopped. It’s that we’re still experiencing faster growth than ever before. It’s just that those underlying improvements that we’ve been hard at work on, are finally paying off. It’s just that the improvements take-It’s less about, these incremental improvements where you make a small change, and you get this big output. It’s now material change That takes a bit of time, and then you see a step change in our availability.
Swyx [01:01:14]: There’s a thing we used to do at Amazon, I don’t know if this is, a thing, but, if automated software verification or simulation of load testing and all that. I’m, I’m just like at this point, you have a whole map of GitHub. And, while you can assume whatever growth rates on whatever dimensions that you care about and just run it through a system, right? I feel like there’s a way to, I don’t know, have a systems model of GitHub and, see what breaks. But obviously, I’m pro— I’m not that close to the problem, so.
Kyle [01:01:39]: But yeah, so yes, totally. And I would say, that’s been the journey and work that’s been happening since, I would say November to now. Because October, right, was the time where we even said, “Oh, look at the growth,” and, and then you start to see the chart
Swyx [01:01:53]: It doesn’t
Kyle [01:01:53]: Really pick up. And it’s oh, we tested it at N amount of scale, and now it’s at, N cubed maybe like in some in some vectors. And so now we have to go and build it that way and make sure that it can handle all of that scale.
Swyx [01:02:08]: Let’s talk Copilot. So how many original creators of Copilot are there?
The State of Copilot: From Code Completion to Agents
Kyle [01:02:15]: Oh, geez.
Swyx [01:02:18]: ‘Cause I count like twelve authenticated.
Kyle [01:02:19]: We haven’t— Yeah, I forget, all joking aside, I forget the number of people that were on, the original, GitHub Copilot team. But, there was a bigger group.
Swyx [01:02:30]: I heard it’s, it’s Alex. It there’s, there’s, a three people
Kyle [01:02:32]: Alex worked on it. Udo worked on it. There’s a a bunch of people that were on the team.
Swyx [01:02:35]: And then their entire management line. Okay. So enormously successful at its in its in its day. I think the last number, I think Mario Came to my conference, and talked about the hundred million dollar mark. I think most recently three hundred. I might be out of date as well there.
Kyle [01:02:53]: I don’t think we shared the dollar amounts.
Swyx [01:02:54]: All right, cool. Just, what’s the state of Copilot? It’s, it’s obviously as a concept brought into More of Microsoft. But just at GitHub.
Kyle [01:03:03]: so I think One of, one of the challenges is, that we had with Copilot, right, is that we came out the gate with code completion, and it was super great, powerful, et cetera. And then what we initially worked on after that sort of, initial year and a half, was, going after fine-tuning because our customers, the industry on the whole was really talking about, okay, well, how do we get more more correctness or performance out of this? And so we were working on a whole bunch of efforts to do fine-tuning on, larger and larger code completions or, next edit suggestions with fine-tuning, et cetera.
Swyx [01:03:43]: And let me clarify. Is this fine-tuning one model or per customer a fine-tuned model for
Kyle [01:03:48]: Per cust— Well, both. But, but, fine-tuning one model for the overall, use, and then fine-tuning per customer that wants this as, a service effectively. And around that time is when the next generation of models came, and that’s around the same time that all these other AI, coding tools came to be because the models really sped up. And so everyone kind of, will ask, “Well, what happened to GitHub Copilot?” there’s all this time, and I would say that we were on an era of going okay, we want to improve everyone’s results, and so let’s focus in on fine-tuning because that’ll give us these better results. And then the models got better. And so then ever since, we’ve been really on this kind of journey to go, okay of course, we have, this great code completion, and we’ve done a ton of investment in the better underlying models that we have post-trained better, next set of suggestions with post-training language specific models. All this stuff that kind of, sits in the ether of GitHub Copilot is code completion, but also have now ha— now have, a single underlying, SDK and harness for our coding agent Copilot ultimately. The new CLI, the new desktop app, cloud agents that use the same SDK. And so there was this moment of both, really trying to figure out what our customers want, models, Sherlocking us a little bit, then going and saying, “Okay, what does everyone ultimately need?” And what we think is that it’s not solely about the code generation. It’s really about having the ability to use these coding agent brained, harnesses or run times across, not just the coding experience where I’m going to, send a bunch of tasks out, or I’m going to use Fleet to break up a single task or autopilot similar to Goal all this stuff. But also how do I do that for all of my security remediation? How do I do that for every GitHub issue that comes in, just stick a coding agent on it just to see if it’s possible? How do go through my repository and see all of my documentation and extract out okay, this doesn’t actually match? That amount of sort of AI coding agent automation, I think is a big part of what we see when we’re looking at, okay, we’re still kind of going through a similar but very different flow. It’s just all happening at the same time. There’s not really the same, I’m going to create an issue to track my idea of building this. You’re probably just going to go, do it.
Swyx [01:06:22]: Just do it.
Kyle [01:06:22]: You’re going to say, “Hey, just build this,” right? And, there are still tons of, open issues and projects, et cetera, that are using issues like Peter and OpenClaw to be able to sic all of his agent on that. That kind of infrastructure layer and a really great coding experience that allows you to handle the sort of multiplexing, aspect is what we’ve built, are still building with GitHub Copilot. And so for folks that haven’t really used GitHub Copilot sinceThe thing that got them excited about this Which I I get. I really encourage you to, look at especially the GitHub, Copilot app. That’s my new daily driver. I obviously, if you prefer the CLI, also the CLI, be able to use all the models, the bring your own key side of it. We’re still improving our own models and using those too. And, it’s just like a very different experience, but I think that broader sense is of like software development and how coding agents can help throughout, not just Writing the code, or even verifying it or deploying it is is where we have this unique, angle. The other side is the context piece. Like
Copilot’s Future: Context, Taste, and Personal Developer Workflows
Swyx [01:07:44]: Oh, God
Kyle [01:07:44]: we’re still It’s like one of those things where I think the the final thing that will let me ultimately, feel complete at GitHub is, when we have this ability for GitHub to act like Kyle wants it to act Or Shawn or whatever. And we all codify that in rules and in memory and everything else, but
Swyx [01:08:03]: Well, that’s an open research problem, right? Like it’s
Kyle [01:08:05]: A hundred percent. A hundred percent
Swyx [01:08:07]: AGI when you get it. Yeah.
Kyle [01:08:07]: A hundred percent. But, if we can even just do it where my team, Without me having to codify everything, and as our methods shift on purpose to be able to have that full experience and all the understanding of what’s happening in my dependencies or open source, that feels like a big place for us to be able to continue to provide something really unique and valuable with GitHub Copilot.
Swyx [01:08:29]: Is there a form factor that we haven’t explored? I think like we did code completion Then we did kind of let’s broadly call it agentic IDE Which Cursor Famously popularized, and then now it’s, now it’s all about the sort of agent orchestration Background agent, whatever. And then there’s the security review. I feel like everyone’s like just throwing agents at everything. The entire SDLC has Just, covered with agents. Are we like at the end of history here, basically? Like is it just refinements from here on out?
Kyle [01:09:04]: I think that we’re all still in such this hypermyopic era of AI Where the reality is that for various, boring security and governance reasons at least for most people’s work, why is my coding agent, even if it’s all background agents, background running not, losing all the context that’s available to it across everything that I’m doing outside of coding? I think the most interesting thing to me in AI is actual ambient AI, not insert assistant name thing or, I’ve tried just about every pin in tool and whatever, and they don’t work the way that I’m looking for them to work because they are just trying to capture, and then they are trying to codify and then recall. And I think the thing that I’m looking for, back to the very beginning, I’m looking to be building out the next version of webhooks or, implementing a new feature, and it for it to know every spec doc, every email, the conversations that I’ve had online, everything about how this could be implemented and be able to, use that as part of its decision-making and none of these tools are ultimately doing this. So I think that it’s as if, software development work was a single lane task, was like it only needs a developer. Once I once I write the perfect code, we’ll be done here, but that’s just never been true. It’s all the context of the other team members, what the business is doing what’s popular right now, and I think that’s this huge opportunity for us to go much broader than really excellent coding agents? And that is honestly why I think OpenClaw has been so interesting is that sure, it’s connecting to all the data, sources that Kyle the human cares about, and now my question’s “Okay, how can I take all that and use that every day as a software dev connected together, not just have a new way to kick off a coding agent?” And that’s where we’re at. We’re saying, “Okay, I’m going to go use this CLI under the hood or this SDK,” but that’s not what I’m talking about. I’m talking about I’m having a conversation with you it downloads the podcast, and it realizes, “Oh, Kyle, sounds like Kyle needs this app or this thing or this “ That level of
Swyx [01:11:16]: Just recommends it.
Kyle [01:11:16]: That level of, that level of connectivity I think is where we still have a ton of ways to go in software because then when we have that red thread we want to pull, that idea, it can not only use the perfect way to write that code, but instead all of the sort of taste and judgment calls and expertise that I’ve earned or that we’ve earned as a group and use it as part of the actual implementation.
Swyx [01:11:42]: The extreme of it is AI runs your life, right? And I think there’s a scary inversion of control in the way that I literally doing it in the way that developers mean it in terms of frameworks Like the Hollywood principle, “Don’t call me, I’ll call you.” Like there at some point there is an inversion of control where, you should you stop telling what the AI, the AI what to do. AI tells you what to do. And, that’s a little bit scary, but also, maybe better.
Kyle [01:12:10]: like Nat, I think Nat Friedman shared this in a like a Stripe event like talking about his OpenClaw was, he connected OpenClaw to his cameras, and it was, watching him.
Swyx [01:12:20]: It redirected his Uber. And it,
Kyle [01:12:23]: there’s a degree of this where I was I actually would love OpenClaw to tell me to Drink water. I don’t know that I want it to be, Changing where my car goes, but I do think that’s kind of what I’m talking about, which is it needs to have so much more information at its disposal for it to be helpful to me, and I still don’t think we’re, anywhere near talking about AGI. I’m just talking about every time I have to tell you something I care about that I’ve ever kind of said or I’ve said a dozen times, it should be able to know that codify that or gain access to it. Like the dreaming ideas, are an attempt to kind of do some version of this but I think there’s a much more proactive angle that will help software devs if we can test that out a bit more.
OpenClaw, Ambient AI, and Inverting Control
Swyx [01:13:05]: Yeah. Well, the other thing about OpenClaw that reminded me Is Microsoft has a CVP Dedicated to OpenClaw. Why?
Kyle [01:13:16]: Because you don’t think they should?
Swyx [01:13:17]: I don’t, I don’t know. I think CVP is a high title. What, why is this so important? Like Microsoft Doesn’t even own OpenClaw. What’s, what’s the
Kyle [01:13:29]: so I— we’re talking a lot more about this at, Microsoft Build this year too. I think, the main thing is that what OpenClaw has done is it has made this connection for people to have access to the resources that you have access to and be able to do things for you in a way that previously people were trying to codify into their own agents. And so when you think about it like in the work context, wouldn’t it be great to have a Claw-like object that I could actually run on my work device that or had access to my work assets, made— worked well on Windows what that would look like. And so I think that OpenClaw has become the personification of, a valuable agent that understands me because it has access to all of my information, and it can use a computer. And so thus it can do a lot more than, just a task-oriented process or like a a chat tool, et cetera. And that’s like a bunch of the goal of Build, right? We’re at Build this year trying to take a very different approach of it’s unapologetically aimed at developers. We’re trying to show the bigger investment to not just say, “Hey,” like you said, “Why do you have a CVP of OpenClaw?” Well, because, one of the problems that we have, right, is that our agents, if you install them not on a Mac Mini or not on a hosted device, you install them on a personal device or a work device, we need better sandboxing at the OS level. I need to be able to use that Claw and not, get fired. And so Microsoft is “Okay, great, let’s, do that too.” And then it’s, okay, well, where should I be able to talk to this agent? Should each of us just have a Claw available to us at work? Probably. And so there you go. And continuing to contribute a ton to the open source project too. Microsoft, I think as I’ve gotten more and more, information there’s so much investment into the open source, projects themselves that for whatever reason just I think there’s like this they don’t want to come off those teams don’t want to come off as like taking any credit or getting any recognition. But so many of these core contributors or teams are full-time just pushing into open source projects. And, I think that’s, that kind of shows the difference between, well, why are we looking so hard at something like Claw? Why are we looking at sandboxing on Windows? Why are we looking at cloud versions of sandboxing? Why are we looking— Because ultimately, we need more platform components. We don’t need everyone to be building the same exact, top-line product. And so if we’re building for builders, that requires us to give you all these components and tell you what they are and how they work and why you should be interested versus only delivering that single vertical over and over and over again.
Microsoft, Windows Sandboxing, and Platform Components for Agents
Swyx [01:16:23]: I think, my maybe one way of framing it Is that Microsoft is the original operating systems company. And here is the new operating system for AI.
Kyle [01:16:35]: like I think that we are also in an era where we are— we need to help build that bridge? All joking aside operating systems need to look different than they looked five years ago because it’s not just you using them anymore. And that’s changed the whole idea. It’s not, “Okay, my Claw is going to create a user account.” Doesn’t work like that? And so just just like all of us, we all have to look much more deeply in the stack, all the way down to, the silicon layer in Azure to be “Okay, well, What do we need now?” ‘Cause the workloads are different. It’s not just, “Okay, we need more inference.” It’s, “Okay, well, what type of inference do we need? What type of compute do we need to run these agents or run these agentic flows?” it’s a really interesting kind of like multi-layer problem, versus kind of, I would say software in the last five or six years were all going to our events, and we’re kind of saying a version of the same thing. SaaS product has new SaaS thing. It’s the best SaaS thing ever.
Swyx [01:17:42]: It was boring for a while.
Kyle [01:17:43]: And so now it’s like Oh my goodness, we’re at physics.
Swyx [01:17:47]: It’s great.
Kyle [01:17:48]: We’re at physics problems. And that’s exciting.
Swyx [01:17:50]: We’re— we’re now trying to make, semicondu- room temperature superconductors. Still. That’s, that’s, that’s never going away. No, I think, that’s a really good overview of, everything. I think, have I have we left anything unsaid that you wanted to really get out there that we should cover?
Build Announcements, Enterprise Adoption, and AI at Work
Kyle [01:18:07]: I’m really excited by for folks checking out, checking out the announcements that we have at Build go you can go look at them online, take a look. I think that I’m hoping that it’s driving, a degree of curiosity and interest because there’s such this big shift that we’re making at Microsoft for developers, where if you’re a daily driver of a Mac device or a Linux device, and you’re “Okay, I don’t use Windows,” there’s improvements that are being made that I think are going to surprise folks to just be “Oh, that’s in— they really want to do that?” not, And I’m talking for developers. I’m not talking for I play video games on the weekends on my Windows computer. I’m talking my daily driver. Like-All the way from that to, okay, well, what is it like to build an agent or build an app and deploy it and run it at work in particular? I think that is a big piece of it where I talk all the time with the team how I build on the weekend should be how I build at work. But if you’re working at a Fortune one hundred or a Fortune five hundred, you’re probably not vibe coding an app and then shipping it to some service. You got to go through security and compliance. How can we move just as fast at work? And that’s, I think, something that we have a bunch of different offerings for to give you that same sort of agility and power, but in the work context. And then I will tell you I’ve mentioned it a couple times, and, it’s very freaking cool. If you are in the M365 land in any way, check out WorkIQ, check out FoundryIQ. These little, oversimplifying it context engines are wild good. And, we’ve given them to our developers at GitHub, we’ve given them to employees at GitHub as we’ve used these tools to be able to just ask questions around everything that you have in your work context. And with FoundryIQ, be able to just do the same exact thing across all your existing stores. What— Not move to new tools, just connect them in. It’s surprisingly powerful, and you your boss is still not going to get fired, and IT is not going to turn it off because it’s leaking all this private information. That is the trick that I think, is sometimes getting lost when we’re talking about all these all these great new platforms. ‘Cause I can use them, I’m “Oh, this is super powerful. Oh, and I can’t I can’t use it.” and it’s Not because I’m at work at GitHub. It’s be
Swyx [01:20:34]: ‘Cause I’m not allowed, yeah
Kyle [01:20:35]: It’s ‘cause I’m not allowed, because they can’t do all the things that large, complicated companies need. And so, whether it be I said, just the kind of interesting daily driver curiosity all the way through to, “Oh, my gosh,” “I can go use this at work tomorrow potentially,” and have that context layer, have that intelligence, it’s a huge, it’s a huge shift. And so check it out. I’d love to hear— I’m, I’m not shy on social. I’d love to hear feedback. What’s working what’s not. But hopefully surprise folks a little bit.
Swyx [01:21:07]: What I’m hearing— so first of all, I think that’s, that’s a great pitch. What I’m hearing, actually, is that you should put the WorkIQ people next to the Copilot people. ‘Cause, the exact prob- context problem that you named They solve enough for you to do your job, which is nuts.
Kyle [01:21:23]: So, the thing that we are lit— that’s literally what has been Happening the last several months.
Swyx [01:21:29]: I already forecast you were going there.
Kyle [01:21:30]: It’s totally ‘cause, you’re totally right. The code, the code and the code asset problem is a little bit unique. But otherwise
Swyx [01:21:36]: That’s it
Kyle [01:21:37]: We’re all working
Swyx [01:21:37]: It’s context
Kyle [01:21:37]: With each other now. It’s all just context, exactly.
Swyx [01:21:40]: Amazing. Great. I’m going to be there. I’m going to be doing
Kyle [01:21:43]: Great
Swyx [01:21:43]: A couple sessions there. I’m going to be interviewing Satya.
Kyle [01:21:46]: I know.
WorkIQ, Copilot Context, and What to Ask Satya
Swyx [01:21:47]: When I first started the pod, though, I had, Jeff Dean on. Jeff like It’s like hall of fame of People I want to meet someday. Satya’s on there. So, what should I ask Satya?
Kyle [01:21:57]: I think, I think that the best question to ask is what he thinks is true in, two or three years from now. It seems like such a throwaway question. But ultimately, the way that the way that he is looking at this AI problem in, inference problem, token problem, and what we’re how we’re actually going to be working I think you can see some of the recent shifts that have been happening inside of Microsoft to kind of drive us to a place where it’s not four, five, six, seven, eight different things. It’s not a lack of context everywhere. But, why is this sort of approach in two years going to, pay off? Because that I think
Swyx [01:22:41]: Wow, that’s a bold Okay. I’ll ask it. I’ll say you I’ll say I prompted by you but
Kyle [01:22:45]: Absolutely
Swyx [01:22:45]: It’s a bold question because there, I think there’s a lot of, doubts to be honest, Externally. And so, yes, I want, a straight answer from him on that I think would reassure a lot of people, and honestly, give me a lot of food for writing. So, thank you so much for spending your time. Thank you for doing what you do. I think as a CEO, you don’t need to be the external face. But, because you are authoritative, ‘cause you have so much background with GitHub, and it’s so authentic, we on the outside feel it. So thank you for that.
Kyle [01:23:16]: Of course. Appreciate it. Thank you so much, Sean.

 Login