Imagine a dark warehouse. Racks and racks of devices with wires, tubes, and electronics sticking out. The next AI data center? No. This is Lila Sciences‘ dream for the future of science. A dark warehouse full of AI-guided robotics and lab equipment, cranking out new experiments 24/7, building toward a scientific superintelligence.
Their automated lab is almost hypnotizing to watch. They have floating plates zipping around on Wall-E-esque tracks, used vision-language models to control Windows 95 boxes, and created the world’s largest collection of voided warranties. In the process they’ve built a massive library of scientific reasoning tokens. Over 10 trillion of them, all experimentally validated.
No warranties were voided in the making of this video
To say Lila is ambitious is an understatement. Their goal is a scientific superintelligence wired directly into the wet lab. They are all in on the bitter lesson, and the thesis follows from it: a lab is an infinite token generator. Produce data at scale, and the synergies give you a general reasoner that can tackle any scientific problem. They are committing hard. Biology, chemistry, drug discovery, and materials science, all at the same time. Time will tell if it works, but it is an exciting hypothesis.
In our latest episode we sat down with Lila’s very own Andy Beam (CTO) and Rafa Gómez-Bombarelli (CSO, physical sciences) and went on a journey through the possibilities of AI-run science, almost as wide-ranging as Lila’s goals.
Did we mention they do both materials science and biology? In the same AI science factory? Same time, same lab, same AI. Finally a guest who can settle a long-running debate we’ve had amongst ourselves: is biology or materials science harder?
Watch to find out!
We discuss:
The internet is spent, science is next. Why Lila thinks the scientific method is the last untapped internet-scale dataset, and why they treat RL as a data generation mechanism with nature as the verifier.
The lab as a data center. Instruments as nodes on a graph, a magnetically levitating “PCI bus” transport layer between them, orchestration as a slurm queue. Andy is not short on analogies.
Why Lila insists it is not an automation company. They optimize for flexibility and generalizability over raw throughput, which means humans stay below the API line wherever automating does not pay.
Your experiment has a runtime. We put Escalante Bio’s question to Andy: if science is the token generator, what is the runtime of your data collection? His answer, in short, is that you cannot make the ribosome go faster. Why Lila bets on fast round-over-round iteration rather than big noisy multiplexed screens, and how Rafa’s team rebuilt a gas sorption measurement to run roughly 2,500x faster.
What is actually in 10 trillion scientific tokens. Not sequences. Experimentally verified reasoning traces, a kind of data that Andy argues exists on the internet in quantities that round to zero.
Breadth as a path to depth. Small molecule chemistry priors transferring to metal organic frameworks for carbon capture, and the claim that the general model beats domain-specific models sample for sample.
If you have the data, what do you need the model for? Sri Kosuri’s koan about the ML-for-drug-discovery business model, and Andy’s answer: the coding model got better because it also read Shakespeare and carnitas recipes.
The serendipity they want to automate. Emily Whitehead survived the first pediatric CAR-T cure only because the doctor treating her happened to know, from pediatric arthritis, which antibody would blunt her IL-6 response. Roll that dice again and you probably lose her. Breadth is how you stop depending on luck.
Move 37 for catalysts. Model suggestions for platinum-group-free electrocatalysts that went from boring, to what a 40-paper expert called stupid, to the best performers they have made.
Six months to in vivo CAR-T data in non-human primates, and the zero-FTE virtual startup commercial model that fell out of it. For context on why that number is startling, AbbVie paid $2.1B for Capstan on the strength of preclinical in vivo CAR-T data.
You cannot have scientific superintelligence if you are just a good test taker.Ken Stanley, who wrote Why Greatness Cannot Be Planned, runs open-endedness at Lila. RL at scale gives you a ruthlessly Vulcan problem solver. Machine creativity is a different thing, and it is the part nobody has solved.
The chain of thought is an unreliable narrator. The model reasons in latent space and only emits tokens. Sometimes it skips the experiment entirely and is still right. So how much do you trust the reasoning versus the verifier?
Reward hacking when the rollout is physical. Chains of thought that collapse into repetition, and a model that got annoyed and swore at the scientist who kept asking it to redo a plate map. What happens when a pathological loop has a wet lab inside it?
The bittersweet lesson.Rafa’s inversion of the bitter lesson: in AI, scaling is a roadmap. In materials, scaling is a filter, because only the things that scale end up mattering.
Not your typical Flagship company. Why a famously single-asset biotech incubator spun out a platform bet, and Andy’s line that if Lila called itself a biopharma it would have a top-three GPU cluster.
Bottlenecks they would remove by fiat. Sim-to-real for physics-based simulation, and the fact that RL training runs at roughly 5% mean FLOP utilization.
Thinky only seems to come up for air once every few months; most recently with Interaction models - but each time they do they impress, showing both taste and depth. Today they introduced Inkling — not a SOTA model, but a very solid new family for a baseline American open model:
Our model, called Inkling, is a Mixture-of-Experts transformer with 975B total parameters, 41B active.
It supports a context window of up to 1M tokens.
It was pretrained on 45 trillion tokens of text, images, audio and video.
It is the first in a family of models of different sizes: alongside it we are sharing a preview of Inkling-Small, a lighter-weight model with 12B active parameters, trained with a similar recipe, that achieves strong performance with even lower cost and latency.
Inkling reasons natively over text, images, and audio, and balances cost with performance through efficient and controllable thinking effort
Thinking Machines Lab launched Inkling, its first fully released open-weights foundation model family entry, positioning it as a customizable multimodal base model rather than a benchmark-maxed flagship.
Thinking Machines announced Inkling as an open-weights model that “reasons efficiently across text, image, and audio modalities,” with full weights available and immediate support on its Tinker platform and Playground @thinkymachines.
Mira Murati described Inkling as the company’s “first model,” “trained from scratch,” with open weights and same-day fine-tuning on Tinker @miramurati.
Soumith Chintala framed it as Thinking Machines’ “first general model,” stressing open weights, 975B parameters, native multimodality, and availability on Tinker, Hugging Face, and partners @soumithchintala.
John Schulman added timeline context: pretraining began last winter, and from mid-January a small team built coding, reasoning, and agentic training on top @johnschulman2.
Lilian Weng characterized Inkling as a foundation model aimed at “solid performance across a broad categories of capabilities” and intended for practical use plus customization @lilianweng.
TML staff repeatedly emphasized that this is a day-1 release and a foundation for future iterations rather than their final frontier push @soumithchintala, @cHHillee, @keirp1.
Independent commentators immediately tagged it as the strongest U.S.-based open-weight release so far, though generally still behind the top Chinese open-weight and best closed models on some benchmarks @natolambert, @ArtificialAnlys, @scaling01.
Community readers extracted 45T training tokens from the release materials @eliebakouch, @ArtificialAnlys, while one post says 48T@mervenoyann. The more repeated figure in this dataset is 45T.
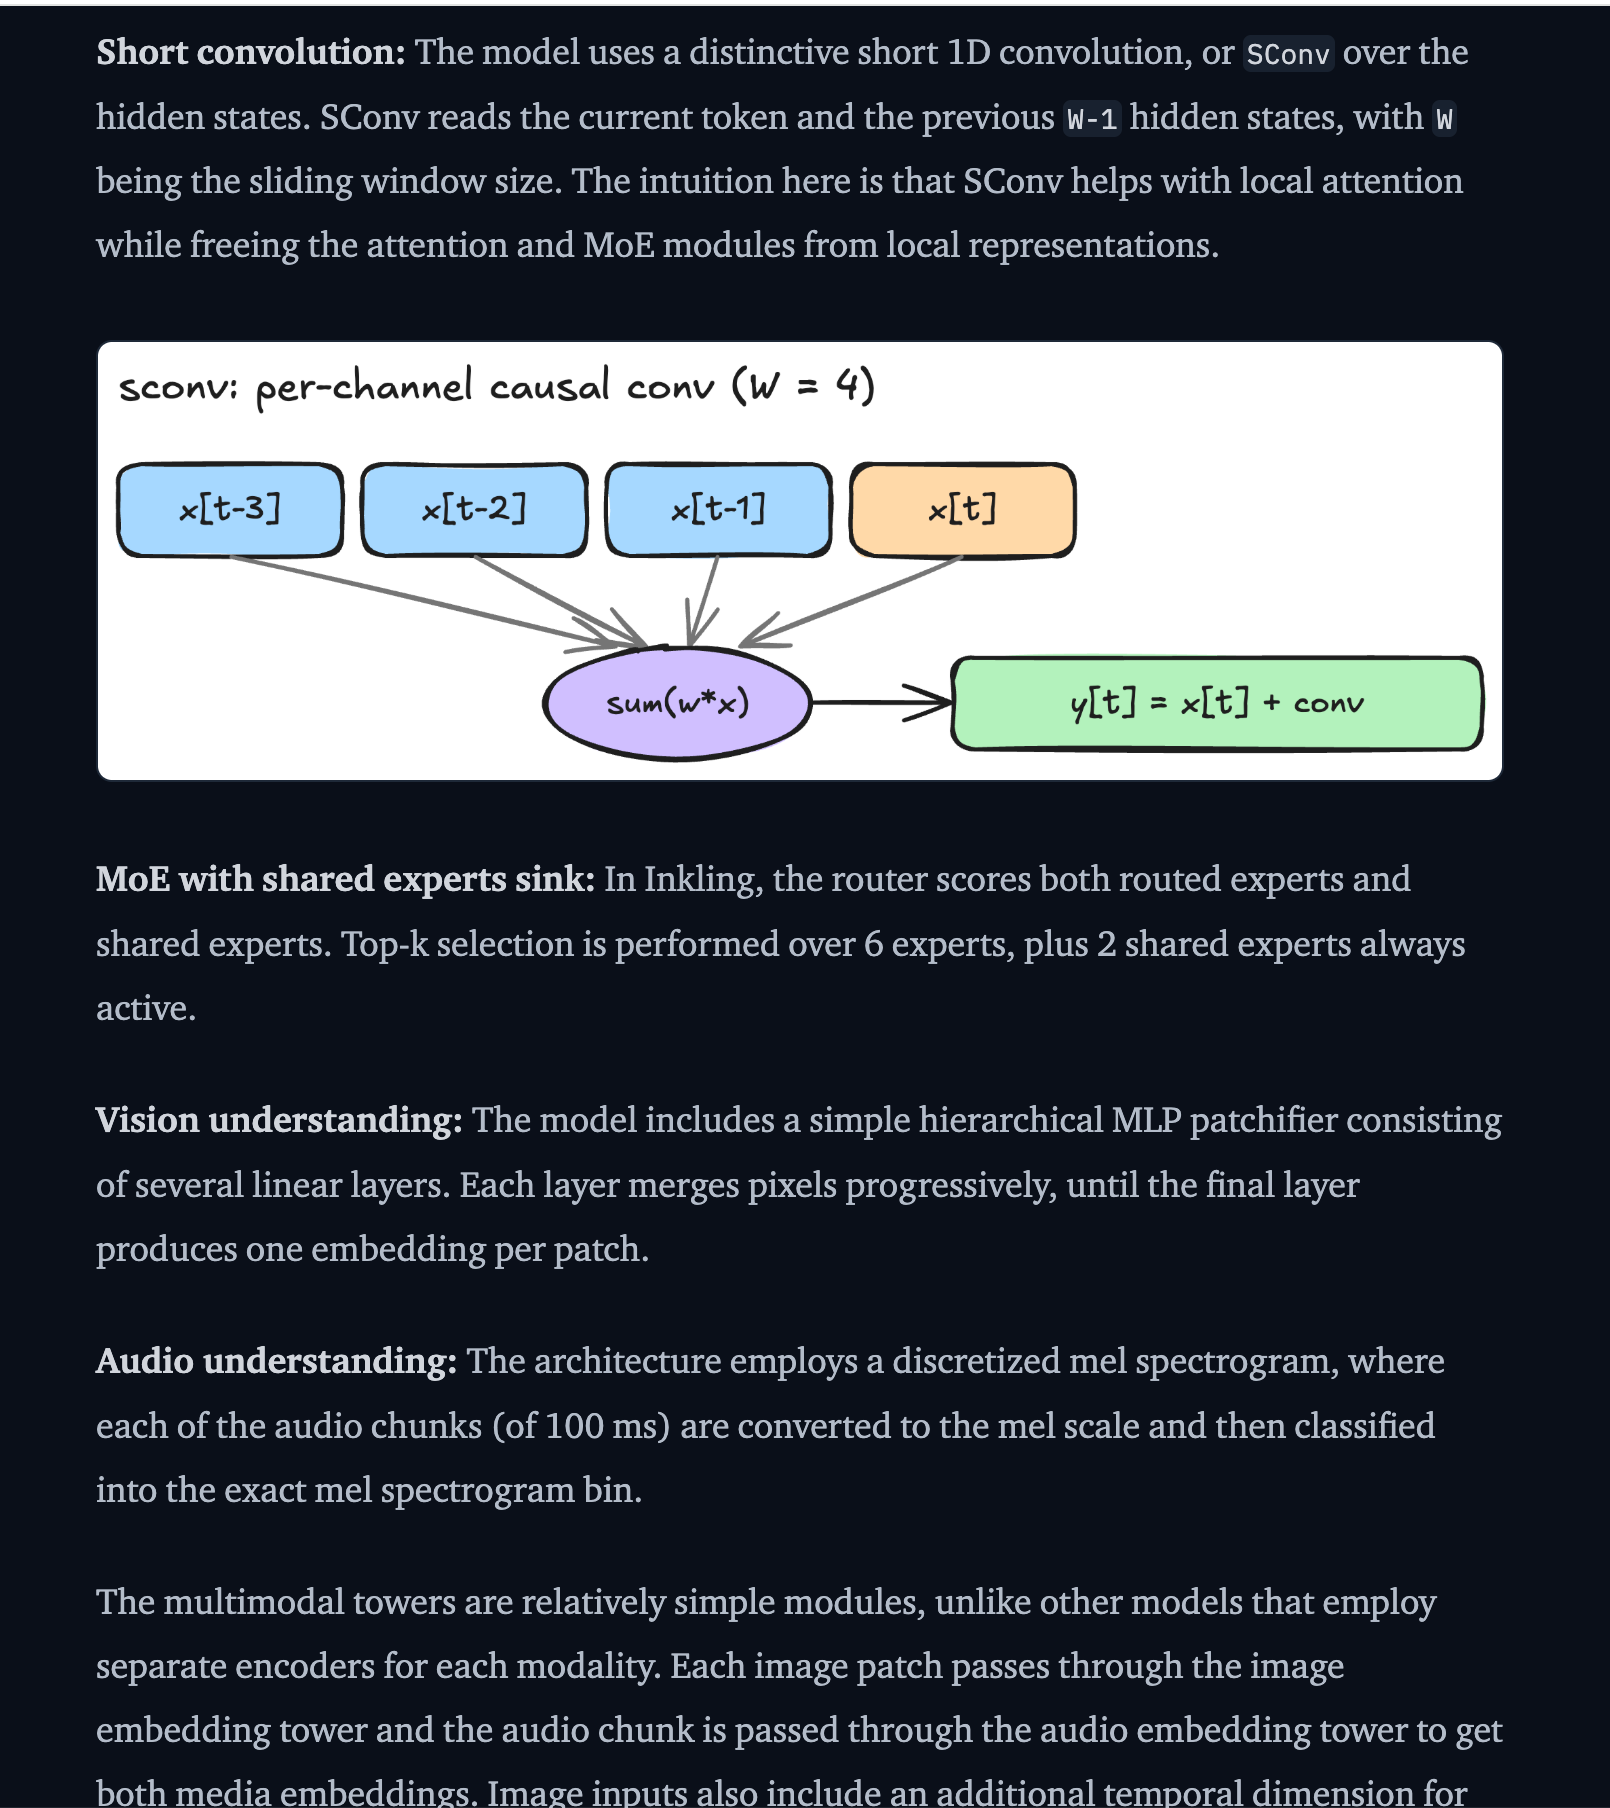
MoE with shared expert sinks / 2 shared experts, noted as atypical since many recent MoEs use 1 shared expert @eliebakouch, @ariG23498.
DeepSeek-style auxiliary-loss-free load balancing was cited in community readings of the architecture @eliebakouch.
muP and Muon/weight decay variants were inferred from the writeup and confirmed by optimizer expert reaction: Aaron Defazio said they are using his corrected weight decay approach, “MuonC/AdamC” @aaron_defazio, while community readers also pointed out muP @stochasticchasm, @Laz4rz.
8 MTP heads for speculative decoding were highlighted by vLLM @vllm_project.
Variants
Inkling-Small is repeatedly referenced as an upcoming or separately discussed smaller model @LiorOnAI, @teortaxesTex.
Community summaries describe Inkling-Small as 276B total / 12B active and unexpectedly competitive versus the larger model on several evaluations @eliebakouch, @nrehiew_.
Performance and benchmarks
Independent benchmark framing
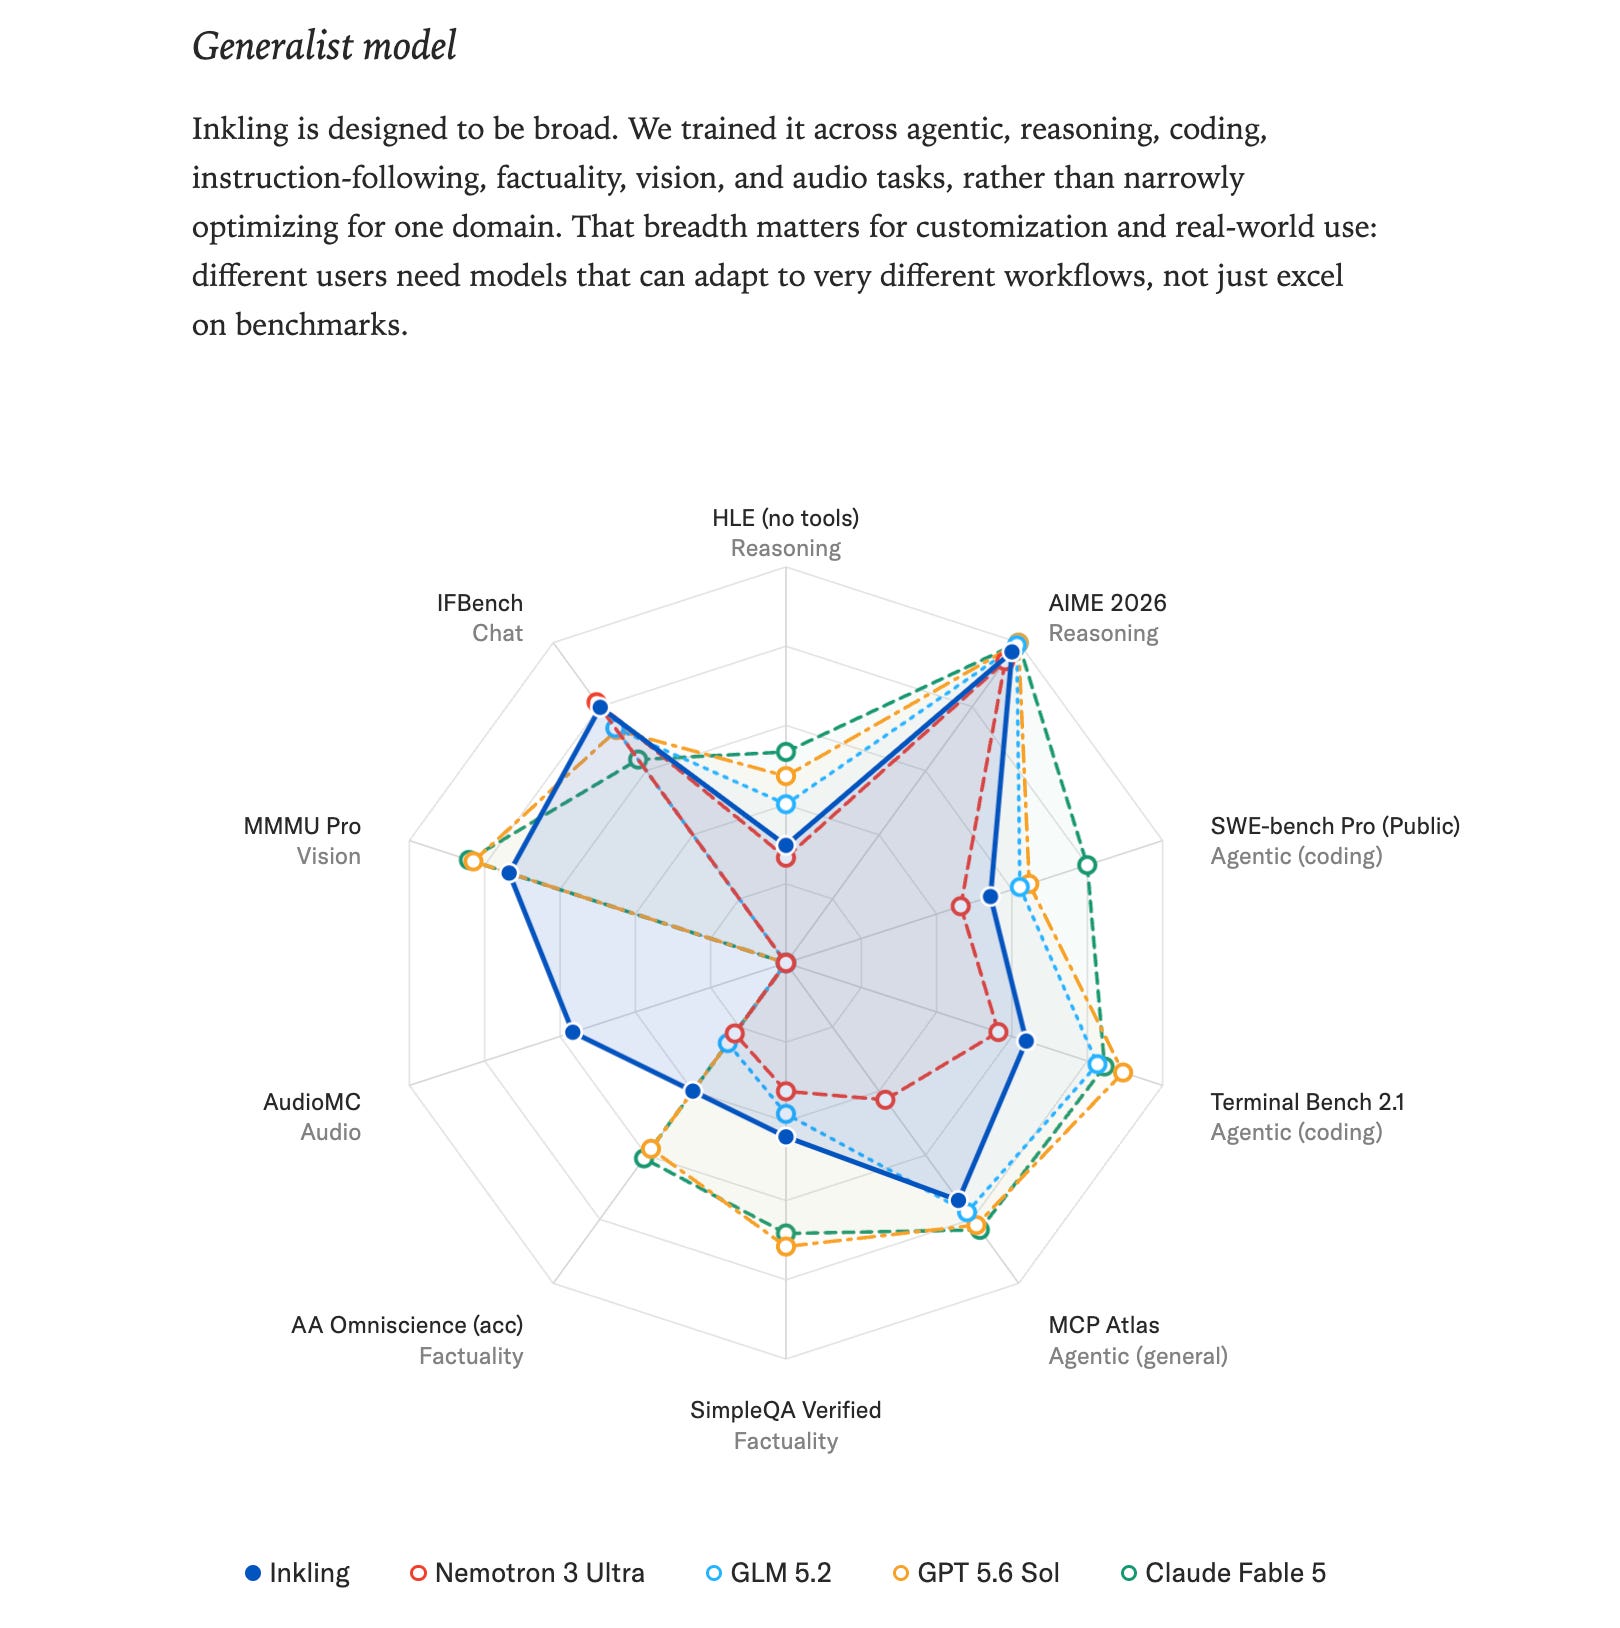
Artificial Analysis said Inkling debuts at 41 on the Intelligence Index, making it the leading U.S. open-weights release and ahead of Nemotron 3 Ultra (38), Gemma 4 31B (29), and gpt-oss-120b (24)@ArtificialAnlys.
Artificial Analysis also said Inkling averages 25K output tokens per Intelligence Index task, vs 43K for GLM-5.2 max, 38K for Kimi K2.6, and 37K for DeepSeek v4 Pro max, framing it as relatively token-efficient @ArtificialAnlys.
Natolambert called it a “clear step up from Nemotron Ultra” and “new best American model,” but still “a bit behind GLM 5.2 on agentic benchies, and Kimi K 2.6 on multi modal” @natolambert.
Design Arena said Inkling entered Agentic Web App Arena at #9 overall, Elo 1257, in the same band as Claude Opus 4.6 and Gemini 3.5 Flash, and called it the highest-ranking U.S.-based open-weight model for agentic workloads @DesignArena.
Arena added Inkling to Agent Arena / Text / Vision / Code Arena on launch day @arena.
Specific benchmark numbers cited
From Artificial Analysis:
GDPval-AA v2 Elo 1238, higher than Kimi K2.6 (1190) and DeepSeek v4 Flash max (1189)@ArtificialAnlys.
τ³-Banking 24%, above Kimi K2.6 (21%) and slightly above DeepSeek v4 Flash max (23%)@ArtificialAnlys.
Qualitative performance takes
Positive:
“Sharp and concise” reasoning, not rambly @MichaelElabd.
Strong tool calling and good long-horizon error recovery on agentic tasks @MichaelElabd.
Alex Kirillov claimed Inkling avoids the common “audio in = intelligence penalty” seen in many omni models, though another user asked for stronger supporting evidence and benchmarks @alex_kirillov, @giffmana, @alex_kirillov.
More mixed / critical:
Scaling01 argued the benchmarks are “not that great,” describing it as roughly “another Kimi-K2.6” and behind all closed models and GLM-5.2, speculating the release may have been timed ahead of Kimi-K3 and DeepSeek-V4-GA @scaling01.
Stochasticchasm said it seems “very strong for multimodal” but “not super strong for terminal bench etc.” @stochasticchasm.
JJitsev pushed back on hype around “only open-weight model trained without distilling,” saying Inkling uses distillation from open weights and underperforms GLM 5.2 on TerminalBench-style evals @JJitsev.
TeortaxesTex offered a contrarian positive spin: mediocre benchmark-maxing may actually suggest less corner-cutting/distillation contamination and a more independent data pipeline @teortaxesTex.
Inference, systems, and launch ecosystem
Official and partner infrastructure facts
NVIDIA said Inkling was trained on GB300 NVL72 and that an NVFP4 checkpoint was available on Hugging Face on day 0 @NVIDIAAI.
vLLM said day-0 support includes NVFP4 and BF16, optimized for Blackwell and Hopper, reaching up to 380 tok/s/user on 4× GB200 with MTP@vllm_project.
Inferact detailed system work: sconv-aware tensor-parallel sharding, low-latency fused collectives (5× faster at bs=1), and direct integration of TML’s FA4 sheared-bias kernel@inferact.
LMSYS/SGLang said Inkling architecture support was implemented natively, including ShortConv, relative positional attention, shared expert sink MoE, prefill full CUDA graph, MXFP8 KV cache, full parameter and LoRA RL in customized Megatron backend, routing replay, cross-runtime parameter sync, and DFlash speculative decoding from Modal@lmsysorg.
Modal said Inkling on Modal uses a custom DFlash speculator for 67% higher throughput and interactivity@modal.
Soumith Chintala separately amplified that Modal’s DFlash speculator is “much faster than MTP” @soumithchintala.
Community optimization observations
Lysandre reported replacing TML’s causal Conv1D with causal-conv1d yielded +4% tok/s, and replacing attention with FlashAttention-4 yielded another +11%, for ~15% total throughput gain without retraining @LysandreJik.
Unsloth released 1-bit GGUF quants said to be 86% smaller (270GB vs 1.9TB) while retaining 74.2% of top-1% accuracy, with vision and audio support @danielhanchen.
Available on Tinker, Hugging Face, and via launch partners including Databricks, Baseten, Modal, vLLM/SGLang stacks @soumithchintala, @Yuchenj_UW, @baseten, @modal.
Facts vs opinions
Factual claims directly supported by launch and partners
Pretraining began last winter; agentic/coding/reasoning work started mid-January @johnschulman2.
Day-0 support on major serving stacks, with concrete performance claims from vLLM/Inferact/Modal/NVIDIA @vllm_project, @inferact, @modal, @NVIDIAAI.
Interpretations and opinions
“Best American open model” / “saved American open-source frontier” are judgments, albeit repeated by several respected observers @natolambert, @karinanguyen, @saranormous.
Claims that Inkling is especially important because it is not distilled from OpenAI/Anthropic are disputed. Jxmnop called it “the ONLY open-weight model” without such distillation @jxmnop, then partially walked it back: “apparently they did distill lol. but only a tiny bit” @jxmnop. Andrew Carr also contested the purity framing, noting use of Kimi 2.5 for SFT traces @andrew_n_carr.
Claims that Inkling was “rushed” ahead of Chinese releases are speculation from critics, not evidenced by the launch materials @scaling01.
Claims that relative attention gives TML a finetuning moat because backward is hard are speculative @typedfemale.
Claims that Inkling avoids multimodal intelligence loss are promising but not yet benchmark-complete in the tweet set @alex_kirillov.
Different perspectives
Supportive / bullish
Open-weight and permissive license as strategic win: Many saw the Apache-2.0 release as a major boost to the U.S./Western open ecosystem @latkins, @saranormous, @brexton, @hyperindexed.
Customization over leaderboard chasing: Researchers and builders praised the explicit framing that Inkling is a broad, tunable foundation rather than a benchmark-maxed point solution @gneubig, @ben_burtenshaw, @thealexker.
Strong release quality: Several users praised the transparency, grounded tone, and comprehensive technical documentation @lvwerra, @saranormous, @rasbt.
Architecture interest: The non-RoPE positional choice and scaled short-conv usage drew positive attention as evidence TML is willing to make meaningful architecture bets @stochasticchasm, @rasbt, @ChangJonathanC.
Neutral / analytical
Strong but not top overall: The most balanced reads place Inkling as the new U.S. open-weight leader, but behind GLM/Kimi/DeepSeek or top closed models on some fronts @natolambert, @ArtificialAnlys, @stochasticchasm.
Good base model thesis: Multiple analysts read the release as a systems/business move: ship a solid, efficient, post-trainable base and let Tinker plus downstream RL/fine-tuning create differentiation @ben_burtenshaw, @kimmonismus, @tinkerapi.
Critical / skeptical
Not frontier overall: Critics argued it is still clearly behind top Chinese open-weight models and the strongest closed models @scaling01, @JJitsev.
Purity claims overstated: Some pushback focused on exaggerated claims that it is uniquely “pure” or non-distilled; the thread set includes both hype and corrections @jxmnop, @jxmnop, @andrew_n_carr, @JJitsev.
Benchmark middlingness as concern: Some readers saw the moderate benchmark profile as evidence it may simply lag current Chinese open frontier rather than inaugurate a new frontier @scaling01.
Context: why this matters
First major TML public model: This is the first true external model release from Thinking Machines after months of anticipation around a lab staffed by ex-OpenAI leaders and researchers. That made the choice of open weights itself notable @Hesamation, @TechCrunch.
A U.S. open-weight answer to Chinese momentum: Many reactions explicitly compare Inkling to GLM, Kimi, DeepSeek, and Qwen. The release lands amid concern that Western open-weight models have trailed Chinese ones on capability and release cadence @scaling01, @teortaxesTex, @sriramk.
Open base + post-training stack thesis: TML’s messaging strongly suggests a strategy similar to “ship a competent open substrate, then differentiate via customization/fine-tuning/RL infrastructure.” That aligns with Tinker distribution and with user reactions centering controllable reasoning, concise outputs, and adaptation rather than raw leaderboard supremacy @thinkymachines, @MichaelElabd, @ben_burtenshaw.
Inference ecosystem maturity: The release also showcases how far open inference stacks have come. Day-0 support for a 1T-class multimodal MoE with new architectural components and multiple kernel-level optimizations would have been far less plausible a year earlier @vllm_project, @inferact, @LysandreJik.
Architectural experimentation at scale: Relative positional bias instead of RoPE and large-scale short-conv usage are the kind of choices researchers watch closely because they may indicate future architecture trends if they prove robust under scaling and post-training @stochasticchasm, @rasbt, @ChangJonathanC.
Release style as signal: Several commentators praised the unusually restrained release language, explicit admission that it is not the strongest overall model, and detailed technical notes. For expert audiences, that improved credibility relative to more benchmark-maxed launches @eliebakouch, @lvwerra, @thealexker.
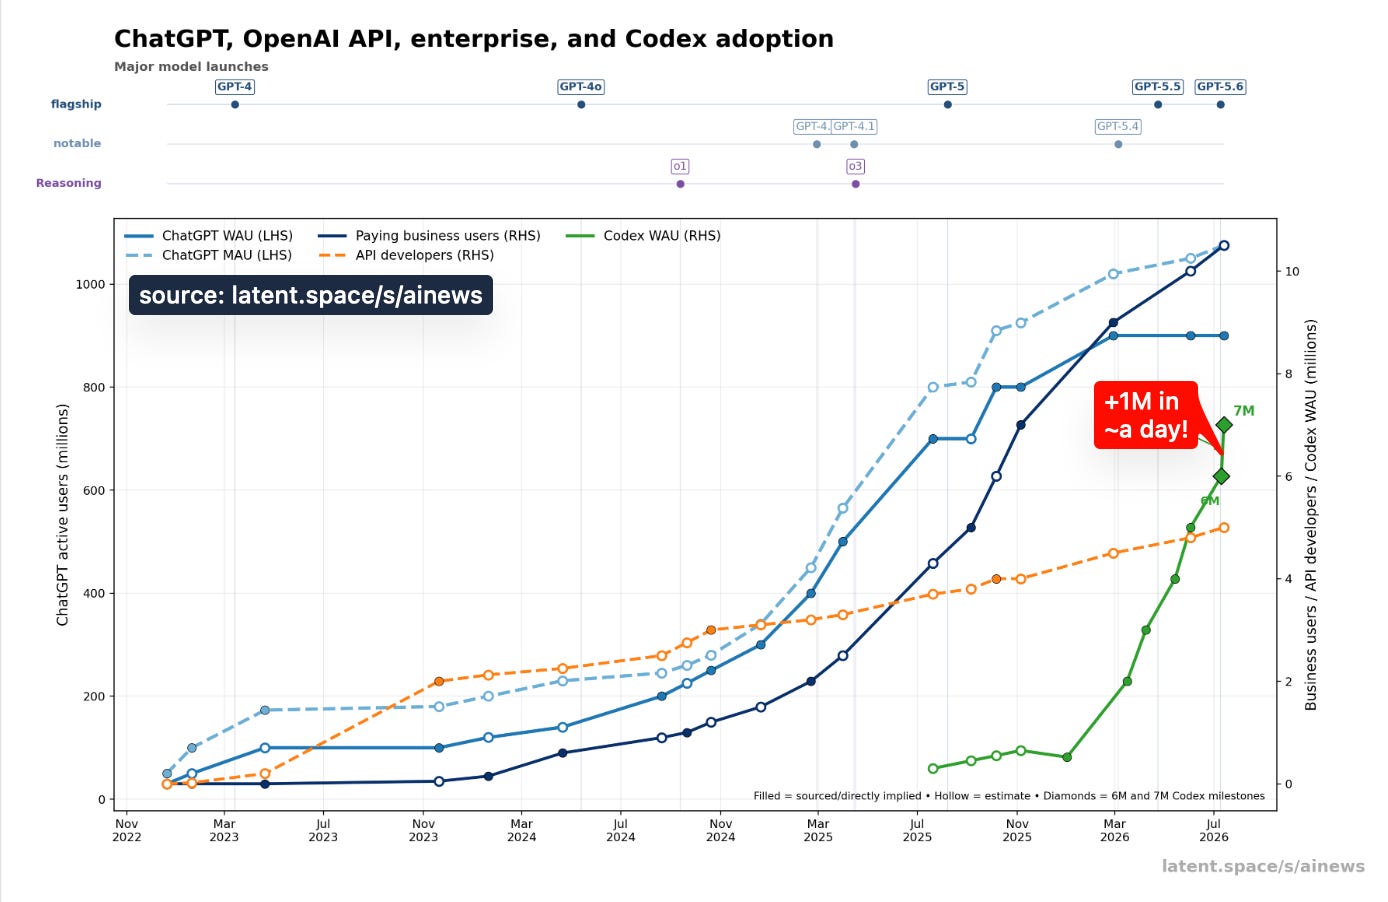
Yesterday’s headline story became even more true, with Superapp usage adding yet another 1M users since we last wrote:
In other news, published his final AIEWF26 recap of recaps:
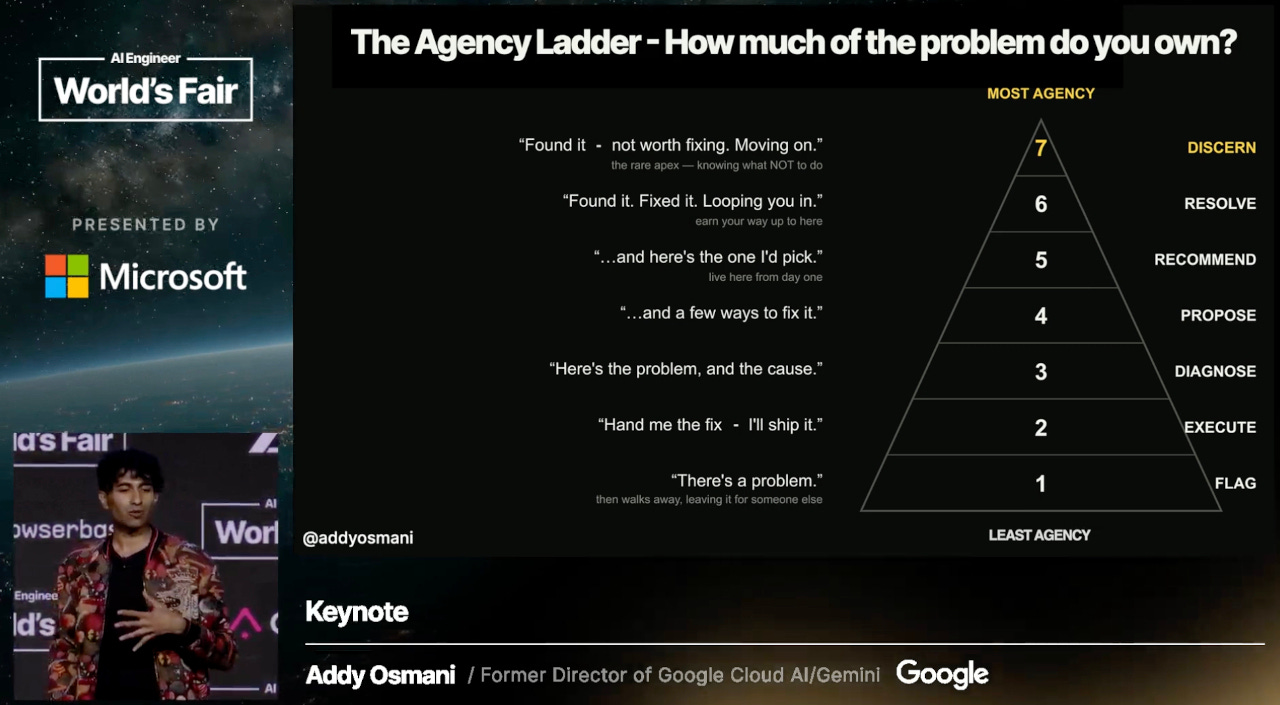
Including coverage of Addy Osmani’s excellent keynote covering what AI engineers should continue doing even when the cost of code generation trends to zero:
Harness quality and observability are becoming a first-class differentiator: several tweets converged on the idea that model quality alone is no longer enough. @swyx warned that stale agents.md instructions can act like self-inflicted prompt injection, causing multi-hour stalls in long-running tasks. LangChain added tracing for Codex and later expanded to Cursor, Copilot, Pi, and OpenCode in LangSmith, exposing tool calls, subagents, and token usage. @Teknium shipped Hermes updates to parallelize any subset of tool calls and previously exposed banked resets directly in Hermes Agent. The meta-point was stated crisply by @andykonwinski: companies that can encode their value into evals and environments may gain a more durable edge than those relying on capital or raw scale alone.
Open Models, Quantization, and Local Inference Compression
Aggressive compression is bringing frontier-adjacent models onto consumer devices: PrismML released Bonsai 27B, based on Qwen 3.6 27B, in two compact variants: Ternary Bonsai 27B at 5.9 GB / 1.71 effective bits and 1-bit Bonsai 27B at 3.9 GB / 1.125 effective bits, both under Apache 2.0. The claim is notable not just for size, but for preserving multimodal, tool-using, long-context agentic workflows locally; a demo shows Hermes running it on an RTX 5090, while Locally AI highlighted phone deployment. In parallel, Tencent Hunyuan released 1-bit and 4-bit Hy3, describing a 295B flagship-scale model that can be served on a single GPU via llama.cpp with MTP enabled.
Quantization and edge deployment continue to broaden the open-model operating envelope: @danielhanchen announced NVFP4 dynamic quants across the Gemma-4 family and additional large models including Qwen3.5-122B-A10B and GLM-4.7-Flash. @MiaAI_lab’s DGX Spark thread sketched practical multi-node local deployments, including 1M-context DeepSeek v4 Flash and MiMo-V2.5 on 2× DGX Sparks, and GLM 5.2 NVFP4 across four. The common theme across these posts is that local inference is no longer just a toy path: it is becoming viable for serious agentic workflows, especially when paired with low-bit weight formats and optimized harnesses.
Multimodal and World-Model Systems: Video, Realtime VLMs, and Motion
Realtime multimodal interaction is moving from “watch then answer” to continuous perception: OpenMOSS released MOSS-VL-Realtime, an 11B vision-language family under Apache 2.0 with 256K context, designed for continuous video streams. Its key systems property is that it can keep watching while generating, revise or interrupt answers as scenes change, and remain silent when evidence is insufficient. A companion technical thread from @Open_MOSS emphasizes a cross-attention architecture, XRoPE for unified temporal-spatial positioning, and unified templates across offline/streaming/realtime settings.
Long-video understanding is increasingly framed as active evidence search, not passive frame ingestion: a dense summary from @ZhihuFrontier described OmniAgent, built on Qwen2.5-Omni-7B, which uses an Observation–Thought–Action loop to request only the frames/audio it needs. On LVBench, OmniAgent-7B reportedly scored 50.5, beating Qwen2.5-VL-72B at 47.3, while consuming only ~203 frames vs 768. The training recipe is also notable: passive SFT hurt performance, while 58K agentic trajectories and entropy-weighted RL via TAURA improved it. The larger research pattern here aligns with Andrew Carr’s note that motion is a fundamentally novel data type requiring dedicated collection, infra, and model treatment rather than being reduced to images-with-time.
Open world models are inching toward interactive, longer-horizon simulation: @RekaAILabs outlined the data stack behind omni world models, stressing petabytes of video, 6 pipeline stages, and the doubled payoff from data-quality improvements when models both generate and understand video. @omarsar0 summarized LingBot-World 2.0 as one of the first open releases claiming hour-scale, 720p/60fps interactive generation, though still without long-term memory. On the application side, PixVerse Game was highlighted as pursuing the harder problem of real-time interactive video response rather than canned game-like clips.
Research Infrastructure, Benchmarks, and Evaluation Methodology
Perplexity open-sourced WANDR, a benchmark for wide-and-deep agentic research: @perplexity_ai described WANDR as a 500-task benchmark built from de-identified production research tasks, requiring 170,495 source-backed records across multiple difficulty tiers. Rather than grading against a static gold set, WANDR re-fetches cited pages and checks claims against underlying evidence, which better matches dynamic web research. @AravSrinivas framed this as the internal benchmark behind Perplexity Computer’s deep-and-wide research harness, while @denisyarats emphasized its additional role as an RL environment synthesized from production traces.
Eval design is getting more adversarial and more realistic: Agent Arena highlighted work cutting system costs by 89% while matching the best static config’s accuracy, arguing that full system config > LLM routing alone. Relatedly, Google DeepMind work on model routing argued that routers should be judged not just by accuracy/cost but by behavioral differentiation among experts and stability under paraphrase; otherwise routing may be functionally meaningless. @HamelHusain’s automated evals post landed in a similar place: these systems can spot issues humans miss, but still lack enough domain taste and feedback loops to replace experts.
Benchmarks are expanding beyond one-shot SWE tasks toward degradation and search realism: mini-swe-agent marked one year while now powering multiple software benchmarks; SlopCodeBench was cited as measuring how agents erode codebases over sequential tasks rather than just solving one isolated issue. This broadens the benchmark surface from “can it solve a task?” to “can it avoid making the repository worse over time?”
Physical AI, Collective Intelligence, and Robotics
Sakana AI pushed collective intelligence from software into physical self-repairing systems: across multiple posts, Sakana introduced “Smart Cellular Bricks”, published in Nature Communications. The system consists of many identical cubes, each running a small neural network and communicating only with physical neighbors, yet able to infer global shape and detect damage without centralized control. A follow-up detail is especially notable: the cells can detect missing neighbors across six spatial directions with 95% accuracy and regrow target structures; in simulation, the method scaled to 18,000+ cubes (detail thread).
Physical autonomy is also showing up in much smaller form factors: @alextoussss posted a striking demo of an autonomous micro-drone achieving an air-to-air kill of a flying moth, framed as a step toward mosquito eradication. Separately, @fchollet highlighted Airtap, which turns SMS into a headless agentic execution layer for mobile apps, using text as the control plane and intervening only for authentication. These are different ends of the autonomy spectrum, but both point to interfaces where humans specify goals while systems handle embodied or semi-embodied execution.
Notable open-model release: Bonsai 27B stood out as the strongest technically substantive open-model launch in the timeline, due to its combination of 27B scale, phone-class footprint, and Apache 2.0 licensing.
swyx’s note: thanks to Richard for covering AIE while I was working on the conference itself! Make sure you have opted into the AINews feed to get our weekday updates. AIE next returns to NYC, Oct 12-14, with a heavy focus on AI in Finance this year.
AI engineering has come a long way in three years. When swyx coined the term “AI engineer” in June 2023, he was giving a name to a new kind of developer emerging from the big bang of large language models. It seems like ancient history now, but remember when we called the intersection of AI and software development “prompt engineering”? That was just months before swyx’s reframing.
The latest AI Engineer World’s Fair showed just how much the field has matured. Whether or not “AI engineer” has become a formal job title everywhere is almost beside the point. The engineering practices that have developed around AI over the past three years — building coding agents, designing harnesses, managing context, evaluating model outputs, and orchestrating increasingly autonomous systems — are becoming part of mainstream software development.
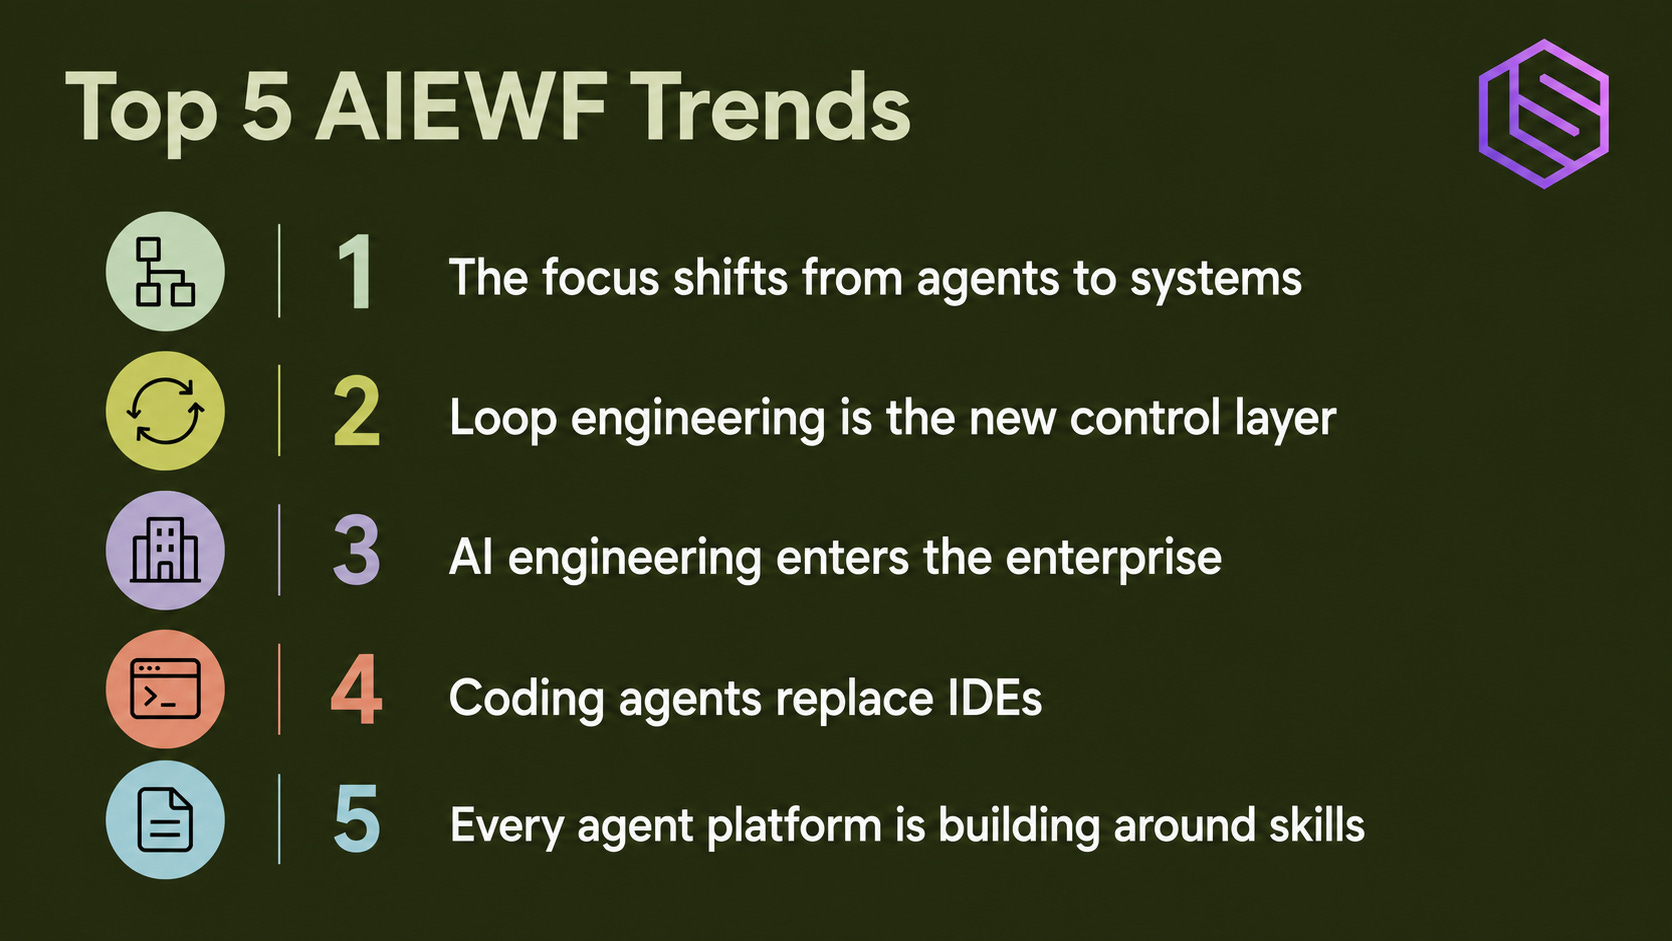
Rather than focusing on individual announcements at AIEWF, this post will pick out five larger trends that show where AI engineering stands in 2026.
1: The focus shifts from agents to the systems around them
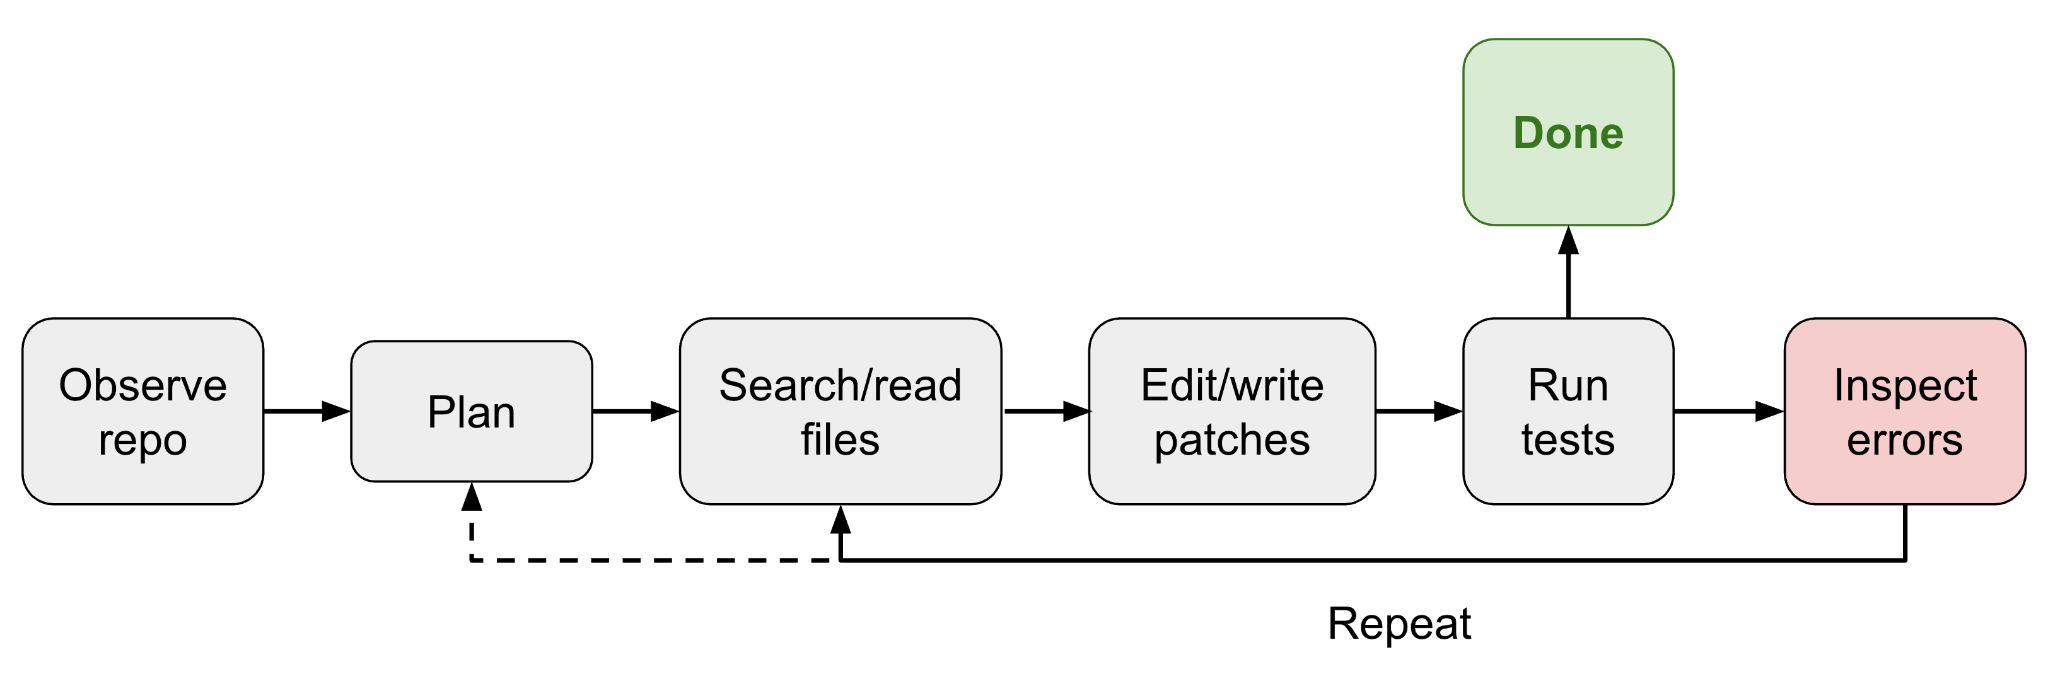
One of the clearest ways to see how AI engineering has evolved is to compare two essays by former OpenAI researcher, and now co-founder of Thinking Machines Lab, Lilian Weng. Her influential 2023 article, LLM Powered Autonomous Agents, described the anatomy of an LLM agent in terms of planning, memory and tool use. AutoGPT, BabyAGI and GPT-Engineer were among her examples — proof-of-concept systems that suggested autonomous agents might soon become practical.
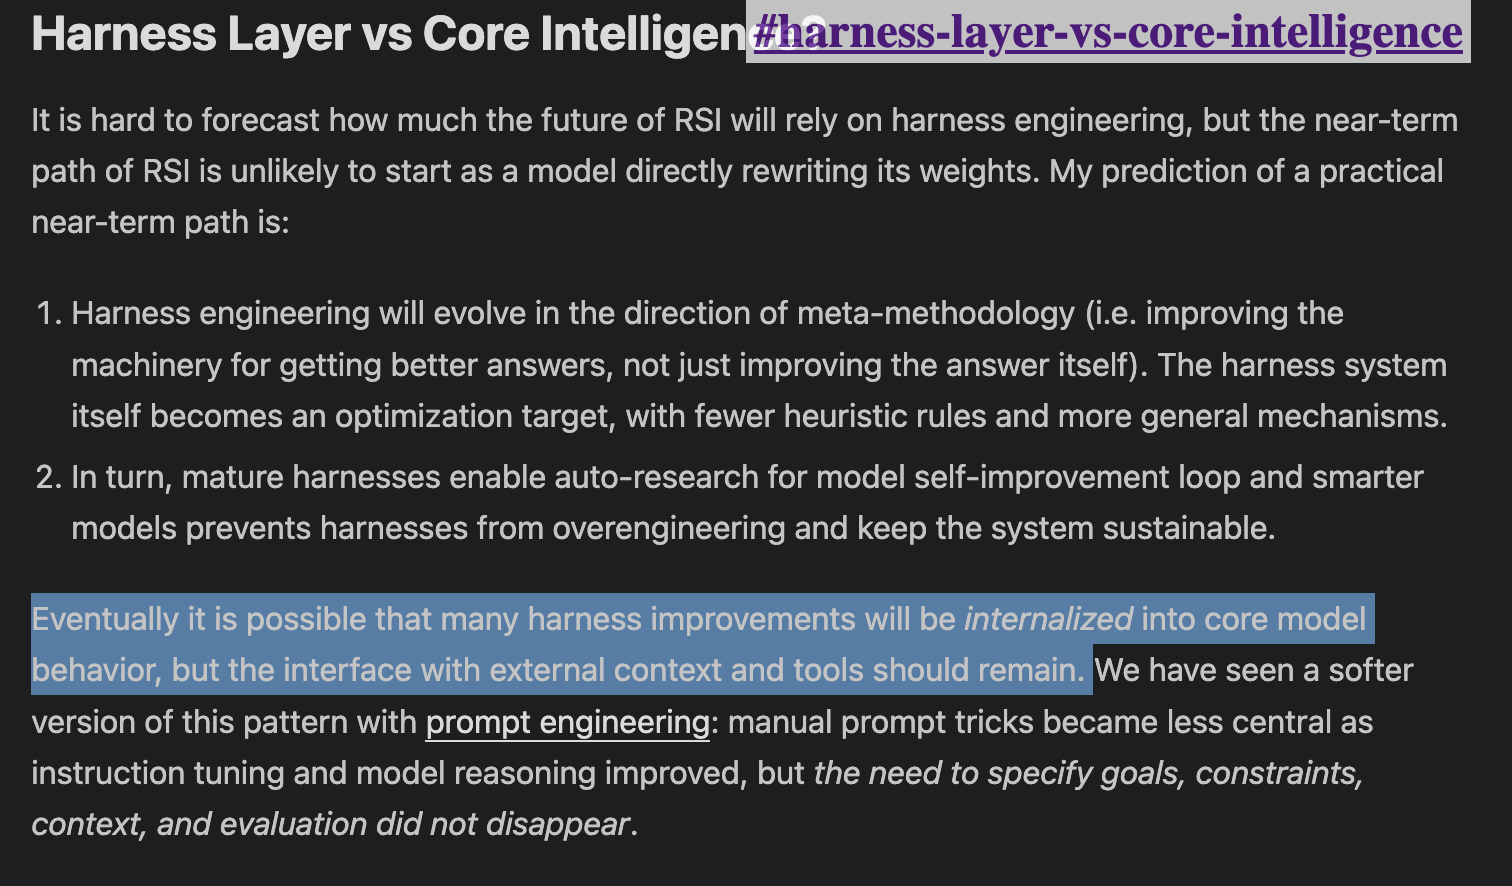
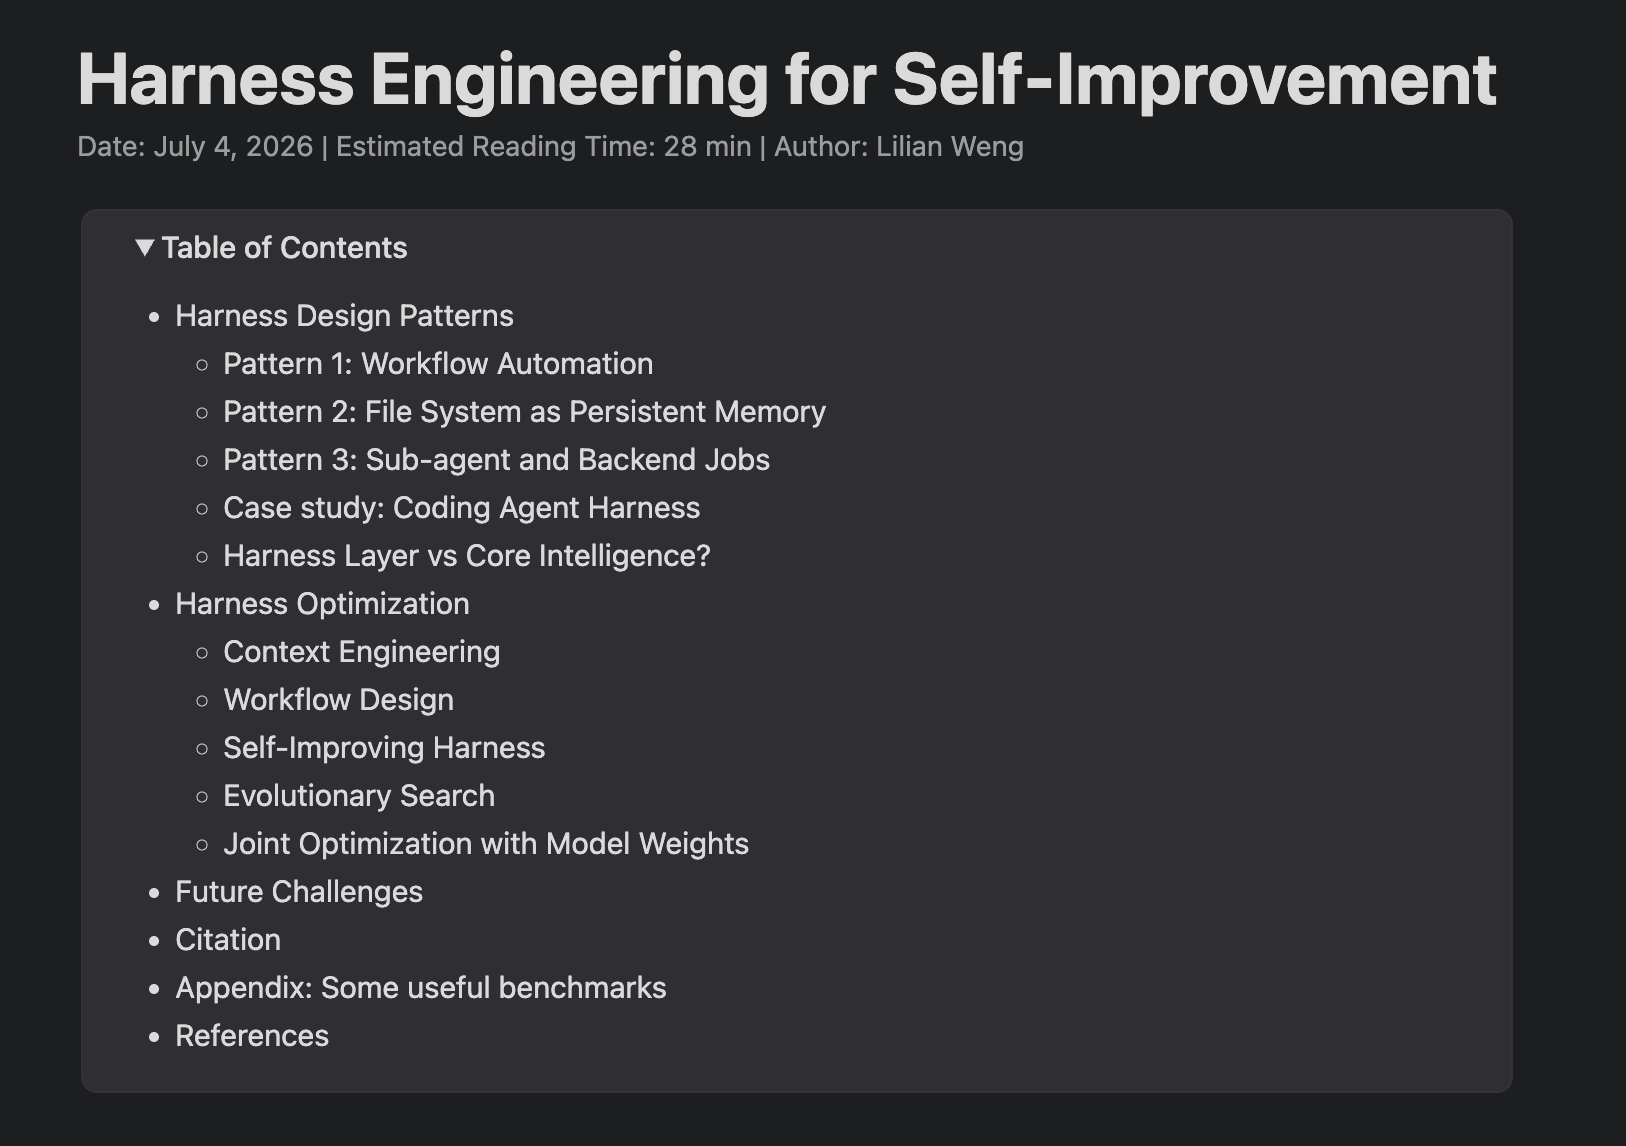
Her new 2026 essay, Harness Engineering for Self-Improvement, takes a very different perspective. Rather than focusing on the agent itself, Weng argues that the system surrounding the model has become just as important: the harness that manages workflows, context, permissions, evaluation, persistent state and continuous improvement. In other words, AI engineering has moved beyond prompting models toward engineering reliable systems around them.
Coding agent loop; Image by Lilian Weng
This shift was very much top of mind at AIEWF. I don’t think AutoGPT — the buzzy autonomous agent project everyone was talking about in 2023 — was even mentioned this year. Instead, the conversation revolved around Claude Code, Codex, Gemini CLI, Cursor, Warp and all the infrastructure needed to make coding agents dependable in production.
I remember being turned off by the AutoGPT buzz at the 2023 event, mainly because all the discussions seemed to focus on removing humans from the equation. But over the past few years we’ve learned that complete agent autonomy is not only unreliable, it isn’t even desirable — especially at scale. So it was a relief that at AIEWF, agents were largely positioned as augmenting the AI engineer, rather than replacing them.
During the OpenAI keynote on day 2 at AIEWF, Romain Huet emphasized this point. Using tools like OpenAI’s Codex, Huet argued, engineers can more easily collaborate with agents. As he put it, “software ate the world, and then AI ate software, but now what we’re here to say is that the AI engineers are eating the world.”
Despite the growing power of AI engineers, there’s also a sense that even the frontier companies don’t fully understand how their models are evolving — and so how much control can engineers truly have over them? In a separate keynote, Anthropic’s Thariq Shihipar talked about how their latest model, Claude Fable, is like an organic system — “models are grown, not designed.” There’s a “capability overhead,” he said, where “Claude gets smarter in a spiky way.”
All the more reason to build systems for agentic development, so that we can evaluate and monitor the outputs.
2: Loop engineering is the new control layer
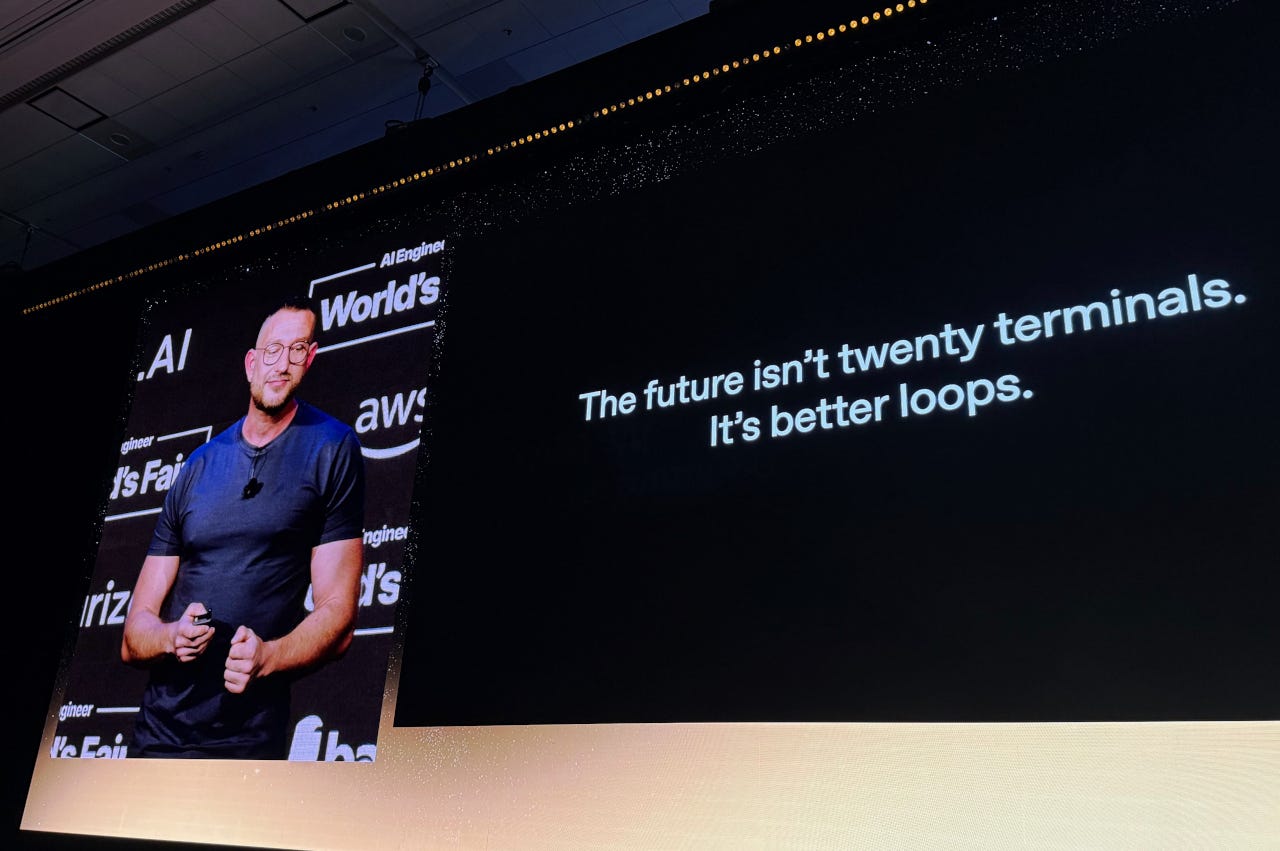
By the end of the first morning of keynotes at AIEWF, it was clear that “loops” was the buzzword du jour of the event. Overuse of the term aside, it did highlight a key point of tension around AI engineering: how much control should agents have, and where should humans remain in the loop?
OpenClaw creator Peter Steinberger advocating for better loops.
One approach a lot of leading engineers are now taking is putting themselves in an “outer loop” — to oversee the largely autonomous work being done by agents in an inner loop.
Roland Gavrilescu is co-founder and CEO of Introspection, a new company building infrastructure for deploying self-improving systems. In an interview with Latent Space, he explained how the concept of “autoresearch” provides the necessary feedback structure for agent loops:
“You can think of the system as having an inner loop and an outer loop. The inner loop is the primary system interacting with users and performing the work. Autoresearch is more concerned with the outer loop: another system that studies and maintains the primary system.“
The outer loop can include feedback signals, evals and human input. So it might still be largely autonomous, but the point is it is a method of oversight for the primary agent loop. Former Google engineering leader Addy Osmani had a nice line relating to this, saying that “agents can run much more of the inner execution loop, but that outer loop is still engineering.”
The term “loop engineering” came up multiple times during AIEWF, suggesting that it’s the human AI engineer’s responsibility to build these loop systems. Even the “ClawFather” Peter Steinberger, creator of OpenClaw, makes a point of putting himself in the outer loop. In the OpenAI keynote, he explained that “the agent runs the inner execution loop; I set the direction and I make decisions in the outer loop.”
The Loop Debate at AIEWF.
On the final day, an on-stage debate was held to determine whether fully autonomous agents were capable of managing loops in reality. Dex Horthy from HumanLayer claimed that “the hype is outrunning the discipline.” He wasn’t against loops, per se, noting that Kubernetes is built on control loops — “but they’re deterministic loops.” Geoffrey Huntley, creator of the Ralph Loop, admitted that loops were “frontier thinking,” but he had a wonderful analogy for the audience to ponder:
“[We’re] kind of like locomotive engineers now. That’s our job: to keep the locomotive on the rails.”
3: AI engineering enters the enterprise
This way of working with AI tools is starting to make its way into enterprises, typically via a new role called a “forward deployed engineer” (FDE) — where engineers work directly with organizations to implement AI capabilities.
Natalie Meurer, who leads FDE at Sierra, told Latent Space that implementing AI into organizations typically requires a lot of orchestration. “Every enterprise we work with wants to know how it can maintain everything its agentic ecosystem is capable of doing,” she said. “It needs to manage all the integrations and all the teams that contribute to the agent.”
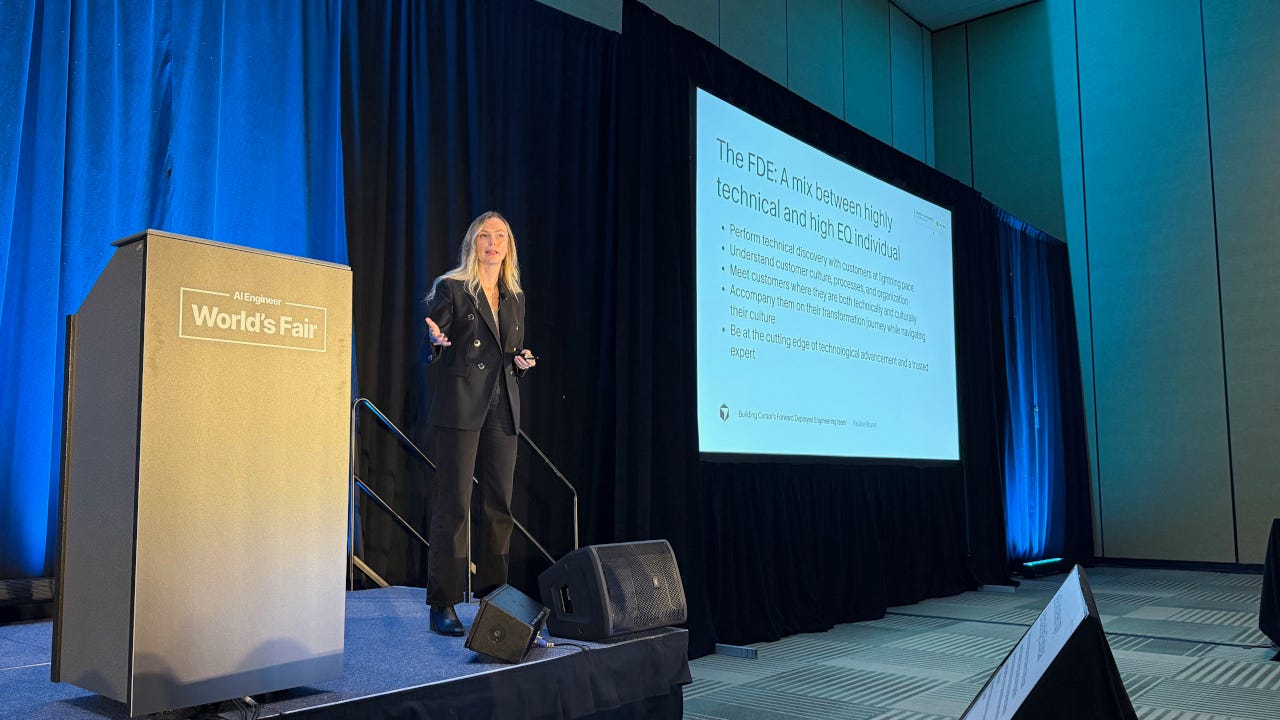
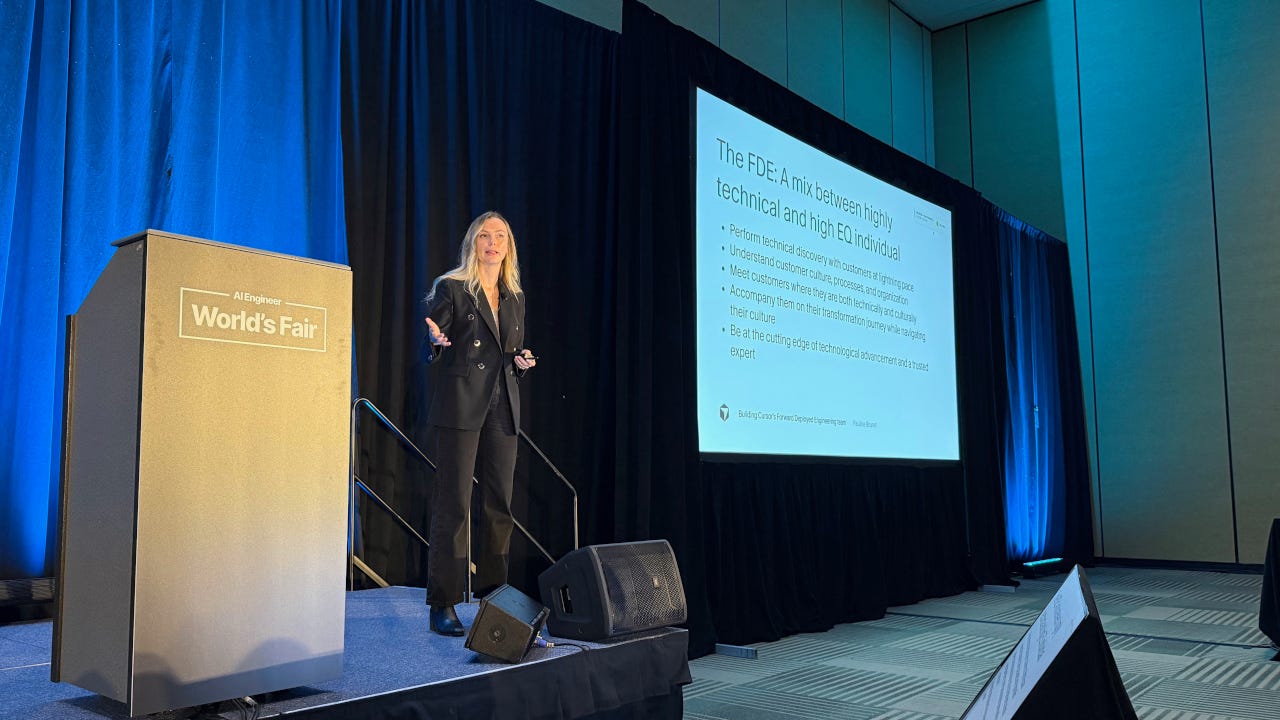
Cursor’s Pauline Brunet talking about FDEs in an AIEWF session.
In her session at AIEWF, Cursor’s Pauline Brunet spoke about what their FDEs look to achieve in each engagement:
“When [we] walk away at the end of the engagements — and we, in our case, have deployed cloud agents, long-running agents, automations, [and] we’ve built applications on top of our Cursor SDK — that when we walk away, it is a strict ROI for them. That means they’re not gonna turn things off when we leave.”
Another term used regularly at the conference was “software factory.” At Cursor, “a software factory means long-running agents helping people throughout that entire process,” said Brunet. This is basically what her team of FDEs is responsible for implementing, sitting alongside their customers’ engineers.
Where human engineers fit into a software factory is a key issue for enterprises. Warp CEO Zach Lloyd explained that organizations need to choose which parts of the lifecycle to automate, and where humans should be brought into the loop.
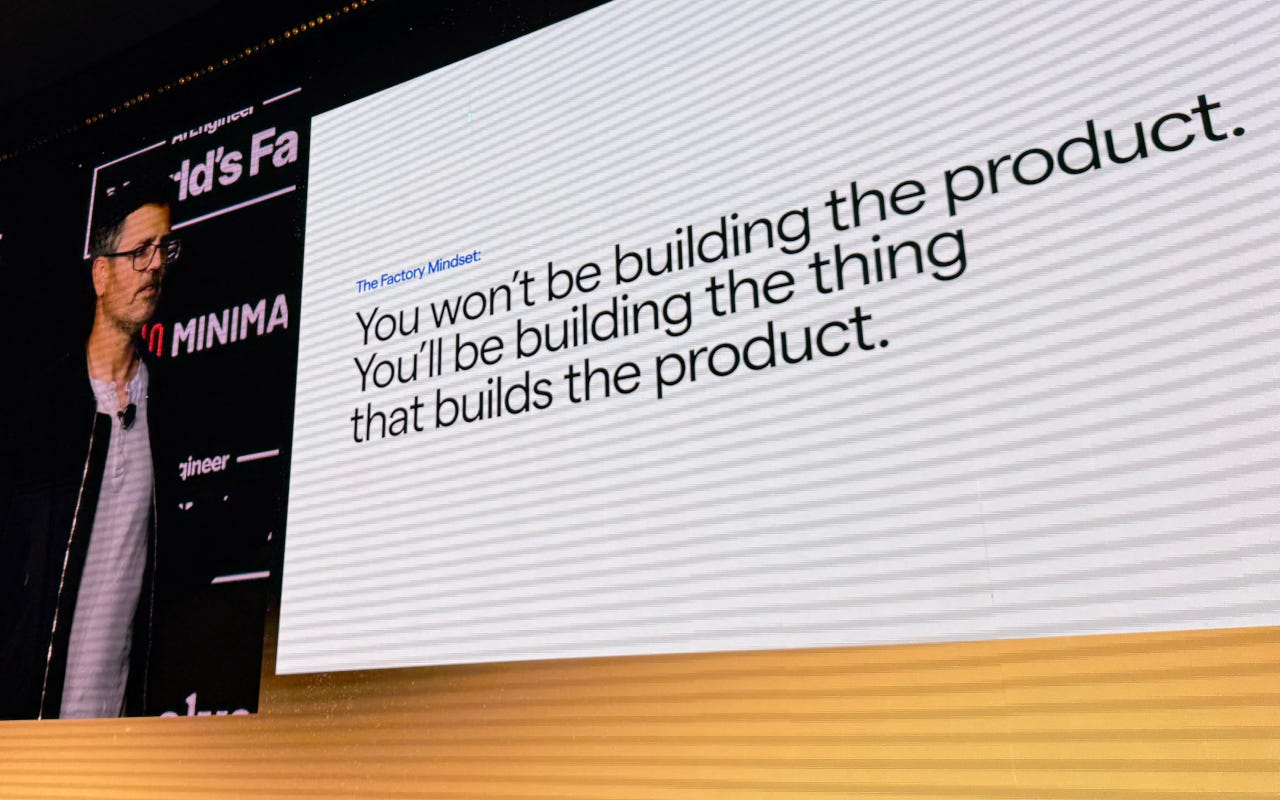
Warp’s Zach Lloyd on building the thing that builds the product.
“You choose your repositories, the parts of the software lifecycle you want to automate, and the points where humans should be brought into the loop,” Lloyd told us, regarding his company’s new software factory platform, Oz. “Different organizations and codebases will have different preferences. Do you fully automate code review? Do you have humans review certain high-risk changes?”
Another concern for enterprises is managing their unique organizational data in AI systems. Prukalpa Sankar from Atlan spoke at the conference about “context engineering,” explaining in a tweet that it’s important to consider “how context flows from your business systems into a shared company brain, then out to agents, copilots, and apps through MCP, APIs, and retrieval.”
Finally, lest we think enterprises are all-in on agents, Cursor’s Brunet pointed out that enterprise adoption of AI “is still concentrated among early adopters.” So finding “the right champions inside an organization” is a challenge for FDEs at this stage.
4: Coding agents replace IDEs as the developer interface
Perhaps the biggest practical change since the first AI Engineer Summit is how developers interact with AI on a daily basis.
In 2023, AI-assisted programming largely meant GitHub Copilot completing the next few lines of code. Most developers were still writing almost everything themselves, using AI as an intelligent autocomplete. But now we have tools such as Claude Code, Codex, Gemini CLI, Cursor and Warp. These “coding agents” can typically understand a broader objective, explore a codebase, modify multiple files, run tests, debug failures and iterate on their own work before presenting it back to the developer.
In Barr Yaron’s AI engineering survey, coding agents was a key trend.
The trend of coding agents now extends to web development too — with the recent release of Vercel’s eve, which the company calls an “agent framework,” comparable to its popular open source React framework, Next.js.
Vercel’s Chief of Software, Andrew Qu, told Latent Space at AIEWF that agents are effectively a new type of software. “They [agents] are not as predictable as web applications,” he explained. “The infrastructure can look similar, but the interaction, interface and outputs are much more dynamic.”
Qu added that the job of building a framework for agent development is far from over. “A year ago, we did not know sandboxes would become so important, or how much demand there would be for secure code execution and long-running jobs,” he said. “As we learn more from production, there will be much more to build.”
A for agents? Andrew Qu flashes the Vercel triangle logo.
This brings us back to the software factory trend, when developers are managing multiple agents. Charlie Holtz, CEO of Conductor, reminded the AIEWF audience that regardless of the coding harness, human engineers should always remain in control.
“I don’t want the future to be built around factories,” Holtz said. “I want to feel like a human, I want to be in the flow, I want to be in front of an orchestra, waving my baton.”
There was a sense during the conference that AI engineers aren’t yet aligned on which term is more appropriate: software factories or orchestras? Even Geoffrey Huntley, a loopmaxxing advocate, cautions about getting ahead of ourselves when it comes to automation:
“My biggest concern is that this time next year at the conference, we’re going to see a whole bunch of folks saying, our factories failed, our loops failed. These are things that we are still yet to figure out.”
5: Every agent platform is building around skills
One of the talking points of the conference was “skills,” a concept Anthropic popularized when it introduced “agent skills” to Claude last October. To borrow Addy Osmani’s definition, skills “encode the workflows, quality gates, and best practices that senior engineers use when building software.”
At AIEWF, Vercel’s Andrew Qu said that skills were “useful as portable, on-demand knowledge.” Introspection co-founder Roland Gavrilescu declared that AI engineering has shifted “from agent tools to agent skills.”
In a session on the main stage, Philipp Schmid from Google DeepMind showed how using skills (and other declarative Markdown files) allows developers to use “agents without code.” His main point was that skills reduce the need for orchestration code, which up till recently was typically done using Python. His conclusion:
“Agents are just files. We write markdown files to extend capabilities. Agents can learn from those, can create their own files.”
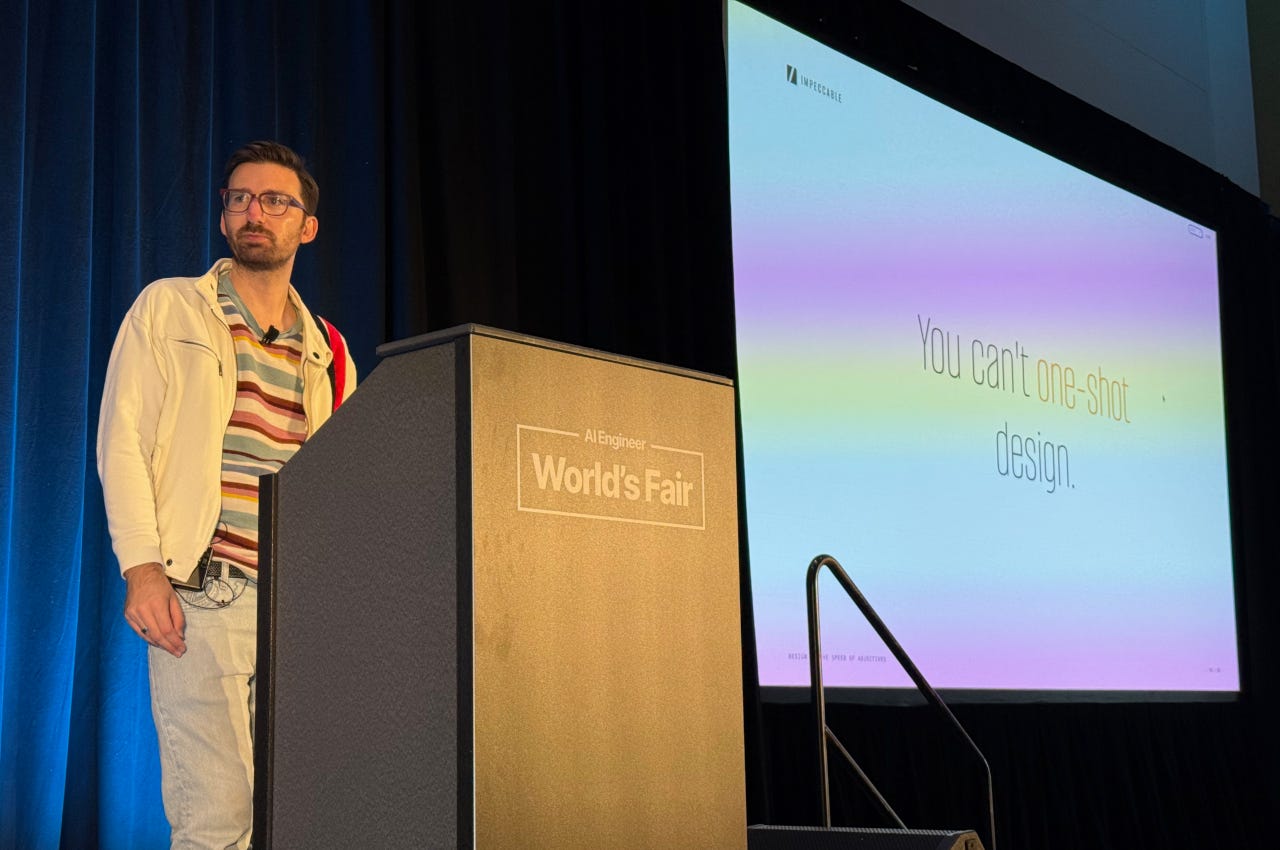
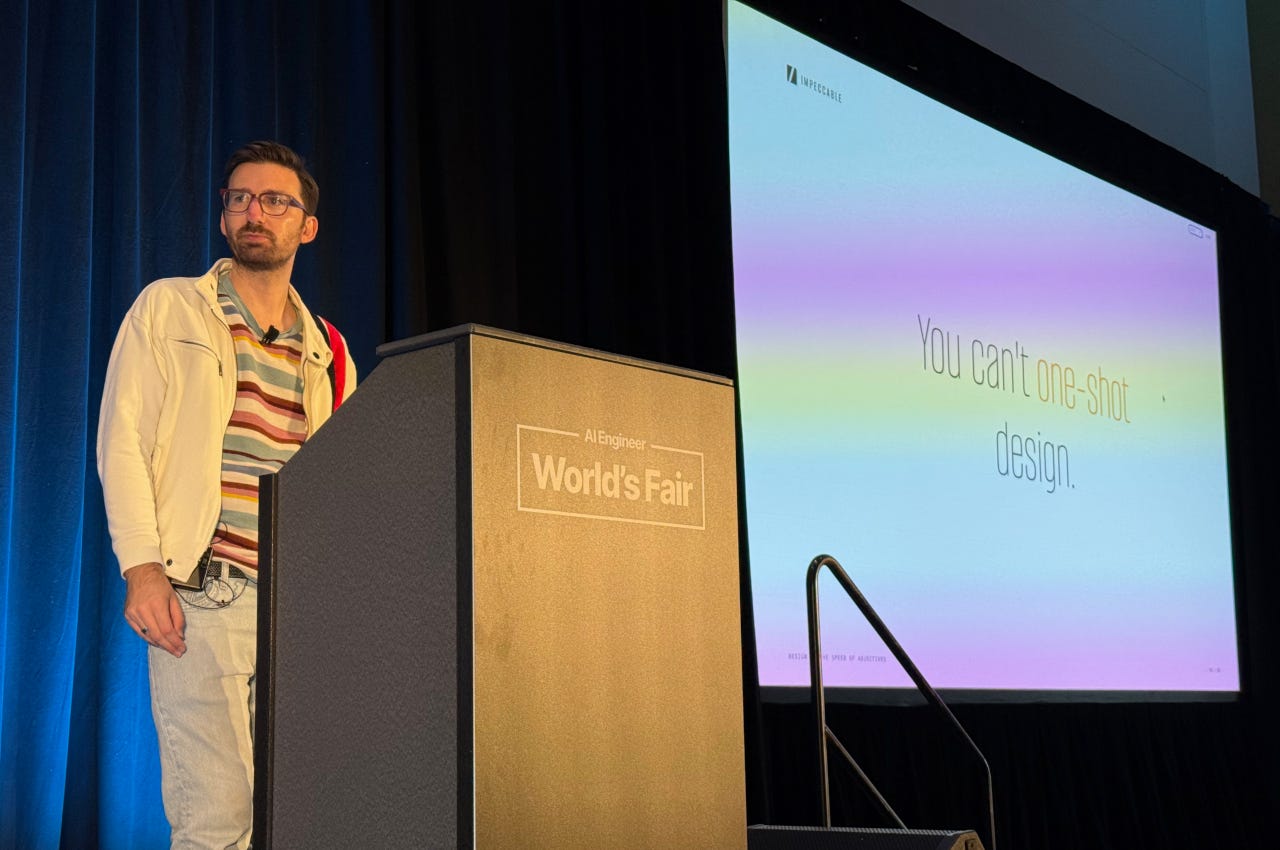
Paul Bakaus, who used to work for Google but now runs a company called Renaissance Geek, has created an entire project around agent skills. Impeccable is an open source design skills system that gives coding agents a vocabulary for improving interfaces. He even advocates for “skill engineering” as a discipline in its own right.
Paul Bakaus: “You can’t one-shot design.”
In an interview with Latent Space, Bakaus argued that most skills — and indeed most models — are not very creative. “They converge in one direction, and if everybody uses the same skill to do frontend design work or something like that, everything ends up looking the same,” he said.
Apparently there’s also such a thing as “skills hell,” which Matt Pocock said is comparable to previous developer frustrations — like frameworks hell. In a virtual presentation, Pocock provided a detailed checklist for writing skills, which you can see in the video below. In a nutshell, he advises writing fewer and smaller skills, and putting more thought into structure.
In a closing keynote, Y Combinator president Garry Tan implored the audience to use skills and other “AI native” approaches at their own startups or employers. Talking about business functions like sales, support and finance, Tan said that “the AI native companies that I see inside YC encode all of that as skills, written procedures that their agents execute, and they hire engineers whose job it is to maintain those skills, to do the work the skills can’t do yet.”
But again, there’s a danger in relying too much on what agents autonomously do. As AIEWF attendee Tyler Brown noted on X, “autonomy without structure creates as much slop as leverage.” One of his learnings from the conference was to “re-visit and re-implement your skills”:
“Each time there’s a new model release, it’s as if you have a kid that grows from middle school to high school. You have to change the curriculum for them to get the benefits of the new model.”
Agent engineering at scale
It’s been three full years since The Rise of the AI Engineer and the first AI Engineer Summit. Looking back, it really is striking how much the conversation has evolved. Three years ago, the focus was on proving that LLMs could act as autonomous agents at all (and the answer at that time was usually no). AutoGPT, prompt engineering, and early orchestration frameworks like Langchain dominated the discussion back then.
Now that agents not only work, but have proven they can scale, this year’s AI Engineer World’s Fair was able to concentrate on the bigger problems: building reliable systems, orchestrating teams of agents, managing context, evaluating outputs and integrating AI into production software.
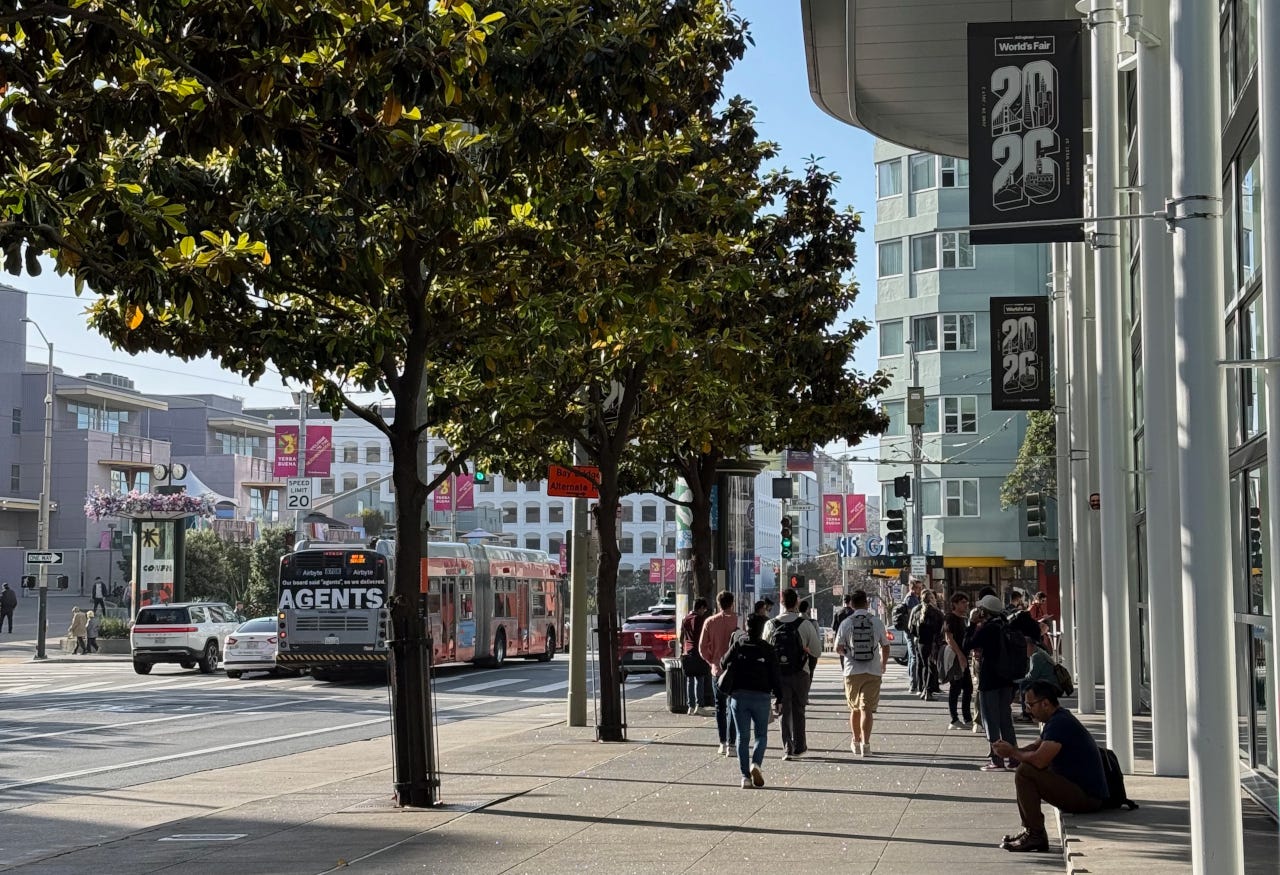
Agents are everywhere now…even on the back of San Francisco buses.
The term “AI engineer” may have started life as a new job title, but at AIEWF 2026 it felt more like a description of where software engineering itself is heading. Whether developers call themselves AI engineers, software engineers or Forward Deployed Engineers, they’re increasingly working with the same set of ideas: coding agents, harness engineering, designing loops, and orchestration.
Comparatively, the last update we got about Claude Code is the roughly 2M users and $2.5B ARR in Feb (“The number of weekly active Claude Code users has also doubled since January 1 [six weeks ago]."). Now we have a sense of where Codex started the year (Fidji puts the Jan 1 number at around 550k-700k users), we can reasonably conclude that Codex has followed a similar trajectory and is now around 10x user growth year to date.
Agent RL Infrastructure: Prime Intellect’s Verifiers v1 and Long-Horizon Rollouts
Prime Intellect’s verifiers v1: Prime Intellect released verifiers v1, a substantial redesign of its environment stack for agentic RL and evals. The key abstraction splits environments into a taskset, harness, and runtime, explicitly supporting “bring your own harness” workflows for coding and computer-use agents across heterogeneous execution setups, as highlighted by Johannes Hage and in a follow-up deep dive. The release was framed by team members as months of infra modernization work with major efficiency gains, including richer commentary from willccbb, mikasenghaas, and xeophon.
Why it matters technically: one of the most important underlying changes is that rollout traces are now stored as message DAGs, so each message is stored once instead of repeatedly copied into full histories; that shifts trace growth from O(n²) to O(n) in turn count, making long-horizon multimodal rollouts and router replay much more practical, per Prime Intellect. The team also claimed a concrete training configuration: a 100B reasoning model, on 40-turn SWE agent tasks, in a user-supplied coding harness, for 1000 RL steps, using 6 H200 nodes in under 2 days (willccbb). That claim was reinforced by ecosystem support from vLLM, which noted verifiers’ rollout path runs on vLLM with exact token IDs/logprobs to avoid tokenization drift between serving and training.
Coding Agents, Harness Design, and Cost-Per-Task Competition
Harnesses are becoming the product surface: several posts converged on the idea that model quality is no longer the only differentiator; the harness/orchestrator increasingly determines outcomes. threepointone’s talk was summarized as “the harness is the app,” while LangChain argued that winning agent products will come from task-specialized harnesses, not generic wrappers. Factory pushed a related UI angle with “design mode,” where users point at UI elements/files instead of verbally re-specifying edits. On the orchestration side, omarsar0 emphasized provider-switching across models as a hedge against pricing/policy churn.
Benchmarks are moving from token price to cost per task: skirano built a coding-agent index explorer and found notable cost/perf tradeoffs such as Terra Max slightly ahead of Fable 5 Max on score for materially lower cost, while Cognition reported that Devin Fusion now uses Fable 5 and that, surprisingly, it can be lower cost per task than Opus 4.8 because stronger delegation and judgment reduce unnecessary work. imjaredz highlighted the key stat from those experiments: in 81% of Fable-led runs, the lead model never makes a code edit, implying expensive models can be cheaper when they avoid wasted actions.
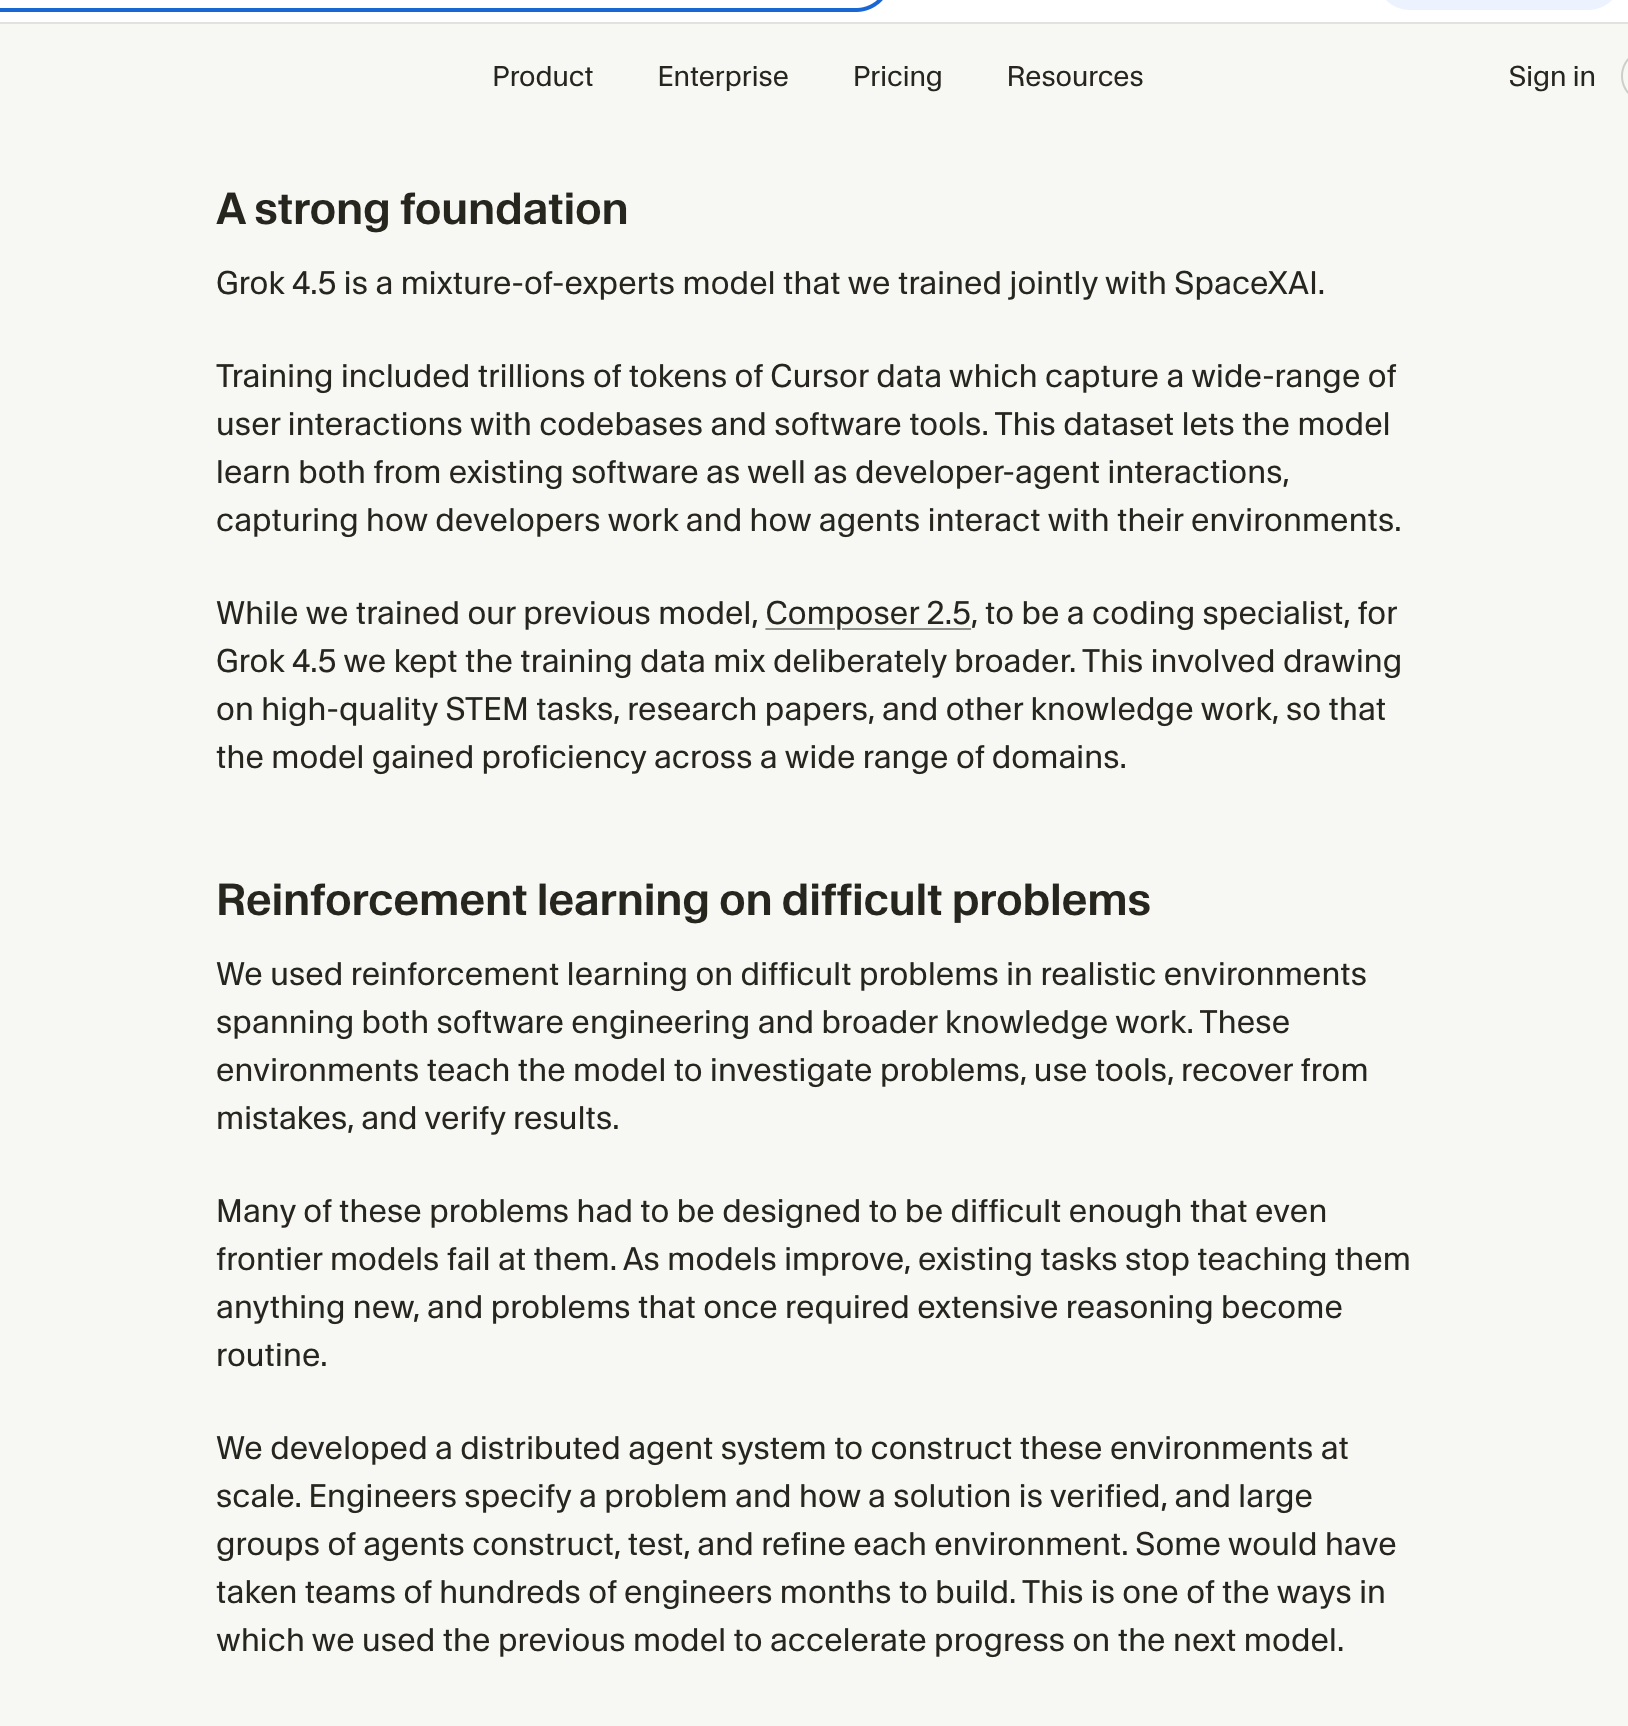
Real-world agent benchmarks are getting denser: Arena placed GPT-5.6 Sol at #2 on its agent leaderboard based on 7.8K real-world agentic sessions, with strong steerability and task success; later, Arena put Grok-4.5 at #13, a significant jump over Grok 4.3. Artificial Analysis also emphasized cost per task as an increasingly important metric for long-horizon knowledge work, arguing token pricing alone misses effects from turns, verbosity, and cache hit rates. Separate evaluation work from Parlance Labs compared automated eval platforms and foundation models on failure analysis over production voice-agent traces, while dair.ai highlighted a paper on the anatomy of CLI coding-agent failures, focusing on where runs become unrecoverable rather than only final pass/fail.
OpenAI GPT-5.6 Sol, Codex Usage Fixes, and Product Surface Expansion
OpenAI addressed Codex/Sol usage burn transparently: the biggest operational thread came from thsottiaux, who explained several fixes for GPT-5.6 Sol in ChatGPT Work/Codex: inference optimizations yielding roughly 10% more usage, a rollback of context limit from 372k to 272k after billing/usage side effects, reversion of some experimental reasoning-effort (“juice”) changes, and fixes for overactive multi-agent behavior at high/xhigh settings. Community reverse-engineering from theo proposed that compounding factors around long context, subagent spawning, and fast mode were behind the severe burn, though he later corrected one billing detail in a follow-up. Reactions split between criticism of a perceived “nerf” narrative (ns123abc) and praise for unusual transparency (theo, sama).
Users are reporting strong coding/computer-use capability: multiple practitioners argued that OpenAI has taken the lead on coding models, including schrockn, while gdb repeatedly showcased ChatGPT Work and Codex workflows for startup prospecting, web design, mobile work, and site generation. Particularly illustrative user demos included Star_Knight12 using Sol in Cursor to set up Blender MCP and render a floating MacBook without prior Blender experience, and petergostev showing GPT-5.6 Sol Ultra building a Doom-like game in SQL.
Product-level expansion continues: ChatGPTapp announced ChatGPT’s return to WhatsApp in the EEA, plus Kakao/Viber support in additional markets. OpenAIDevs opened submissions for OpenAI Build Week. Across the OpenAI ecosystem, gdb summarized the moment succinctly: “you can just create things.”
Open Models, Inference Systems, and Quantization
Transformers↔vLLM integration removes duplicated model implementation work: Clement Delangue highlighted a major open-inference usability improvement: Hugging Face Transformers models can now run in vLLM at native speed, often matching or exceeding hand-written implementations. If this generalizes broadly, it reduces the long-standing burden of implementing each new architecture twice—once for research/training and once for high-performance serving—and could materially accelerate adoption of new open model architectures.
Quantization remains a major lever: waterloo_intern previewed a new quantization method claimed to beat existing approaches, including NVIDIA’s ModelOpt, by finding better layerwise precision assignments faster, with more aggressive quantization and higher benchmark scores. Complementing that, Unsloth published an AWS guide to LLM quantization and deployment spanning GGUF, NVFP4, and FP8. There was also practitioner commentary around fp4 RL / fp4 serving from nrehiew_, arguing low-bit post-training may enable cheap serving with limited quality loss.
GLM-5.2 and local/open coding stacks continue to gain traction: several users described moving real workflows onto open or semi-open setups. juanjucm wrote up using GLM-5.2 for coding-agent workflows, while TheZachMueller reported migrating one actual work pipeline from Claude to a stack built around GLM 5.2 NVFP4 plus Kimi K2.7 Code NVFP4 on an 8xB200 node, getting denser reports for pennies albeit at slower wall-clock latency. nutlope also released LlamaCoder v4, rebuilt around GLM 5.2.
Security, Privacy, and Data Control in Agent Tooling
Grok Build code upload controversy: the most consequential security story came from IntCyberDigest and hrkrshnn, who alleged that xAI’s Grok Build CLI was uploading entire repositories—including private code and secrets—to a Google Cloud bucket, far beyond what was needed for the coding task. The criticism centered on scope, silent server-side mitigation, and unclear retention/deletion guarantees. This triggered broader discussion about what agent tools actually transmit and why opt-out UX can diverge from wire-level behavior.
xAI’s response emphasized ZDR and privacy controls: SpaceXAI replied that for teams using zero data retention, trace and code data is not retained, API key use respects ZDR, and the /privacy command can disable retention and delete previously synced data. That answered some operational questions but did not fully resolve community concern around default behavior, prior uploads, and disclosure norms.
Trust boundaries are becoming a central open-vs-closed argument: several posts extended the conversation beyond this incident. mchiang0610 and jmorgan argued that open models are not just about cost but about control over the human-AI learning loop and keeping institutional knowledge in-house. Arav Srinivas said ZDR availability was one reason Perplexity integrated Grok 4.5 quickly into its Computer harness.
Continual Learning, Multimodal Systems, and Research Directions
Continual learning is re-emerging as a first-class systems problem: ysu_nlp argued that a world where every organization owns its own human-AI learning loop depends on solving continual learning, and that current approaches—memory/RAG, domain post-training, task RL—are not yet sufficient. That theme recurred in new work from skyfallai, which introduced Morpheus, described as a persistent enterprise simulation for real-world RL where the world does not reset; fchollet endorsed it as a benchmark better aligned with real deployment than stationary episodic RL.
“Sleep and dreaming” for LLMs: behrouz_ali and coauthors proposed that LLMs may need a sleep phase to consolidate short-term into long-term memory plus a dreaming phase for recursive self-improvement, introducing Knowledge Seeding and reporting benefits on continual learning/reasoning tasks. This dovetails with broader dissatisfaction around current continual-learning recipes and with Oak Lab, the new venture from Rich Sutton and collaborators pursuing animal-like intelligence that learns from experience rather than today’s standard LLM pipeline.
A broad spread of non-LLM-agent research shipped: notable items included Sakana AI’s Smart Cellular Bricks for decentralized physical self-recognition and repair in modular systems; ByteDance’s UniVR-34B, described as learning reasoning/dynamics/planning directly from visual demonstrations; Google DeepMind’s Predicting the Past skill for historical inference workflows; and Anthropic’s research on how Claude’s expressed values vary across models and languages based on analysis of 300K+ anonymized conversations.
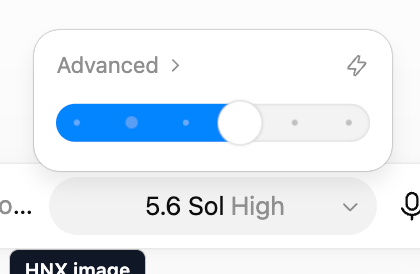
After buying Statsig and making a big deal out of GPT5’s routing/getting rid of the model picker, the main issue now is that GPT 5.6’s extra options are confusing people a bit. Most people just have a single slider:
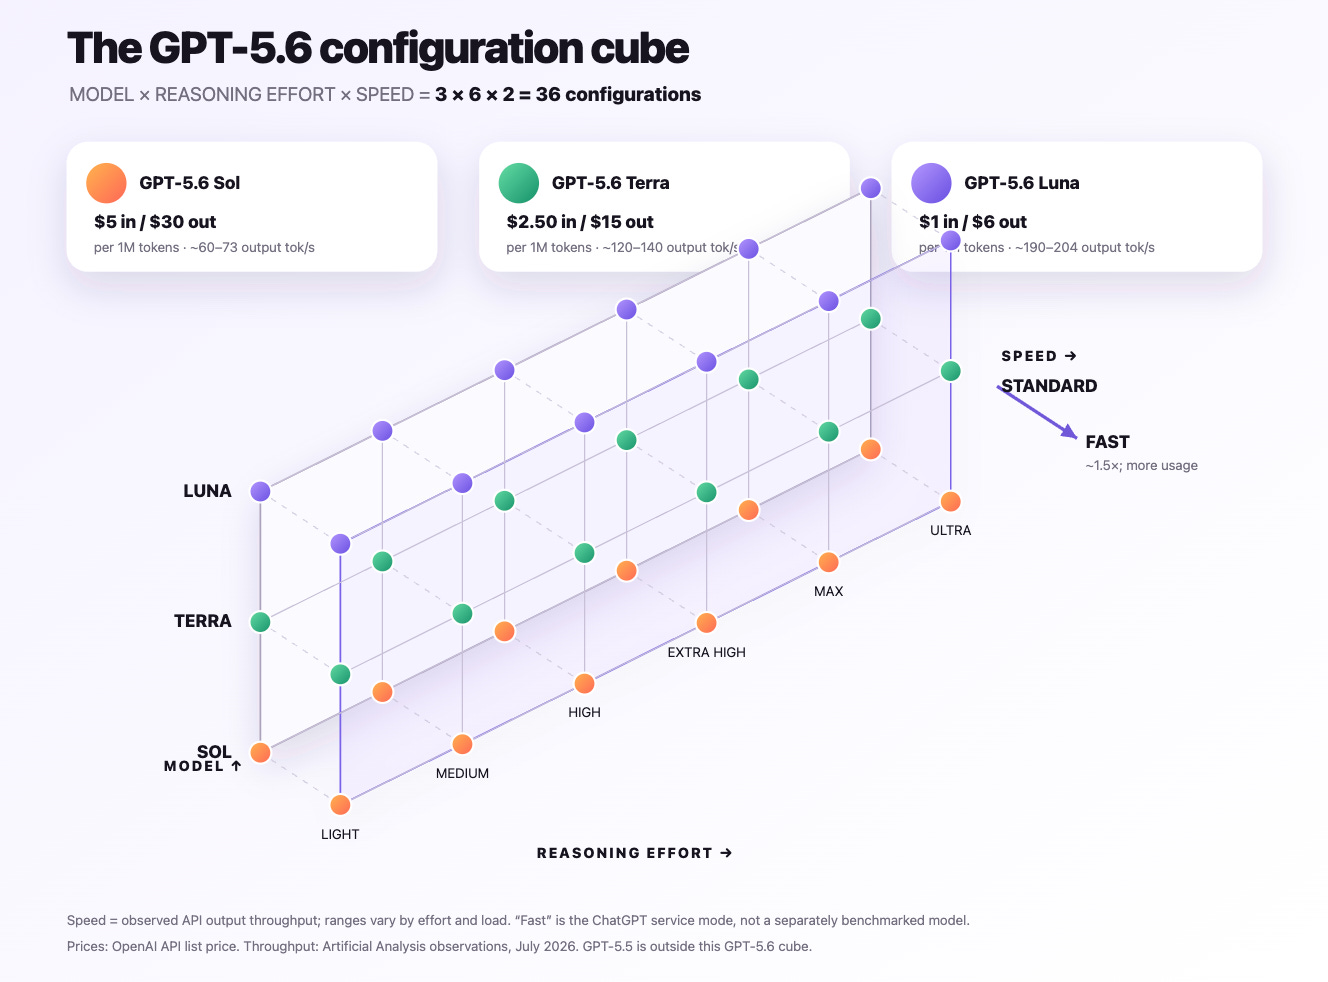
But API users have literally 36 variants of GPT 5.6 now:
Most people can get by with just 3 rough clusters
And many guides are coming up:
The top AIE talk so far this week has been Theo’s closing keynote, and the last of the online track will be released this weekend.
OpenAI’s GPT-5.6 rollout: model stratification, agent UX, and early benchmark signals
GPT-5.6 introduced a more explicit model/compute ladder: users are now navigating Luna / Terra / Sol plus multiple effort levels, with community guidance converging around “start lower than you did on 5.5.” OpenAI staff explained that Max means one model spending longer on a hard problem, while Ultra parallelizes work across subagents; they also noted that 5.5→5.6 effort settings are not directly comparable (guidance from @reach_vb, follow-up, practical default suggestion). The community reaction was mixed: many praised the added control, while others criticized the 30+ configuration combinatorics and missing “Auto” routing (@rasbt, @Yuchenj_UW).
The product launch landed with real UX regressions, and OpenAI publicly course-corrected fast: users complained that the new ChatGPT Work / Codex split was confusing, chats/projects became harder to find, and usage burned down faster than expected (@scaling01, @simonw, @kimmonismus). OpenAI responded unusually directly: multiple usage-limit resets, acknowledgements that defaults nudged users toward overly expensive settings, and a commitment to restore familiar sidebar/navigation patterns and clarify positioning between Work and Codex (@thsottiaux reset announcement, second reset, full corrective roadmap).
Initial eval picture: GPT-5.6 appears strongest in agentic coding / presentation / some science tasks, but not unambiguously dominant everywhere. Examples: #1 tie in Code Arena: Frontend with Claude Fable 5 while being ~2× cheaper on listed IO pricing (Arena); best recorded Presentation Elo on AA-Briefcase with a ~500-point jump over GPT-5.5 (Artificial Analysis); CritPt gains over GPT-5.5 and beats Fable 5 by ~4 points (Artificial Analysis); and strong results on WeirdML at lower cost (@htihle). At the same time, users reported instruction-following issues, uneven token efficiency in practice, and some concern about jailbreakability / reward hacking (@teortaxesTex, @Mononofu, @kimmonismus).
Parallel-agent workflows, computer use, and the “harness is the product” theme
GPT-5.6’s biggest perceived leap may be orchestration and computer use rather than pure chat quality. Multiple users highlighted that Sol is unusually strong as a planner / verifier / orchestrator, often using subagents automatically and reacting more quickly to steering (@omarsar0, @Hangsiin). OpenAI also showcased computer use with Sol Ultra and promoted ChatGPT Work as bringing agents to consumer/mobile scale (OpenAI demo via @gdb, Work positioning). Community reports described very high-throughput GUI automation and Blender workflows (@mckbrando, @kimmonismus).
A recurring operational issue is hidden subagent cost explosion: users found that spawned agents may inherit premium settings, draining quotas much faster than expected. One concrete claim was that spawn_agent doesn’t let users choose model/effort, so Sol Ultra spawns more Sol Ultra by default (@evi77ain). This fits the broader pattern of people liking the capability jump but finding the cost model opaque.
The broader systems trend is toward harness-centric competition. This came through in product commentary from Perplexity’s Arav Srinivas (“the real product is now the harness around it”), in LangChain’s launch framing around Deep Agents + Nemotron + OpenShell, and in a growing set of memory / orchestration tools like OpenWiki and OpenSWE (@dee_bosa quoting Arav, @hwchase17, OpenWiki proactive memory, OpenSWE adoption). The meta-point: frontier model parity is tightening, so value is increasingly shifting to routing, memory, tool use, safety rails, and enterprise context.
Meta’s Muse Spark 1.1 and the widening frontier of “good enough, fast, cheap” models
Muse Spark 1.1 was the other major model story of the day, with many practitioners calling it the most surprising release of the week. Reports consistently emphasized strong UI/frontend generation, fast responses, and unusually aggressive pricing, often framing it as near-frontier quality for a large subset of coding/product tasks (@alexandr_wang, @rowancheung, @kimmonismus).
Benchmarking suggests a real step up, but not outright frontier leadership. Artificial Analysis scored Muse Spark 1.1 at 51 on its Intelligence Index, up 8 points from 1.0, roughly tied with GLM-5.2 / GPT-5.4 / GPT-5.6 Luna and behind Grok 4.5 / GPT-5.6 Sol / Claude Fable 5. Notable details: 1M context, median speed ~114 tok/s, pricing $1.25 / $4.25 per 1M input/output tokens, and strong token efficiency (Artificial Analysis). Arena also placed it #9 on Code Arena: Frontend with strong gains in instruction-following and longer-query categories (Arena).
The strategic implication many drew: Meta’s compute-heavy bet is starting to show up as cost-effective inference products, not just talent headlines. Several commentators argued this materially raises competitive pressure on OpenAI/Anthropic, especially if Meta improves distribution and API ergonomics (@scaling01 asking for OpenRouter, @alexandr_wang, @mweinbach).
Open models, infra, and efficiency work
Open-model tooling kept shipping despite the closed-model attention vacuum. Unsloth released Qwen3.6 NVFP4 quants with claims of 2.5× faster inference, including 27B on 24GB VRAM and a 35B-A3B variant hitting 17,561 tok/s on B200 (Unsloth, technical details from @danielhanchen). QuixiAI reported Qwen3.6-35B-A3B-NVFP4 on dual B60 at 65 tok/s and 128k context (QuixiAI).
Inference optimization remains a major live research area. Cohere open-sourced Hardware-aware Dynamic Speculative Decoding in vLLM, addressing the familiar issue where speculative decoding helps at low batch sizes but hurts at high ones (Cohere/vLLM, vLLM commentary). Google/Hugging Face’s Gemma challenge reported up to 5× faster single-A10G inference, with 315 TPS lossless and 491.8 TPS fastest overall (Gemma).
Agent evaluation / self-improvement work is getting more concrete: “LLM-as-a-Verifier” reported SOTA on Terminal-Bench V2, SWE-Bench Verified, RoboRewardBench, and MedAgentBench using repeated sampling plus score-logprob ranking (paper thread); Meta researchers proposed an explicit memory agent to combat behavioral state decay in long-horizon agents (summary).
Science, math, health, and modality-specific systems
Math/science capability claims escalated sharply. OpenAI staff and community members circulated examples of GPT-5.6 Sol Ultra producing a claimed proof of the Cycle Double Cover Conjecture using 64 subagents in under an hour (claim from @eknight, amplified by @gdb). Separately, Bubeck noted a single-person 1M-line Lean formalization effort with GPT-5.6 (@SebastienBubeck). These are still claims pending external scrutiny, but they indicate where labs want the narrative to go: parallelized research agents as a scientific compute primitive.
Health is becoming a first-class benchmark and product vertical. OpenAI said GPT-5.6 is a major step forward for health intelligence, highlighting that Luna at lowest effort beats GPT-5.5 at highest effort while costing 25× less (OpenAI). Karan Singhal added that, in blinded physician comparisons over 20,000 axis ratings, physicians found fewer flaws in GPT-5.6 responses than physician-written responses across a hard task set (details).
Audio/music and creative tooling also moved: Kyutai + Mirelo released MuScriptor, an open model for multi-instrument audio-to-MIDI transcription from full mixes, not stems (MireloAI, Kyutai). Sakana’s new Picbreeder-style work explored open-ended creativity with VLM agents, concluding that diverse agent populations help but still fall short of human open-ended exploration (Sakana).
Security, safety, and policy frictions
Security concerns rose alongside capability gains. OpenAI moved its Bio Bug Bounty into a private ongoing program and doubled rewards to $50K, specifically seeking universal jailbreaks against predefined biosafety challenges (OpenAI). Separately, OpenAI tightened access requirements for its most cyber-capable models, requiring hardware security keys for Trusted Access for Cyber members starting Sept. 1 (@cryps1s).
Evidence of misuse remains salient: a new study reported Boko Haram members using frontier chatbots for bomb-making and related tactical queries (@AntoniaJuelich). That thread sat uncomfortably next to ongoing online discussion that GPT-5.6 may be relatively easy to jailbreak or reward-hack in some settings (@Mononofu).
Policy discourse remains polarized and speculative. The “AI 2040 / Plan A” transparency-and-governance scenario drew both support and ridicule, with Ajeya Cotra emphasizing the centrality of total research transparency while critics questioned feasibility and assumptions about superintelligence/governance capacity (@ajeya_cotra, @binarybits, @banteg satire).
Top tweets (by engagement)
OpenAI launch and rollback management: OpenAI’s product lead acknowledged launch confusion, promised UI fixes, and reset usage twice while clarifying that Codex is here to stay (full thread).
Claude Code desktop browser: Anthropic shipped an in-app browser for Claude Code desktop so Claude can browse docs/sites inside the app (@ClaudeDevs).
OpenAI org update: Fidji Simo announced she is leaving her full-time role at OpenAI and becoming a part-time advisor, citing the need to focus on recovery from chronic illness while continuing work related to AI and health (@fidjissimo).
Perplexity harness expansion: Perplexity added Grok 4.5 as an orchestrator in Computer after internal evals showed strong WANDR performance at roughly half the cost of Opus 4.8 (Perplexity).
On any other day, the launch of a surprisingly good/competitive Muse Spark 1.1 from Meta Superintelligence Labs, including, for the first time, in the Meta Model API (signaling high confidence for broad usage and third party testing which is bearing out in their sister models), would deserve title story status, but they had the misfortune of going up against a mainline frontier model launch:
As previewed a couple weeks ago before government approval, 5.6 comes in three new sizes, Sol, Terra and Luna, corresponding to the sizes of Sun, Earth and Moon, as an alternative to the more literary sizing of Claude variants, and a new ultra effort level, “our highest-capability setting, coordinating multiple agents across parallel workstreams to finish complex tasks faster”:
max gives GPT‑5.6 even more time than xhigh to reason and explore alternatives, run checks, and revise its approach. ultra goes further by coordinating four agents in parallel by default, trading higher token use for stronger results and faster time-to-result on demanding tasks.
On multiple benchmarks (not just the ones featured here), 5.6 both achieves higher performance at lower cost than Fable or Opus.
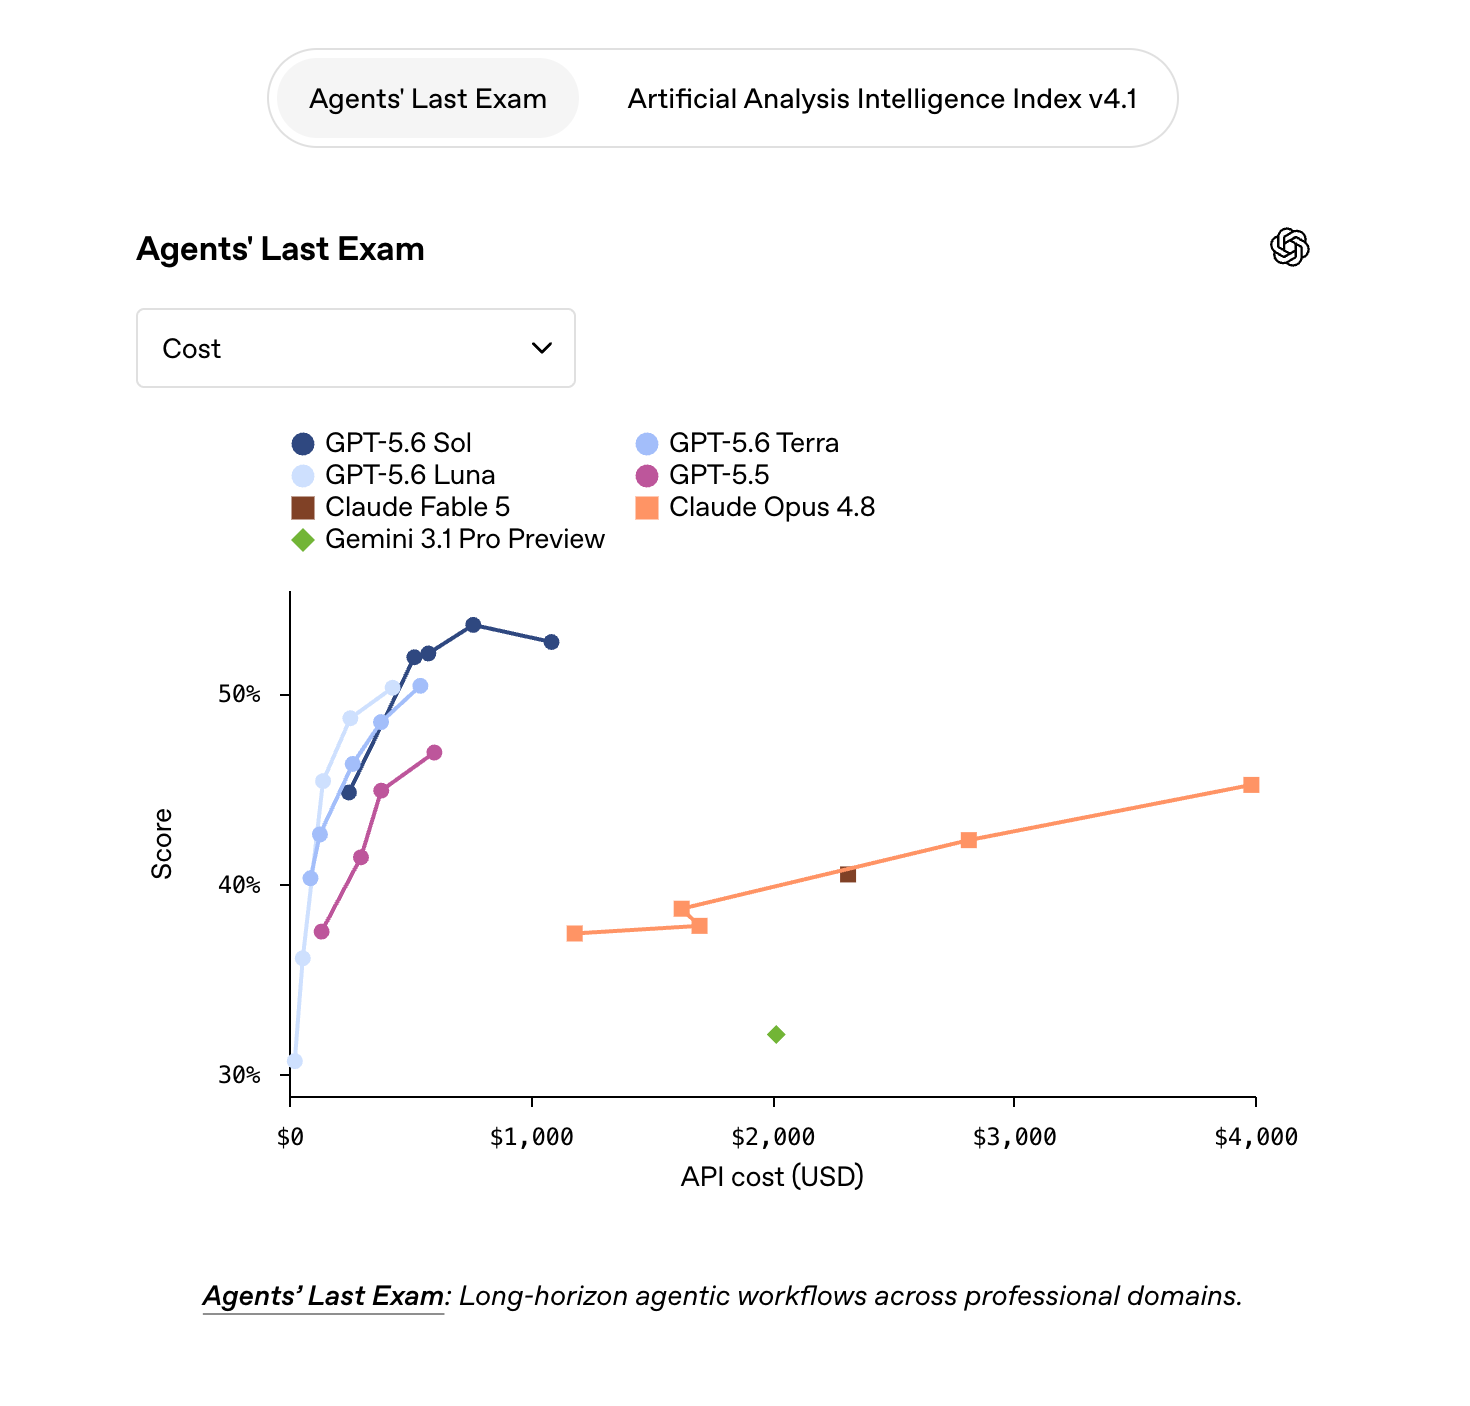
“Terra performs just above Fable 5, while Luna outperforms Opus 4.8; each does so in roughly one-third of the time, with about half as many output tokens, and at approximately one-quarter the estimated cost. It also sets new state-of-the-art results on Terminal‑Bench 2.1 and DeepSWE, which test complex command-line workflows and long-horizon engineering in real codebases.”
There are also harder-to-benchmark improvements in computer use, presentation/document generation, and scientific research that should nevertheless be taken very seriously.
As we predicted in April, the newly launched ChatGPT Work and Codex desktop app update today is probably the penultimate step for OpenAI’s superapp strategy (the last open question is what happens to the agentic browser….)
OpenAI launched a new three-model GPT‑5.6 family and simultaneously expanded the product stack around it.
OpenAI announced GPT‑5.6 Sol, Terra, and Luna rolling out across ChatGPT, Codex, and the API via @OpenAI and @OpenAIDevs
In ChatGPT, Plus, Pro, Business, and Enterprise users get access to GPT‑5.6 Sol through medium+ effort settings, while Pro and Enterprise can select GPT‑5.6 Pro for highest-quality results on complex tasks, per @OpenAI
API pricing introduced a tiered lineup: Sol $5 / $30 per million input/output tokens, Terra $2.5 / $15, Luna $1 / $6, with cache-write pricing added for the first time and 90% cache-read discount retained, according to @ArtificialAnlys
OpenAI framed the family around a price-performance ladder: Sol = flagship/highest ceiling, Terra = GPT‑5.5-like capability at lower cost, Luna = fastest/cheapest high-volume option, via @OpenAIDevs
The launch bundled major app-layer changes: ChatGPT Work, a new desktop app merging Codex + ChatGPT, Sites beta, programmatic tool calling, and multi-agent beta in the Responses API, via @OpenAI, @OpenAIDevs, and @OpenAIDevs
Official claims and benchmark results
OpenAI’s official message emphasized strong agentic/coding performance, better artifact quality, and improved economics.
Sam Altman called it “obviously the best model we have ever produced” in the launch post, linking the release blog, via @sama
Altman also highlighted enterprise economics: “5.6 sol is a huge step forward for dollars-per-task,” via @sama
Greg Brockman said the goal is “the best price for any level of target performance” and the highest possible ceiling, via @gdb
OpenAI claimed GPT‑5.6 Sol sets a new high of 53.6 on Agents’ Last Exam, beating Claude Fable 5 adaptive by 13.1 points; at medium reasoning it beats Fable by 11.4 points at roughly one-quarter the estimated cost, while Terra and Luna also outperform Fable at around one-sixteenth the cost, via @OpenAI
OpenAI said GPT‑5.6 improves artifact quality across presentations, documents, and spreadsheets, with outputs exportable into existing enterprise tools, via @OpenAI
OpenAI positioned GPT‑5.6 as state of the art for reasoning through complex tasks and for producing materials matched to templates, reference files, and preferred style inside ChatGPT Work, via @OpenAI
OpenAI also said GPT‑5.6 is its most capable model yet on cyber and bio-related tasks, with some API calls potentially blocked or paused for extra safety review in dual-use areas, via @OpenAIDevs
OpenAI highlighted better Computer Use performance: faster, more token-efficient, support for batching and parallel operations across multi-step tasks, plus picture-in-picture supervision, via @OpenAIDevs
Independent evaluations and third-party measurements
Independent evals broadly placed Sol near or at the frontier, especially on coding-agent workloads, while also surfacing caveats.
@ArtificialAnlys reported GPT‑5.6 Sol (max) scores 59 on its Intelligence Index, 1 point below Claude Fable 5 (max), at about one-third of Fable’s cost per task
On the same analysis, Terra and Luna score 55 and 51 on the Intelligence Index, with ~50% and ~80% lower cost per task than Sol, respectively, via @ArtificialAnlys
Artificial Analysis said Sol leads the Coding Agent Index at 80, ahead of Fable 5 and Opus 4.8, and is also cheaper per task than both on their harnesses, via @ArtificialAnlys
It also noted Sol defines a new Pareto frontier of intelligence vs output tokens, while Terra and Luna are not on that frontier, via @ArtificialAnlys
Artificial Analysis found minor improvement over GPT‑5.5 in AA‑Omniscience but with a higher hallucination rate than GPT‑5.5 max, via @ArtificialAnlys
It reported similar GDPval-AA v2 performance to Claude Fable 5, suggesting comparable ability on economically valuable tasks, via @ArtificialAnlys
@ValsAI ranked GPT‑5.6 #2 on Vals Index and Vals Multimodal Index, saying Fable 5 remains ahead on several benchmarks but GPT‑5.6 is “clearly in the same class”
Vals also said Sol is #1 on CyberBench and Excel Modeling Benchmark, and #1 on Legal Research Bench, ProofBench, SWE-bench, and Terminal-Bench 2.1, adding that Fable had a nearly 100% refusal rate on CyberBench, via @ValsAI
@arcprize said GPT‑5.6 Sol scores 7.8% on ARC‑AGI‑3 and is the first verified frontier model to ever beat an ARC‑AGI‑3 game
@GregKamradt noted 92.5% on ARC‑AGI‑2, calling it SOTA while costing an order of magnitude less than GPT‑5.5 Pro three months earlier
@ArtificialAnlys later reported GPT‑5.6 Sol (max) leads CritPt, a benchmark of unpublished research-level physics problems, by roughly 4 points over Claude Fable 5
@llama_index said day-0 ParseBench results show GPT‑5.6 continues to do well on text and tables but still struggles on charts and layout, and that Luna is ~6× cheaper than Sol with only minor degradations
@jerryjliu0 similarly said ParseBench shows no high-level change versus GPT‑5.5 on tables/text/charts/layout, stressing persistent weakness on complex text layouts, chart transcription, and source-element bounding boxes
Technical details
The technical story of GPT‑5.6 is as much about inference orchestration and token efficiency as raw capability.
OpenAI shipped three model tiers with multiple reasoning effort levels; users discussed Light, Medium, High, Extra High, Ultra, leading to a large configuration matrix, via @rasbt
OpenAI added Programmatic Tool Calling in the Responses API and Multi-agent beta, indicating more explicit support for orchestrated tool use and agent decomposition, via @OpenAIDevs
OpenAI’s app layer now uses Codex as the core of the new Work product, per @sama and @gdb
Several posts stress parallel agents/subagents as a major capability lever; @aidan_mclau explicitly mentions users can increase the number of 5.6 subagents
@LiorOnAI summarized likely drivers as adaptive reasoning, parallel agents, programmatic tool use, and higher token efficiency
Artificial Analysis reported Sol max uses ~15k output tokens per Intelligence Index task vs 16k for GPT‑5.5, and fewer than Opus 4.8, GLM‑5.2, and Gemini 3.5 Flash at comparable intelligence, via @ArtificialAnlys
@OpenRouter said early testing found the 5.6 models more token efficient, lowering both cost and time-to-task completion
The desktop/app layer brought a Chrome extension, revamped in-app browser, authenticated sites, persistent multi-tab sessions, file downloads, and tighter cross-device handoffs, via @OpenAIDevs, @OpenAIDevs, and @OpenAIDevs
Sites entered beta for paid users, offering hosting, storage, and optional auth for GPT-built apps, via @OpenAIDevs and @OpenAIDevs
The “Sol autonomously post-trained Luna” claim
This was the most provocative technical claim around the launch, but its interpretation became contested almost immediately.
Multiple accounts amplified the statement that OpenAI says GPT‑5.6 Sol autonomously post-trained GPT‑5.6 Luna, via @scaling01, @tejalpatwardhan, and @dejavucoder
The claim fueled RSI/autoresearch speculation; @tenobrus said if true as stated, it would be a “pretty large update” for automated researcher timelines
@eliebakouch framed it as OpenAI asking Sol to post-train Luna “with 100k GPUs” for an experiment
@gdb said the implication is easy to overlook for accelerating engineering workflows, reinforcing that OpenAI wants this read as more than a marketing flourish
But skeptical clarifications emerged quickly: @nikolaj2030 asked whether this actually meant Sol completed a small controlled post-training task—modifying a config, editing a scheduler file, and launching a run—rather than end-to-end real-world post-training of Luna
@nrehiew_ interpreted the screenshot similarly: Sol could go from high-level ideas to editing configs and launching experiments, not fully owning Luna’s end-to-end post-training
@scaling01 argued that what’s probably happening is a model implementing LLM-as-a-judge graders, reward-shaping logic, or small training configs on top of existing OpenAI RL infrastructure—not autonomous end-to-end research or training systems
@scaling01 explicitly said we should distance these statements from literal autonomous end-to-end post-training or research, which models still cannot do
Counterbalancing that skepticism, @aidan_mclau said it is routine for him to have 5.6 e2e do an entire RL run, suggesting meaningful internal workflow automation even if not self-sufficient research
The consensus across technical observers was not that Sol independently invented and trained Luna, but that GPT‑5.6 may now be capable of executing meaningful chunks of model-improvement workflows inside mature internal infrastructure
Internal productivity and recursive improvement signals
OpenAI also used internal-usage data to argue that GPT‑5.6 materially changes researcher throughput.
@scaling01 highlighted an OpenAI claim that it doubled experiment throughput per researcher since the start of the year
@eliebakouch quoted OpenAI saying average daily output tokens per active researcher were more than twice the highest level observed for GPT‑5.5 during internal testing
Another OpenAI stat, relayed by @eliebakouch, said over six months the share of research compute devoted to internal coding inference grew 100-fold, while internal agentic token usage increased ~22-fold
@FakePsyho linked these developments to OpenAI’s performance in top programming contests, describing systems close to GPT‑5.6 plus custom harnesses as decisively beating elite human competitors
This fed broader RSI/autoresearch discussion, especially from people who see long-horizon coding and heuristic optimization as proxies for model-improvement capability
Product implications: ChatGPT Work, Codex merge, desktop, and Sites
The model launch doubled as a product strategy reset: OpenAI is pushing from “chatbot” to “work OS.”
OpenAI launched ChatGPT Work, an agent powered by Codex + GPT‑5.6 that can act across apps and files, stay on tasks for hours, and turn a goal into finished work, via @OpenAI
Work can ingest context from docs, Slack, Notion, Microsoft 365, and Google Drive and produce decks, docs, spreadsheets, dashboards, visualizations, and interactive explanations, summarized by @kimmonismus
The Codex app merged into the new ChatGPT desktop app, confirmed by @avstorm and @OpenAIDevs
Developers now get inline diff editing, PR review side panel, better SSH video rendering, and stronger computer use, via @romainhuet and @reach_vb
Sites lets users turn work into shareable hosted apps/websites from ChatGPT, via @OpenAIDevs and @simpsoka
@OpenAI, @OpenAI, and @OpenAI marketed GPT‑5.6 through case studies: a broccoli farmer, a mathematician, and a family cereal business
This product reframing was read by some as OpenAI’s answer to Anthropic’s Cowork / Claude Code stack, via @jerryjliu0 and @kimmonismus
Many developers and evaluators saw GPT‑5.6 as a meaningful frontier advance, especially in coding and knowledge work: @gdb, @AravSrinivas, @OpenRouter, @Teknium
Several posts focused on cost efficiency as the real win, with Sol matching frontier peers while being materially cheaper: @ArtificialAnlys, @omarsar0, @cline
Others highlighted the agentic stack—Work, Codex, multi-agent, programmatic tools—as more strategically important than raw benchmark deltas: @TheRundownAI, @kimmonismus, @fidjissimo
Neutral / analytical views
Some analysts saw Sol as roughly same class as Fable, but not decisively ahead overall: @ArtificialAnlys, @ValsAI
@teortaxesTex argued the release may reflect OpenAI strong post-training recovering toward Anthropic despite a stronger Anthropic base model
@simonw pointed to notable API additions but also implied growing product complexity
Critical / skeptical views
@scaling01 asked whether GPT‑5.6 Sol is worse at math, pushing back on the “everything got better” narrative
@scaling01 criticized the ARC‑AGI‑3 scoring setup, saying Sol would score 0% under official scoring methodology capped at $10k and objecting to use of a $25k budget
@Hangsiin and @Hangsiin pointed to subscription/credit confusion, saying Sol costs more credits than GPT‑5.5 while usage limits differ less than API pricing suggests
@QuinnyPig said OpenAI’s pricing/subscription strategy is confusing, particularly around future pricing jumps or inclusion terms
@MParakhin complained that GPT‑5.6 Pro no longer has extended thinking, preferring an option to pay for much longer reasoning
@theo and @simonw criticized the growing app/mode fragmentation around ChatGPT, Codex, and Work
Safety and security concerns
The launch also surfaced one of the strongest public cyber-safety debates around a recent frontier model release.
@alxndrdavies from the AI Safety Institute said they found universal jailbreaks in all rounds of testing that enabled long-form agentic task completion in vulnerability discovery and exploit development
@EthanJPerez called it “the highest stakes safety issue of any model release yet”
@yonashav praised OpenAI for allowing third-party unreleased-model safety assessments to be published even when inconvenient
@Mononofu said ease of jailbreaking plus reward-hacking reports make them worried OpenAI may have rushed the release to keep pace with Fable
At the same time, OpenAI explicitly warned some cyber/bio requests may be paused or blocked mid-stream for additional review, via @OpenAIDevs
This created a split narrative: strong cyber capability is treated as a product advantage by some evaluators, but as a serious deployment risk by safety researchers
Context
Why this matters goes beyond a single model benchmark win.
The launch happened amid a compressed week of frontier competition that also included new releases from Meta Muse Spark 1.1 and Grok 4.5, leading multiple observers to describe the frontier as newly crowded: @matanSF, @kimmonismus
OpenAI’s differentiation is increasingly framed less as “best raw benchmark score” and more as cost-efficient agentic work, consistent with posts from @sama, @ArtificialAnlys, and @LiorOnAI
The product bundling suggests OpenAI is moving from a model vendor to a full-stack work platform, with its own browser, connectors, orchestration primitives, hosted app deployment, and desktop runtime
The strongest forward-looking signal may be the internal claim that researchers already use these systems to materially increase output and automate chunks of RL/post-training workflows, even if public discussion often overstates that as “the model trained itself”
The launch also sharpens a recurring engineering question raised by many tweets: whether the frontier is now bottlenecked less by a single monolithic model and more by orchestration quality, tool APIs, subagents, evaluation harnesses, and economics
Frontier models and evaluations
Meta launched Muse Spark 1.1 and the Meta Model API in public preview, positioning it as a strong agentic, coding, multimodal, and computer-use model. Official posts came from @finkd, @alexandr_wang, @shengjia_zhao, @ren_hongyu, and @OpenAIDevs
Key technical details repeatedly cited: 1M-token context window, video understanding, multimodal reasoning, and API availability, with @altryne and @xinyun_chen_ among those emphasizing long-horizon agentic gains
Benchmark claims around Muse Spark 1.1 included competitiveness with GPT‑5.5 and Opus 4.8 on agentic evals, strong performance on Harvey’s Legal Bench, TaxEval, MedScribe, and some out-of-distribution evals over Opus 4.8 and Grok 4.5, via @alexandr_wang, @alexandr_wang, @_jasonwei, and @cline
Grok 4.5 continued to draw benchmark discussion: @arena said it reached #3 in Code Arena: Frontend, while @alexgshaw discussed Terminal-Bench 2.1 reward-hacking caveats. Several posters argued Grok now belongs in the frontier set, including @teortaxesTex
Agents, orchestration, and developer tooling
Multiple posts reinforced that harness/orchestration quality is becoming as important as the base model. @dair_ai highlighted a study where changing only the orchestration layer cut blended cost per task 41%, tokens 38%, and median wall-clock 44% at quality parity
LangChain/LangSmith tooling updates focused on observability for coding agents: tracing Claude Code sessions into LangSmith via @LangChain, plus discussion of OpenWiki Brains for proactive memory agents from @BraceSproul, @hwchase17, and @colifran_
@ManusAI launched Branch, allowing parallel sessions that inherit full context
@antigravity described investment in dynamic agent teams, active sidecars, and generative UI
@CoreWeave introduced ARIA, an AI Research and Improvement Agent inside W&B that reads runs, forms hypotheses, launches experiments, and scores against baselines
@TheTuringPost highlighted SkillCenter, a package manager/index for agent skills, while @steveruizok shipped a “papercuts” CLI for agents to report broken tool paths and frustrations
Inference, efficiency, and open model infrastructure
Ollama announced fundraising and said it now has 9M+ active builders, framing the moment as scaling “open models into AI that you can own,” via @ollama
Hugging Face / Reachy Mini economics were striking: @andimarafioti said 9k Reachy Minis generate 15k hours of conversation/month; using GPT-realtime would cost $45k/month, so they built an open alternative at $0.25/hour and free on laptop
@dmitrshvets shared speculative decoding research claiming 4.37× speedup over autoregressive decoding and +24.7% over a strong DFlash baseline
@fal detailed a diffusion serving stack reaching 0.45s inference using kernel optimizations, quantization-aware distillation, and timestep distillation
@ostrisai added isolated reference-token attention for Krea2 edit training; example timings showed major gains from KV caching, such as 31.63s → 10.90s for 3 refs
@vllm_project announced the first vLLM Conference, underscoring how open inference stacks remain a central layer of the ecosystem
@QuixiAI reported Qwen3.6-35B-A3B-NVFP4 at 65 tok/s on dual B60 with custom SYCL kernels and 128k context
Robotics, multimodal systems, and AI-for-science
@perceptroninc launched Perceptron Egocentric, an embodied reasoning/annotation system said to beat pipelines built on Gemini 3.5 Flash and Gemini Robotics-ER 1.6
@DataChaz summarized the economics: 10–15× cheaper than human annotation, with +77% end-to-end F1 on WGO-Bench (0.280 vs 0.158)
@rohanpaul_ai emphasized the output structure: subtask boundaries, per-hand actions, left/right hand grounding, and dense labels from raw egocentric/robot video
Google Research released SensorFM, a sensor foundation model trained on 1 trillion minutes of unlabeled wearable data from 5 million consented participants, via @GoogleResearch
@SebastienBubeck said GPT‑5.6 helped formalize the unit distance solution in 1 million lines of LEAN, compressing what would previously require a team over years into a short single-person effort
@TheTuringPost highlighted a Stanford paper on the “Agentic Garden of Forking Paths”, where AI research personas reproduced human-like ideological variation; 86% of analyses passed independent AI review and 78% were judged methodologically sound by humans
Policy, safety, and ecosystem debate
A cluster of posts sharply criticized the EU’s Chat Control law/proposal from civil-liberties and anti-surveillance angles, including @perrymetzger, @IterIntellectus, and @dhh
Open-source advocacy remained loud: @AndrewYNg said protecting open source AI is critical to permissionless innovation, while @Dan_Jeffries1 argued restricting open source AI would be “civilizational suicide”
@cognition addressed trustworthiness concerns around open-source-derived coding agents, saying their SWE‑1.7 built on Kimi K2.7 was specifically trained for trustworthiness and refused surveillance-style scenarios where the base model complied
On evaluation methodology and behavior science, @TransluceAI argued for measuring how systems behave in the world, not just raw capabilities
Forecasting/futures discussion centered on AI 2040, with endorsements and critiques from @NeelNanda5, @RichardMCNgo, @scaling01, and others debating compute gaps, geopolitical assumptions, and takeoff dynamics
As GPT 5.6 is confirmed to launch tomorrow, today is pretty much the last day anyone will be excited about a GPT 5.5 equivalent model launch, and that is exactly what SpaceXAI did:
xAI/“SpaceXAI” publicly launched Grok 4.5 as a new coding-and-agents-focused frontier model, positioned on capability-per-dollar rather than absolute benchmark supremacy.
Elon Musk first said Grok 4.5 would be made public “tomorrow” based on strong beta feedback, calling it “Opus-class,” but faster, more token-efficient, and lower cost @elonmusk.
Musk later framed Grok 4.5 internally as “roughly comparable to Opus 4.7, but much faster,” emphasizing usefulness to Tesla and SpaceX engineers over benchmark chasing @elonmusk.
The official launch came from xAI’s account, describing Grok 4.5 as “our first model trained specifically for coding and agents,” trained with Cursor, and offering “frontier intelligence at leading speeds and cost efficiency” @SpaceXAI.
Cursor said it partnered with xAI to train Grok 4.5, called it “our most powerful model yet,” and stressed that it was “the first we’ve built for more than software engineering” @cursor_ai.
Cursor also announced in-product availability with “double usage for the first week” @cursor_ai.
Cursor clarified that “Grok 4.5 and Composer are two different model weight classes,” and that Composer 2.5 would remain available with future models in that smaller class @cursor_ai.
Early ecosystem support appeared immediately: Grok 4.5 became available in Grok Build/API/Cursor @milichab, day-0 support was announced for Hermes Agent @Teknium, and later live availability in Hermes Agent/Portal/OpenRouter/Grok subscriptions was confirmed @Teknium.
Musk said the context window would likely move from 500k back to 1M “by next week” @elonmusk.
Official claims and product details
Positioning
Officially, xAI’s message was not “best overall model,” but near-Opus quality with materially better economics and speed:
“Opus-class model, but faster, more token-efficient and lower cost” @elonmusk
“First model trained specifically for coding and agents” @SpaceXAI
“Frontier intelligence at leading speeds and cost efficiency” @SpaceXAI
“Most powerful model yet” and “first we’ve built for more than software engineering” @cursor_ai
This framing matters: xAI is explicitly targeting the coding-agent workflow market that has recently been dominated by Anthropic/OpenAI/Cursor-style tool-using systems, not just general chat.
One important spec surfaced via third-party reporting of Musk’s disclosure:
Grok 4.5 is 3x larger than Grok 4.3 at 1.5T parameters@ArtificialAnlys
That is a notable jump, and likely central to why multiple observers interpreted 4.5 as xAI’s first entry into the true flagship coding-agent tier rather than an iterative refresh.
Benchmarks and independent evaluations
Artificial Analysis
Artificial Analysis provided the most substantive external evaluation in the tweet set.
Key results:
#4 on Artificial Analysis Intelligence Index, score 54, behind only Fable 5, GPT-5.5, and Opus 4.8@ArtificialAnlys
Average output tokens per Intelligence Index task: ~14k, over 60% lower than Opus 4.8@ArtificialAnlys
Average total tokens per Coding Agent Index task: 1.9M, versus 7.2M for Fable 5 in Claude Code and 6.2M for GPT-5.5 in Codex @ArtificialAnlys
Artificial Analysis’ interpretation was clear: Grok 4.5 is near-frontier on capability, but unusually strong on efficiency, making it sit on the Pareto frontier for cost/performance.
Musk explicitly amplified the Artificial Analysis assessment @elonmusk.
We’ve been running a bit of an Agent Cloud series surveying all the top inference/compute/cloud providers, from Databricks to Daytona to Railway and, even further back, E2B, but we’re excited to conclude this series returning to Modal, which has just raised a monster $355M Series C.
The cloud was built for developers. But agents are now changing that.
The old infra stack was designed for a human who could read docs, reason through YAML, and understand dashboards to figure out what they need when something broke. While this was painful for developers, it worked since they could fill in missing context in their heads.
However, agents don’t have that luxury. Now in this new era of agents, everything has to be tighter.
They need a place to write code, run it, inspect the output, change the environment, debug failures, and try again. Fast iteration and feedback loops with all the necessary context are crucial for agents to operate properly. Furthermore, sandboxes are a clear representation of this shift as agents can easily spin up isolated environments. This programmatic infra even extends to research:
Two years ago, we were one of the first to cover Modal with CEO Erik Bernhardsson and Alessio designed our favorite LS thumbnail of all time:
At the time, Modal was just a teeny little company with a $17M Series A.
Today, fresh off their $355M Series C, Modal is one of the clearest examples of the agent cloud future being built in real time: a cloud platform moving past traditional web app assumptions toward the workloads AI actually creates such as elastic inference, sandboxes, GPU burst, post-training, background agents, and infrastructure that agents themselves can operate.
In this episode, Modal CTO Akshat Bubna joins swyx and Vibhu to unpack why AI applications don’t fit traditional cloud assumptions, why Kubernetes was never designed for bursty compute-heavy workloads, and why Modal is now shifting from developer experience to agent experience.
We go deep on Modal’s AI infra stack: serverless functions, decorator-based infrastructure, elastic inference for custom models, GPU snapshotting, DeFlash, speculative decoding, Auto Endpoints, sandboxes, persistent storage, networked containers, private IPv6, RDMA, multi-node training, and Modal’s capacity pool across 17 cloud providers. Akshat also explains why RL rollouts can require 100,000 sandboxes, why production agents need hard guardrails, why observability may matter more than reading code, and why AI has made infrastructure exciting again.
We discuss:
Why Kubernetes wasn’t built for bursty AI workloads
How Modal started as a better runtime before becoming an AI cloud
Why Modal added GPUs before ChatGPT
The shift from developer experience to agent experience
Why observability matters when agents are writing the code
Elastic inference for custom models across audio, video, robotics, and comp bio
GPU snapshotting, cold starts, and why inference workloads are so bursty
Why RL rollouts can require 100,000 sandboxes
DeFlash, speculative decoding, and frontier-level inference performance
Auto Endpoints and making optimized inference easier to deploy
What Modal adds beyond vLLM, SGLang, and raw GPU rental
Modal’s 17-cloud capacity pool and supercloud strategy
Networked sandboxes, sidecars, private IPv6, and RDMA
Serverless multi-node training for post-training and research workloads
Auto-research, model-guided sweeps, and agents launching GPU experiments
Compute strategy, capacity planning, and batch tiers
Why production agents need specialized sandboxes and hard guardrails
Modal’s take on managed agents, CI, Gitpod/Ona, Python, TypeScript, and Modal Bench
00:00:39 Modal’s origin and why Kubernetes wasn’t enough
00:04:32 Developer Experience → Agent Experience
00:06:21 Modal’s AI cloud primitives
00:09:14 Sandboxes, agent loops, and proto-Cognition
00:12:12 Elastic inference, GPU snapshotting, and 100,000 sandboxes
00:15:24 DeFlash, speculative decoding, and Auto Endpoints
00:19:59 Production-grade inference beyond raw GPUs
00:22:00 Background agents, Ramp Inspect, and the agent lifecycle
00:24:08 Modal’s 17-cloud supercloud strategy
00:26:40 Networked sandboxes, private IPv6, and RDMA
00:32:48 Multi-node training, post-training, and auto research
00:37:36 Compute strategy, capacity planning, and batch tiers
00:40:55 Open models, real-time AI, and production agent infra
00:43:06 Hard guardrails, managed agents, and specialized sandboxes
00:46:06 Why AI made infrastructure exciting again
00:48:30 Model APIs, differentiated products, and agentic video
00:51:50 CI, coding-agent infra, SDKs, and Modal Bench
00:57:28 Closing Thoughts
Transcript
Introduction: Modal, Series C, and the Art Party
Swyx [00:00:00]: We’re here with Akshat, CTO of Modal, together with Vibhu. Congrats on your Series C.
Akshat [00:00:10]: Thank you.
Swyx [00:00:11]: Your party yesterday was amazing.
Akshat [00:00:15]: Yeah.
Swyx [00:00:15]: From all the photos and all the swag.
Akshat [00:00:17]: We had a bunch of art installations, which was fun, seeing, like, our products on pedestals next to, like, Rodin.
Swyx [00:00:25]: Very nice. Very nice. When you started, it was not the GPU inference company. Maybe it was in your mind. Take us back to the origin story.
Modal’s Origin: A New Runtime Beyond Kubernetes
Akshat [00:00:39]: I first met Eric, who’s the CEO, through an investor. Back then Eric was already thinking about building, a new runtime, and he got there thinking through why are workflow orchestration products so hard to use. It’s because you have to run them on Kubernetes. Kubernetes is hard to manage. It’s not built for burstiness and, custom images,
Swyx [00:01:03]: Yeah
Akshat [00:01:03]: It has a terrible developer experience.
Swyx [00:01:05]: And I’ll, I’ll interject
Akshat [00:01:06]: Yeah
Swyx [00:01:07]: For listeners, who are new, we interviewed Eric two years ago, and there’s a bit more of the story there from Spotify and all those things.
Swyx [00:01:14]: And I came across Eric through Data Council because he did that talk on the serverless container stack that you guys did, which was like, that was my first like, “Okay, I need to take Modal very seriously” moment.
Akshat [00:01:26]: Yeah.
Swyx [00:01:26]: But it was still very unclear, like, do I need all this for just my data pipelines?
Akshat [00:01:33]: Yeah. initially what we were thinking about was if we build a better runtime, it’s a very useful primitive in itself. It’s There’s a lot of things that, get solved by serverless functions, like you can do, ETL stuff, you can do job queues, you can do all this, like, bursty processing, which it turns out every company had needs for. but then we also were thinking about this as like, this is a primitive that we can build a whole collection of products on, which are very verticalized. So perhaps data engineering would’ve been the first one, but we were thinking about inference. Back then it was more classical inference, like computer vision stuff and running XGBoosts and whatnot. But we added GPUs to the product a year before ChatGPT came out.
From Serverless Containers to GPU Workloads
Swyx [00:02:19]: Nice.
Akshat [00:02:19]: We just didn’t think it would be that big of a deal.
Swyx [00:02:22]: Yeah, just like add A100.
Vibhu [00:02:23]: Was there any, like, early key problem that really sparked off why you built it?
Akshat [00:02:28]: Yeah. Primarily it’s just, none of the tooling that was out there was built for, one, a really great developer experience, and also there’s a general trend of, a lot of the workloads that we were seeing were very. I wish there was a better word for it, but compute-heavy. Like, they need, one, like, need a lot more resources, so you need to burst up and down a lot, versus like Kubernetes designed for, like, slow scaling and, more for, like, web server use cases. And also there’s just a lot more specialization in, like, what kinds of environments these workloads run in. Like, we had sometimes they need accelerators, sometimes they need different kinds of images, and this is just like a consistent thing that we saw across a lot of companies. That would be the next step.
Software-Defined Infrastructure and Decorator-Based DX
Swyx [00:03:13]: Yeah. Yeah. Be nice. I don’t know how much this factored into the early story, but I wrote a post when I was at Temporal about infrastructure, software-defined infrastructure or something like that.
Akshat [00:03:22]: Yeah, the self-provisioning
Swyx [00:03:23]: Self-provisioning.
Akshat [00:03:24]: Yeah.
Swyx [00:03:24]: Yeah. I can’t even remember my own post.
Swyx [00:03:26]: And then you put me on the landing page.
Akshat [00:03:28]: Yeah. We really like, the term and so we stole it.
Swyx [00:03:32]: Because you had the insight that everything can just be in decorators co-located with the code, right?
Akshat [00:03:37]: Yeah.
Swyx [00:03:37]: Was that a big part of the original
Akshat [00:03:39]: Yes
Swyx [00:03:39]: Story or it was just like a DX layer?
Akshat [00:03:41]: That was, really important because we really didn’t want people to spend, so much time, writing YAML, and it seemed like you could really condense the surface area of what you’re doing, put it in code so you can operate on it just like you operate on other code, and like build stuff that’s more expressive and dynamic. and so yeah, that was always a very important part.
Swyx [00:04:04]: Then the pushback is this is a DSL.
Akshat [00:04:07]: Yeah.
Swyx [00:04:07]: It’s you’re closed source. I am locked into Modal.
Akshat [00:04:11]: Yeah. We never really got pushback for that because the nice thing about Modal is you can bring whatever code you have, and sure, the DSL is at the configuration layer for, what hardware you’re using, how you’re scaling things up, but you still own the code.
Akshat [00:04:27]: And that’s, that’s been an important, part of our story, even as we do inference now.
Swyx [00:04:32]: Yeah.
Vibhu [00:04:32]: How much of do you think still stays the same today? Like if you were to build something today, DevX very important, but I feel like, a lot of this has been changed with just hook it up to an agent, have Claude Code, have Codex implement a tool. there’s very agent native primitives that are different than if I’m doing this myself, right?
Developer Experience → Agent Experience
Akshat [00:04:54]: We’ve changed our SDK team to think about agent experience instead of, developer experience and we think that the same benefits that apply for DX also apply for AX, which is why would you have an agent read through hundreds of Kubernetes files and like write YAML that’s not even typed when it can make a couple of changes in a decorator and it gets this self-provisioning runtime of, being able to see its changes live in action? yeah, it just seems from the customers we talk to, they find Modal is much faster for agents to use versus operating on a different substrate.
Swyx [00:05:34]: Yeah, because like you, again, you co-locate the infrastructure requirements to the code that runs it.
Akshat [00:05:38]: Yeah.
Swyx [00:05:38]: Well, the negative thesis now is that nobody’s looking at their code anymore, so there’s no point.
Akshat [00:05:44]: Yeah, people aren’t looking at code. one thing we still see is really important is observability.
Swyx [00:05:51]: Yeah.
Akshat [00:05:51]: Like how good is your dashboard? And of course, like we have, we push a lot of it to the CLI so the agents can do their own investigation, but you still need humans to go interpret what’s going on and, make judgment calls and whatnot. and that’s I feel like, Maybe more important now than looking at the code itself.
Swyx [00:06:11]: Yes, because like, you can try to treat the code as a black box and then use, see the observable action that comes out of it, and then just prompt a change.
What Modal Is For: AI Cloud Primitives
Akshat [00:06:21]: Yeah.
Swyx [00:06:22]: So I think it takes a bit of restraint to not specialize, to say, “I want to ship a new primitive,” and then just be general purpose.
Swyx [00:06:31]: People ask you, “What are you for?” You’re like, “ I don’t know. We can do this, we can do that.”
Vibhu [00:06:36]: Well, I’d be curious to see, like, okay, if we were to ask you, like, what is Modal for even at a high level? There’s a lot you guys do, sandboxes, GPUs, everything. How do you answer?
Akshat [00:06:46]: Modal is a cloud platform that’s built for, where we’ve built the primitives from scratch for AI applications. and right now it covers, inference, training, batch processing, and sandbox workloads.
Akshat [00:07:00]: But we’re building a lot more
Swyx [00:07:02]: I noticed you didn’t say web server, so there is still a role for, like, the always-on large-scale Kubernetes type things.
Akshat [00:07:09]: Yeah, absolutely. We’re, we’re not trying to compete with the renders of the world, because yeah, we think the differentiator for us is the, are the workloads that need specialized compute, need to scale up and down a lot. yeah, they’re, they’re, they’re just shaped differently.
Working Alongside Frontier Startups
Vibhu [00:07:26]: I think you’re building a lot of it alongside the startups, right? They’re innovating quite a bit, even in your, like, latest blog post. Like, even in the series C, the customers that you mention here, the cognitions, technical ones, ramps and whatnot, they’re, they’re innovating with you, right? And that’s not something AWS is doing directly with.
Akshat [00:07:45]: Yeah, absolutely. I think, this is again classic. We’re a small team. We can move really fast. our engineers are working with our customers and figuring it out. Yeah.
Swyx [00:07:54]: So my first week at Cognition, I walked in, there was someone wearing a Modal shirt. I was like, “What are you doing here?” They’re like, “Yeah, I just. I am embedded inside of Cog.”
Akshat [00:08:05]: Yeah, I think that was Peyton. We sent him over
Swyx [00:08:07]: Yeah.
Akshat [00:08:07]: Because, the latency of communication was too high otherwise.
Swyx [00:08:12]: Yeah, distributed node, you have to - you have to place one and collocate.
Vibhu [00:08:16]: Yeah.
Swyx [00:08:16]: So I had a, I had direct personal experience, right? So I worked on smol developer three years ago. it was inspired by Claude 1. I think you onboarded me at some point, like, just before, and I was like, “Oh, like, I need some bursty compute. Like, I was just gonna try using Modal.” And it was a, it was a pretty pleasant experience. apparently, I showed up in the board meeting, like the analytics.
smol developer, Sandboxes, and Proto-Cognition
Akshat [00:08:39]: Yeah, you blew up on Hacker News and,
Swyx [00:08:41]: Yeah
Akshat [00:08:41]: We got a big traffic spike. I. I think the way you used smol developer was Modal functions for running stuff, which was. Like, the, that was a good use case. but then, yeah.
Swyx [00:08:53]: Yeah. That - So to me, that was proto-cognition.
Akshat [00:08:55]: Right.
Swyx [00:08:56]: If only I had, like, stuck to it.
Swyx [00:08:58]: Like, that was like, if - did you say draw the tech tree
Akshat [00:09:00]: Absolutely
Swyx [00:09:00]: You’re just like, “Yeah, like, probably this will happen.”
Akshat [00:09:02]: Yeah. Like, he was so close. You were just rebuilding upon us
Swyx [00:09:04]: I just didn’t realize.
Akshat [00:09:05]: But the funny story there is at the same time, we were talking to a bunch of customers who needed something like sandboxing.
Swyx [00:09:14]: Yeah.
Akshat [00:09:14]: This is like twenty-three.
Swyx [00:09:15]: Yeah.
Akshat [00:09:16]: So we built
Swyx [00:09:17]: You introduced a new API right after that.
Akshat [00:09:18]: Yeah.
Swyx [00:09:19]: Yes.
Akshat [00:09:19]: Like, we built sandboxes in May of twenty-three before anyone was even knew this was gonna be a thing. And the first example we published was, we took smol developer
Swyx [00:09:28]: Smol developer
Akshat [00:09:28]: And put it in a loop, so the agent can iterate on itself.
Swyx [00:09:33]: Loops are hot these days.
Vibhu [00:09:34]: It’s the looper.
Akshat [00:09:34]: Yeah.
Vibhu [00:09:35]: Loops in. When was this, twenty-three?
Akshat [00:09:38]: Yeah.
Vibhu [00:09:39]: A small check.
Akshat [00:09:39]: Yeah.
Swyx [00:09:39]: It’s like twenty-three. so the. the, those for listeners, like, the problem was the models are not built for any of this, right?
Swyx [00:09:46]: Like, you’re just trying to like. They’re not post-training to understand, like, looping and, like, self-correction and tool calling was there, but, like, also not that great.
Akshat [00:09:55]: Yeah.
Akshat [00:09:55]: I don’t remember if you used tool calling in this one, but yeah, the models would just diverge after like ten iterations and not produce anything meaningful.
Swyx [00:10:03]: Yeah. But like, then. So okay, like now talking to myself three years ago, the answer
Vibhu [00:10:08]: Of course they will get better
Swyx [00:10:09]: Collect all the failures, build benchmark, and then collect all the, examples, build the RL environment
Akshat [00:10:15]: Right
Swyx [00:10:15]: Sell it for like ten billion dollars to Meta.
Swyx [00:10:17]: And then also train a model and then sell that for sixty billion dollars to Elon. And this is
Akshat [00:10:23]: Yeah, of course
Swyx [00:10:23]: The funny machine. Like, it’s like, it’s about the hardware.
Akshat [00:10:28]: It’s hard to have that inherent conviction that the stuff will get that much better.
Swyx [00:10:33]: In retrospect, it’s so fucking obvious.
Akshat [00:10:36]: Fair enough.
Swyx [00:10:37]: Like, what else were we doing back then? I don’t know. anyway. Yeah. So this. That was the start of your sandboxing journey, right? I feel like it didn’t blow up until, like, last year.
Akshat [00:10:49]: Yeah.
Swyx [00:10:50]: So there was like a couple years of quietness.
Akshat [00:10:52]: Exactly, yeah. We were
Vibhu [00:10:53]: I think very underrated product value. Like, my experience with Modal, Charles, before he had joined Modal, met this guy at a hackathon, and he really insisted we wanted to run some small model, not hosted anywhere, and he’s like, “ there’s this cool company, Modal. They’ll like spin up a GPU sandbox, we can throw it on there. They’ll take a Hugging Face link.” And like there’s so much value just right there, right? Like instant hosting, spin it up, spin it down. It’ll stay cold, but we run the demo a few days later, it’ll come back up and like all this stuff in retrospect, like it’s still what we needed like today.
Akshat [00:11:27]: Yeah, it’s still needed today. workload shapes have changed a lot as, we run stuff for people with really massive production scale and, there it’s it’s not about scaling from zero to one, but it’s how do we scale really elastically, from like thousand to fifteen hundred GPUs very quickly in a given region. It’s the same shape problem.
Elastic Inference, GPU Autoscaling, and Custom Models
Vibhu [00:11:50]: Okay. So you look at, say, Cursor Composer, right?
Akshat [00:11:53]: Yeah.
Vibhu [00:11:53]: They had a. “We’ll do RL on a model every couple hours.” you guys have a whole version of RL inference gym and whatnot.
Vibhu [00:12:01]: When you look at workloads like that, you’re doing train runs where you need to scale up, scale down every hour thousands of GPUs, right? That’s the example for we do need it, right?
Akshat [00:12:12]: Yeah. Well, so I’ll, I’ll take a step back and, maybe talk about like how people use Modal today. because our biggest use case is, elastic inference. And the thing we first found product market fit, with was inference for custom models. So we stayed away from the LLM space, and we were serving companies like Suno for audio, Runway for video, robotics, comp bio companies that train their own model elsewhere. But Modal is the best black box that for deployment, scaling to however many GPUs you need as your traffic pattern changes. And we saw all of them like have a very unpredict- predict- predictable, traffic pattern. it’s like diurnal. It’s Some days, like the company will do a launch and, they’ll need like, way more. And it’s not just one model that they deploy. They-- all these companies deploy, lots of different models in different regions, and so the autoscaling problem becomes even harder because then you have to scale within a certain region, and those cycles are offset. So different times you scale up in different regions.
Akshat [00:13:20]: So that’s like our sort
Vibhu [00:13:22]: And that
Akshat [00:13:22]: Yeah
Vibhu [00:13:22]: That in and of itself is a huge category. There’s a bunch of inference providers which, provide this fireworks, does this as a service together, whatnot, Base10. that’s carved into its own niche for language models, at least right now.
Akshat [00:13:36]: Yeah. the thing that we have specialized in is the autoscaling aspect.
Vibhu [00:13:41]: Yeah.
Akshat [00:13:41]: Because we found that it’s not universally true that everyone else can autoscale, and we’ve gone deeper into it on the tech side by, we’ve incorporated GPU snapshotting into the product so we can take the GPU state, like your torch.compile model, snapshot it, and the next cold start is way faster. And so going back to your question, it’s That’s why you need a lot of burstiness for inference. But then people also do a lot of demand training, like for RL stuff, your rollouts are bursty, as you said. People also do a lot of batch jobs. So we’ll see, a lot of companies, before they have a training run, they’ll need thousands of GPUs to run encoding or something like that. And I think those things are much more bursty than. I agree that agents are not that bursty. sandboxes are, except when you’re doing RL. RL is just
RL, Batch Jobs, and 100,000 Sandboxes
Vibhu [00:14:28]: Or commerce
Akshat [00:14:28]: Insanely bursty.
Vibhu [00:14:29]: Yeah.
Akshat [00:14:30]: Yeah. Like when you’re doing, rollouts, you sometimes need a hundred thousand sandboxes in your sandboxes.
Vibhu [00:14:37]: Yeah. I’m curious if you’ve seen early sparks of continual learning. There are some people, like our friends, ngram, recently announced this
Akshat [00:14:45]: Yeah
Vibhu [00:14:45]: They’re, they’re trying to do training. That also seems like a different workload, right? If you’re doing training twenty-four/seven per se, there’s a very weird dynamic of how you’re using GPUs between people and whatnot, but seems like something you guys would work for.
Akshat [00:15:00]: As you said, we’re, we’re fortunate to work with a number of, customers at the frontier and grab some of our customers. and they are taking the primitives we have, and trying to use them in very interesting ways, like continual learning. It’s possible as the stuff gets better, some of that will be part of, our offering as well if, more people need it. but we’re, we’re just waiting to see
Vibhu [00:15:23]: Yeah
Akshat [00:15:23]: How it shakes out.
Vibhu [00:15:24]: Is there a primitive that you added after sandboxing that was the next step in the story?
LLM Inference, DeFlash, and Speculative Decoding
Akshat [00:15:32]: I guess we’ve been going much deeper into LLM inference
Vibhu [00:15:35]: Yeah
Akshat [00:15:35]: Because we realized that some of the advantages we have with like autoscaling, again, especially in different regions and whatnot, are, not present elsewhere. and the place where we had a gap was we weren’t, working on the model layer itself. Like we were a black box. And, we realized that, we can get to frontier-level model performance, with, by having great people who work on this. And, we’ve been open sourcing a lot of our work, in terms of, Recently, we, shared our work on DeFlash, which is a block-based, speculator, and we’ve open sourced, all of it. So, you can - By using open source DeFlash, you can get the same performance as you would with one of the proprietary providers. And the next thing we’re thinking about here
Vibhu [00:16:23]: I thought this was
Akshat [00:16:24]: Yeah
Vibhu [00:16:24]: An interesting blog post as well, right? Like, I think in here you make a claim that. Not a claim, just that how effective speculative deco-decoding really just get to.
Akshat [00:16:33]: Yeah.
Vibhu [00:16:33]: Anything you wanna point out from this around, what people should know?
Akshat [00:16:39]: Yeah, absolutely. the high-level summary is, it would help to describe what speculative decoding is.
Vibhu [00:16:44]: Yes.
Akshat [00:16:44]: I will, yes.
Vibhu [00:16:45]: I think, like
Akshat [00:16:46]: Yeah
Vibhu [00:16:46]: So we’ve covered like Eagle and all this
Akshat [00:16:47]: Yeah
Vibhu [00:16:47]: Like Hydra and all those things, but it was like two years ago.
Akshat [00:16:51]: Yeah.
Vibhu [00:16:51]: I think it doesn’t hurt, right?
Akshat [00:16:52]: Yeah. Speculative decoding is you have a smaller model, called a draft model, predict tokens ahead of the bigger model, and then you have the bigger model, verify all of this, all the tokens are predicted. And the reason it’s faster is if you’re predicting, one token at once, you’re bound by memory bandwidth. But if you can batch the verification of, the draft model, then you’re much more efficient using compute, and it’s faster, and as long as your draft model is producing a lot of tokens that can get accepted, which is called the accept length, you can get a speed up that’s, multiple times of, the original model speed. and well, that’s what we highlight here. It’s Like people talk a lot about we made these kernels faster and whatnot, but improving kernel will only give you like few percentage points of improvement, and, increasing accept length, literally is a multiplicative decrease
Vibhu [00:17:47]: Like two to four X.
Akshat [00:17:48]: Yeah, exactly.
Vibhu [00:17:48]: Without much head-on performance.
Akshat [00:17:50]: Yeah. I think it may - you are running a second model, right? So it may be something more expensive in the compute,
Vibhu [00:17:57]: I meant quality performance
Akshat [00:17:58]: Probably not by much
Vibhu [00:17:58]: But yeah. I think
Akshat [00:17:59]: So there’s no drop in quality performance
Vibhu [00:18:01]: Yeah
Akshat [00:18:01]: Because you’re always. You’re never accepting a token that the big model
Vibhu [00:18:04]: It’s strictly better
Akshat [00:18:05]: Yeah
Vibhu [00:18:05]: Or it’s same.
Akshat [00:18:06]: Exactly.
Vibhu [00:18:07]: Right. Yeah.
Akshat [00:18:08]: And so we’ve been working a bunch on DeFlash, which is a block-based speculator. so it’s instead of predicting, one token at a time, it’s predicting a block. And we’ve been open sourcing our work with it. The next thing for us here is for helping people train speculators and custom models. it’s it’s something that traditionally is very forward-deployed engineering driven, support deployed, engineer driven, like you work with customers and help them do that. And our vision for. This is why we launched Auto Endpoints, is we want to make frontier-level performance available to everyone. And so, we mentioned this in the announcement, we teased it. The next thing we’re, we’re launching is, as you run an auto endpoint, we shadow traffic
Auto Endpoints and Frontier-Level Performance
Vibhu [00:18:54]: Do you want to explain what auto endpoints are?
Akshat [00:18:57]: Yeah.
Vibhu [00:18:57]: I lovely, yeah.
Akshat [00:18:58]: Yeah. So, this is, I guess, going back to your Modal is you touch the code, but, sometimes people don’t wanna touch the code, and they wanna get started with an endpoint that works and has all the great performance and, scalability that Modal has. So we’ve made that easier with, a way to create an endpoint from our UI, from the CLI, that has all of our optimizations that we talked about, like the DeFlash stuff already baked in, and there’s full transparency. So we give you the code, you can go run it yourself, and if you want, you can eject out into the full Modal experience, which we see as people get sophisticated, they do wanna tweak the models, they wanna, fine-tune stuff. You can still do all of that. It’s it’s not a black box. And yeah, the next thing, as we teased later in the post, is how do we give you value even beyond this in terms of having your draft models evolve as your data distribution evolves, again, without having to talk to a person and, yeah.
Vibhu [00:19:59]: I guess just to understand it directly, you have the GPUs, you have an endpoint that’s compatible, you serve open model. If someone was to do this themselves, what’s the delta that you guys provide? So you do a lot of open source great work on effective inference. how does it compare to, say, I take the same model, 5.2 FP8, take shelf inference engine, vLLM, SGLang, get compute of similar capacity, similar cost. What’s the delta that plugging into something this, like this offers outside of the benefit of, scaling?
Production Inference Beyond Raw GPUs
Akshat [00:20:34]: It’s interesting because we’ve taken the approach of open sourcing our contributions and upstreaming them. we work closely with the SGLang team. We want the improvements that our team, comes up with to be, there in open source for others to use, even outside of Modal. The benefit to us is we have a team that has significant expertise in terms of if you do have something that is not there, our team can help you get that performance, first. the other thing is with these endpoints, we are way more elastic, as you said, than, anyone else, and you have true scaling to zero. you have true, burstiness, and in practice, that matters a lot more to people than just finding, the GPU and, running Modal code on something.
Vibhu [00:21:20]: Yeah. And I will say it’s not that straightforward to just. like what I said is easier said than done, right?
Akshat [00:21:26]: Yeah.
Vibhu [00:21:27]: It’s I think still for the average person, still hard to just gut check using different. There’s, there’s quite a bit of combinations you can make there. the trade-offs aren’t really known at face value.
Akshat [00:21:40]: Yeah. it’s it’s not just that. I think it’s it’s that running production-grade inference is a hard infer problem.
Vibhu [00:21:49]: Yeah
Akshat [00:21:49]: Even if you subtract out the autoscaling
Vibhu [00:21:50]: Yeah
Akshat [00:21:51]: Is controlling things like tail latency and, making sure every, request is delivered at least once and whatnot.
The Model and Agent Lifecycle
Vibhu [00:22:00]: There’s a lot of innovation that you can do here. I think, it’s very interesting that you’re starting to encroach on, like as you become a full cloud, you’re starting to encroach on other people’s turf.
Vibhu [00:22:09]: What will you not do?
Akshat [00:22:13]: Well, we wanna follow our users and, make sure they get like a platform that has everything that works well together. so right now we’re focused on the model lifecycle and the agent, lifecycle. so both like going from data prep to training to inference, and then also if I want to deploy a background agent, let’s say, sandbox, do persistent storage, a whole bunch of other stuff.
Vibhu [00:22:38]: We talked to Cole, who did, OpenInspect. Yeah.
Akshat [00:22:42]: Yeah.
Vibhu [00:22:42]: And RealInspect also is on Modal.
Akshat [00:22:44]: Yeah. So Ramp Inspect was a great example of a background agent that was really successful because they, were able to use some of the primitives like snapshotting and fast scaling to just have something that feels really reactive and works well.
Ramp Inspect and Background Agents
Vibhu [00:23:02]: Yeah. That’s the new CTO of, Ramp right there.
Akshat [00:23:05]: Yeah, Rahul.
Vibhu [00:23:08]: It was really fun. yeah, okay, I think, all very bullish. Like, one of my reflections was also I did not originally. So when I met you guys
The Inference Inflection: CPU, GPU, and Co-Location
Vibhu [00:23:19]: You weren’t that much in the GPU game, and now you’re all about, inference. And one of the points that I hinged on for Jensen’s keynote at GTC this year was, what we’re calling like the inference inflection, right? That let’s say in AI workloads or machine learning workloads, it used to be like, let’s call it eight to one GPU to CPU, and now it’s more like one to one, which is like a interesting. Like, - because of how much agents are blocked or call out to this, to CPU heavy stuff the actual, like, limiting factor, like, swings back and forth from GPU to CPU a lot more than it used to be all GPU and then occasional CPU.
Akshat [00:24:01]: Yeah.
Vibhu [00:24:02]: GPU, CPU. And now it’s like just constantly, and you just have to locate everything.
Seventeen Clouds and the Supercloud Strategy
Akshat [00:24:08]: Yeah. And that’s one of the things that, again, we see as, something appealing about Modal, which is we’ve built this capacity pool that spans, 17 cloud providers, so we’re, we’re very good at Running on various kinds of cloud capacity across the world
Swyx [00:24:24]: You don’t have your own data centers?
Akshat [00:24:25]: We don’t have our own data centers. We just run across a lot of neo clouds
Swyx [00:24:29]: Yeah. Are
Akshat [00:24:30]: Metal providers.
Swyx [00:24:30]: Yeah. Question mark.
Swyx [00:24:31]: Yeah. You’re, you’re running the math, and you’re like, “What’s the cutover point where you’re like.”
Akshat [00:24:36]: Yeah, it’s a good question. part of it is we see our differentiator in the software layer, and, being capital light and focusing on the software helps us move really fast. so far it’s worked out well because there are so many other people building data centers that we’re able to work effectively with them, and again, focus on what makes us, special.
Swyx [00:24:55]: Yeah.
Swyx [00:24:56]: 17 gets you into, like, the local providers sometimes. Like
Akshat [00:25:00]: The,
Swyx [00:25:01]: Which was the most interesting one?
Akshat [00:25:02]: There are a lot more neo clouds than you expect, and they all have various degrees of, various levels of reliability. And, that’s why it’s something we’ve invested a lot of time in, is building our own reliability layer on top. so if the GPU falls off the bus or something happens, we user workloads are not affected, and that lets us use a lot more capacity than,
Swyx [00:25:30]: Yeah
Akshat [00:25:30]: You as a user would be able to.
Swyx [00:25:32]: It’s a useful thing to have because like now everyone knows, like, what layer you are and, like, you optimize for being the super cloud of all clouds.
Akshat [00:25:41]: Yeah. That’s, that’s, that’s the idea. and so I guess when you mentioned colocation, that’s, that’s another interesting thing where, one thing we’ve seen is people come to us when they want, very specifically located, CPUs or GPUs, like they want
Swyx [00:25:57]: Oh, they pin it in like
Akshat [00:25:58]: Yeah
Swyx [00:25:58]: EU?
Akshat [00:25:59]: Exactly. Or EU, US.
Swyx [00:26:01]: Right. Data resiliency
Akshat [00:26:02]: Australia
Swyx [00:26:02]: Locality thing or performance or what?
Akshat [00:26:04]: It’s either data locality or latency, yeah.
Swyx [00:26:07]: Yeah.
Akshat [00:26:07]: Like, you want your. They’re running sandboxes and model. They want them to be right next to a
Swyx [00:26:10]: Yeah, it’s easy then
Akshat [00:26:11]: Yeah
Swyx [00:26:12]: To. That is important in all those things. and so, like, you’ve accidentally, I don’t know if it’s accident, but, like, you’ve built the perfect primitive for agents to express themselves. And then, like, it’s almost very funny how every extra development just involves more file system, just involves more CPU.
Akshat [00:26:30]: Yeah.
Swyx [00:26:31]: Just like the things that you already have. I don’t know much about, if there’s any, like, networking usages that are interesting, but you’ve also done some good work on networking.
Networking, Sidecars, Private IPv6, and Sandboxes
Akshat [00:26:40]: Yeah, that’s exactly right. Like, we’re just taking compute storage and networking and building stuff on that layer, for, again, the stuff people need.
Swyx [00:26:49]: Yeah
Akshat [00:26:50]: We see a few interesting networking things coming up. one is people want networked sandboxes. so we have
Swyx [00:26:57]: For like a Docker cluster type thing.
Akshat [00:26:59]: Yeah.
Swyx [00:26:59]: Sorry, Docker Swarm. Oh, fuck. What is it called?
Akshat [00:27:02]: Compose.
Swyx [00:27:03]: Compose type thing.
Akshat [00:27:04]: Yeah. So if you want Docker Compose, our sandboxes now support, this thing called sidecars. So you can. A sandbox is a pod of containers, and you can run multiple containers in, a sandbox. also useful because, going back to networking, people want a lot of control over, outbound networking from a sandbox.
Swyx [00:27:23]: Yeah.
Akshat [00:27:23]: Like, they might wanna run a middle proxy for, like, maybe logging stuff for RL or, controlling how egress can happen to a domain, injecting credentials. and yeah. So we’ve, we’ve had to build a lot of that stuff ourselves.
Swyx [00:27:38]: Yeah.
Akshat [00:27:39]: But then also sometimes people want, sandboxes spanning multiple nodes to talk to each other, which is an emerging thing we’re seeing. We have support for that for a different reason, and yeah, we’ll see if that becomes stable.
Swyx [00:27:52]: Like, just an open socket. It’s a. This is directly like mTLS.
Akshat [00:27:56]: We do support that, which is you can, expose a tunnel inside a sandbox.
Swyx [00:28:01]: Yeah.
Akshat [00:28:01]: And then you can either expose it to public internet or it can be, you can add like a HTTP, auth layer above it. But we have this thing called I6PN, which we haven’t talked about, which is this, like, overlay network using IPv6 addresses. so if Modal containers, within the same workspace, when this is enabled, can address each other using this private IPv6 address, and no one else can.
Akshat [00:28:28]: So it’s like private networking, for containers. We built it because we needed it as a primitive for our distributed training product. so we have this other feature, which is you can add a decorator to a function, and you get a cluster of GPUs. and they have RDMA networking. so you can run a distributed training job, that’s truly serverless. and we did the overlay network for that. But then we’ve seen that people are using it for other reasons, and, I’m intrigued to yeah, what would people do with it.
Swyx [00:28:59]: Build primitives and let people figure it out, right?
Akshat [00:29:01]: Yeah, exactly.
Swyx [00:29:02]: You put out a pretty interesting
Akshat [00:29:03]: They’re like, they read the docs webpage. Let me use that
Swyx [00:29:06]: Yeah
Akshat [00:29:06]: Something they never intended to work. This is literally not even in our docs page. People somehow found it, and they’re using it.
RDMA, Memory Movement, and Distributed Training
Swyx [00:29:12]: Huh.
Swyx [00:29:14]: The way you portrayed it with, like, RDMA versus TCP, like, very well laid out, but just the transfer speed change at scale for RL, like yeah, you have it, you have it built in. I’m sure someone found it. It’s found it to be a lot more efficient before you made a thing out of it, right?
Akshat [00:29:32]: Yeah. And not to split hairs, I guess the overlay network is the TCP overlay network.
Akshat [00:29:39]: The reason we have that is you need that to do the key exchange for RDMA before you set up the RDMA network on top of that. but then people found the TCP part.
Swyx [00:29:48]: Can I tell you, this is like a big aha moment for me because
Akshat [00:29:51]: Yeah
Swyx [00:29:51]: So I review 2,200 submissions for the World’s Fair.
Akshat [00:29:56]: Yeah.
Swyx [00:29:57]: And then I got this from John Osterhout
Akshat [00:29:58]: Huh
Swyx [00:29:59]: Who I don’t know if. Do John Osterhout by name?
Akshat [00:30:01]: The name sounds familiar.
Swyx [00:30:02]: He published a. He’s a well-known professor, published a lot of interesting software design books, and this is the talk he chose to submit, is on RDMA at Inference. And I’m like, you wouldn’t think that this guy, who is like operating systems guy, would care about RDMA.
Akshat [00:30:20]: I, it makes sense to me because I,
Swyx [00:30:24]: This is the cloud, right? Yeah
Akshat [00:30:25]: Like, the way you move around your KV cache and how efficiently you can do it, how efficiently you move, your weights from your training GPUs to your inference GPUs in RL is there’s a lot of degrees of freedom, and it is a systems problem
Swyx [00:30:41]: Yeah
Akshat [00:30:41]: Moving memory around
Swyx [00:30:42]: Yeah
Akshat [00:30:43]: Scheduling.
Swyx [00:30:44]: This shows you how primitive my understanding of networking stuff is.
Swyx [00:30:46]: Is this like the domain of WireGuard as well?
Akshat [00:30:50]: Not quite.
Swyx [00:30:51]: It’s adjacent?
Swyx [00:30:53]: Explain everything.
Akshat [00:30:54]: Sure.
Swyx [00:30:56]: How do we move memory around GPUs?
Akshat [00:30:58]: Well, so sorry. Yeah, that is memory. Sorry, I was talking more, and maybe I was talking like five minutes back, about the private IPv6, addressing that you’ve set up.
Swyx [00:31:09]: Yeah.
Akshat [00:31:09]: Is it like it’s a VPN?
Swyx [00:31:10]: Yeah, it is like a VPN, and yeah, WireGuard is, yeah, you’re right. It is,
Akshat [00:31:16]: Right. Yeah, you already moved on to new topics
Swyx [00:31:17]: A similar
Akshat [00:31:18]: Okay
Swyx [00:31:19]: In the same space, WireGuard is, encrypted and this is,
Akshat [00:31:23]: And you don’t need encryption.
Swyx [00:31:23]: Yeah.
Akshat [00:31:24]: Yeah.
Swyx [00:31:24]: This is not encrypted. that’s the main difference. This is TCP and we have eBPF programs that will reject or allow the TCP connection based on whether you’re allowed to do it.
Akshat [00:31:35]: Used to involve a full sidecar, but now you have eBPF in the Linux kernel.
Swyx [00:31:39]: Yeah.
Akshat [00:31:40]: Yeah. I don’t know if this is a natural follow-on to the topic of like my skepticism on distributed training is that while, like, people spend a lot of money on, like, cables to hook up GPUs, and even that is not, like, fast enough, and that’s the bottleneck, is your networking fast enough?
Swyx [00:31:59]: Yeah. So I guess you’re talking about fully distributed training like, Dialog or something which is like cross data center
Akshat [00:32:06]: That would be, yes.
Swyx [00:32:07]: That’s the extreme.
Akshat [00:32:08]: Yeah.
Swyx [00:32:08]: You’re in the middle, and then other people would have like the Mellanox cables up in, like, their actual data center.
Akshat [00:32:14]: When you run multi-node training on Modal, RDMA, I think Mellanox, is, or InfiniBand is like a, is all seen as RDMA. but it’s a way to bypass the TCP networking stack and, transfer, stuff much faster, between one node, to the other. And we have I think like 3 terabit per second, internal networking
Swyx [00:32:40]: Okay
Akshat [00:32:40]: Which is the standard that’s needed.
Swyx [00:32:42]: Okay. So I misunderstood what
Akshat [00:32:43]: 50
Swyx [00:32:43]: What part of the stack you were
Akshat [00:32:44]: 50 gigs over
Swyx [00:32:45]: Yeah
Akshat [00:32:45]: If you went
Swyx [00:32:45]: Yeah
Akshat [00:32:46]: RDMA.
Swyx [00:32:46]: Okay.
Swyx [00:32:48]: Yeah. I, very impressive work.
Multi-Node Training, Post-Training, and Auto Research
Swyx [00:32:52]: So effectively you’re extending like the model philosophy to the training cluster, like, yeah.
Akshat [00:32:59]: Yeah. And we’re, we’re not going for like large scale training runs. the thing that we’ve built multi-node training for is, we see a lot of, smaller scale post-training. like, people are post-training like medium sized fund models, so they can, get higher quality on inference. this is a perfect fit, for something like that.
Swyx [00:33:21]: Yeah. That is my impression of how a lot of these labs explore branches in post-training and then eventually merge whatever they find in.
Akshat [00:33:31]: Yeah. The other use case we’ve seen for multi-node training is even if you have a big cluster, your researchers are still doing small runs
Swyx [00:33:38]: Yes
Akshat [00:33:39]: Having elasticity there
Swyx [00:33:40]: Right, sure
Akshat [00:33:40]: Matters a lot more.
Swyx [00:33:41]: Yeah. the, like, this is like the current limiting factor for auto research, which is like you need to give your model some GPUs in order for it to completely run.
Akshat [00:33:51]: We have a blog post on auto resource and model is,
Swyx [00:33:55]: Yeah
Akshat [00:33:56]: Yeah, like, turns out to be pretty good substrate for that.
Swyx [00:33:59]: So my impression is auto research means many things, like
Akshat [00:34:01]: Yeah
Swyx [00:34:01]: Anything that Andrej coins. Right now it’s still science fair, right? Like not like, I don’t know how many people are doing this.
Akshat [00:34:08]: We’re having a golf.
Swyx [00:34:08]: Yeah.
Akshat [00:34:09]: I thought the same thing.
Swyx [00:34:11]: Yeah, you would know.
Akshat [00:34:12]: We, like, our internal both training and inference teams use this the general shape of this quite a bit. like we have this one internal repo called auto inference, which essentially we’ve automated our own forward-deployed engineering efforts using, this harness, which is, the agent will just spin up a sweep of different things. It’ll even run like, NVIDIA inside profiler and it’ll like tweak configs and it’ll arrive the right thing. it’ll change your GPUs both from H200 to B200, and works really well.
Swyx [00:34:47]: Nice.
Akshat [00:34:47]: So yeah.
Swyx [00:34:48]: By the way, I enjoy that your forward-deployed engineering is so technical that you have to do these things.
Swyx [00:34:52]: It’s very different from forward-deployed engineering from other people.
Akshat [00:34:54]: Yeah. For our forward-deployed engineering team is, essentially they’re like applied inference researchers or applied training researchers.
Swyx [00:35:02]: Someone told me like they have to be able to build, but they also have to be able to sell. do they have to sell or are they like they’re good, they’re just like post-sale type of thing?
Akshat [00:35:09]: It does, being able to talk to a customer and engage effectively with them
Swyx [00:35:13]: Yeah
Akshat [00:35:13]: Matters a lot.
Swyx [00:35:14]: They want the same thing.
Akshat [00:35:15]: Yeah.
Swyx [00:35:15]: ?
Akshat [00:35:15]: But it’s it’s not really a sales, thing. We pair them with-- We have solution architects as well that are more on the sales side.
Swyx [00:35:23]: Okay. Let’s spend a bit more time on auto research. This is a big focus for for this year. Where does this go? like, have people explored enough? Like, there’s all these beautiful charts of like improve and then level off a bit and then you find the next thing. Is this one abstraction up from normal training? Is that how we think about it, or do you think about it differently? Like model level training versus high, like driven hyperparameter search.
Auto Inference and Modal Bench
Akshat [00:35:51]: Yeah, like,
Swyx [00:35:51]: Someone, some people call it like neural architecture search or whatever, right? Like.
Akshat [00:35:54]: Yeah, - So the stuff I’ve seen people do with it is nowhere on the architecture level. It’s pretty much tweaking parameters, but it’s it’s a hyperparameter sweep that’s guided by some model intuition, so it’s like much more efficient than, whatever other, sweep you would have.
Swyx [00:36:12]: Yeah, it’s just, it’s just a question of where you want to spend your compute?
Akshat [00:36:16]: Right.
Swyx [00:36:16]: ‘Cause yeah, you can just throw infinite amounts of money on this and somehow you’ll bang out Shakespeare?
Akshat [00:36:22]: Yeah, infinite monkey.
Swyx [00:36:24]: Yeah, so like the very good for model. and I think it’s also very important that agents can spin up other agents, can spin up their infrastructure. Like very good for you. how good is our LLMs at generating model code? Like the benefit of existing LLMs is that you are in the data.
Akshat [00:36:42]: Yeah. They’re, they’re surprisingly good. I think like pre Cloud 4 they were not, and then now they’re able to shot, stuff out of the box. But we’re playing around with releasing like a Modal Bench for like the harder
Swyx [00:36:55]: Yeah
Akshat [00:36:55]: Things, that the LLMs cannot do yet and maybe
Swyx [00:36:59]: What’s an example of that?
Akshat [00:37:01]: I think the things that- Sometimes agents struggle with, without right guidance and a skill is, how to, use the rest of our observability. Like how to. Something is failing, like how do you look at the logs and then update the right thing? It’s reasoning about that. But they’re able to shot, like
Swyx [00:37:23]: Yeah. You can just add a skill to it?
Compute Strategy and Capacity Planning
Akshat [00:37:26]: Yeah. So we have a Modal skill now that. Which is why we built this Modal Bench. It’s to find things like that, so we can address them in our tool.
Swyx [00:37:35]: Tune a skill. Yeah.
Akshat [00:37:36]: Yeah.
Swyx [00:37:36]: No. it’s it’s good. are you facing any shortages? like we talk a lot about GPU shortages, but also CPU, also memory.
Swyx [00:37:44]: Yeah.
Akshat [00:37:45]: We have had a lot of growth, which means that, there’s - we’ve had to be much better about
Swyx [00:37:53]: Planning
Akshat [00:37:54]: Proactive capacity planning.
Swyx [00:37:55]: Yeah.
Akshat [00:37:55]: So we have,
Swyx [00:37:57]: Which by the way, like it’s like a MBA’s like dream
Akshat [00:38:00]: Yes
Swyx [00:38:00]: Is like just planning this stuff. I think last time you and I talked about something maybe about this.
Akshat [00:38:03]: Yeah. we have a really competent team of people that we call, The role is called compute strategy. so yeah, if anyone listening here or wants to work on that
Swyx [00:38:13]: Compute strategy?
Akshat [00:38:13]: Yeah.
Swyx [00:38:14]: I think,
Akshat [00:38:14]: I feel like,
Swyx [00:38:15]: I think the normies call it FP&A or something.
Akshat [00:38:18]: Well, it’s more It’s it’s not FP&A. It’s it’s There’s a lot of interesting financial questions of like what is the blend between one year and three-year reservations? how do we forecast our own capacity? how do we. especially since our capacity is very fungible across different GPU types and different regions, like you have to model a lot of it. and you also have to have an opinion on how the supply chain is gonna evolve, and then you have to like, take bets,
Swyx [00:38:49]: Yeah
Akshat [00:38:49]: Based on that.
Swyx [00:38:50]: Tokenomics.
Akshat [00:38:50]: Yeah.
Swyx [00:38:51]: This is like probably a not a real point, but, I was trying to think about like what other industries. I was trying to think about like, we cannot be first to like these kinds of problems.
Akshat [00:38:59]: Yeah.
Swyx [00:39:00]: And what other industries have had this? And I was like, airlines with fuel and like they have to hedge their fuel and like, I think for a long time Southwest because they made like a hero fuel bet, they like were like super low cost because
Akshat [00:39:12]: Oh
Swyx [00:39:12]: Compared to everyone else.
Akshat [00:39:14]: Yeah. I hadn’t thought about that.
Vibhu [00:39:16]: We’re at a fun time too?
Akshat [00:39:18]: Yeah. It’s. A lot of the compute business in general, for us is also about being very good about capacity management. That is how you have great unit, economics. but also over time it’s how you can unlock more value for customers. Like, one of the things we’re building now is like a way for customers to get, If they don’t care about latency, like get much cheaper pricing and they’ll get results back in like next 24 hours or something, like a batch tier essentially.
Batch Tiers and Latency-Insensitive Workloads
Swyx [00:39:47]: Yeah.
Akshat [00:39:47]: And those are levers we have because we control the whole stack and scheduling and whatnot to give people a sufficient
Swyx [00:39:53]: Yeah. I feel like they’re not as popular. Like those, like the Frontier Labs have all those APIs. They’re not as popular as they should be.
Akshat [00:40:00]: The demand that we see for something like that is not for LLMs. although sometimes people wanna run evals and
Swyx [00:40:08]: Okay
Akshat [00:40:08]: Synthetic data prep and there it makes sense.
Swyx [00:40:10]: Okay.
Akshat [00:40:11]: But it’s from a lot of LLM companies, like people who are doing computational bio, like they have to run really big batch jobs and they don’t care about when they get it back.
Swyx [00:40:22]: Yeah. And like they have a reasonable. It’s it’s also like a cousin to the stopping problem of like, will this finish in time?
Akshat [00:40:30]: Yeah. You can bound it.
Swyx [00:40:33]: Yeah.
Akshat [00:40:33]: Like you can give people
Swyx [00:40:34]: Yeah
Akshat [00:40:34]: SLAs on it.
Swyx [00:40:35]: Yeah. I think what’s, what’s interesting is like the next phase of model.
Swyx [00:40:38]: Like what, do people expect from you, now that you’re established and you’re like well-known compute player among all these leading companies. You had an inference launch week, and we talked a little bit about the launches. like what else? Like what else should people know?
What Modal Builds Next
Akshat [00:40:55]: We are building primitives that make our users’ lives much easier. So, I think for example, with LLM inference, thousands more companies are gonna post-train their own models and, deploy open source models for inference. so we’re thinking a lot about what is the best product shape for that. And, that involves everything from our training gym to, then, endpoints that get frontier-level performance. again, but I haven’t talked to anyone. It looks somewhat different on other verticals. Like, we’re also seeing a lot of real-time, audio-video stuff in there, which is why like, we’re working on things like regional routing, with fallbacks. So you can get GPUs that are as close to users as possible. so you get like low latency for video streaming and whatnot. And then on the agent side, it’s,
Akshat [00:41:52]: We’re still working very closely with our customers because stuff is changing so fast in terms of what they need. And, I think beyond sandboxes and persistent file systems, there’s a lot of other things people will need from this agent stack as they build production agents. So yeah, we’re thinking about those other things that fit in there.
Swyx [00:42:13]: I want to ask what the other things are.
Akshat [00:42:15]: Yeah. I probably should share right now.
Swyx [00:42:17]: I think-- I think, okay, so, I do think a lot about the principal components of cloud, and you do talk about compute storage networking.
Akshat [00:42:25]: Yeah.
Swyx [00:42:25]: Because so far for me, it’s fine. so far for the. the first couple generations of cloud, it’s fine. What’s different, qualitatively different about agents that you need some new permission level? Like a lot of people, okay, and I’ll just kinda spew tokens at you until it like hopefully sparks something.
Akshat [00:42:43]: Yeah.
Swyx [00:42:44]: Like the new level now is whatever Claude Code does, which is dangerously scope permissions or like allow list by command or like whatever, right? And sometimes they’re like, “Well, okay, we have like this adaptive thinking mode where like, just trust me, bro. I will make the calls for you.” Is that it? like mediated permissions.
Hard Guardrails vs. LLM-Mediated Permissions
Vibhu [00:43:03]: Now you’re looping it with a goal and letting it roll.
Akshat [00:43:06]: Yeah, I’m, I’m skeptical of LLM media permission for stuff that is at the sandbox level because you do want hard boundaries.
Swyx [00:43:16]: Yeah.
Akshat [00:43:16]: Otherwise, someone can exfiltrate stuff.
Swyx [00:43:20]: But like
Akshat [00:43:20]: Yeah
Swyx [00:43:20]: Maybe that’s old school thinking. Maybe we’re the dinosaurs.
Swyx [00:43:23]: Maybe the AI OS or the LLM OS is really the kernel is a goddamn LLM.
Swyx [00:43:30]: Like it makes you feel uncomfortable.
Akshat [00:43:31]: Yeah, I’m, I’m told
Swyx [00:43:32]: But that’s what trusting the LLM is. Like imagine a spherical cow perfect LLM.
Akshat [00:43:36]: Right.
Swyx [00:43:37]: That it.
Akshat [00:43:39]: Maybe.
Swyx [00:43:41]: I wanna test the boundaries, right?
Akshat [00:43:42]: Yeah.
Swyx [00:43:42]: Like, and I don’t believe that, but I wanna see where I’m wrong ‘cause that’s, that’s the consensus.
Akshat [00:43:49]: Yeah. I think you always need hard guardrails when you want, And you can pair those with softer guardrails, right? And that’s gonna be a lot of mediated.
Managed Agents and Specialized Sandboxes
Swyx [00:44:00]: There. I’ll also get you a end with a couple of your commentary on like the ecosystem outside of Modal. Manage agents. Everyone has one. Gemini, OpenAI, Claude, very useful for you, but also like it is their way of starting to edge into your space.
Akshat [00:44:17]: Yeah.
Swyx [00:44:17]: What’s going on?
Akshat [00:44:19]: Yeah, we’re, very excited to partner with Anthropic and some of the other foundation labs, will not name who we’re also working with. the way we see it is the manage agent thing is a great place to start if you’re starting out building an agent and, But then when you get to, building something more production grade, like you’re a company that’s like Ramp that’s building their own, Ramp also runs their accounting agent on us, so their external-facing agent. You need a lot more control over, your compute primitive on things like, what sort - how do you persist different files that the agent has access to, and how do you snapshot and restore? How do you control the networking? maybe you want GPUs. When you get to that point, you kinda want, a specialized sandbox provider, that gives you those things, and that’s the role that we are trying to play.
Swyx [00:45:15]: Yeah
Akshat [00:45:16]: We don’t really have an opinion on the harness, whether it runs - it’s a cloud-managed agent, and you hook it up to Model Sandbox, or you run the harness in Model Sandbox. We’ll see where people converge with that.
Swyx [00:45:26]: Yeah. Do you any opinions on like the meta harnesses, or just another layer on top of these things?
Akshat [00:45:31]: You mean like the OpenPipe
Swyx [00:45:33]: OpenPipe is one. I think Vercel had one, which I can’t remember the name of right now. Fredshot had one. and then, to me, most recently was Data Databricks that had Omnigen. All these are meta harness. Like it’s kinda pseudo agent cloud type things.
Akshat [00:45:50]: I personally have not played around with them.
Swyx [00:45:53]: Yeah.
Akshat [00:45:53]: Build agents with them.
Swyx [00:45:54]: Everything’s bullish Modal, as long as it consumes more infra.
Akshat [00:45:57]: That’s why we’re focusing on the infra layer. It’s somewhere where our, relative competence is and, also it’s a hard problem to solve.
Swyx [00:46:06]: Yeah. I will say like just generally reflecting on that, I don’t know if - if there’s other topics on Modal, but like just generally reflecting as an infra person, not as intense as you, but in that field, this has like been the most exciting time in infra. Like it was boring for a while, and you couldn’t really get people excited about data infrastructure. Like Eric would get on Data Console, everyone just watched the video and like say, “Look at how many sandboxes I can spin up,” and no one gave a crap.
Why Infrastructure Became Exciting Again
Akshat [00:46:39]: Yeah.
Swyx [00:46:40]: And like now everyone gives a crap.
Akshat [00:46:42]: That’s true. It is a very exciting time, and I think a lot of that’s driven by just the amount of scale all of this stuff needs.
Swyx [00:46:50]: I think the, like a lot of your initiatives or a lot of your like product directions make sense in retrospect, which is like the best kind, but I wouldn’t necessarily have thought about it myself, which.
Akshat [00:47:00]: We need the predictions.
Swyx [00:47:02]: I think there’s a lot that you just don’t even see, right? Like you have the batch, you have the voice, you have the multimodal, but what else?
Akshat [00:47:10]: What else is coming up for us
Swyx [00:47:11]: Yeah. Where do you see things going?
Akshat [00:47:13]: Yeah. I, in general
Biotech, Robotics, and Non-LLM AI Workloads
Akshat [00:47:15]: It’s it’s clear that there’s there’s a huge shift happening. I think one thing that’s not as obvious to people because LLM inference gets talked about so much and is also we work a lot of companies that are, doing things like drug discovery and computational bio, like the Chai Discoveries of the world. Big things are probably gonna happen there. we work a lot of robotics companies that are putting robots in like active deployments and getting good results out of them.
Swyx [00:47:45]: Is there Air Gap Modal? Is there a version that is like prem air gapped whatever?
Akshat [00:47:50]: No. We,
Swyx [00:47:51]: You should cloud only.
Akshat [00:47:51]: Yeah.
Swyx [00:47:52]: Yeah. Okay. But yeah, so what you’re saying is like because you’re focused on primitives and they’re good primitives, you find use cases in all these kinds of things.
Akshat [00:48:01]: Yeah.
Swyx [00:48:01]: Probably diversifies you a little bit away from LMS all the time.
Akshat [00:48:05]: Yeah, absolutely. We’re, we’- our goal isn’t to only serve the LLM inference market.
Swyx [00:48:10]: There are a lot just on the website, the audio,
Akshat [00:48:12]: Yeah. We said both on
Swyx [00:48:14]: Computational bio images. Yeah, there’s a lot here. There’s QTA TTS, customizing. Oh, Chatterbox. there was customizing Whisper.
Akshat [00:48:24]: Okay. Yeah.
Swyx [00:48:25]: This screen reminds me of a fallen competitor, which Replicate.
Model APIs vs. Differentiated AI Products
Swyx [00:48:31]: What’s your postmortem on what happened?
Akshat [00:48:34]: This is one thing we’ve stayed away from is providing an API for models because I think providing model APIs is some of it ends up serving like a really hobbyist market, which is much less sticky.
Swyx [00:48:50]: Yeah.
Akshat [00:48:50]: And we’ve always wanted to build for companies that are building products and need more flexibility that’s not just an API.
Swyx [00:48:57]: Which you can build an API for a model and this is clearly what it is. But you - but what you’re saying, you can wrap it into a more fully functioning back end that you run.
Akshat [00:49:06]: Yeah. So all of our examples, it’s not that spin up this model, here’s an API token, use it. They’re all code.
Swyx [00:49:13]: Okay.
Akshat [00:49:13]: And so the point is that this is just an example.
Swyx [00:49:16]: Starter code.
Akshat [00:49:17]: Yeah. But you can tweak it however you want.
Swyx [00:49:20]: Yeah.
Akshat [00:49:21]: And if you’re like a company building a product, like, computational bio whatnot, yeah.
Swyx [00:49:26]: I guess I’m trying to tease out for listeners
Akshat [00:49:28]: Yeah
Swyx [00:49:28]: When does it stop becoming, oh, you’re just an API call and you’re just a wrapper on API to becoming what you call a product, right?
Swyx [00:49:36]: Like, what is that layer? Like what-- Like, more lines of code, but like beyond that, what is the substance that people add that qualifies it to be something more?
Akshat [00:49:46]: I think there’s a little bit of like a selection effect of like a lot of the companies who do wanna get deeper into that level are probably building something that’s more differentiated. And, I think, an example is like - with LLM inference, originally we, worked with companies that were building their own post-training frameworks or they were, - Ramp early in the day was training their own tokenizer and like swapping out the tokenizer in Llama and whatnot. I’m not saying that’s, that successful, in that case. But a better example is like, let’s say Suno. because Suno, does not use Modal for training.
Swyx [00:50:26]: Mikey on the pod. Yeah.
Akshat [00:50:27]: But they use Modal for all their inference and that’s because they have like a custom-- They have completely custom model architecture and that means that they have to be at the code level and tweak things that are not, just an API.
Swyx [00:50:41]: It’s interesting as well, like we had, Ethan, most recently on the xAI Groq team make a prediction that like the next tier in video gen is not a better video model, it’s a better model or agent that orchestrates video models.
Video Agents and Production Workflows
Akshat [00:50:56]: Oh, interesting.
Vibhu [00:50:56]: Language model backbone that can use tools
Akshat [00:50:58]: Right
Vibhu [00:50:59]: And write code.
Akshat [00:51:00]: Like, yes, I can make my second video or my second video from Groq, but I want my minute video.
Akshat [00:51:06]: And I’m not going there through normal video gen.
Swyx [00:51:10]: Yeah, that’s interesting. I - So we have GPU sandboxes and recently have seen a few companies doing agents that do video manipulation or,
Akshat [00:51:22]: Yeah. Give it FFmpeg and just do it.
Swyx [00:51:23]: Run FFmpeg. But like
Akshat [00:51:25]: That’s not enough.
Swyx [00:51:25]: Yeah.
Akshat [00:51:26]: You need to give it Adobe.
Swyx [00:51:27]: Yeah, I hadn’t put it together with like it would be a video production thing. in my mind these things were going more towards editing
Akshat [00:51:36]: Yeah.
Vibhu [00:51:36]: Well, shout out Mantis.
Akshat [00:51:37]: I think about this a lot.
Swyx [00:51:38]: .
Akshat [00:51:41]: Yeah. Sorry.
Vibhu [00:51:41]: Luma. Luma Agent is a version of this for video production, but it’s a off.
Swyx [00:51:46]: I was gonna get your quick takes, on some other stuff that happens
Gitpod/Ona, CI, and Runtime Sandboxes
Swyx [00:51:50]: In recent news and just-just see if you have anything interesting. Gitpod, very like-- somewhat like, different market. They’re in like the CI/CD market, but technically very impressive. I don’t know if you’ve like taken a real look at them.
Akshat [00:52:03]: Yeah. we’ve, - People on our team have talked to the Gitpod team and they’- they’re technically very strong.
Swyx [00:52:10]: Yeah.
Akshat [00:52:10]: I - We’re, we’re very bullish at Modal on the CI market as well because
Swyx [00:52:15]: Okay
Akshat [00:52:15]: There’s, there’s more agents, coding agents.
Swyx [00:52:18]: Yeah.
Akshat [00:52:19]: They’re gonna run a lot more CI and the primitives there can be much better.
Swyx [00:52:23]: I think there’s a lot of wasted CI.
Akshat [00:52:25]: Yeah.
Swyx [00:52:25]: So is it just like let’s filter? Like what is the highest order bid here in improving CI for agents?
Akshat [00:52:32]: Well, there’s a lot of wasted time in CI on like
Swyx [00:52:36]: Preparing
Akshat [00:52:36]: Preparing your artifacts and like, getting you to the preparing your dependencies and whatnot.
Swyx [00:52:44]: Oh.
Akshat [00:52:44]: And, like build systems help with that. But like if you have primitives that are like memory snapshot and restore, can you just run CI more efficiently?
Swyx [00:52:55]: Oh, okay. Okay. Okay. Interesting. Yeah. another form of like, demand compute.
Akshat [00:53:02]: Yeah, exactly.
Swyx [00:53:03]: Yeah.
Akshat [00:53:03]: It needs the same again, platform.
Swyx [00:53:06]: Yeah. So, for those who don’t know, Gitpod rebranded to Ona.
Swyx [00:53:09]: It was like there was this whole thing. I - I like semi-sounded the alarm at Cognition. I was like, “You should take these guys seriously because their infra is very good.”
Akshat [00:53:17]: Yeah.
Swyx [00:53:18]: And but, then they join OpenAI and, presumably we’ll, we’ll see Codex Cloud from the Ona team.
Swyx [00:53:26]: Like which I think would be very strong. - To me, like teams like that can set up the networking and like the secure boundaries for like, and your like agents to have their own cloud each, effectively is what you’re doing and I’m just trying to draw the analogy or the differences if you have studied them. Like what is the philosophical difference?
Akshat [00:53:47]: My sense is maybe they didn’t go after the right market at the right time because - I guess also got lucky with like agent use cases really taking off and, needing, like more of like a sandbox shaped thing than like, my understanding is, yeah, Gitpod
Swyx [00:54:06]: Really sandboxes work
Akshat [00:54:07]: Never mind
Swyx [00:54:07]: Like CI/
Akshat [00:54:08]: Yeah
Swyx [00:54:09]: Is sandboxes.
Akshat [00:54:09]: Yeah.
Swyx [00:54:10]: It’s just like build time sandboxes versus runtime sandboxes and it turned out runtime was better.
Akshat [00:54:15]: Right. And the difference there is runtime sandboxes have a different configuration surface of like how you configure images, how you like attach like storage
Swyx [00:54:25]: Yeah. It’s it’s fascinating. Other people, Astral also OpenAI.
Python, TypeScript, and the Future of SDKs
Swyx [00:54:30]: Also like Python tooling ecosystem people. Are you still bullish build- building on top of Python? Also recently Modular also got bought by Qualcomm. Just any of your takes there?
Akshat [00:54:43]: Yeah. we had Python as our first SDK language because that was the language that people did data and ML in. I now have Go and TypeScript SDKs as well. and our runtime is completely language- It is written in Rust, but it’s it’s not tied to Python by any means. We haven’t seen-- I think with like inference and training stuff, people are still very Python and the interesting thing with like the agent stuff is people use our TypeScript SDK a lot more because they’re not doing anything that needs ML.
Akshat [00:55:13]: I don’t think we’ll have to go beyond that super soon
Swyx [00:55:16]: Yeah
Akshat [00:55:16]: ‘cause Python and TypeScript is still Dominant.
Swyx [00:55:19]: The last two languages in the world.
Akshat [00:55:21]: Yeah.
Swyx [00:55:21]: That’s it.
Akshat [00:55:22]: Well, English and prompting is the fourth language.
Swyx [00:55:25]: English and prompting. I occasionally talk to people who try to build new languages. They’re like, - Even, what’s his face? Brett Taylor, who’s chairman of OpenAI was like, “We need a new language for LLMs.” So no one has come across one, and I keep looking. Python and TypeScript - You have a lot of data plus, but then also they are very imperfect as just as languages themselves. Then my close is, I think Modal used to be a big bet on developer experience.
Agent Experience as a Company-Building Wedge
Swyx [00:55:52]: And you’ve pivoted the team to agent experience. Is it like the way now, like, do - do, - can entire companies and unicorns, multi-unicorns be built on just having better agent experience? Do you need something else?
Akshat [00:56:05]: It’s a big part of our identity. it’s not just, like the very tactical, how does an agent use the CLI, but it’s also how easy is it to spin something up? Like, what is your iteration time when you wanna spin up a new service and, you wanna get something going in prod? in practice, that matters a lot, to people. And, I think it will continue to matter. Like, people are building stuff even faster, and if you give them ways to do it quickly not have overhead, then.
Swyx [00:56:37]: I think the debate for me has been, do you do anything differently that is, like, very fundamentally different for developer experience versus agent experience?
Swyx [00:56:44]: You seem to be on the side of they’re, they’re like this. They’re like cosine
Akshat [00:56:48]: Yeah. We also have a blog post on that.
Swyx [00:56:49]: Cosine similarity on, like, zero point nine or whatever.
Akshat [00:56:53]: Yeah. pretty much it’s the main shift for us has been, as I said, like, we built this, benchmark, Modal Bench, to see where agents are lacking
Swyx [00:57:02]: Yeah
Akshat [00:57:02]: Literally add surface areas to a product if they’re reaching for something, like maybe this should just be a CLI.
Swyx [00:57:09]: They halluc Oh, yeah. They hallucinate their own features.
Akshat [00:57:11]: Yeah. And sometimes it makes sense. Like if they’re reaching for this thing, it’s product feedback. Like, give it to them. And then, yeah, moving-- we used to only have, like, logs and metrics in our UI, just moving all those things to the CLI as well, so they’re accessible in that form.
Swyx [00:57:26]: Simple as that.
Closing: Modal Bench, AX, and Execution
Swyx [00:57:28]: Cool. Thank you so much. Yeah.
Akshat [00:57:29]: Yeah. Thank you.
Swyx [00:57:30]: This was great.
Akshat [00:57:30]: This was fun.
Swyx [00:57:30]: Yeah. It was a great update and, I can see why you guys have succeeded so much. it is really, focus, but also really good execution.
Akshat [00:57:39]: Thanks. we have a long way to go.
Congrats to Meta Superintelligence on having the top 2/3 image/video models in the world! This would’ve been a candidate for a title story, but unfortunately that is pretty much all the detail we have about Muse Image/Video - no paper, no technical detail whatsoever. Still, this beats the Microsoft MAI models from last month which is nice.
We are noted Lilian Weng fans, so we take notice whenever she drops another research recap, especially rare now that she is a cofounder at Thinky. Today she is thinking about the relationship of harnesses to RSI:
While we have written before about how even Greg Brockman is now quietly endorsing agent/harness engineering, it is refreshing for a respected thinker and neolab cofounder like Lilian to also agree that “Even when many harness improvement[s] get eventually internalized into core model, the need to specify goals and context will not disappear.”
Her post breaks out the main proven design trends in harnesses that everyone should know, and then recaps the harness optimization literature, most notably from the well known ACE paper to even more recent trends like Meta-Harnesses, which we have covered anecdotally on AINews.
It surely also provides a hint as to what Thinky is Thinking, beyond just Interaction Models.
Agent Products, Harnesses, and Long-Running Workflows
Anthropic expands “background agent” UX on top of Claude: The biggest product launch by engagement was Claude Cowork coming to mobile and web, positioning Claude as a task-running background teammate rather than a foreground chat UI. Related posts show the product convergence around a shared home tab and tighter Chat/Cowork integration from @mikeyk. Separately, Anthropic extended access to Claude Fable 5 on paid plans through July 12 in a highly engaged announcement from @claudeai, though many users noted the awkward timing relative to weekly limits in reactions from @kimmonismus and others.
Harness engineering is increasingly the center of agent design: Lilian Weng’s new post was widely referenced as reframing recursive self-improvement around the harness, not direct weight self-modification; Sakana’s summary connects this to The AI Scientist, ShinkaEvolve, and Darwin Gödel Machine in their thread. LangChain echoed the same shift with a new Deep Agents course and an open-source harness project in posts from @LangChain and @hwchase17. Google is also productizing this direction: Gemini API Managed Agents added background execution, remote MCP servers, custom function calling, and credential refresh in posts from @_philschmid and @OfficialLoganK.
Practical agent infra keeps getting more opinionated: There were several notable operator-facing updates: Codex Mobile iOS added task management, filtered diffs, SSH key login, branch comparison, and attachment flows in posts from @Dimillian and @reach_vb; Hermes Agent added pluggable secrets managers plus native 1Password integration and export of sessions/datasets to formats including private Hugging Face repos in @Teknium’sthreads; Weaviate 1.38 made its MCP server GA with runtime-gated write access, notably allowing MCP_SERVER_WRITE_ACCESS_ENABLED to be flipped live without restart in @victorialslocum’s post. A more experimental pattern came from @omarsar0, using a Dial MCP server so agents can escalate decisions via phone call/SMS/iMessage for human-in-the-loop control.
Model and Modality Releases: Audio, Speech, Robotics, and Media Generation
Meta’s Muse Image/Muse Video push agentic generation into media: Meta Superintelligence Labs launched Muse Image and previewed Muse Video in announcements from @AIatMeta, @alexandr_wang, and @_tim_brooks. The notable technical angle is not just image quality, but an explicitly agentic generation loop: planning, web search, tool use, code execution, and self-refinement before rendering. Meta also says performance improves with scaled test-time compute, and that self-refinement behavior emerged during RL rather than being hand-scripted in this follow-up. On public evals, Muse Image quickly reached #2 on Image Arena behind GPT Image 2 in Arena’s ranking, while Muse Video debuted at #3 on Video Arena in another Arena post.
NVIDIA and Cohere both shipped strong audio releases: NVIDIA released Audex, a 30B parameter / 3B active MoE with 1M context for unified text+audio work, summarized by @HuggingPapers and described in more detail by @_weiping. The model’s core claim is preserving text intelligence while adding broad audio generation and understanding via a single MoE backbone. Cohere launched Cohere Transcribe Arabic, described as the most accurate open-source Arabic ASR model, under Apache 2.0, with emphasis on dialects, code-switching, and Arabic-accented English in posts from @cohere and @JayAlammar.
Open robotics keeps consolidating around Hugging Face + NVIDIA: NVIDIA expanded its robotics stack into the HF ecosystem by bringing GR00T 1.7 and Isaac Teleop into LeRobot, aimed at open humanoid robotics workflows, in @NVIDIARobotics’s announcement and integration guide. On the embodied side, UMA showed a strong full-stack robotics narrative: @RemiCadene described a prototype built by a small team in 9 months, while the Northstar reveal and @psermanet’s safety note emphasized vertically integrated hardware/software for trustworthy robots.
Training, Inference, and Post-Training Techniques
Liquid AI’s “Antidoom” directly targets reasoning-loop failure modes: One of the clearest technical releases of the day was Liquid AI’s Antidoom, an open-source training method to reduce doom loops where small reasoning models repeat tokens until context exhaustion. The reported reductions are substantial: LFM2.5-2.6B from 10.2% → 1.4% and Qwen3.5-4B from 22.9% → 1% under greedy sampling, with downstream eval gains. The method, FTPO (Final Token Preference Optimization), relabels the loop-triggering token and redistributes probability toward alternatives, summarized well by @helloiamleonie and @LiorOnAI. This is a good example of the field’s recent pattern: removing specific failure modes rather than only scaling parameters.
Inference efficiency and compression remain a major frontier: NVIDIA’s Puzzle-75B-A9B compression work got strong attention via @omarsar0: compressing a hybrid MoE parent model while preserving reasoning, coding, long-context, and agentic quality, with roughly 2x server throughput and 1M-context concurrency on H100 rising from 1 request to 8. On the tooling side, Nsight Python 1.0 launched in @HagedornBastian’s post, making GPU perf analysis scriptable in Python. Unsloth also shipped GGUFs for DeepSeek-V4-Flash, plus export to NVFP4/FP8 and speedups for GRPO and MoEs in @danielhanchen’s update.
Agent RL and verification are getting more specialized: @cwolferesearch highlighted how GRPO-style normalization is being adapted for agentic RL at the task or environment level to handle higher reward variance in multi-turn environments. Separately, @omarsar0 flagged a training-free verifier paper from Stanford/NVIDIA/Berkeley that reads calibrated continuous scores off scoring-token logits, posting strong numbers across Terminal-Bench V2, SWE-Bench Verified, RoboRewardBench, and MedAgentBench and suggesting verification is becoming an independent scaling axis.
Interpretability, Model Internals, and the “J-Space” Debate
Anthropic’s J-space work dominated interpretability discussion, but also drew sharp criticism: The community split between seeing the work as useful mechanistic analysis and objecting to the consciousness framing. Strong critiques came from @danburonline, @paul_cal, and @scaling01, who argued the vectors are causal largely by construction under the Jacobian-lens definition. A useful historical reference came from @jacobandreas, pointing readers back to the original Jacobian lenses paper.
The stronger technical takeaway is cross-model structure, not consciousness rhetoric: @eliebakouch computed CKA similarity on J-lens geometry across 38 open models and found surprisingly universal layer/depth organization, even across unrelated families like Llama and OLMo. Anthropic and Neuronpedia also released J-lens weights for open models, noted in this follow-up. In parallel, Goodfire introduced Block-Sparse Featurizers for multidimensional concepts in activations, arguing many vision concepts are inherently 2–4 dimensional blocks rather than single directions, in their thread.
Benchmarks, Evaluations, and Domain-Specific Systems
Agent and legal benchmarks continue to expose the gap between “passes many criteria” and “fully solves real work”: Agent Arena placed Claude Sonnet 5 (Thinking) at #6, with strongest signals in confirmed task success and bash usage, but still with uncertainty around steerability. Artificial Analysis launched Harvey LAB-AA, a legal-agent benchmark over 120 private legal tasks across 24 practice areas, where Claude Fable 5 led at 14.2% all-pass rate; Claude Opus 4.8 and GLM-5.2 tied at 7.5%, with GLM hitting that at roughly ~6% of Fable’s cost per task in their release. The big message is that models can satisfy many individual rubric items yet still fail to produce acceptable end-to-end deliverables.
Research automation and specialized domain systems are broadening: Google promoted Experience AI Scientist, a multi-agent system for end-to-end scientific workflows, in this ICML post. DeepMind also launched Predicting the Past, grounding Gemini in Aeneas and Ithaca for Greek/Latin historical analysis via plain-English interactions, in their thread. On legal AI commercialization, Norm Ai announced a $120M Series C at $1.2B valuation and described a full-stack “agentic law” setup spanning software plus an AI-native law firm in @johnjnay’s post.
New open model from Tencent Hy: Hy3 (295B total 21B active - apache 2.0) (Activity: 653): Tencent released the non-preview Hy3 open model collection on Hugging Face, described as a 295B-parameter MoE with 21B active parameters, now under Apache 2.0 rather than the prior restrictive community license. The post highlights that the earlier license reportedly excluded use in regions including South Korea, the UK, and the EU, while top comments point to claimed benchmark gains over HY3-Preview and frame this as potentially relevant for high-end local/home inference setups. Commenters viewed the Apache 2.0 relicensing as the most important change, especially given Tencent’s recent translation models also using Apache licensing. There was cautious optimism that the reported benchmark improvements may translate to real-world usefulness, but with implicit skepticism until tested outside vendor charts.
Commenters highlighted that Hunyuan/HY3 is now listed as Apache 2.0, contrasting it with the prior “community” license that reportedly restricted usage in regions such as South Korea, the UK, and the EU. This was viewed as technically important for deployment because Apache 2.0 removes many commercial and geographic usage barriers.
Several users focused on whether Tencent’s claimed benchmark improvements over HY3-Preview will translate into real-world workloads. Given the reported 295B total / 21B active MoE-style configuration, commenters suggested it could be relevant for “high-end home setups” if inference formats such as GGUF become available.
There was early speculation that HY3 could become an alternative to Qwen and MiniMax models in local/open-weight workflows, but commenters were waiting for quantized releases and independent testing before drawing conclusions.
Thariq had been working on a “Field Guide to Fable” blog series, and happened to have a keynote planned the day of the relaunch, so he kindly pivoted the entire keynote in one night to give the most timely advice he had, which was released today:
The 4 segments are (my watchalong commentary in italics):
2:32Unhobbling Claude: Understanding model behavior
The constraints on a model are often imposed by US - “the harness we put them in, and the way we prompt them”. Therefore when we encounter a new class of model, we should expect to remove or change those harnesses and prompts in order to elicit new behaviors that you otherwise would never see because you were overly limiting (aka hobbling) the model.
a close cousin to “unhobbling” - if unhobbling is about clearing out outdated knowns, then this is about finding things you didn’t even know you didn’t know.
easiest techniques:
telling claude to do a “blindspot pass” for your unknowns
brainstorm for “wildly different design directions”
interview me - similar to /grill-me, but prioritizing high impact questions
“Interview me one question at a time about anything
ambiguous — prioritize questions where my answer
would change the architecture”
use references: in the case of migrations
keep implementation-notes.md: a running log of underspecified decisions made on your behalf
quiz me - ensure MY understanding
14:29Dealing with Grief: Reflecting on the emotional shift in coding productivity
What you used to spend weeks on is now done in hours
16:30Being unreasonable: Demanding good, fast, and cheap results
“Tradeoffs are not real” - because Fable is more capable, you can be more ambitious and not accept tradeoffs.
“Building is easy, generating value is still hard”.
Overall, an excellent talk that we will be mapping out the implications of as the world acclimatizes to the first Fable-class models.
Tencent Hunyuan’s Hy3 Release and the Open-Weight Frontier
Hy3 lands as a serious open model: Tencent released Hy3 under Apache 2.0, a 295B MoE with 21B active parameters, 192 experts / top-8 routing, GQA, 256K context, and a 3.8B MTP layer for speculative decoding. Multiple posts framed it as competitive with much larger systems on reasoning, coding, and agentic tasks, with particular emphasis on reliability improvements like tool-calling stability and anti-hallucination work @eliebakouch, @HuggingPapers, @ShunyuYao12.
Inference support was unusually day-0 mature: @vllm_project said Hy3 runs natively in vLLM from launch with tool-call and reasoning parsers, MTP speculative decoding, and validated support on NVIDIA and AMD. A follow-up detailed Tencent production kernels now upstreamed into vLLM main, including load-balanced decode scheduling and fused FP8 MoE serving, with reported gains of up to 2.95x on mixed-length decode and latency reductions of roughly 24% TTFT and 17% TPOT versus default backends @vllm_project. Community reaction was strong enough that @Teknium quickly made Hy3 free on Nous Portal for two weeks.
Broader open-model context: Hy3 was immediately compared against GLM-5.2, with some posters arguing Tencent has now joined the very top tier of open-source labs if the benchmark and vibe-test results hold @teortaxesTex, while others still maintained GLM-5.2 as the best currently usable open-weight model in practice @tinygrad, @mbusigin. The net takeaway: the open frontier is compressing fast, and the competition is increasingly about deployment robustness rather than just raw leaderboard deltas.
Agent Benchmarks, Harnesses, and Long-Running Memory
AutomationBench-AA adds a more realistic agent eval: @ArtificialAnlys launched an independent leaderboard for Zapier’s AutomationBench, evaluating agents across 657 tasks and 40 simulated SaaS apps with both objectives and guardrails. Claude Fable 5 led at 48.6%, narrowly ahead of Opus 4.8 at 48.5%, with Gemini 3.5 Flash at 42.6% and GPT-5.5 xhigh at 42.1%. More interesting than the ranking: every model still breaks business rules, and Gemini looked notably strong on objective-per-guardrail-violation and cost efficiency. Open weights remain meaningfully behind, with GLM-5.2 max the best listed open model at 27.8%.
Capability indices are becoming multidimensional: Artificial Analysis also introduced six domain-specific indices—Finance & Accounting, Legal, Healthcare & Medical, Strategy & Ops, Engineering, Economics—to move past single scalar model scores @ArtificialAnlys. The headline was familiar—Claude Fable 5 plus Opus 4.8 fallback leads—but the more useful insight is how sharply rankings reshuffle by domain and how steep the price/performance frontier has become. This aligns with @fchollet, who argued that reporting benchmark scores without cost per task is increasingly meaningless.
Memory and retrieval remain bottlenecks for persistent agents: Two papers got traction here. First, A-TMA tackles “ghost memory,” where stale and current facts are retrieved together in long-running assistants; on the LTP benchmark, adding it to Graphiti reportedly improves conflict accuracy by +0.240 absolute@omarsar0. Second, ReContext is a training-free long-context inference harness that replays model-internal evidence right before answer generation, improving evidence utilization across eight 128K datasets @dair_ai. Combined with BlockSearch for million-token in-context retrieval @dair_ai, the theme is clear: better memory behavior is increasingly being engineered at inference time, not just trained in.
Anthropic’s J-Space / Global Workspace Results
Mechanistic interpretability took center stage: Anthropic released research claiming a global-workspace-like internal structure in Claude, centered on a small subset of activations they call J-space@AnthropicAI, @AnthropicAI. The core claim is not chain-of-thought extraction, but identification of a privileged internal representational substrate that appears available for report, modulation, and flexible reasoning. Anthropic also shipped a Neuronpedia demo for open-weight models @AnthropicAI.
Why researchers cared: Interpretability researchers treated this as stronger evidence for a model “working memory” or internal workspace than prior public work, even if they disagreed with the framing. @NeelNanda5 called it the best evidence yet for a working-memory-like mechanism. @Jack_W_Lindsey argued understanding this privileged space could be key to LLM cognition. Posts also highlighted practical safety angles: the workspace can reportedly surface hidden concepts, detect prompt injections, and expose internal sabotage-related features before they are verbalized @mlpowered, @LiorOnAI, @omarsar0.
But the “consciousness” language was contested: Anthropic’s public framing invited strong pushback. Supporters said the results suggest a functional analog of access consciousness rather than phenomenal consciousness @BorisMPower, while critics argued the company was overclaiming by conflating privileged latent activation with consciousness @AlanCowen. Even some sympathetic takes emphasized the bigger story is a new intervention point for auditing and steering models, not philosophy.
Inference, Serving, and Systems Efficiency
Speculative decoding remains hot infrastructure: @lmsysorg added DSpark to SGLang for confidence-driven, variable-length verification. The pitch is that under high load it avoids verifying every draft token, improving the throughput/latency tradeoff relative to fixed-budget speculative methods; DeepSeek-V4-Pro reportedly reached 383.7 tok/s at batch=1 on B300. Microsoft also discussed prompt-level optimization of GPT-5.5 in the GitHub Copilot harness to improve latency and token efficiency after launch @code, @pierceboggan.
Inference efficiency is increasingly the strategic bottleneck: @jon_durbin argued that inference, not training alone, is now “the whole game,” because every data pipeline, RL loop, and agent runtime ultimately cashes out as test-time compute. That perspective also showed up in lower-level kernel work: Chutes reported major speedups for MiniMax MSA and GatedDeltaNet-2, including ~7x sparse-attention training improvements on RTX Pro 6000 / SM120 and better fused FP8 kernels @jon_durbin.
Infra releases beyond model serving: Cloudflare launched Workers Cache, a regionally tiered cache in front of Worker entrypoints configured via standard HTTP headers @Cloudflare. OpenAI shipped GPT-Realtime-2.1-mini, bringing reasoning and tool use to the mini realtime line at the same price as the prior mini, alongside claimed 25%+ p95 latency reductions from caching improvements @OpenAIDevs, @OpenAIDevs.
World Models, Speech, and Document AI
MIRA is a notable world-model demo: General Intuition and Kyutai, with Epic Games, introduced MIRA, a playable multiplayer world model for Rocket League trained on 10k hours of bot-collected data @gen_intuition. It runs in real time at 20 fps, and posts highlighted a 5B-parameter model running an entire 2v2 match on a single NVIDIA B200, with no explicit physics or rendering engine @TheRundownAI. This was one of the clearest signals that video/world-model work is moving from toy demos toward interactive simulators.
Speech remains highly competitive: AssemblyAI released Universal-3.5 Pro Realtime, a streaming STT model with 4.1% WER on AA-WER Streaming and contextual priming that can be updated mid-call without reconnecting @ArtificialAnlys. On the TTS side, Artificial Analysis said Speechify Simba 3.2 now leads its Speech Arena at 1233 Elo, ahead of Gemini 3.1 Flash TTS, Sonic 3.5, and Inworld Realtime TTS 1.5 Max, while also being the cheapest among top-ranked models @ArtificialAnlys.
Document-context pipelines are becoming multimodal by default: LlamaIndex and LanceDB described a retrieval pipeline for messy PDFs that separates pages, chunks, and extracted assets into linked multimodal tables, reporting 82% any-page-hit@5 and 74% answer accuracy on a labeled ESG-report benchmark @lancedb, @llama_index. This pairs with Jerry Liu’s broader argument for a dedicated “document context layer” for agents @jerryjliu0.
Top tweets (by engagement)
Anthropic’s global workspace paper dominated engagement, with the primary announcement on Claude’s internal workspace/J-space far above everything else @AnthropicAI.
Tencent Hy3 was the biggest pure model-release story, especially among technical accounts discussing open-source competitiveness and deployment @teortaxesTex, @ShunyuYao12.
MIRA’s playable world model was the standout multimodal/system demo @gen_intuition.
Will Depue’s “Stargate for Data” thread was the most substantive strategy post, arguing that data collection—not compute alone—becomes the binding constraint and potential moat for frontier labs @willdepue.
John Carmack’s memory-system thread drew significant technical interest by arguing inference hardware could exploit deterministic access patterns and much cheaper memory tiers than HBM for large-model serving @ID_AA_Carmack.
AI Reddit Recap
/r/LocalLlama + /r/localLLM Recap
1. Large Open-Weight MoE Model Releases
longcat 2.0 (1.6T, ~48B active) weights are now open under MIT license (Activity: 638): LongCat 2.0 weights are now open under the MIT license via announcements from elie and ModelScope, with technical details in the LongCat 2.0 blog post. The model is a very large MoE system with 1.6T total parameters and roughly 48B active parameters per inference; commenters note the released weights occupy about 3.55 TB in BF16 and 2.05 TB in FP8. Commenters emphasized the practical deployment burden from the multi-terabyte weight size, and noted that Meituan—described as China’s Groupon/Uber Eats analogue—reportedly trained it on fully domestic Chinese chips, prompting discussion about the geopolitical/market significance.
Commenters highlighted the scale and deployment footprint of LongCat 2.0: 1.6T total parameters with approximately 48B active parameters, implying a sparse/MoE-style architecture. One user noted the released weights require about 3.55 TB in BF16 and 2.05 TB in FP8, which is important for anyone planning local storage or inference infrastructure.
A technical point raised was that Meituan reportedly trained the model on 100% domestic Chinese chips, which commenters framed as significant for AI hardware supply-chain independence. This is especially notable given Meituan’s role as a major Chinese internet company comparable to a mix of Groupon and Uber Eats rather than a traditional AI lab.
Several users focused on the permissive MIT license and planned benchmarking against frontier open models such as Qwen and DeepSeek. The combination of 1.6T total parameters, only ~48B active parameters, and open weights suggests the model may be practical to compare with other high-end MoE open models if inference tooling supports its architecture efficiently.
One of the highlights of the final day of the AI Engineer World’s Fair was a debate about loops. It nicely captured an argument running through the whole conference: are autonomous software factories viable now, or is the engineering discipline lagging behind the ambition?
Allie Howe from Keycard was the moderator and she opened by asking, “is there or is there not a delta between the hype behind loops and what actually works in practice?”
The pro-loop case was presented by Geoffrey Huntley, creator of the Ralph Loop, and Keycard CEO Ian Livingstone. Huntley opened by saying loops are already here. “It’s inevitable, it’s here to stay,” adding that “I don’t see myself going back to writing code by hand.”
Livingstone said that verifiability is ultimately what it’s about — and you can achieve that with any code, regardless of how it was produced. He also pointed out that loops have always been a core aspect of software development:
“A loop is at the core of ‘I try something, I learn something, I apply something.’ And all we’re really talking about is how quickly we can expedite that process.”
On the skeptical side were Dex Horthy from HumanLayer and Greg Pstrucha from Subroutine. Horthy began by noting that he wasn’t anti-loops. “The basic take here is not whether loops are good or bad,” he said, noting that “Kubernetes is actually built on loops — built on control loops. But they’re deterministic loops.” Horthy’s issue is that “the hype is outrunning the discipline.”
“I haven’t seen proof that we are at a point where we can just step up an abstraction level,” Horthy said, referring to agents controlling the coding. “I actually think we need to step down an abstraction level, if anything.”
Pstrucha was mainly concerned about the economic viability of agentic loops, which he said wasn’t sustainable. You can’t “orchestrate your problems away by buying more tokens,” he said.
“[We’re] kind of like locomotive engineers now. That’s our job: to keep the locomotive on the rails.” - Geoffrey Huntley, loops advocate
Huntley then offered this wonderful analogy for loopmaxxing: “[We’re] kind of like locomotive engineers now. That’s our job: to keep the locomotive on the rails.”
The discussion turned to software factories, the metaphor that has really taken hold of the industry. Horthy worries that when everything is automated in a factory-like agent environment, “you never touch the problem.” So instead, he advises to start small and iterate with agent loops — to “build up intuition” and not try to automate end to end from the start.
Even Huntley recognized some of the dangers in loops. He said that software factories represent where we are headed in the future, but cautioned that it’s not yet solved in the market. “This is frontier thinking,” he said.
At the end of the hour-long debate, Howe polled the audience to ask which side ‘won’. Ironically, this resulted in a human failure: the stage lights were too bright for Howe or any of the debate participants to see how many hands were raised. If only an agent was in charge of dimming the lights.
Anthropic’s next big thing: Claude Tag
Perhaps one example of a company moving to a software factory model is Anthropic. Mike Krieger, one of the co-founders of Instagram back in Web 2.0 and now Head of Labs at Anthropic, was interviewed by swyx in one of the morning sessions.
Krieger talked about Claude Tag, Anthropic’s internal model which the company announced to the world last week. He described Tag as more delegated, asynchronous and proactive than Claude. It perhaps suggests what an early software factory looks like in practice — not agents replacing a team, but multiple people delegating responsibilities to a system like Claude Tag.
Mike Krieger talking with swyx at AIEWF today.
“Most usage is actually much more delegated,” he said regarding his team’s usage of Tag. He gave an example of how they instruct the agents: “Don’t just fix this bug. Now you are responsible for this part of the codebase, and I want you to monitor this feedback channel and proactively take on tasks.”
“That’s really changed how we operate currently,” he continued. “It’s much more this multiplayer, async, proactive way.”
However, he also indicated there are some negative consequences to becoming more automated. He noted that his team is “bottlenecked on reviews” and on the “human ability to fully conceptualize what we’re doing.”
2026 AI Engineer Survey
Back to the current reality for most AI engineers. This morning, Barr Yaron from Amplify presented her annual survey of the industry.
According to Amplify’s data, 95% of respondents now use agents — roughly double last year’s share. Among teams using agents, 89% said those agents could write data, up from 52% the previous year.
“Agents are no longer reading, summarizing, drafting,” Yaron said. “They’re taking actions inside the systems.”
Barr Yaron presenting her AI engineering survey.
The controls, however, remain comparatively primitive. Human approvals and permissions were the two leading safeguards, followed by a scattered collection of task decomposition, retrieval, memory and sandboxing techniques.
“Nobody has settled the control layer for agents,” Yaron said.
Cost is also a concern. Forty percent of respondents said that AI costs regularly limit how ambitiously they use AI, while another 36% said it sometimes does. Token usage is now the second-most monitored production metric, behind quality.
The survey captured the conference’s central contradiction. AI has made experimentation cheaper and enabled teams to produce more software, but 59% of respondents to the Amplify survey fear that today’s AI-generated code is creating long-term liabilities.
Closing keynotes
The final sessions of the conference appropriately took us back to thinking optimistically about AI technology — about building with it. After all, that’s why the AI Engineer World’s Fair exists, and it’s where the fun is!
Theo Browne showcased several software projects he had built, or was still building, with AI. His point was that the scale of what an individual developer can realistically attempt has shifted. “What used to be a startup is now a side project,” he said, while projects he would once have dismissed as “too big” are moving within reach.
Garry Tan, president and CEO of Y Combinator, followed by giving that optimism an organizational form. The fastest-growing founders YC sees, he said, are “not treating AI as autocomplete, they’re treating it as a workforce.”
Garry Tan at AIEWF.
Tan’s closing prescription was: “Build an AI-native company, not a company that just uses AI.”
The debates during the week showed how much engineering remains before the AI-native vision is viable for all. But the closing keynotes offered a reminder of why the engineers who attended this conference are pursuing it: they just want to ride those locomotives!
Andrew Qu is Chief of Software at Vercel, where he works with the CTO across internal engineering, product experimentation and emerging technologies. He has built libraries for MCP, created skills.sh and led the development of eve, Vercel’s framework for building agents.
In this interview with Latent Space, Qu explains why agents represent a new form of software, what Vercel learned from building its own, and why Vercel itself is turning into an agent!
From web applications to agents
Latent Space: What does a Chief of Software do at Vercel?
Andrew Qu: My role is pretty unique. I work with the CTO to ship impact in any way, shape or form. It’s a mix of internal engineering, external experimentation and staying on the frontier by building things.
That means building new libraries and frameworks and showing people how to do things for the first time. I built an MCP library that made it easier to create some of the first MCP servers, and I also built skills.sh to make agent skills easier to discover and use.
Latent Space: How did Vercel evolve from focusing on web development to investing heavily in agents?
Qu: Vercel’s origins were about making it easy for developers to ship websites and web applications. More recently, we’ve seen a shift from people building pages to people building agents.
While building our own agent in v0, our vibe-coding product, we ran into a lot of paper cuts that existing tooling did not solve: switching models or providers, adding fallbacks and making runs resumable.
We turned those solutions into reusable libraries that could support v0 and also help customers build their own agents. Over time, we accumulated a set of primitives and decided to assemble them more cohesively. That became eve.
Why eve became necessary
Latent Space: How did you reach the point where Vercel needed a dedicated agent framework?
Qu: About a year ago, I started working toward putting an agent on every desk inside Vercel. That led me to build a successful data agent, and along the way a number of best practices emerged: filesystem agents, skills, compaction and subagents.
These were all things I wished had come out of the box. Eventually, we asked: what if there were a prescriptive way to do this, so other developers did not have to go through the same exploration? That is where eve came from.
Latent Space: Are agents simply another kind of application, or a genuinely new form of software?
Qu: I think agents are a new type of software. They are not as predictable as web applications. The infrastructure can look similar, but the interaction, interface and outputs are much more dynamic.
That changes how you build them. You need different primitives for context, tools, resumability and long-running work.
Latent Space: What kinds of problems are particularly well suited to agents?
Qu: We see a lot of business agents. Internally at Vercel, we use them for repetitive work ranging from a first pass at legal contract redlining, to marketing retrospectives and identifying people to contact, to writing queries against our data stores.
A good candidate is often a repetitive task that still requires some reasoning. It is not just fixed automation, because the system has to interpret the situation and decide what to do.
Building effective agents
Latent Space: When should an agent work autonomously, and when should a human remain in the loop?
Qu: I don’t think the future is all autonomous loops, and I don’t think it is all human-in-the-loop. It is about choosing a feedback cycle that fits the task.
If the task is well defined and you know what the final output should look like, it can be reasonable to let a loop continue until it is done. For more careful or surgical engineering work, you should check back in and make sure you are steering the model correctly.
Latent Space: Your approach evolved through prompting, bespoke tools, coding-agent harnesses, filesystem agents and skills. What was the main lesson?
Qu: We are still figuring out what makes an agent productive. Along the way, we have been collecting these primitives and bringing them together in eve.
There will be more to add as best practices emerge. A year ago, we did not know sandboxes would become so important, or how much demand there would be for secure code execution and long-running jobs. As we learn more from production, there will be much more to build.
Latent Space: Is Vercel creating an end-to-end agent platform comparable to the one it built for web development?
Qu: Yes and no. We value partners that provide specialized parts of the agent lifecycle, but we also want it to be very easy for developers to get started.
If you deploy eve to Vercel, you get observability and evaluations out of the box. We want to make that experience more comprehensive while making it easy to integrate with partners rather than owning every component.
Skills and current knowledge
Latent Space: Why have skills become so important?
Qu: Skills are useful as portable, on-demand knowledge. Models often contain outdated information. For example, they still sometimes recommend Vercel Postgres, even though we deprecated it years ago in favor of our marketplace.
A skill can tell the agent that Vercel Postgres is deprecated and steer it toward the current approach. Until companies can audit and update every old piece of content, skills provide a way to forward-correct the model.
I would recommend publishing skills for the latest version of your product. But companies should also audit their existing content, identify what is outdated and update it or add clear notes.
An agent-readable web
Latent Space: How will websites evolve as more traffic comes from agents?
Qu: We have published reports showing bot traffic rising while human traffic is stagnant or declining, even as impressions increase, because agents and bots are hitting websites more frequently.
The future of the web is therefore to be as accessible to bots and agents as possible, so they can learn about your product and use it successfully.
At Vercel, we already detect when an agent makes a request and serve Markdown directly. Instead of forcing it to process HTML designed for a visual browser, we provide a format that is easier to read.
Latent Space: Does that mean one experience for humans and another for agents?
Qu: I think so. Humans may continue to receive the visual site, while agents receive a more structured, machine-readable representation. We are already doing that today.
What comes next
Latent Space: What problems are you most interested in solving next?
Qu: One of the things at the top of my agenda is multiplayer agent development. Whenever a team collaborates, people struggle to share context.
I may have techniques for getting a front-end interface right on the first attempt, but another person may not know them. I am interested in how we can share that context between teammates and allow them to contribute to it.
Latent Space: Will agents become a separate application category, or a standard capability built into most software?
Qu: It depends on who you are and what you are building. For Vercel, Vercel itself is becoming an agent. We have an agent on the website, in Slack and in the dashboard that can do things on your behalf.
Other companies will ship agents as standalone products. For us, agents are tightly coupled to everything we build. We want the entire platform to be agent-friendly — and, in many ways, to make the platform itself an agent.
Adobe Principal Scientist Carlos Sanchez at AIEWF.
For as long as I can remember (and I managed websites in the dot-com period), “personalization” has been a holy grail for websites. But up till now, that’s typically meant selecting from a predefined set of options. A retailer might recommend an item based on a previous purchase, or place a visitor into one of several audience segments — that’s been the extent of personalization.
Adobe Principal Scientist Carlos Sanchez is exploring a more radical possibility: what if the website itself could be assembled around the needs of each visitor?
At the AI Engineer World’s Fair in San Francisco, Sanchez demonstrated what Adobe calls an “agentic site” — a web experience that interprets a visitor’s intent, retrieves relevant material from the company’s existing content, and composes a personalized page in real time.
Adobe calls this approach an “audience of one.” Sanchez’s larger point was that the technology is no longer hypothetical.
“Many people don’t even think it’s possible to generate a web page on the fly,” he told Latent Space after his session. “People think it is future-looking. No, you can do this. It’s not the future, it’s the present now.”
From personalized components to personalized pages
During his presentation, Sanchez demonstrated a site that used the visitor’s browsing behavior and search queries as signals. The system grouped those signals into an intent category — such as exploring, researching or preparing to purchase — and then used an LLM to assemble a page suited to that intent.
In one example, a visitor interested in camping received a version of a coffee-machine site whose copy, product selection and supporting content had been reorganized around making coffee outdoors.
Sanchez also showed a more open-ended interface in which someone could enter a query such as “Europe AI conferences” and receive a page composed specifically around that request.
“We call this ‘audience of one,’ because the idea is to personalize the site in real time based on the user accessing it and what the user is doing,” Sanchez said.
The idea is that the site’s existing content is the grounding corpus. Adobe’s system retrieves from that material rather than asking an LLM model to invent an entire experience from scratch.
For AI engineers, one potential constraint is latency. In his session, Sanchez said that Adobe evaluates models not only for accuracy, but also for speed: “We don’t want the site generation to take more than one or two seconds.”
Sanchez says the economics are already becoming plausible. He estimated the current inference cost at “one to two cents per page.”
“But our point is also this is only going to get cheaper,” he said. “This is where we are today. In six months, who knows where we’re going to be.”
AI makes it easier to build, but harder to choose
Adobe has not yet broadly deployed these experiences on production customer sites. Sanchez said the company is presenting the concept to customers and looking for organizations willing to experiment.
Commerce is an obvious initial use case, because personalization can be connected directly to conversion. But the opportunity is not necessarily limited to retail. “It could work for other things — anything that needs more conversion and has a big matrix of user types or personas,” he told me.
Still, Sanchez acknowledged that he’s unsure if agentic sites will become a widespread reality.
“With AI, it’s very easy to build things, but it’s hard to know what to build,” he said. “We build things and then we find the customers.”
It’s not just Adobe feeling the uncertainty around its ‘audience of one’ concept. Website owners are currently evaluating all kinds of AI functionality: chat interfaces, structured content (like WebMCP), generative UI, personal agents, and more. Not to mention trying to find ways to bring users in from third-party AI platforms.
“I think it’s a combination of all these crazy different ways,” Sanchez said. “You are in a chat, I want to show UI, I want to get you to buy something. Then you’re in a site, I want to steer you this other way. Maybe you’re in an OpenAI chat and I want to bring you into my site. Everybody’s trying to figure this out on the marketing side.”
A web built for humans — and agents
Of course, websites in 2026 and beyond won’t just be personalized for human visitors.
As personal agents become more capable, a user may delegate some purchases or research tasks entirely. The agent could arrive carrying a much richer expression of the user’s preferences than the destination site could infer from cookies or recent browsing behavior.
Sanchez expects websites to evolve for both kinds of visitor. “Whether it’s going to be two versions [of a website] or not, that may be blurry,” he said. “But obviously, you’re going to have to target both.”
Also, not every transaction will work the same way. A personal agent might autonomously reorder toilet paper, while a person buying a jacket may still want to inspect the product and make the final choice through a visual interface.
That means websites will need to support different levels of delegation and involvement, rather than treating “agentic commerce” as a single interaction pattern.
Technologies such as WebMCP could allow a site to expose structured tools directly to an agent, while MCP Apps and other generative interfaces could bring interactive product experiences into the user’s chat environment. An A2A backend might allow agents to interact without traversing the conventional visual site at all.
It might end up being one site with both visual components and agent-accessible tools — two distinct experiences — or perhaps a human-facing website paired with an agent-to-agent service.
“That’s still what everybody’s trying to figure out,” Sanchez said. “But there’s going to be agentic targeting, for sure.”
Whither websites?
Whether websites survive the AI era at all is another big question we’re all grappling with.
What I gleaned from Sanchez at AIEWF was that the traditional website is unlikely to disappear completely, but its role will surely change.
Rather than being a fixed collection of pages that every visitor navigates, a “website” could become a governed content and interaction system that assembles an appropriate interface on demand. At least, that’s the future that Adobe is actively exploring.
Impeccable’s Paul Bakaus at the AI Engineer World’s Fair.
Paul Bakaus thinks the emerging discipline of “skill engineering” can make AI agents more capable — but he absolutely does not want to remove people from the creative process. He chats to Latent Space about his approach to design in the AI age.
Bakaus is the creator of Impeccable, an open-source design skills system that gives coding agents a vocabulary for improving interfaces. Instead of asking an agent to redesign an entire website in one shot, users can tell it to make a section “bolder,” “quieter,” “denser,” or more polished.
Behind those apparently simple commands is a larger argument about how AI products should be built. Agents need more than instructions, Bakaus said: they need domain knowledge, context and carefully defined ways for humans to steer the result.
“The point is to give you a way to steer what you want to end up with,” he said during a session at the AI Engineer World’s Fair. “It’s never going to be a tool for one-shot design. That’s not the intent.”
The emerging craft of skill engineering
Impeccable began as a relatively simple extension of Anthropic’s frontend design skill. As its audience grew, Bakaus expanded it into a more complex system with multiple components and workflows.
That process led him to start thinking of skill engineering as a discipline in its own right. His workshop at the conference explored what he called the “dark arts” of building skills.
“One of the interesting topics was that most skills — [and] most models — are not very creative,” Bakaus told me. “They converge in one direction, and if everybody uses the same skill to do frontend design work or something like that, everything ends up looking the same.”
Skill engineers must also account for differences between agent harnesses and models. Codex and Claude, for example, do not necessarily handle subagents or permissions in the same way. A skill intended to run across Claude Code, Cursor, GitHub Copilot and Codex cannot assume they all provide identical capabilities.
Bakaus has also experimented with routing inside a skill, allowing it to combine several capabilities and direct a task toward the relevant instructions. He compared this to a mixture-of-experts model, with routing used both to conserve tokens and improve effectiveness.
Giving agents a design vocabulary
Impeccable’s core innovation is to take terms familiar to designers and give them a more precise operational meaning for an agent.
An unassisted model asked to make a page “bolder” may add gradients, neon effects or glass-like surfaces. Impeccable instead defines boldness through concepts such as hierarchy, scale and decisive typography — changes that attract attention without necessarily breaking the existing design system.
“An adjective with nothing behind it is just a nice apostrophe,” Bakaus said. “You really have to tell the agent what you mean.”
He described these terms as words that have been “imbued with meaning.” The model already has some conception of what words such as “bold” or “quiet” mean, but the skill translates them into a specific professional domain.
This is the key, because experts often possess a vocabulary that non-experts do not. Bakaus said he had observed large differences between the work produced by a designer and an engineer using the same model, simply because the designer knew how to articulate the desired result.
“I’ve been trying to put that language — basically compress it into a skill and into a system — to be able to express yourselves better,” he said.
However, he does not believe every part of design can be controlled from this level of abstraction. Directly manipulating spacing may still be the fastest option for a small adjustment, while open-ended prompting can be useful during initial exploration.
The objective is not to replace every tool with an agent, he insisted. It is to determine “the exact level of control” and insert the person at the point where their judgment is most valuable.
Designers and engineers move up the stack
Bakaus sees the boundaries between design, engineering and product management becoming less distinct.
“Designers are moving into code, engineers are moving into design, and vice versa,” he said. “These worlds are all colliding.”
That shift will be uncomfortable for people whose work primarily consists of translating an existing artifact into another form. Engineers who mainly turn Figma designs into code face growing automation, while designers whose contribution is limited to making an existing interface look competent face similar pressure.
“Designers all have to move one layer up the stack to think more about the what,” he said. “I think the role of the product manager and designer is actually converging.”
At the same time, designers are moving closer to implementation — into code. Bakaus initially expected Impeccable to appeal mostly to engineers and assumed professional designers might resent that. Instead, he estimates that designers now make up at least half of its audience.
“So rather than moving directly into code and, you know, having no help,” Bakaus said about designers, “they use Impeccable as a bridge, because it communicates the way they communicate. And that was not obvious to me when I first built it.”
Impeccable also has a live mode that combines visual selection with an underlying coding agent. A user can select a section inside a development environment and request several alternative layouts or (for example) ask for a bolder or quieter treatment. The system operates within the project’s existing code and design system rather than exporting an isolated mockup from a third-party design tool.
Bakaus described this as a potential “design harness” at the intersection of chat and direct visual manipulation.
There will be no auto mode
The AI industry often treats complete automation as the natural endpoint of product development. Bakaus rejects that premise.
He sees two dominant camps: people trying to preserve the traditional Figma-centered workflow, and on the other side advocates of “loopmaxxing” who want agents to work with as little human intervention as possible.
“The truth is somewhere in the middle,” he said.
His preferred model is for AI to produce the first 80% quickly: the competent layout and basic implementation that would otherwise consume a lot of time. The person then owns the final 20%, where taste, context and a distinctive point of view enter the product. This is a key part of Bakaus’s design philosophy in the agentic era.
“People need purpose, and they want to play a role in whatever they create,” Bakaus said. “When you work with the agent, then you feel more ownership of the product.”
Users regularly ask him to add an automatic mode to Impeccable so that the system chooses the commands itself. He has no intention of doing so.
“There is no auto,” he said, “and there will be no auto.”
Asked about the language of software factories and other visions that appear to remove people from engineering altogether, his response was unambiguous.
Coding Models, Agent Harnesses, and the Fable 5 Re-launch
Anthropic re-enabled Claude Fable 5, but with visible safety fallbacks: After a day of pent-up demand, @claudeai announced Fable 5 is back, alongside a clarifying note that updated cybersecurity safeguards may route some requests to Opus 4.8, with biology/chemistry classifiers still overly broad for now @claudeai. The relaunch immediately propagated into tooling: Cursor says Fable 5 leads its evals but is the most expensive per task@cursor_ai; Devin added it across Cloud/Desktop/CLI @cognition; Perplexity restored it as an orchestrator model @perplexity_ai. Anthropic also reset rate limits for users once the model was live again @ClaudeDevs.
The interesting story was less “model is back” than “how people are adapting to frontier-model constraints”: Multiple builders converged on multi-model orchestration rather than single-model dependence. @theo described using Fable only for higher-value reasoning/planning while delegating implementation, verification, and computer-use work to other models; he reports a substantial improvement in end-to-end PR yield @theo. Similar views came from @omarsar0, who argued teams should design model-combination strategies rather than build around one frontier model, and from @MParakhin, who pushed back on “simple-task pre-classifiers,” arguing that reliable routing often requires solving the task first. On the benchmark side, @kimmonismus highlighted Fable 5’s 16.10% on the Remote Labor Index, while @ArtificialAnlys reported Sonnet 5 ranking second on AA-Briefcase but with much higher turn counts and weaker cost-performance tradeoffs at lower effort settings.
Open Models, Chinese Labs, and the Expanding Coding Stack Around GLM-5.2
Z.ai is building product surface area around GLM-5.2, not just shipping a checkpoint: The most concrete launch was ZCode, the official dev environment for GLM-5.2, with BYOK support, cross-platform availability, and a quota boost for coding-plan subscribers @Zai_org. Commentary from @kimmonismus framed it as an AI-native coding IDE optimized for GLM workflows and long-running autonomous tasks. The surrounding ecosystem is moving quickly too: LangChain published guides for using GLM-5.2 in coding flows @LangChain, and @hwchase17 explicitly called out developers turning to GLM-5.2 as a daily driver.
Benchmarks suggest open coding models are closing specific gaps even if not leading overall frontier performance: @mercor_ai reported GLM 5.2 as the first open model to lead a category on APEX-SWE, posting 55.3% Pass@1 on Integration, and ranking as the best open model tested overall there; Kimi K2.7 followed closely. That complements @scaling01, who cautioned against overclaiming that GLM has surpassed top Western frontier models while still acknowledging a rapidly shrinking coding gap.
Inference work around open models is becoming a meaningful part of the story: @vllm_project landed native DSpark speculative decoding support in vLLM for DeepSeek models, reporting around 250 tok/s on 8×B300 with improved acceptance over MTP, and @mgoin_ released a GLM-5.2 DSpark preview claiming roughly 1.5× faster decode. Separately, @jon_durbin reported an in-house dflash drafter on Qwen3-32B yielding ~50% higher throughput on the same hardware.
Agent Infrastructure: Memory, Wikis, Skill Composition, and Structured Workflows
“Wiki memory” is emerging as a practical design pattern for agents: @sydneyrunkle argued for wiki-structured memory as a simple, extensible substrate, and that idea rapidly turned into product releases. LangChain launched OpenWiki, a tool to generate and maintain agent-consumable codebase docs with openwiki --init@BraceSproul, @LangChain. The motivation is consistent across posts: agents repeatedly lose working context between threads and need a maintained, inspectable knowledge layer rather than raw logs @caspar_br.
Memory systems are shifting from retrieval-only to reconciliation and maintenance: Weaviate’s Engram pitch is representative here: candidate memories are extracted, transformed against existing memory, and only then committed, so contradictions are resolved once rather than at every query @PrajjwalYd. @bpalit extends the same argument to enterprise settings, where agent memory must be governed, permission-aware, and shared—not just a folder of markdown files.
Structured composition is replacing naive “give the model all the tools” approaches: @omarsar0 highlighted SkillComposer, which treats skill selection as a joint autoregressive composition problem and reports +23.1pp / +18.2pp gains on SkillsBench over no-skill baselines. On the framework side, Deep Agents added support for recursive language model workflows@sydneyrunkle, and @hwchase17 connected dynamic subagents to patterns like Agentic MapReduce. This general direction—more explicit workflow structure, fan-out/fan-in patterns, and code-enforced orchestration—showed up repeatedly across products and benchmarks.
Security, Evaluation, and Agentic MapReduce
Cognition’s Devin Security Swarm is one of the clearer examples of agent architecture specializing around a real enterprise workflow: The system uses Agentic MapReduce to fan out bounded agents across a codebase, aggregate findings, and validate exploitability before surfacing confirmed vulnerabilities @cognition. Cognition claims this is both more cost-effective and more accurate than alternatives, and says a Fortune 500 pilot found and fixed over a thousand vulnerabilities in production repos @walden_yan. The broader reaction from builders like @jakejluo and @levie was that this pattern will generalize to large-scale document, code, and knowledge workflows.
AI-agent evaluation is quickly becoming its own subfield: @random_walker noted several new papers advancing agent evaluation and described it as a distinct discipline. Practical examples included Agent Arena re-enabling Fable 5 in agent mode @arena, AA-AgentPerf for agents-per-megawatt system benchmarking @ArtificialAnlys, and WorldModelGym, which evaluates whether a world model actually supports good decision-making rather than just producing plausible simulations @RekaAILabs.
There is also a push toward better reporting pipelines for AI failures: FLARE-AI, launched with a coalition spanning cyber and AI safety researchers, aims to standardize flaw and incident reporting so issues can be routed to the right developers and registries instead of disappearing into siloed intake forms @ClementDelangue, @ShayneRedford.
Systems, Inference, and Architecture Work Worth Watching
NVIDIA’s TwoTower result stands out as a concrete speed/quality tradeoff on generation architecture: @NVIDIAAI introduced Nemotron-Labs-TwoTower, adapting a 30B model into a diffusion-style language model that writes tokens in parallel via a two-copy setup. Claimed result: 2.42× faster generation while preserving 98.7% of the original model’s quality. @LiorOnAI summarized the trick as reusing a frozen context model plus a trained writer model, avoiding full retraining from scratch.
On-device and browser inference continue to benefit from agentic optimization and specialized runtimes: @googlegemma highlighted WebGPU Gemma 4 running at 255 tok/s on M4, attributed to kernels written with Fable 5. @andimarafioti demoed a fully open-source realtime voice stack around Gemma 4 31B with Cerebras inference, aiming as a drop-in alternative to OpenAI’s realtime API. At the kernel level, Hugging Face’s kernels library now exposes MiniMax’s MSA kernel@RisingSayak, and Triton-on-Mac drew interest as well @QuixiAI.
Architecture research beyond vanilla LLM scaling also surfaced: @gklambauer pointed to AdaJEPA, a LeCun-led world-model approach with test-time adaptation via latent-state prediction error; @LiorOnAI summarized NEO as learning reusable causal “programs” rather than only next-frame prediction; and @ziv_ravid highlighted “training in imagination” as an active paradigm rather than just speculation.
“You can’t one-shot design.” Paul Bakaus at AIEWF today.
Wednesday was autoresearch day on the AI Engineer World’s Fair main stage.
Autoresearch is — you guessed it — a kind of loop. Introspection co-founder Roland Gavrilescu explained it best in an interview with Latent Space this morning. He said autoresearch “allows you to build loops in which agents help maintain the system itself.” He called it an “outer loop” that “studies and maintains” the primary, inner loop.
While autoresearch was not specifically mentioned by Anthropic’s Thariq Shihipar, who works on Claude Code, his keynote reflected the same idea of continuous discovery and adaptation. “The models are grown, not developed,” he said. “We sort of figure out and learn with the model as we use it.”
Anthropic’s Thariq Shihipar at AIEWF.
Former Google engineering leader Addy Osmani also spoke about loops, but his framing differed sharply from Gavrilescu’s.
Where autoresearch puts agents into the loop that studies and maintains the system, Osmani argued that the outer loop should remain human. “Agents can run much more of the inner execution loop,” he said. “But that outer loop is still engineering.” His summary was even more direct: “That inner loop is capability. The outer loop is agency.”
Addy Osmani’s Agency Ladder
Human agency is still important
This tension between what agents should do and what human engineers should retain was a recurring theme throughout the day. I also detected some pushback against the “software factory” framing that dominated Tuesday. This tweet from Notion’s Geoffrey Litt summed it up:
Litt drew a large audience in the Design Engineering track today, where he spoke about “how and why humans need to understand our code.” Lily Zhang tweeted the key takeaway: “The future will be very polarized: those who understand will keep having the next big idea. Those who delegate understanding will be replaced by the agent.”
Later, Litt posted a thread expanding on his argument. Although he acknowledged that agents are increasingly capable of handling more of the process, humans still need to understand what is happening. “You can learn what the agent is doing to make sure you can be an active participant in the creative process,” he wrote.
Another AIEWF speaker seeking to reinforce human agency was Paul Bakaus, who ran a session about his new design tool, Impeccable. Bakaus rejected both extremes: continuing to design entirely by hand, or “loop-maxing” toward a fully hands-off process. “The truth is somewhere in the middle,” he told me after his session.
His goal is to let agents handle the laborious first 80% of the work, before bringing the human back in “for the last 20% to make it a unique thing — to really put in your taste, your point of view.”
“There is no auto, and there will be no auto.” - Paul Bakaus, Impeccable
For Bakaus, that is not simply a temporary limitation of today’s models. It is also about authorship and accepting responsibility for your work. “People need purpose, and they want to play a role in whatever they create,” he said. “When you work with the agent, then you feel more ownership of the product.”
This philosophy is built into Impeccable itself. “There is no auto, and there will be no auto,” Bakaus told the audience. What he means is that his product will never “one-shot” a solution — the user must be involved in the design process. “The point is to give you a way to steer what you want to end up with,” he added.
Generative media
The same question surfaced during a panel on generative media. As image, video and audio models become more capable, the issue is not merely what they can generate, but whose judgment shapes the result.
Nicole Brichtova, who works on Google’s generative media products, including Nano Banana, drew a distinction between average preference and cultivated expertise. “Somebody who has honed a craft has a very different level of expertise,” she said. “You see things that the average human will not.”
This matters because every model has a default aesthetic, whether its creators acknowledge it or not. “It ends up being us,” Brichtova said. “It ends up being the modeling teams.” She suggested that model developers may need to work more closely with people who have “a really creative point of view” — effectively bringing the art director back into the loop.
Shane Gu made the same point more broadly. Even as models become better at generating and refining their own outputs, he argued, humans must retain the sensitivity to notice what is wrong, generic or insufficient.
“Maybe right now the AI can do a lot of all the promptings and it’s sufficient, but if it’s like that, never be satisfied [that] AI is generating the content. Always find your sensitivity.”
Agentic sites
Even the web itself — the ultimate human information network — is grappling with how much automation to use.
In his session this afternoon on “agentic sites,” Adobe principal scientist Carlos Sanchez demonstrated websites that assemble and personalize pages in real time based on a visitor’s intent. He presented this transition as increasingly inevitable: “This is now possible. It’s only going to get better. It’s only going to get cheaper. It’s only going to get faster.”
But Sanchez also sounded a note of caution. “With AI, it’s very easy to build things, but it’s hard to know what to build,” he told me afterwards. That becomes especially important when an agent is generating experiences on behalf of a brand. “You cannot just generate the whole site,” he said, because the result may stray outside the brand’s guidelines.
That brings the discussion back to autoresearch. Agents may increasingly be able to observe, evaluate and improve other agents, but humans must still define the goals, judge the results, and take responsibility for what the loop produces.
As impressive as agentic technology is now, and as compelling an idea as automated “software factories” might be, you still need humans in the loop.
We’ve heard a lot about loops at the AI Engineer World’s Fair this week. Another buzzword is autoresearch, which involves building an “outer loop” where agents help maintain and improve the primary system, using feedback signals, evals and human input to make progress over time.
At least, that was the framing of Roland Gavrilescu, co-founder and CEO of Introspection — a new company building infrastructure for deploying these self-improving systems. Before starting the company, Gavrilescu worked on agent infrastructure and cloud agents at xAI, where he met his co-founder, Julian Bright.
Ahead of his “Autoresearch in the Wild” session at the AI Engineer World’s Fair today, I spoke with Gavrilescu about the shift from agent harnesses to feedback loops, the role of the open-source Pi framework, and why autonomous software factories must first learn from humans.
From xAI to Introspection
Latent Space: How did your new company, Introspection, come about?
Roland Gavrilescu: Last year, I was at xAI, where I met my co-founder. We were working on agent infrastructure and cloud agents, and we felt there was a new agent form factor that needed to be explored further. xAI was not necessarily the environment where we could focus completely on that.
We decided to leave and ask what a company designed around this new form factor might look like. We were interested in what made companies such as Cursor and Cognition successful, and how we could turn some of those ideas into a product that others could use.
That became the basis for Introspection.
Autoresearch allows you to build loops in which agents help maintain the system itself. The challenge is designing the right signals and feedback mechanisms so agents can improve the system, make architectural decisions and move in the right direction without constantly being bottlenecked by humans.
The loop becomes the product
Latent Space: Your session is titled “Autoresearch in the Wild” — what will it cover?
Gavrilescu: We have heard a lot about what autoresearch can do for improving experiments, but we wanted to talk about what these loops look like in production.
We are presenting three patterns that we think form the basis of a new blueprint.
The first is that the loop is the product. We have moved from focusing on models, to harnesses, and now to loops. The key question is whether you can define the right feedback mechanisms so agents can take on more work without generating more slop.
The second pattern concerns what the loop generates and how you track it over time. We are proposing a concept called an agent recipe.
We moved from agent tools to agent skills. Recipes are a larger container that brings together the components needed to encode human expertise: evals, judges, signal processing and the information that feeds back into the loop.
The goal is to create a portable format that agents can iterate on, almost like a research laboratory, but in a provider-agnostic way.
The third pattern is about what we optimize for. How can the system become both better and cheaper over time?
Companies such as Cursor and Cognition have shown that these products can work. The next stage is making them more accessible, faster and cheaper, and gradually distilling the capabilities of frontier models into systems that you own and that are customized for your environment.
Agent recipes
Latent Space: Can you explain more about what an agent recipe is…
Gavrilescu: It’s like a description of the ingredients you need and how they evolve.
The idea comes partly from data recipes used in model post-training. A data recipe describes how much data from different domains should be baked into a model.
Agent recipes are similar. A recipe might describe how your harness works with different models, the evals you use, the judges you have created, the human expertise you have captured and the failures that led to new evals.
Imagine that tomorrow you suddenly gained access to the Devin codebase. The code alone would not necessarily be that helpful if you could not see how the team arrived at the current version. You would want to understand the failures, mistakes and decisions that informed it.
A recipe captures that process. You begin with a baseline and then record how each signal produced a new judge, embedded new human expertise or led you to introduce a different model.
The inner loop and the outer loop
Latent Space: Does autoresearch mean orchestrating multiple agents, or can it involve one agent repeatedly working and verifying its results?
Gavrilescu: You can think of the system as having an inner loop and an outer loop.
The inner loop is the primary system interacting with users and performing the work. Autoresearch is more concerned with the outer loop: another system that studies and maintains the primary system.
The question is how to design that outer loop so it makes progress on the right problems without consuming an unreasonable number of tokens while deciding what to do.
Pi as the Linux of agent harnesses
Latent Space: You have compared Pi to Linux. In that analogy, is Introspection something like Red Hat?
Gavrilescu: Pi is like the Linux of agent harnesses. Linux has distributions such as Ubuntu, but the underlying system is designed to be extended. Pi is similar: it was never intended to be run as an unchanged, vanilla product. Pi separates the agent loop from its extensions and configuration, which makes the agent portable. You can spin up several different agents by loading different files into the runtime.
We saw an opportunity to combine that extensibility with recipes and open-source building blocks that can evolve for each customer while remaining portable and easy to deploy.
Making loops reliable in production
Latent Space: Reliability and the messy reality of agent loops have been recurring themes at the conference. How does Introspection address those problems?
Gavrilescu: The product is designed around the point at which you are ready to move into production.
You need to know what infrastructure is required to make the loops work, keep costs under control and maintain security. The managed infrastructure covers what is necessary for these systems to operate in production.
A major part of our focus is bringing the kind of infrastructure available inside frontier AI laboratories to a product that other companies can deploy.
Humans remain part of the system
Latent Space: What about the human in the loop?
Gavrilescu: These loops are designed with humans in the loop because you need the right signals as the system makes progress.
The human can effectively become a tool and a source of signals. Agents can be trained to ask people questions through an “ask a human” tool.
During its first few loops, an agent may rely heavily on asking questions and learning what a human would do. Over time, it accumulates those preferences and can become increasingly autonomous.
It is similar to an employee joining a new company. Initially, that employee asks a lot of questions. As they learn how the organization works, they can make more decisions independently.
Taking agent infrastructure into vertical markets
Latent Space: So what kinds of use cases are you seeing?
Gavrilescu: We are concentrating on vertical agents.
Coding agents are clearly working, and we have seen a number of companies succeed in that area. The next question is how to deploy agents in vertical and non-coding domains.
Companies in those markets are asking how they can do this securely without becoming dependent on a single provider. They want the deployment to belong to them, they want to retain ownership of their data, and they do not want to be locked into OpenAI or Anthropic. Introspection is intended to provide infrastructure that addresses those requirements using open-source building blocks.
Frontier AI labs have developed sophisticated internal agent technology. We want to bring similar capabilities into vertical SaaS and services businesses.
Why the work happens in Git
Latent Space: Is Introspection mainly intended for developers, or will product managers and other business users work with it?
Gavrilescu: We are initially focusing on software engineers in vertical SaaS companies.
We want the environment to be agent-friendly, meaning agents can work inside their own repositories and codebases. Everything is Git-based, and Git becomes the audit log that you maintain over time.
In the future, there will be interfaces that enable product managers and others to participate. But we are already seeing product managers move closer to code.
We think the right initial form factor is a human-to-agent interface in which the actual work and its history live in Git.
From orchestras to software factories
Latent Space: Does Introspection fit within the broader idea of software factories?
Gavrilescu: Yes. Designing the loops is essentially designing the factory. The remaining question is how much autonomy the factory should have.
There has also been discussion about “orchestras, not factories.” That distinction is really about the level of autonomy.
An orchestra might retain a human conductor who controls how the loops operate. A factory implies something more fully autonomous.
But you should build toward the factory rather than assume you can create a completely autonomous factory on the first day. Models do not initially possess all the context or understand every decision people inside an organization make. You cannot simply capture all of that knowledge in a Markdown file.
The right approach is to design the human as a core component of the factory. The early system should extract tacit knowledge and workflows from people over time, rather than attempting to automate everything immediately.
How to start with autoresearch
Latent Space: What would you recommend to engineers who want to experiment with autoresearch?
Gavrilescu: The first step is to invest in your signals. What are the things you actually want agents to respond to?
Product feedback is a good example. Not all feedback carries the same value, and you cannot respond to every individual data point. You need a mechanism for filtering the signals and identifying which ones an agent should act on.
The second requirement is control over cost. You do not want to wake up to an unexpected thousand-dollar bill because an agent has been running an inefficient loop.
The third is to follow the research. Look at the kinds of harnesses models are being trained to use and remain close to those patterns. Study how research labs use data recipes and consider how those ideas can be applied to your own product.
The broader goal is to turn your product organization into a miniature research lab, with agents acting as miniature researchers.
Pauline Brunet, VP of Forward Deployed Engineering at Cursor, at AIEWF.
Forward deployed engineering has quickly become one of the most prominent roles in enterprise AI. Sitting somewhere between software engineering, product development and customer implementation, forward deployed engineers [FDEs] work directly with organizations to implement AI capabilities.
At Cursor, the role is especially ambitious. Pauline Brunet, the company’s VP of Forward Deployed Engineering, is building a team that works with organizations to implement agents across the entire software development lifecycle.
In an interview with Latent Space at the AI Engineer World’s Fair, Brunet discussed Cursor’s vision of an “AI software factory,” the challenge of expanding agent adoption beyond individual enthusiasts, and what engineers need to demonstrate if they want to move into forward-deployed work.
What forward deployed engineering means at Cursor
Latent Space: To begin with, how do you define forward deployed engineering?
Pauline Brunet: Forward deployed engineering depends on the business, the product, and the customer. You have to consider how configurable the application is. Is it something customers can use out of the box, or are you deploying something complex and highly configurable?
You also have to consider where customers are in their journey.
I don’t think of forward deployed engineering as a team that supports a traditional, out-of-the-box deployment. I think of it as a team that goes on-site, works inside a customer’s systems and tools, and deploys applications or platforms that help solve challenges at scale.
Those deployments are highly configurable and customized around the customer’s workflows, processes, systems, and tools.
Latent Space: Cursor’s customers are predominantly engineers. How does the FDE role apply to the way they use the product?
Brunet: Cursor is an AI coding platform and coding assistant. We work with people on AI-assisted coding, synchronous and asynchronous agents, and ultimately the idea of an AI software factory.
Today, we work with customers across many industries, including financial services, telecommunications, software development, technology, and semiconductors.
We help transformation leaders, IT leaders, and CTO organizations create an AI software factory across their operations. That includes how they plan and design software, how they write code, how they test and review it, and how they deploy and maintain applications at scale. So, very focused on the software development lifecycle from start to finish.
Building Cursor’s FDE team
Latent Space: How large is Cursor’s FDE team?
Brunet: We’re growing rapidly. Our goal is to grow the team tenfold by the end of December.
Latent Space: Are your current FDE employees primarily engineers, or does the team also include product specialists?
Brunet: They are all engineers. We hire software engineers with at least five years of experience and extensive customer-facing experience.
These are people who have developed and shipped code in production. They have built and designed systems, and they can make trade-off decisions and evaluate which systems or technologies should be used.
They also need customer-facing experience. We have people who previously worked at companies including Spotify, Rippling, and Palantir, and who have deployed production systems for customers.
From coding assistants to software factories
Latent Space: You mentioned the term “software factory,” which has begun appearing more frequently in the industry. What does that term mean to Cursor?
Brunet: For Cursor, it is about the software development lifecycle from start to finish: how you plan, design, write, review, test, and deploy code.
Today, those stages are often handled by different teams. You might have a design team, a development team, and a product manager working alongside them. Each group may be optimizing its own work with AI-assisted coding, but the process remains siloed.
We want to help customers across the entire lifecycle. You should be able to say, “Here is the feature I want to develop,” and then have long-running agents work with you across every step. That could include creating the plan and product requirements document, producing a demonstration of what the feature might look like, writing and testing the code, putting it into production, and maintaining it.
Issues and product feedback should also feed back into that same lifecycle. For us, a software factory means long-running agents helping people throughout that entire process.
Latent Space: So it is broader than agent orchestration alone?
Brunet: Correct. Exactly.
Moving beyond individual AI adopters
Latent Space: What problems are enterprises encountering as they try to implement agent technology?
Brunet: One challenge is that adoption is still concentrated among early adopters.
Within an organization, you might have 10% or 20% of people who are enthusiastic early adopters. They have done great work using local agents and cloud agents for their own tasks, and they have become highly productive.
What is missing in the next phase is the ability to use long-running agents across teams, processes, and workflows.
That requires more support from the top of the organization. Leadership has to say, “This is a priority, and this is how we want to automate or change this process.”
For the FDE team, it is therefore important to find the right champions inside an organization: people who want to meaningfully change the business and who will work with us and their internal teams to transform how work gets done.
Standardizing work with cloud agents
Latent Space:Local AI appears to be gaining momentum, partly because of the increasing availability of open-source models. Are you doing more local AI implementation work with customers?
Brunet: We have local agents that people run through the desktop application or the CLI, and that experience is largely self-service. People have adopted the technology at a phenomenal rate, particularly across Cursor’s user base.
We are also seeing people adopt cloud agents because they are excited about being able to run tasks without keeping their laptops half open. Agents can now work in the cloud on tasks that previously ran locally.
What becomes interesting is when this moves beyond an agent helping with one person’s job. The next question is how agents can work across a function, team, or organization so that processes are automated consistently. For example, you could have a QA agent applying the same process across several development teams.
We are receiving a lot of questions from customers about those kinds of use cases.
How customer deployments influence Cursor’s roadmap
Latent Space: Do the lessons from these deployments feed back into the core Cursor product?
Brunet: Yes. The forward deployed engineering team works very closely with customers on their use cases, so we are naturally a good way for the product and engineering teams to understand what customers want to build next.
We work closely with those teams and play a significant role in helping shape Cursor’s product roadmap.
The changing role of the forward deployed engineer
Latent Space: As agents become more autonomous, how do you expect the FDE role to evolve?
Brunet: I think the role is going to change drastically. I always say that if we are doing the same job we were doing six months ago, we have done something wrong.
Right now, people are still looking for inspiration about the use cases they can solve, so we want to propose new possibilities.
In software development, for example, we can show how designers and product managers might work seamlessly in Cursor alongside developers and testing teams.
We might also ask whether a company has considered using long-running agents to handle call-center or ticketing processes from start to finish.
As we work across industries such as healthcare, life sciences, the public sector, retail, and consumer packaged goods, we will continue identifying use cases across marketing, sales, and supply-chain operations. The FDE role will evolve alongside those possibilities.
How engineers can prepare for an FDE career
Latent Space: There are around 7,000 AI engineers at this conference. What advice would you give developers who want to move into forward deployed engineering?
Brunet: I’ve had this conversation five or six times already today. We are looking for builders with software engineering experience: people who have identified a problem and built a production-grade application or system from start to finish.
You should have designed it, developed it, tested it, and put it into production with real users.
My recommendation is to find those kinds of projects inside your organization and take ownership of them from beginning to end. Make sure you understand why you made each design decision.
How did you select the database? How did you choose the different services? Why did you design the system in that particular way? What were the trade-offs?
You should also understand the measurable return on investment, both in traditional business terms and through evaluations that demonstrate the value you are creating for internal customers.
If you want to get into forward deployed engineering, become familiar with these kinds of projects, gain experience delivering them, and learn how to explain the decisions you made.
This episode has a fun personal twist: There’s a counterfactual world where I was employee #1 at Genesis Molecular AI,1 the company behind today’s episode. A certain introduction happened a few weeks too late and I had already happily signed at Atomwise2, another ML-for-drug-discovery startup. Same problem, different company. I was certain ML was going to transform small molecule drug discovery. Early results were underwhelming. Useful at times, but nowhere near revolutionary. In the last year I’ve seen signs that ML is finally ready to deliver on my convictions from a decade ago. Genesis is one of the places that might have finally cracked this problem. I was super excited to come full circle and catch up with co-founder Evan Feinberg and CTO Sergey Edunov.
If you are at all interested in small molecule drug discovery, we think you will find this fascinating!
In our nearly two hour chat we cover:
What is small molecule drug discovery, and why is it hard
Structure prediction as a hotbed of innovation in AI algorithms
How advances in AI elsewhere have enabled stepwise improvements in predictive power
How the community benchmarks are essentially calling AI slop good enough
The Genesis flagship model (PEARL) can routinely hit a threshold that is necessary for real-world applications
New agentic workflows enabled by these highly accurate models
Read on for more, and also some personal thoughts on the future at the end.
The coolest diffusion research is happening at Genesis
Sergey Edunov came to Genesis from Meta where he led Llama 2 training and Llama 3 pretraining. Sergey was a former physicist who thought he was done with physics after many years of training LLMs. Then, he discovered Genesis, and was blown away with all the novel architecture work they’ve been developing.
It probably surprises no one that modern LLM research has not resulted in fundamentally novel or exciting updates in architectures since almost the advent of the transformer — the entire field is using variants on the same idea that came out in the original “Attention is all you need” paper. Sure, some were quite useful (mixture-of-experts in particular allowed for the massive model paradigm we’re at today), but there was very little conceptually exciting.
“We sort of had to wait for the right primitive to get created, and that turned out to be diffusion… Actually, some of the most innovative diffusion research that’s happening in our field is happening in 3D structure prediction right now.” — Evan Feinberg
The field of 3D structure prediction on the other hand has been a hotbed of research. Genesis’ recent model PEARL (Place Every Atom at the Right Location) is able to understand protein flexibility, and model not just where the ligand goes, but also make small adjustments of the protein so that the two fit better than either alone. The field knew this was missing for a long time, but it was really hard to model until now.
Agentic Discovery
What makes this problem so hard? As Sergey points out, there are 10^60 possible drug-like small molecules. You’ll never be able to search them all, and trying to find the good ones is something like finding a needle in a haystack — except everything except your needle is dangerous.
“There are 10 to the 60 drug-like small molecules in the universe… it’s like finding a needle in a haystack, where everything except your needle is very, very dangerous.” — Sergey Edunov
“Or finding hay in a needle stack might be a more apt analogy.” — Evan Feinberg
Trying to solve the multi-parameter optimization problem is even worse. What makes a strong binder and a molecule with good “ADMET Properties”3 are oftentimes at tension with each other. For example, a good binder is likely greasy, but a greasy molecule is likely insoluble so it won’t enter the bloodstream and get to where it needs to go!
Genesis’ advances in generative AI have now pushed them beyond the threshold where they believe agentic drug discovery loops are finally possible. We all remember the early days of LLMs. They were great chatbots but terrible agents, as small errors compounded rapidly into uselessness. As LLMs got better, the usefulness of agents rapidly improved. Evan and Sergey argue that their models at Genesis recently passed a similar threshold. Their internal agentic drug-discovery system (code named SAPPHIRE) can now iterate like a chemist: look at and reason about poses, form hypotheses, read literature, use internal tools, create candidates for the next iteration. Combining this with automated lab partnerships like the one Genesis has with Incyte, we’re rapidly approaching a time of drug discovery agents running 24/7 making/testing new molecules. Exciting times!
Benchmark crisis: Everyone’s favorite benchmark is slop
One surprising point that isn’t talked enough about: the academic field of “co-folding” has settled on a benchmark value of “2 Angstrom RMSD” as a metric for a “good pose”. Evan does not mince words: this threshold is just bad. Perhaps even deceptively bad. For many strong binders, there’s a very clear pose, one that you can even directly resolve in the PDB electron density! And yet, with a 2Å RMSD threshold, you can get the pose quite wrong in ways that might even mislead a medicinal chemist. For example, flip around an aromatic ring, and everything looks reasonable, but you’re no longer modeling the right interactions.
Evan makes the strong claim that 1Å RMSD is really the threshold necessary to ensure the core of the molecule is sitting where it needs to be, and models all interactions.
“If your model is sitting at 1.8, 1.9 Angstrom RMSD, that’s slop, most likely.” — Evan Feinberg
As a simple example, he points out hydrogen bonds which are responsible for many of the most important interactions in protein-ligand systems. Hydrogen bonds only have a 0.6Å range to be valid! Clearly if you’re accurately resolving all H-bonds, you generally have to be doing much better than the 2Å threshold.
This is clearly a hard-fought lesson for Evan and Genesis. In their opinion, the community is stuck on these benchmarks because academics developing methods were not users. Evan does see signs of life, with the use of new metrics such as lDDT for co-folding. Hopefully soon the community can agree that “1.8Å RMSD is slop”, and start hill climbing on this much harder task.
For a more thorough exploration of the weaknesses in conventional benchmarks, see the PEARL technical report.
PEARL tops OpenBind
Which makes what happened next all the more striking. Near the end of the podcast, we talked about a recent “proof-is-in-the-pudding” moment for Genesis — evaluating their PEARL model on a recently released OpenBind benchmark. This benchmark featured 802 never before seen co-complexes on a target protein EV-A71. This target seems almost custom-chosen to give most classical docking methods a problem. When a ligand binds to the main binding site, the protein moves around to close off the path the ligand used to enter the binding pocket. This process, known as “induced fit” is notoriously hard for traditional methods to model. The tradeoff is easy to understand: treating the protein as a static structure, it becomes difficult to place a ligand in a binding pocket. Treat the protein as dynamic, and now you have to simulate complicated processes that take a long time to resolve.
PEARL was able to model the induced fit of the ligand without running long MD simulations. Across the different evaluation metrics, PEARL came out not just ahead, but oftentimes well ahead of any public model. A truly impressive result.
“Where PEARL was exceptionally good is figuring out how to move this loop. We are basically correct for every single pose.” — Sergey Edunov
Even more exciting, this was done without any fine-tuning, or using any data on the target or homologous targets — the template PDB was released after PEARL’s training cutoff.
Where does co-folding go now?
As someone who has followed or participated in ML techniques for protein-ligand interactions for almost a decade, I was genuinely impressed with the results that Genesis has released recently. This has been many years in development, and I’m sure Evan and the team had many sleepless nights trying to get to this point. I also think other teams are making similar progress — both Isomorphic and Deep Origin have released results that seem spiritually similar and combine computation, wetlab data, ML, to achieve genuine predictive power that seemed impossible a decade ago. Sadly, all of the above are closed source so there’s no way to honestly compare them. Looking at the results I think there might be a time in the not so distant future where we can consider protein-ligand binding “solved”.
I sincerely hope that the academic community can take inspiration from these developments. Once you know something can be done, it’s much easier to execute. Still, I believe that the key enabler in all of the above was the tight integration of ML, large-scale computation, and real-world drug discovery applications. Sadly academia is just not structured in a way that makes such a development easy.
With those parting thoughts, we hope you give the podcast a listen!
ADMET stands for Absorption, Distribution, Metabolism, Excretion, and Toxicity. This set of about 30 properties all need to be optimized in order for a molecule to be considered a “good drug”.

 Login